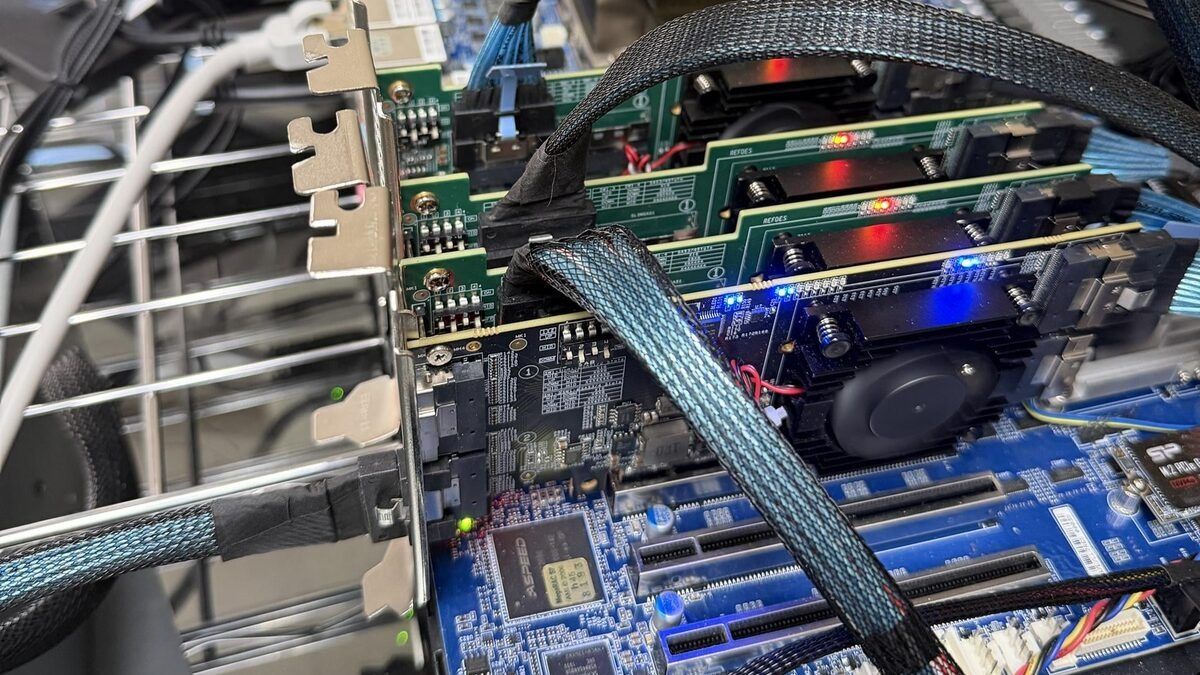
Lawyer’s $9,450 private AI server with 12 used Nvidia V100s now runs every DeepSeek V4.1 Flash expert at 4-bit NVFP4 — hits 184 tokens/s and claims to beat DGX Spark stacks on single requests
I observed, modal, drop-down deviations. Like not closing sometimes in the server. And also if you are using this combo can you suggest some tips regarding performance, UI point of view.