GitHub - sqliteai/waste: Run the full 2.78-trillion-parameter Kimi K3 model beyond available RAM by streaming activated weights directly from NVMe. A dependency-free, embeddable C inference engine.
Run the full 2.78-trillion-parameter Kimi K3 model beyond available RAM by streaming activated weights directly from NVMe. A dependency-free, embeddable C inference engine. - sqliteai/waste
I was recently trying to validate some performance improvements related to lld at $DAYJOB and it was a little frustrating to see the improvements in our benchmarks but not in the live-production dashboards.
KO | EN As technology has advanced, processor speed has risen quickly, but memory speed hasn’t kept up. No matter how fast a processor is, if memory responds slowly the whole system ends up slow. The device that addresses this is the cache.…
AMD’s Venice-X CPU launches in 2027 with 1152 MB of 3D V-Cache, 96 cores, and 5.15 GHz boost clock – Zen 6 CPU for high-performance computing comes with major pillars of Venice
If you happen to find yourself in a sysadmin position, or a position where you just so happen to maintain someone’s infrastructure, chances are that at some point in time the topic “we need a cache” comes up.
GitHub - huawei-csl/KVarN: KVarN is a native vLLM KV-cache quantization backend for your agents: 3-5x more context, throughput above FP16, and FP16-level accuracy. Calibration-free, one flag.
KVarN is a native vLLM KV-cache quantization backend for your agents: 3-5x more context, throughput above FP16, and FP16-level accuracy. Calibration-free, one flag. - huawei-csl/KVarN
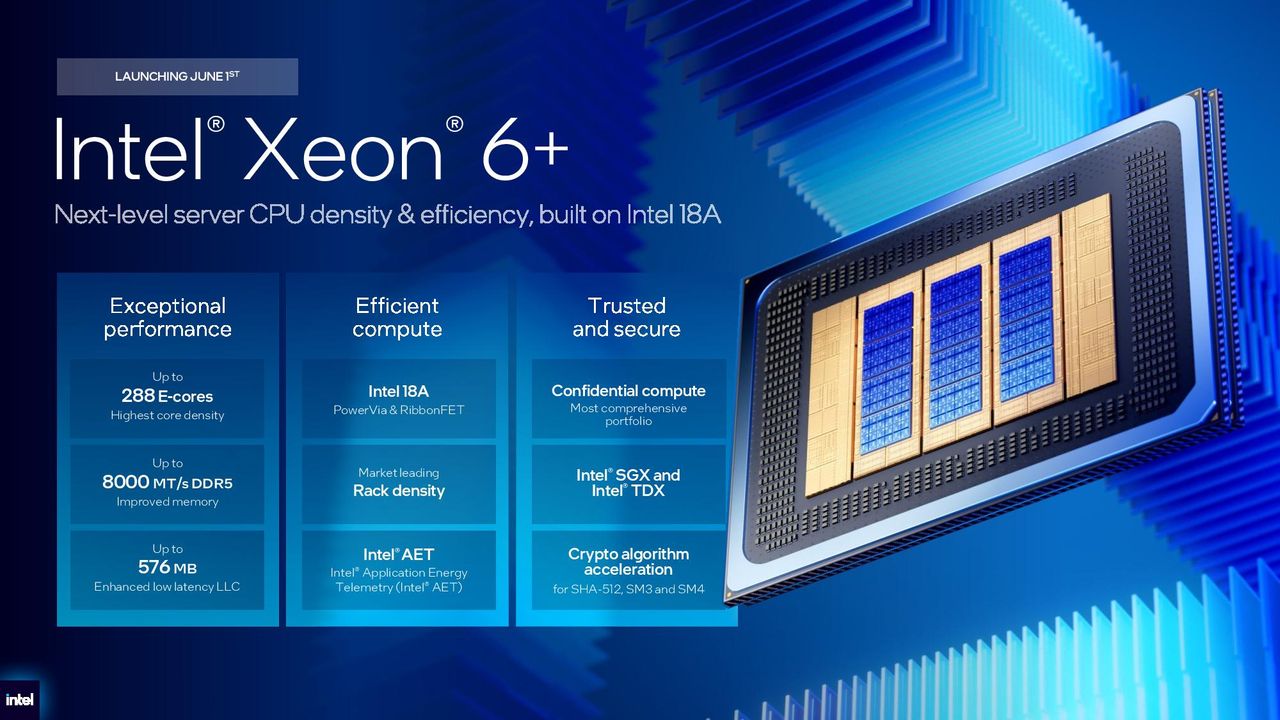
Intel Xeon 6+ ‘Clearwater Forest’ puts 18A in the data center with up to 288 cores, 576 MB of L3 cache — new Xeon 6990E+ is 30% faster per thread than 192-core AMD Epyc 9965, says Intel
Modern LLM serving is hard to tune because each deployment is a stack of interacting choices: model backend, tensor-parallel shape, prefill/decode split…