A practical engineering guide to B-Tree vs LSM-Tree Storage Engines: Write Amplification, Read Latency, and Compaction. Learn core mechanics, production tradeoffs, and best practices.
Breaking down where our 914ms p95 database latency actually went, what same-region tuning fixed (9ms), and how co-located PostgreSQL 18 + PgBouncer 1.26 brought it down to 2ms.
AI performance comes down to three dimensions: Deployments must balance all three: High accuracy is wasted if responses are slow, and raw throughput means…
I'm getting over 5 min response times on Cloud Vertex AI Model Garden Model as a Service DeepSeek V4.1-Flash. Just was curious if anyone else was getting this as well? submitted by /u/jumpintheocean [link] [comments]
Every personalization decision adds latency that has a measurable cost in conversions and order value. Learn where that cost comes from — and how to avoid paying it.
The surge in AI adoption is transforming everything from chatbots to content generation. Still, a common pain point remains: How can organizations confidently…
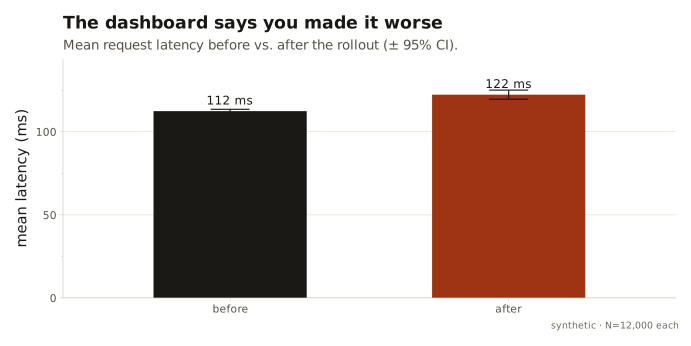
I was recently trying to validate some performance improvements related to lld at $DAYJOB and it was a little frustrating to see the improvements in our benchmarks but not in the live-production dashboards.