Menu

#V100

17 posts

Feed·
17 of 17 posts
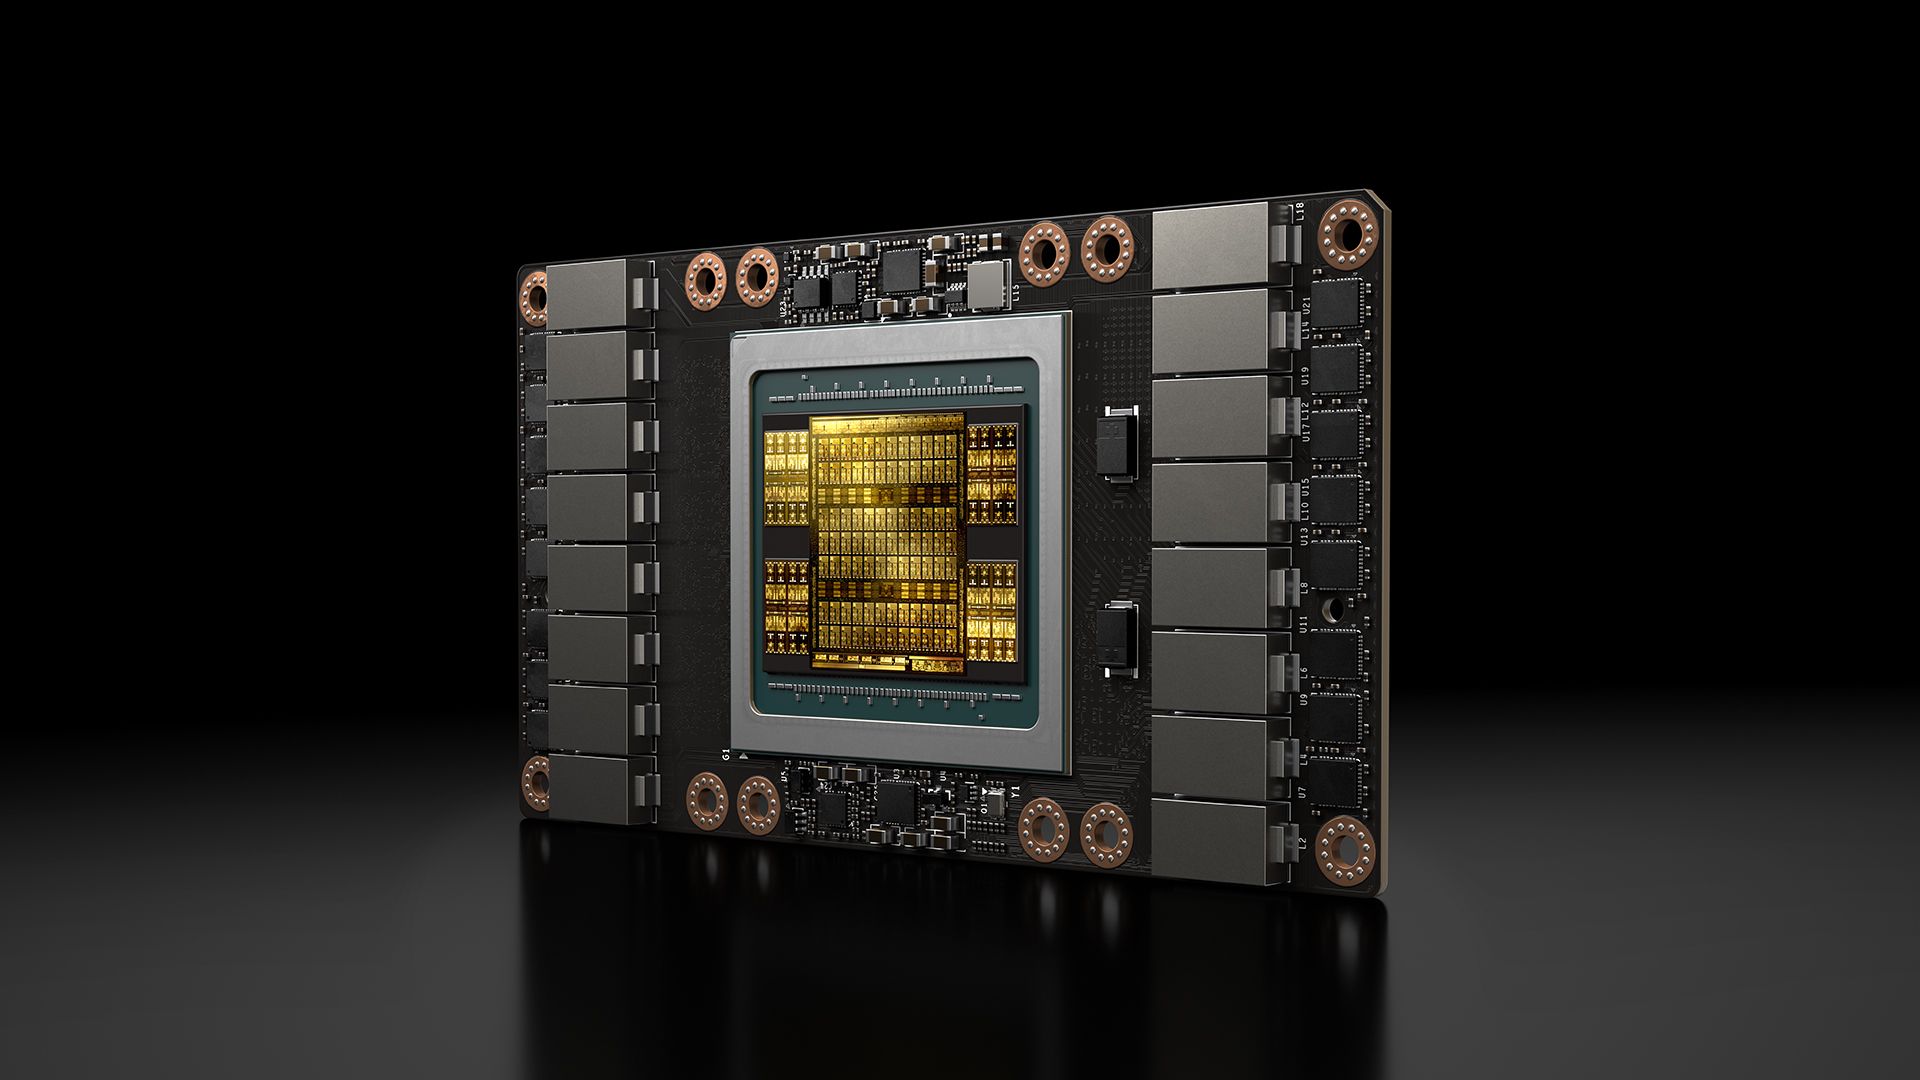
$200 'socketed' Nvidia AI GPU for servers hacked into a PCIe card with custom PCB and 3D-printed cooling — modded Tesla V100 SMX data center GPU runs AI LLMs and is more efficient than many modern midrange offerings in AI inference
🖼️
0Read More

$200 'socketed' Nvidia AI GPU for servers hacked into a PCIe card with custom PCB and 3D-printed cooling — modded Tesla V100 SMX data center GPU runs AI LLMs and is more efficient than many modern midrange offerings in AI inference

Tom's Hardware·Hassam Nasir·6 months ago
#5OAlLCVJ
#nvidia#benchmarking#intelarc#amdryzen#v100

From Latest from Tom's Hardware: $200 'socketed' Nvidia AI GPU for servers hacked into a PCIe card with custom PCB and 3D-printed cooling — modded Tesla V100 SMX data center GPU runs AI LLMs and is more efficient than many modern midrange offerings in AI…

15s
I wrote a custom CUDA inference engine to run Qwen3.5-27B on $130 mining cards
🖼️
0Read More

I wrote a custom CUDA inference engine to run Qwen3.5-27B on $130 mining cards

DEV Community·Haru-neo·6 months ago
#opxc2Bn2
#ai#llm#opensource#software#qengine

From Dev Community: I wrote a custom CUDA inference engine to run Qwen3.5-27B on $130 mining cards

15s
0Read More

How We Built Post-Quantum Encrypted Video Conferencing

DEV Community: encryption·H33.ai·6 months ago
#XQqkUNSe
#dev#strong#v100#article#video

Originally published at v100.ai At V100, we build AI video infrastructure entirely in Rust. 20 microservices. 0.01ms server processing. 220,000+ requests per second. Post-quantum encryption on every call.…
15s