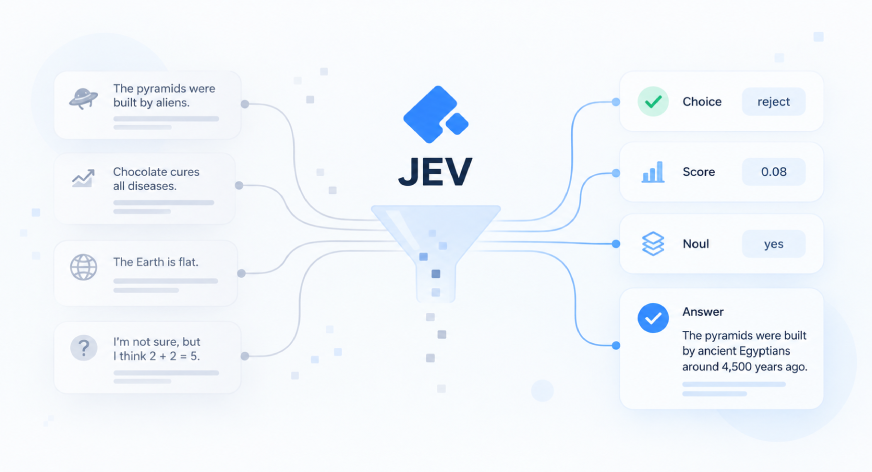
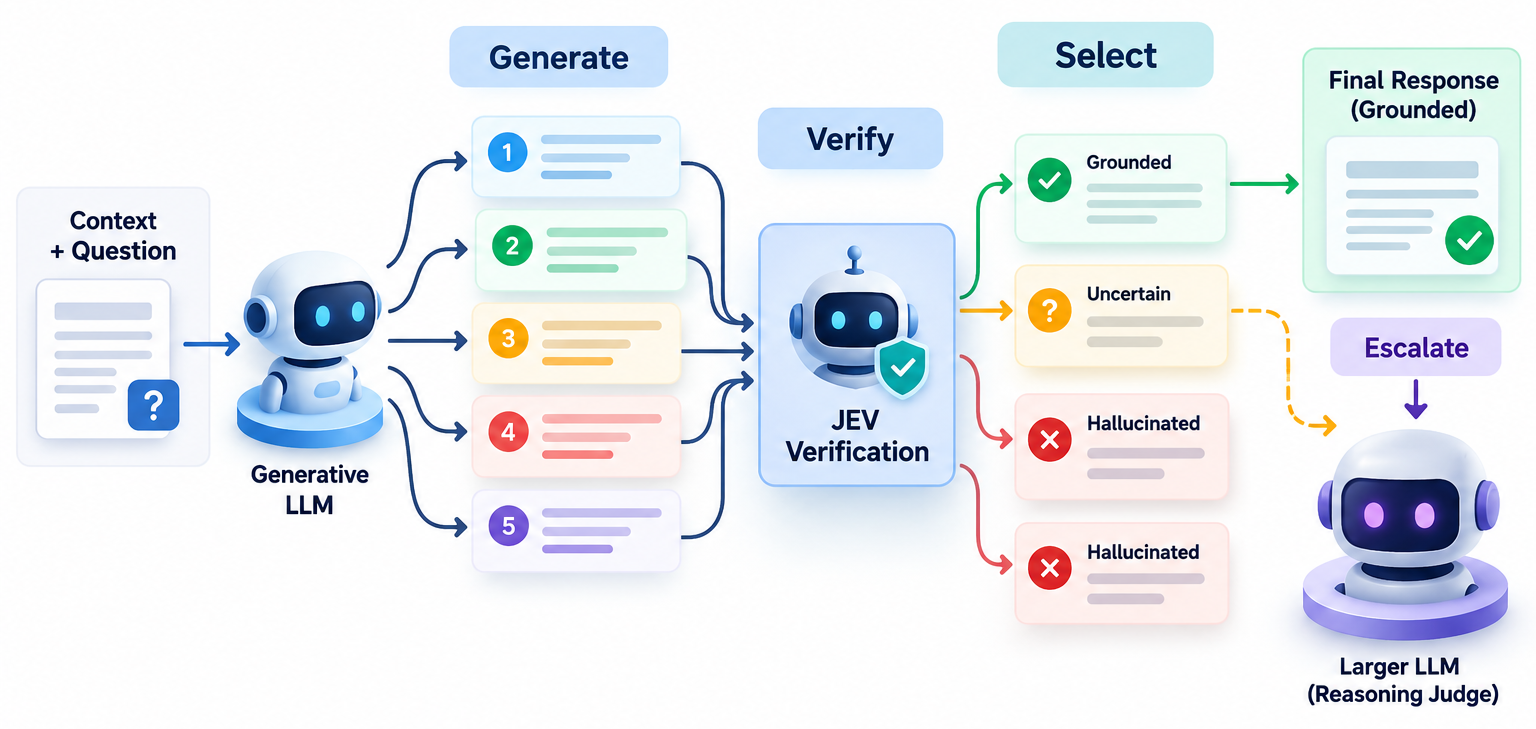
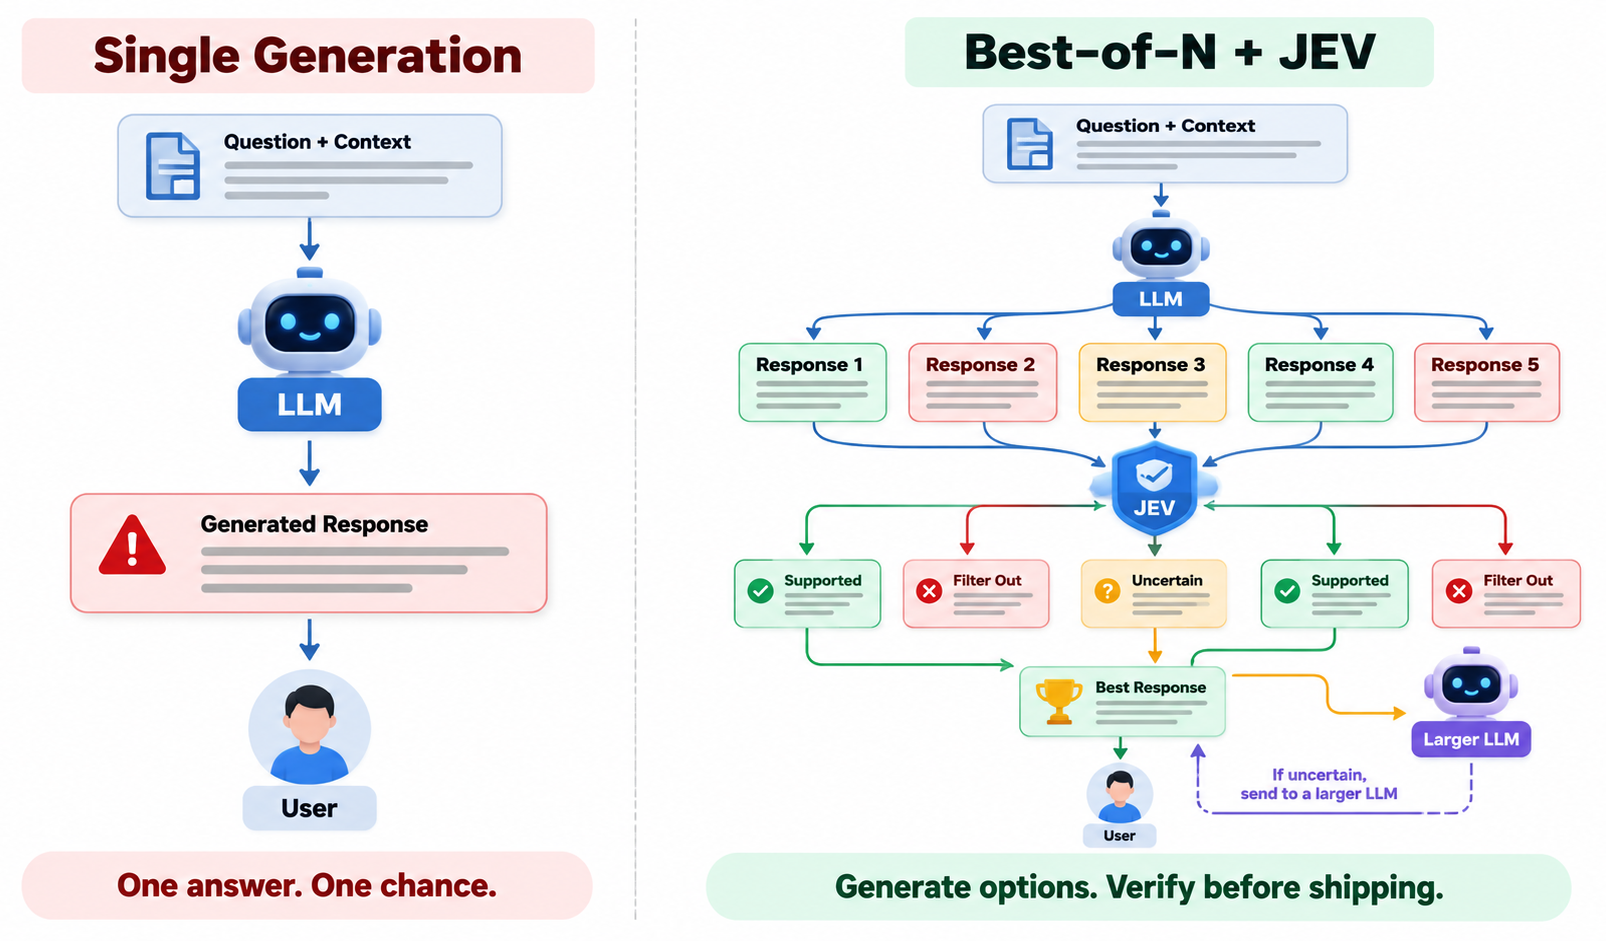
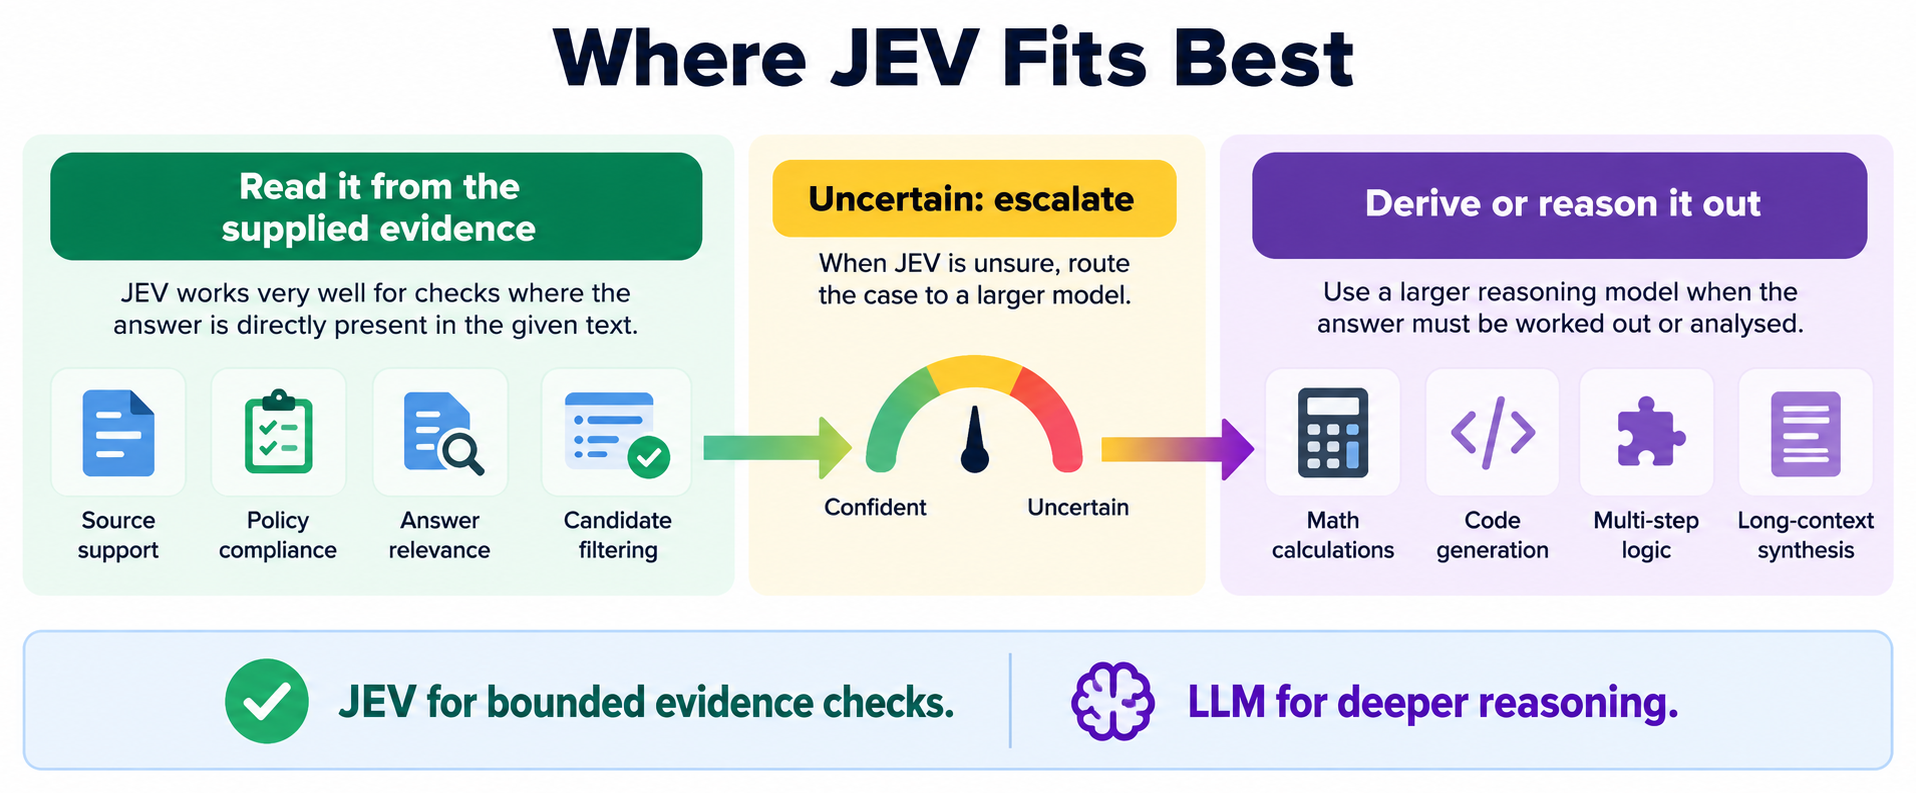
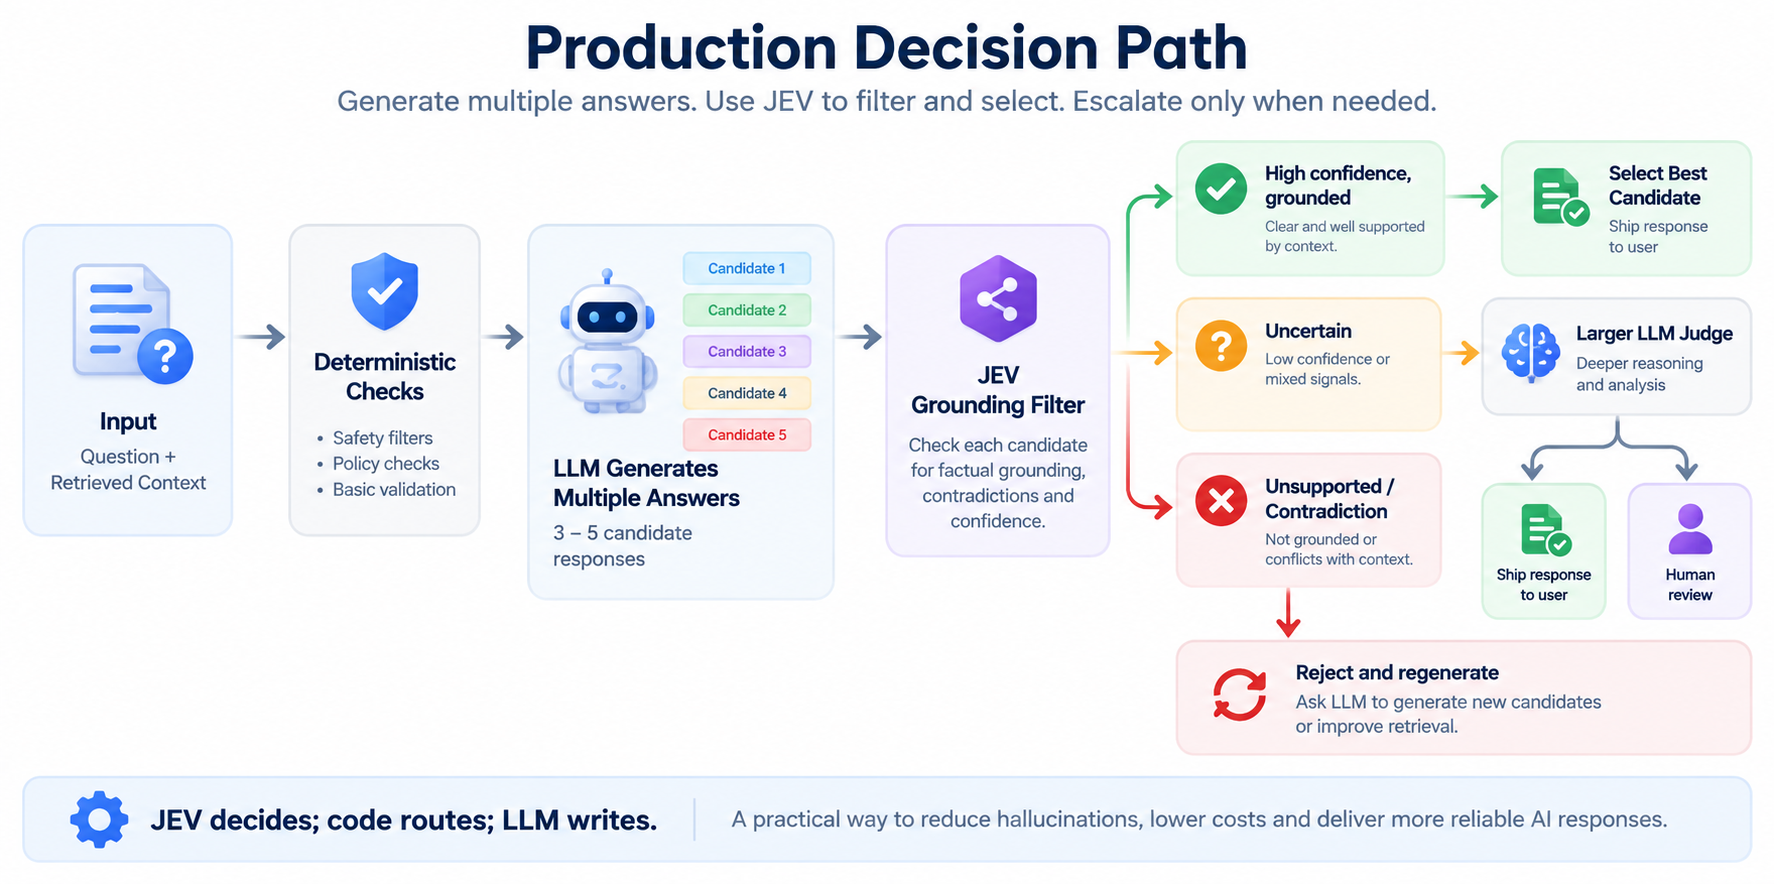
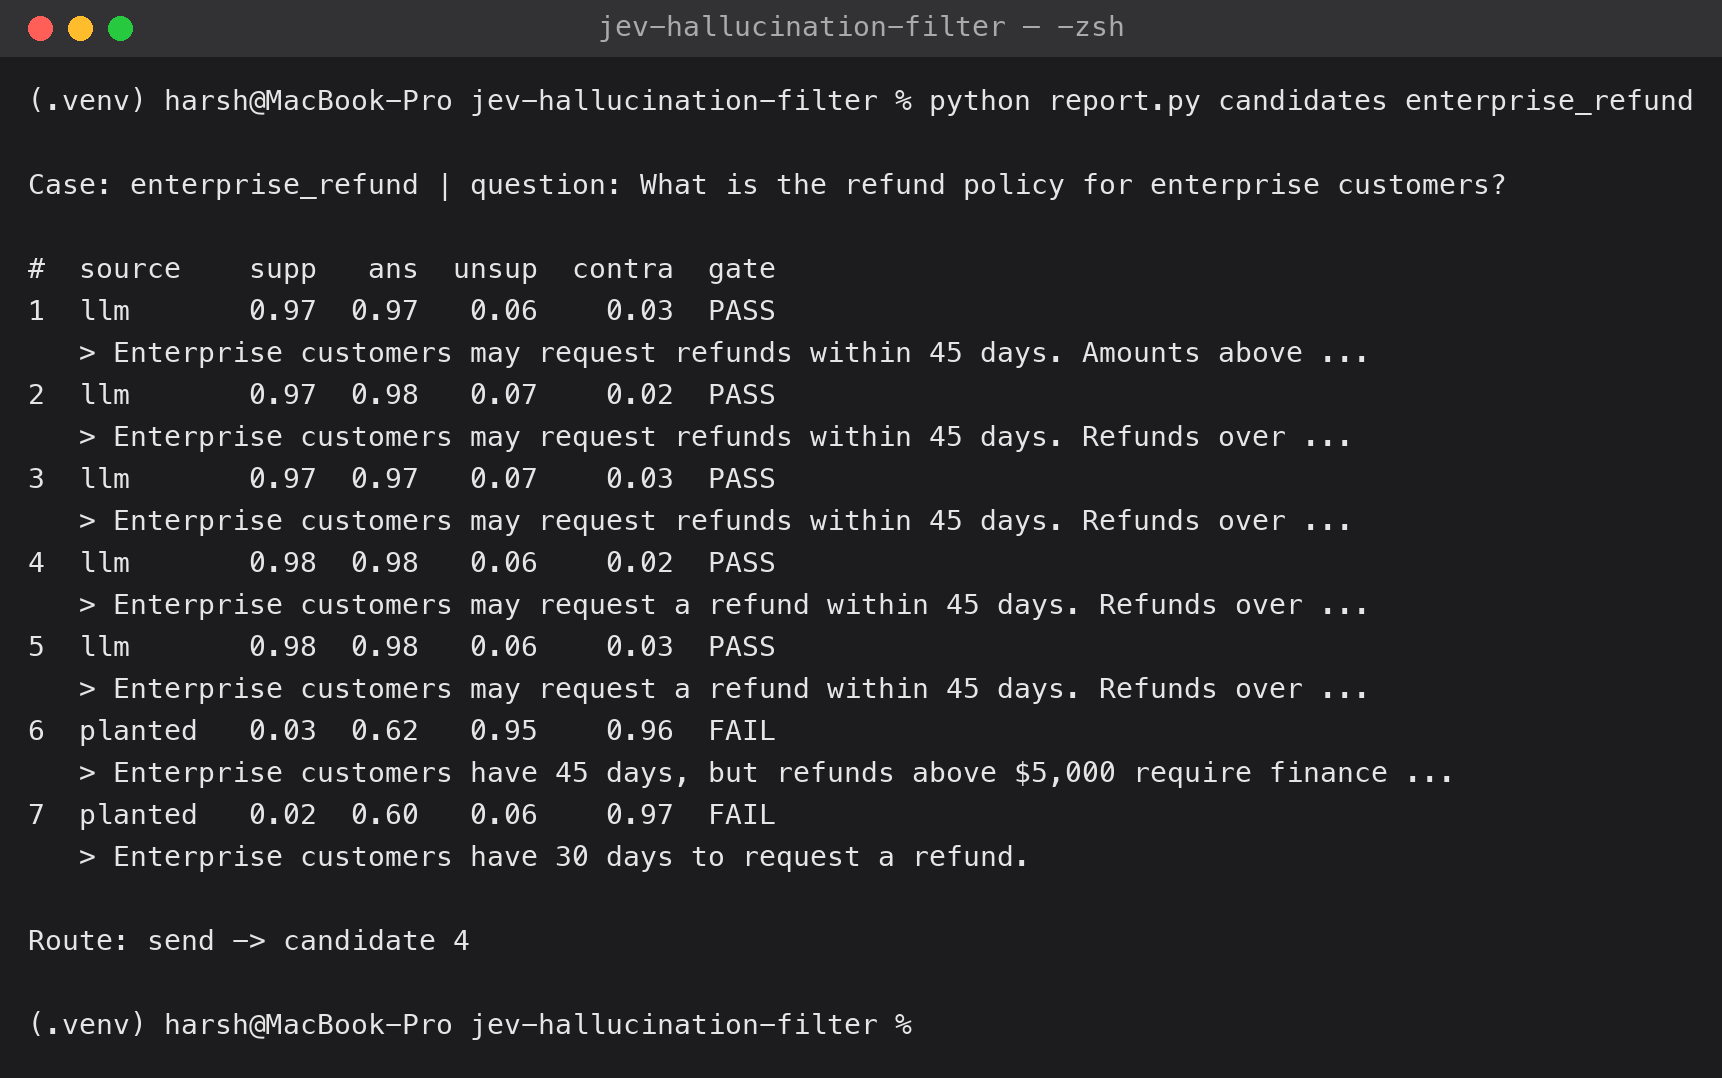
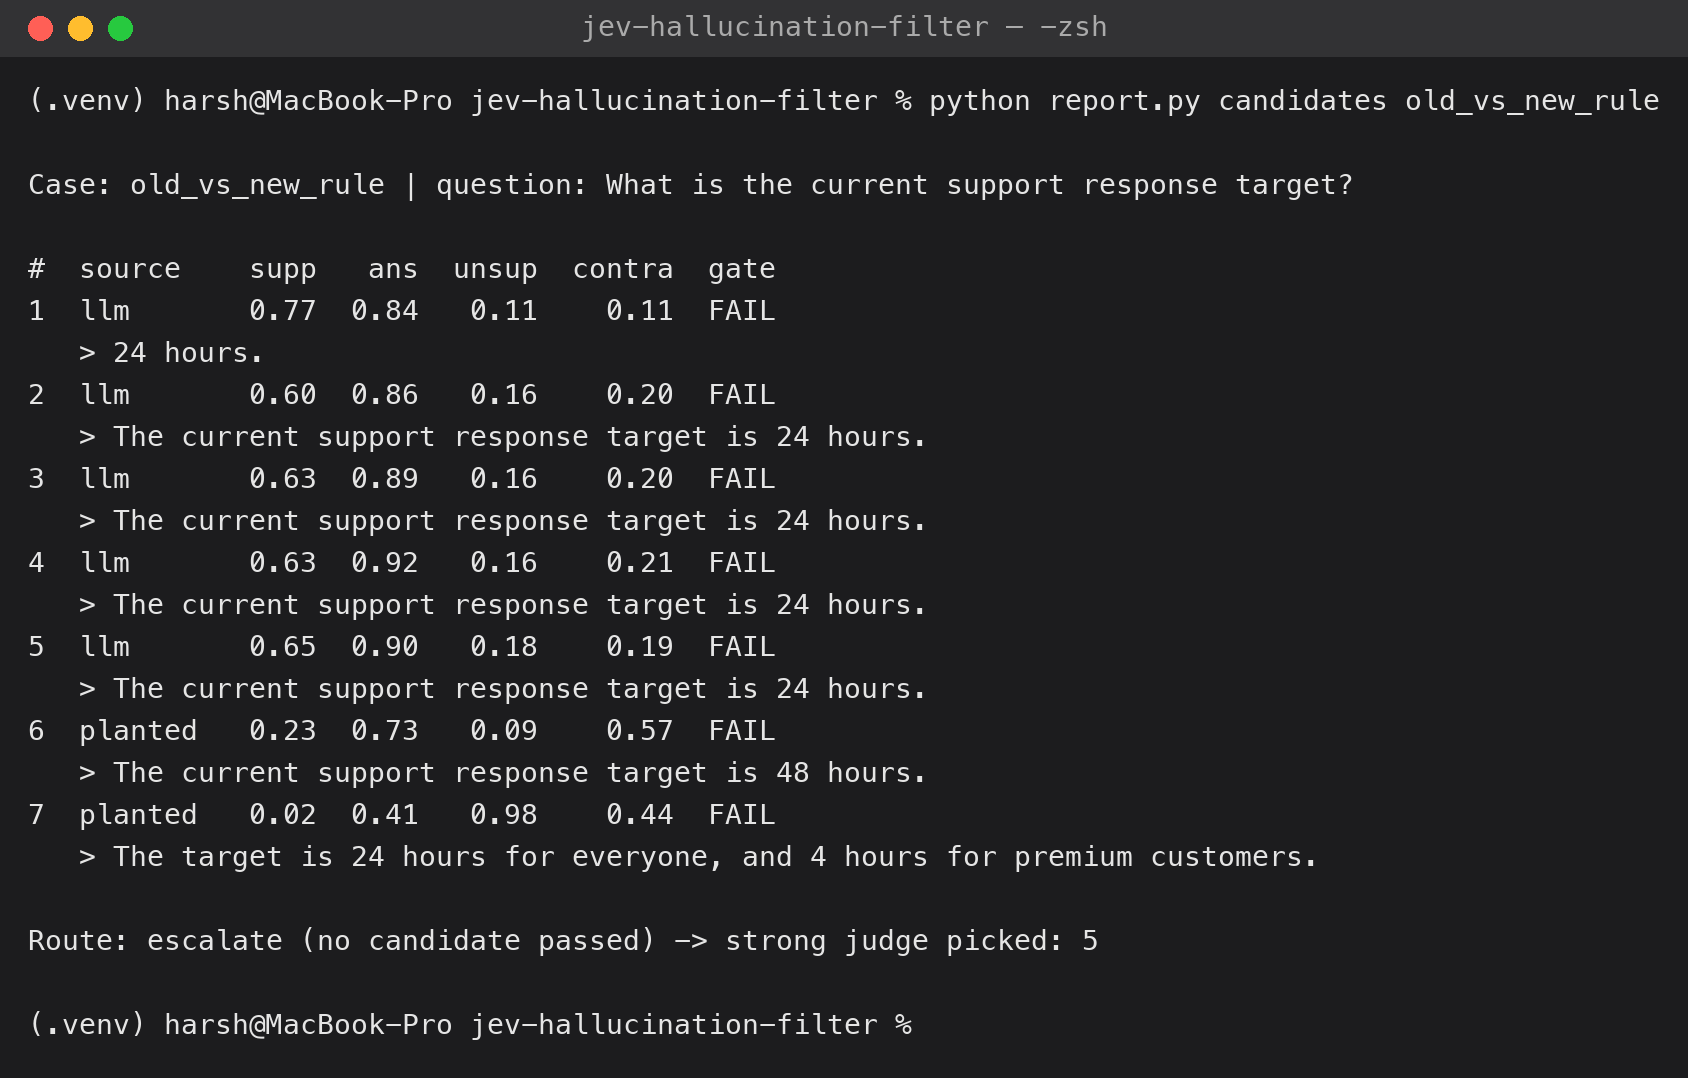
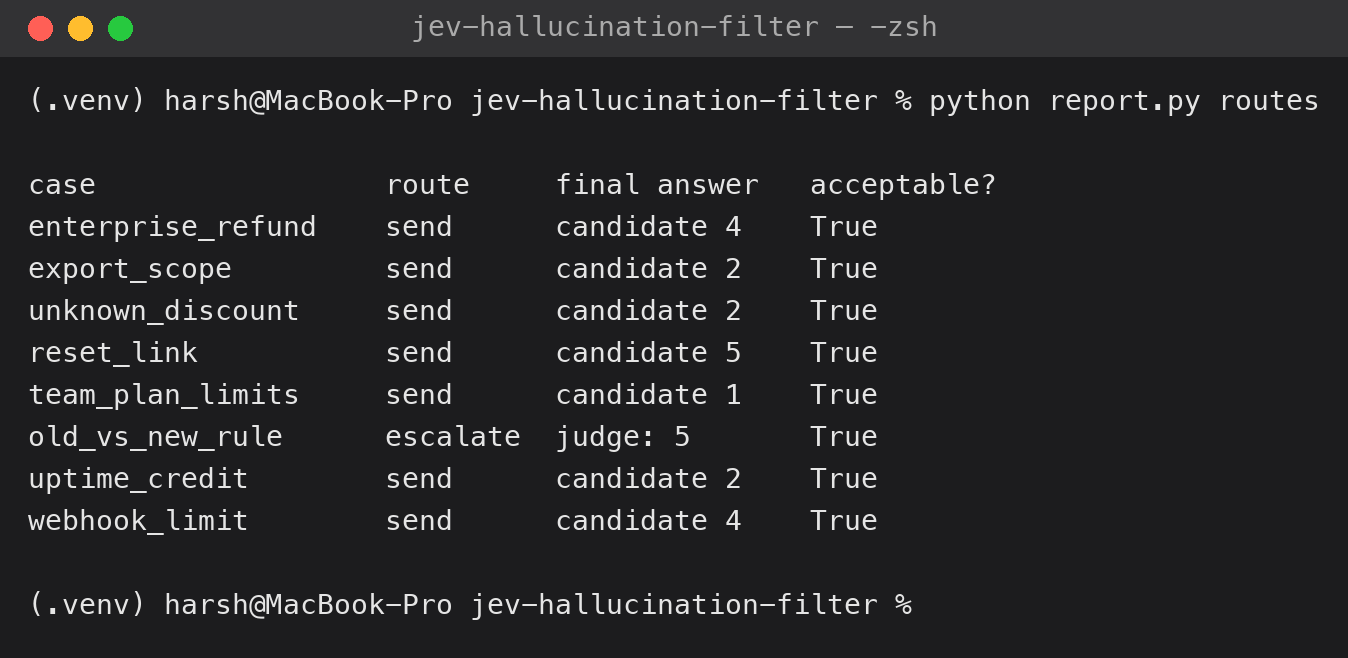
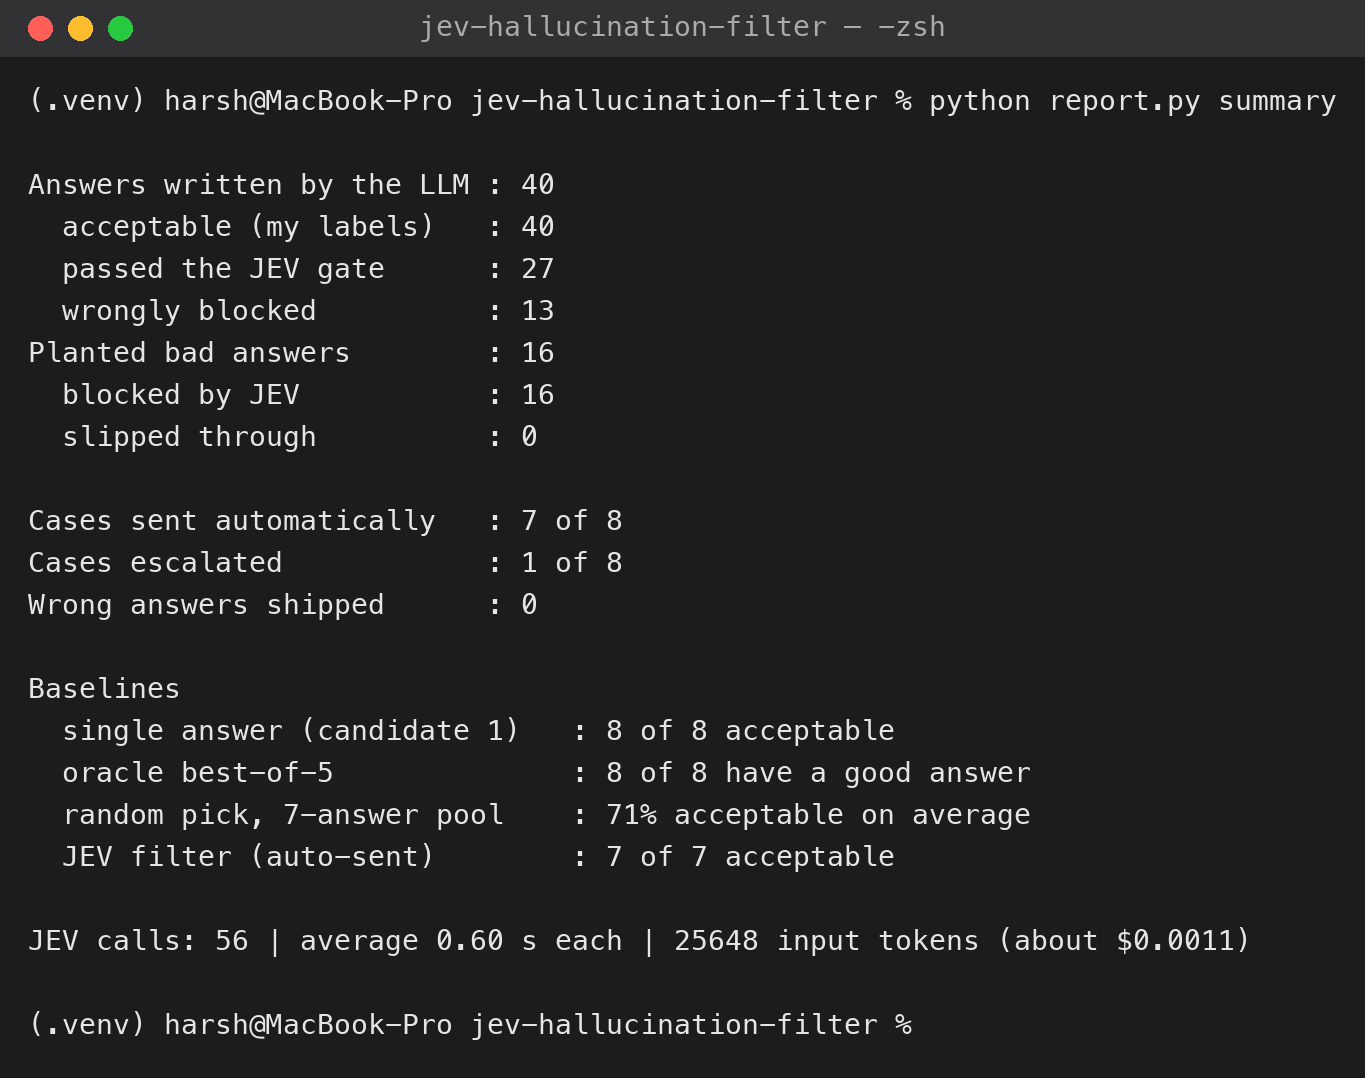
The LLM writes several answers. JEV checks each one. Grounded answers are sent, wrong ones are dropped, and unsure cases go to a bigger LLM.
The majority of hallucination checks begin following the initial writing of an answer by the LLM. We then hold someone up to a second standard of judgment, or we hand over dangerous cases to a person. That works but that is looking at the solution only as one-off.
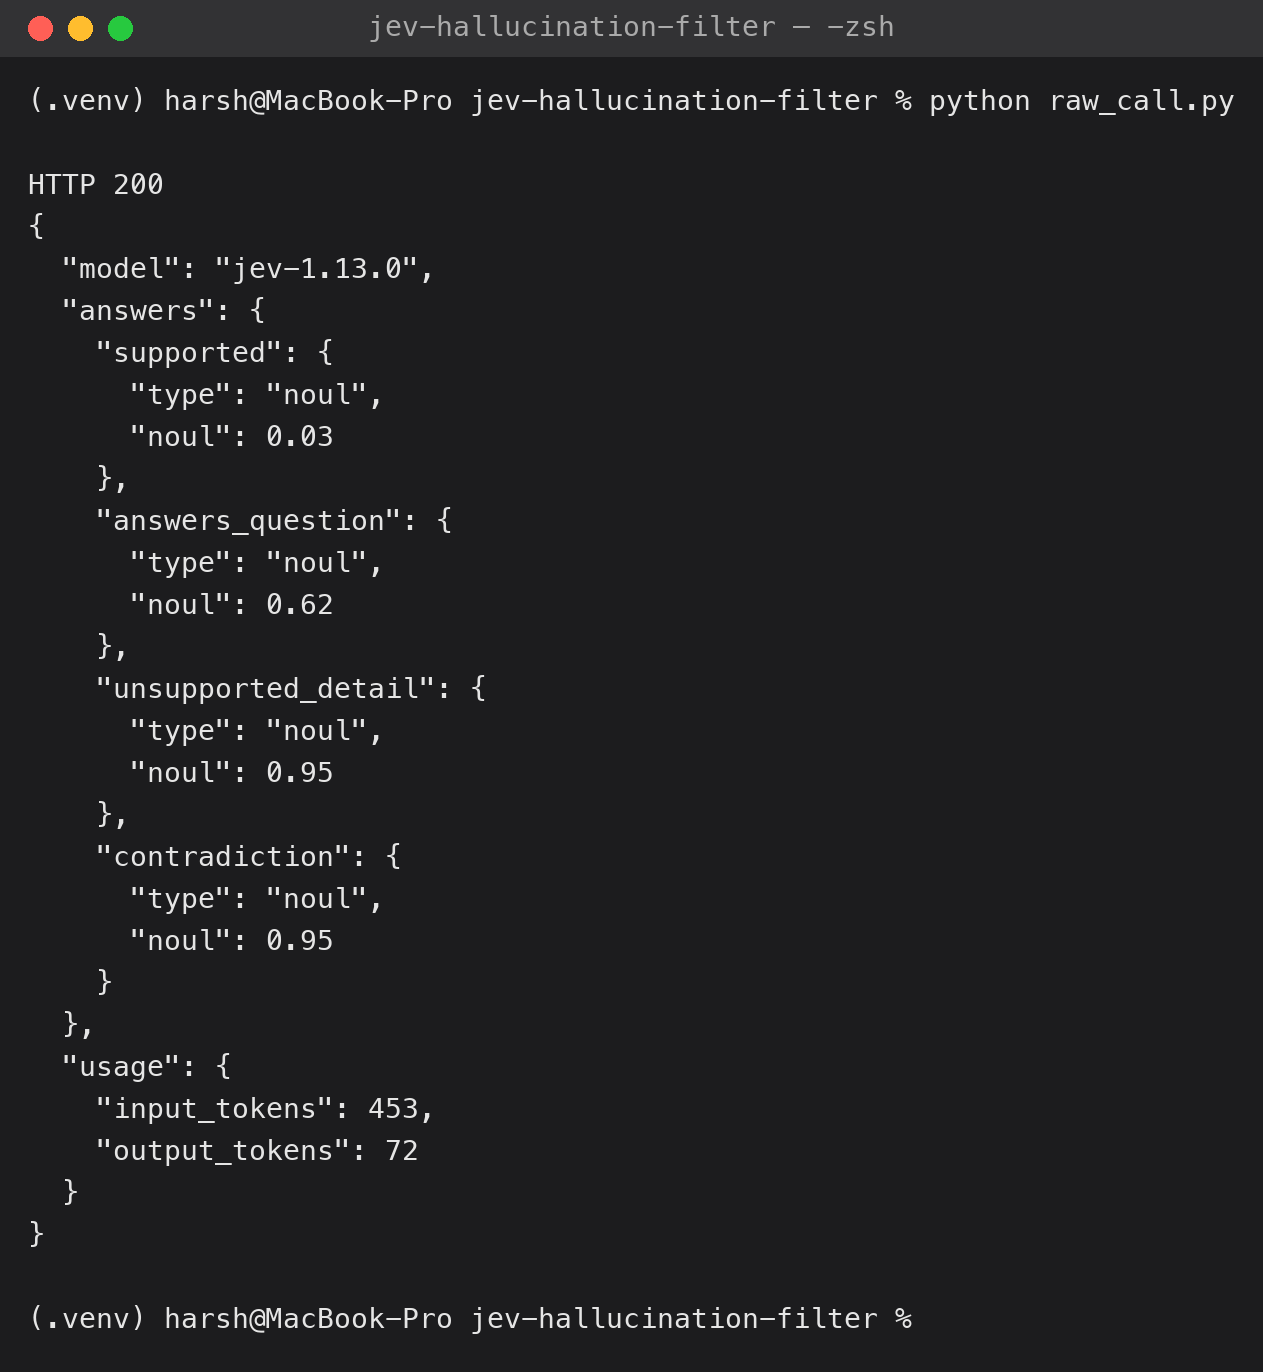
What if the LLM generates five different answers from the same source text and a fast, cheap model verifies each of them before it’s sent? This is what this article is about. The LLM continues to write. The model called JEV, from TypeSafe AI, only examines whether each answer is backed by the source.
First an honest warning. JEV cannot guarantee a not-hallucinatory answer. It’s also a model, can make mistakes. TypeSafe claims JEV is not allowed to “hallucinate” its own responses, since the responses are given in a fixed list, but that can be the wrong answer.…