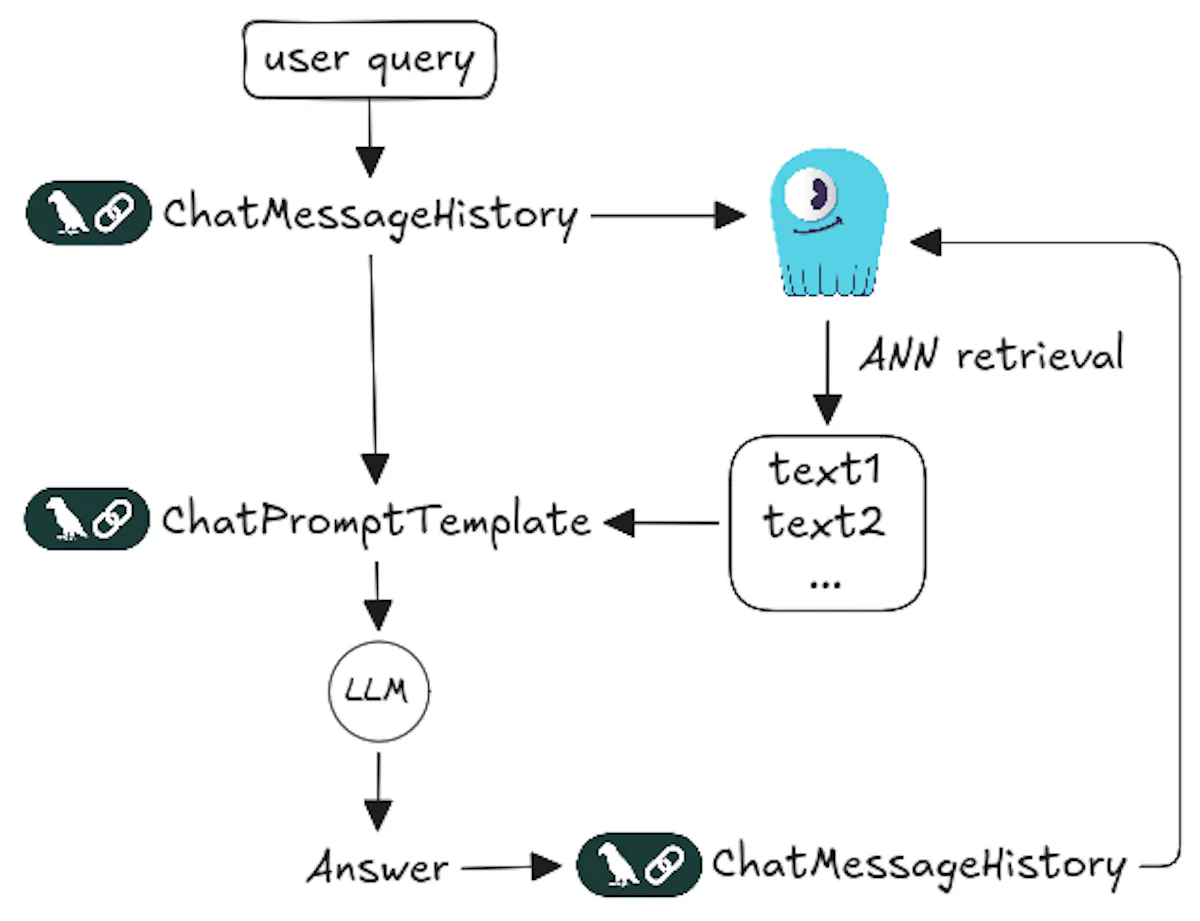
How to replace LangChain’s in-memory chat history with ScyllaDB — so your RAG chatbot retains context across restarts and scales across replicas
This post demonstrates how to integrate ScyllaDB Vector Search into your LangChain project for RAG use cases, as well as how to use ScyllaDB as a durable conversation memory within LangChain.
Background
Large language models are trained on a fixed snapshot of the world. RAG patches that gap by retrieving relevant documents at query time and injecting them into the prompt. The pipeline has two phases:
Index: load documents, split them into chunks, embed each chunk, store embeddings in a vector store.
Retrieve & Generate: enrich and embed the user’s question, find the nearest vectors (ANN search), pass the matching chunks as context to the LLM.
But RAG alone is not enough. You still need to keep track of all inputs provided by the user.
Persistent Chat Memory
LLMs are stateless. Every call starts with a blank slate unless you replay the conversation history.…