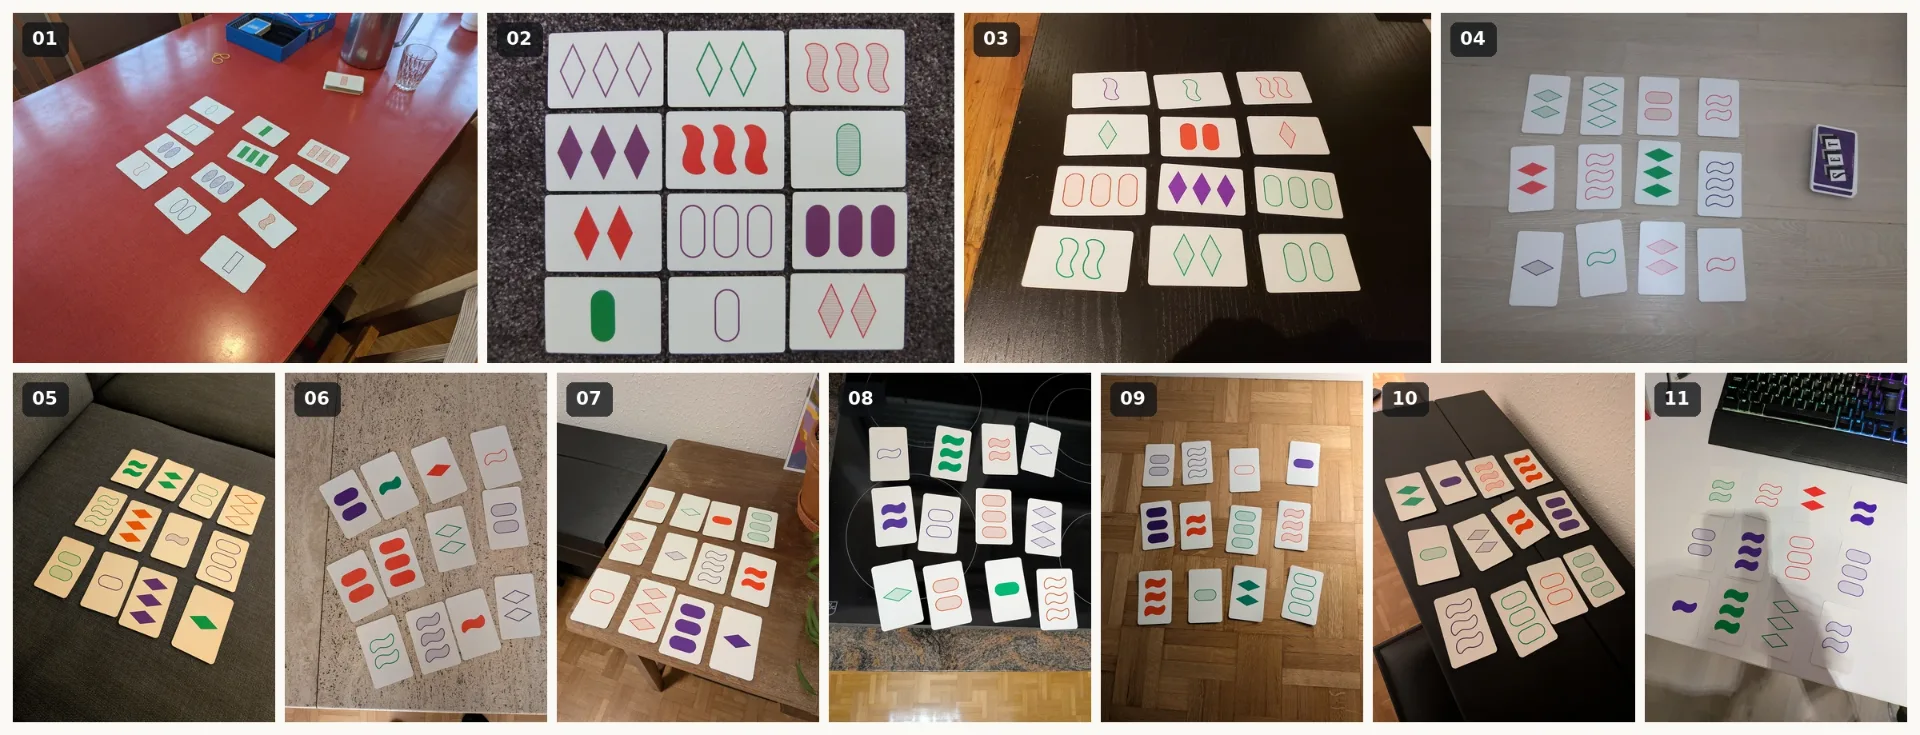
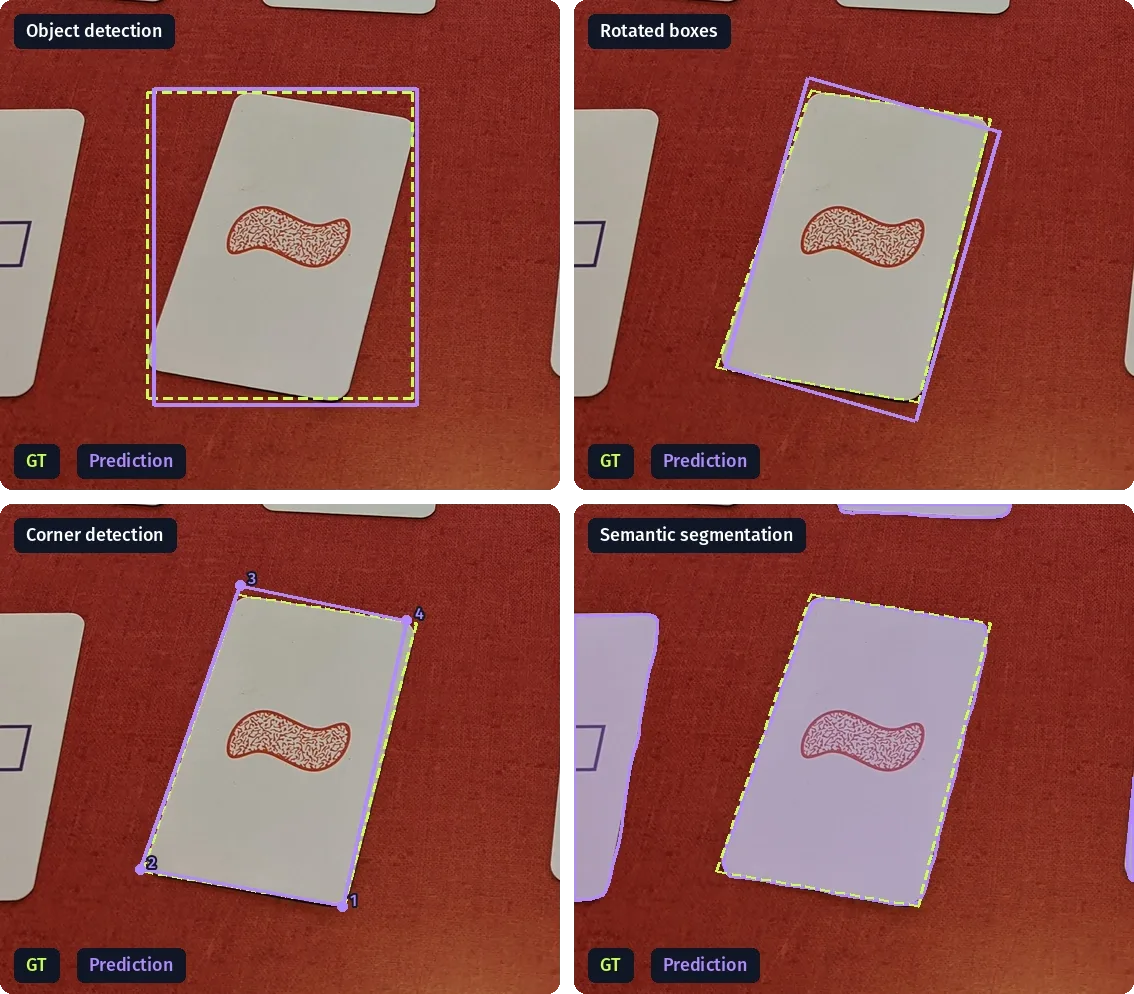
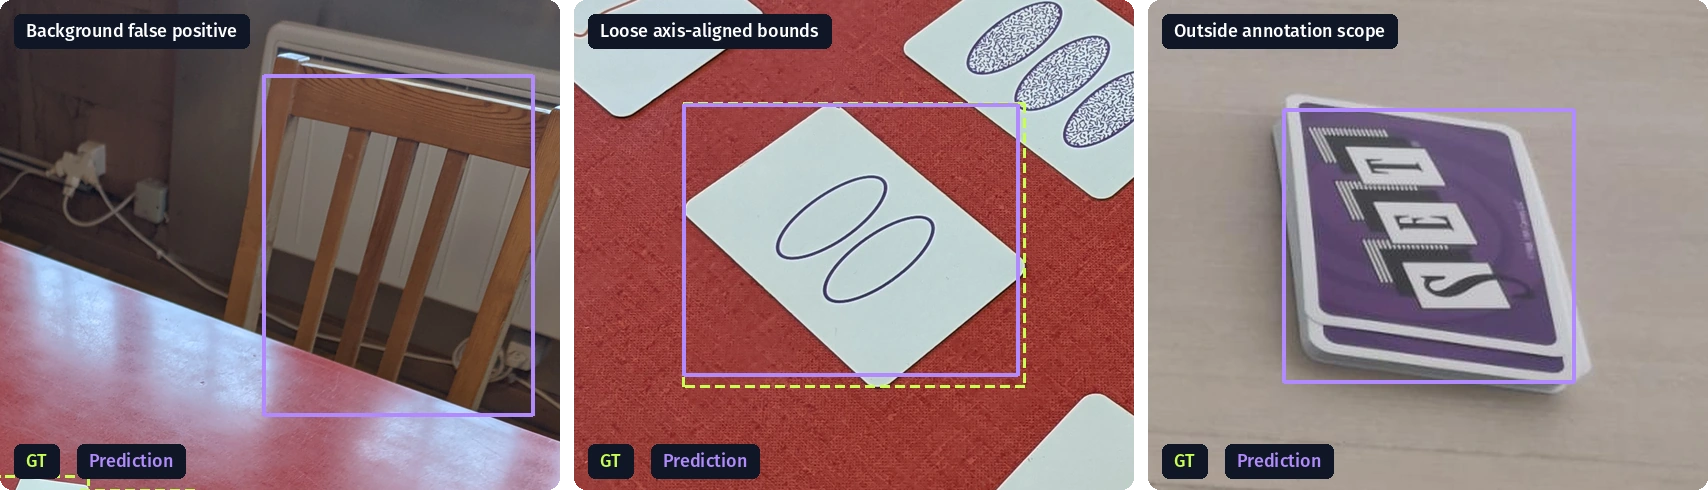
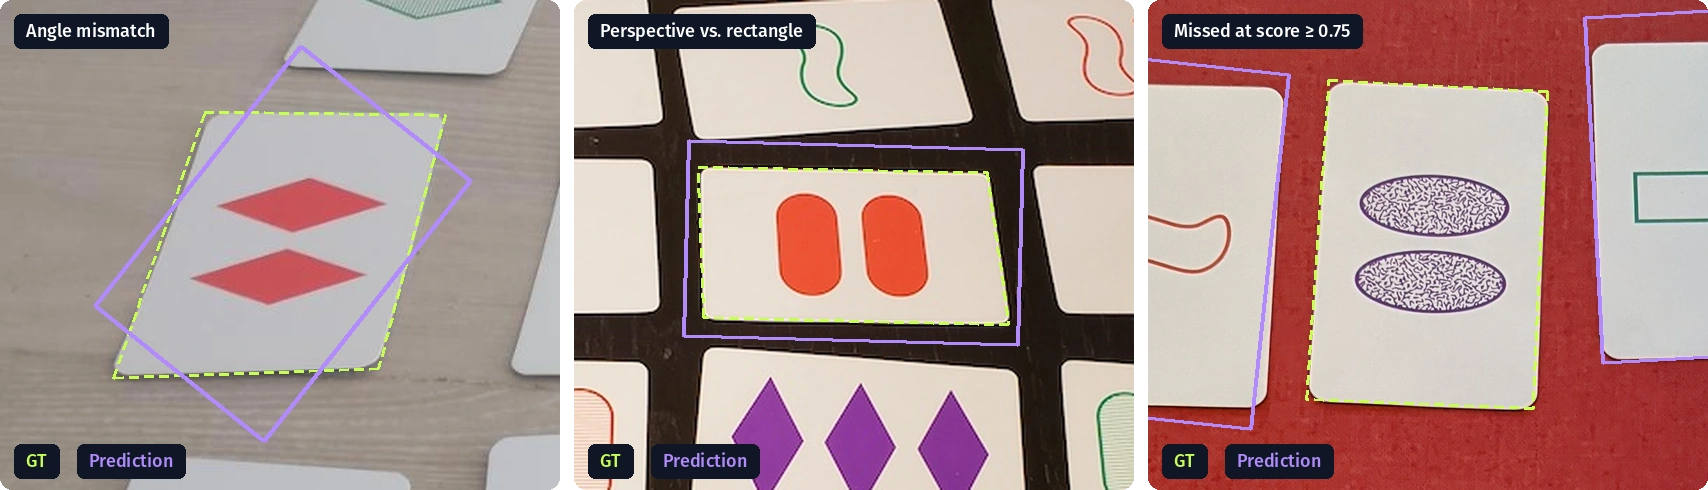
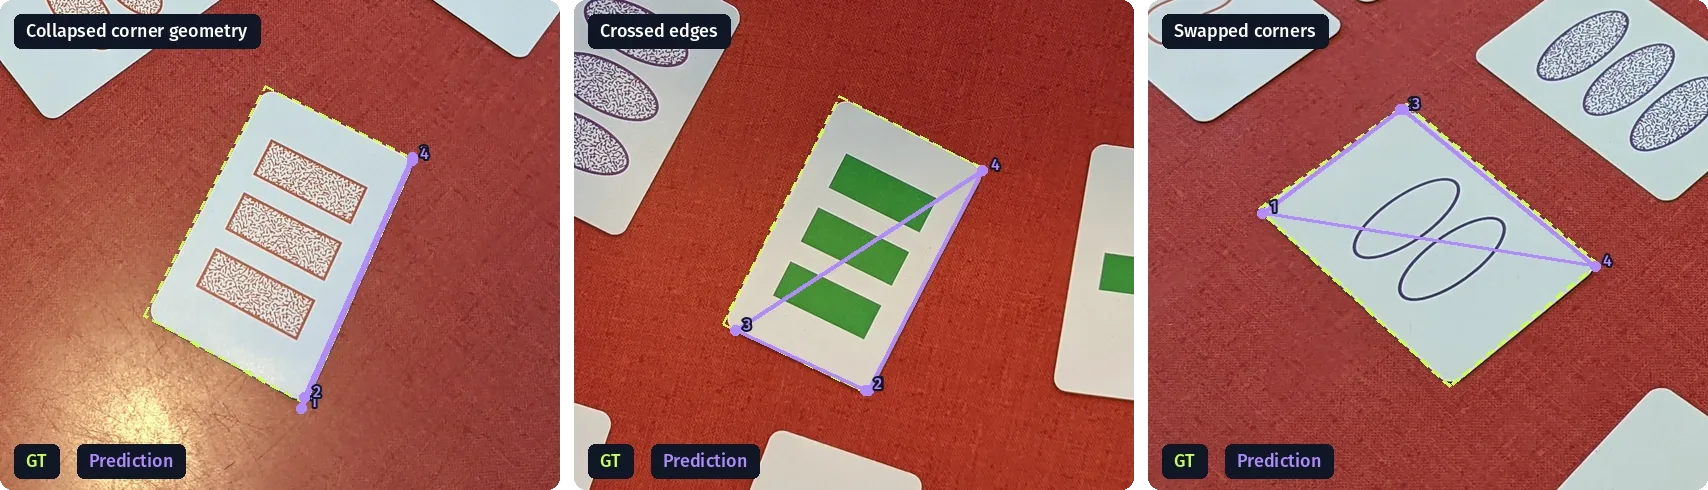
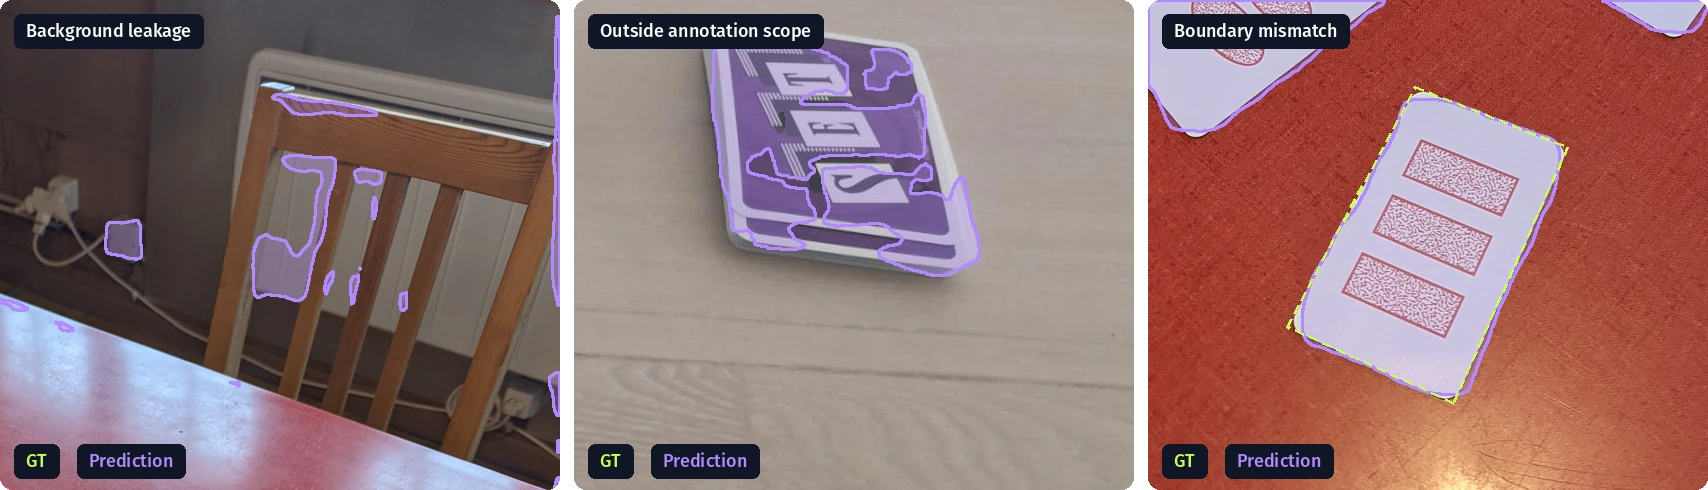
Data is the most valuable part of machine learning. The more diverse, task-specific data you have, the better you can fit a model to your objective. But it is not always easy to collect this data and/or label it according to your requirements. You might need to manually capture data while making sure not to introduce any biases into your dataset or verify annotations from a third party, or nowadays rather verify the annotations of the VLM you used for pre-annotating.
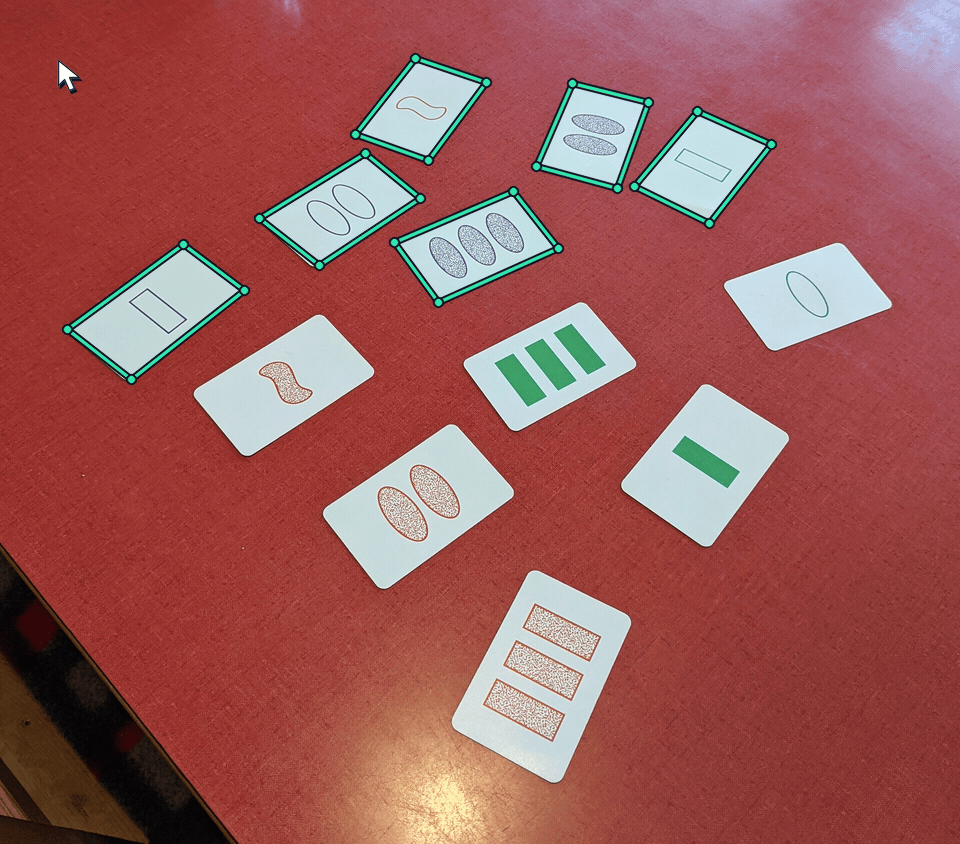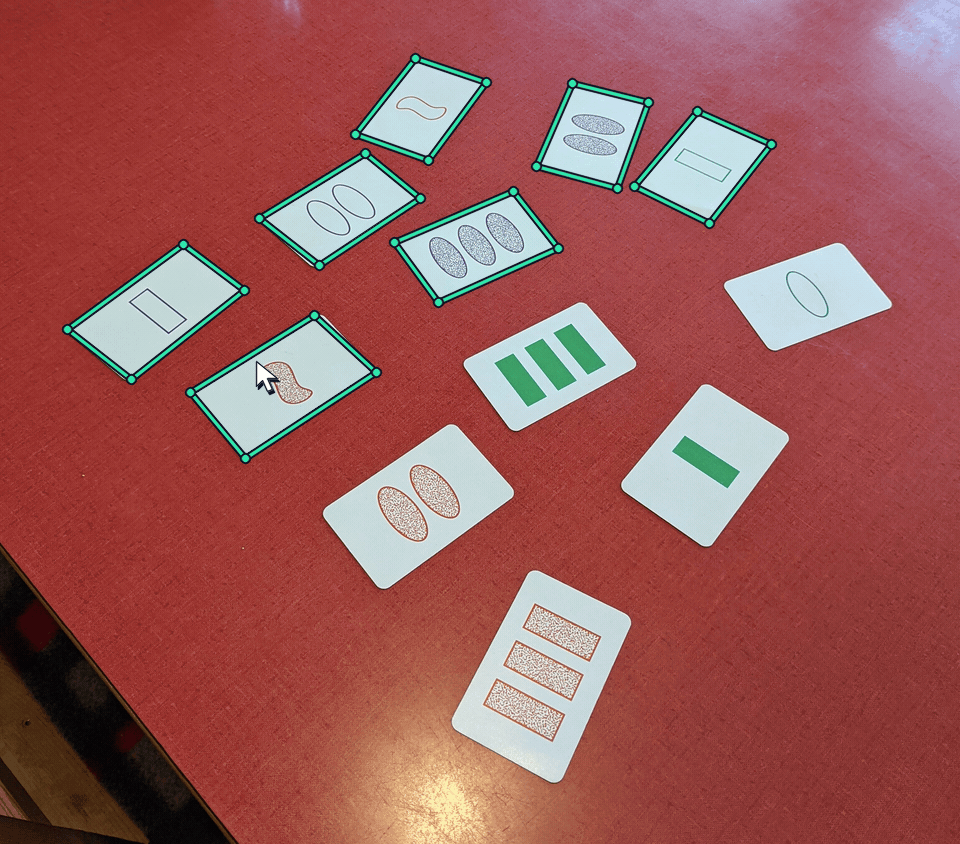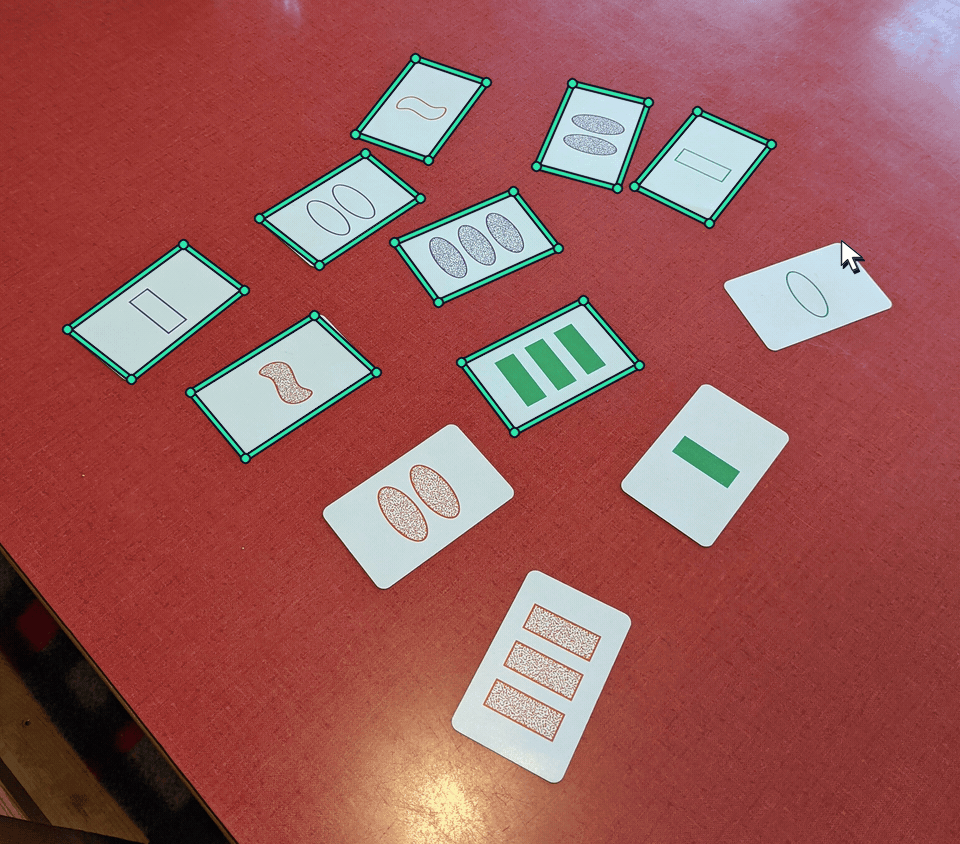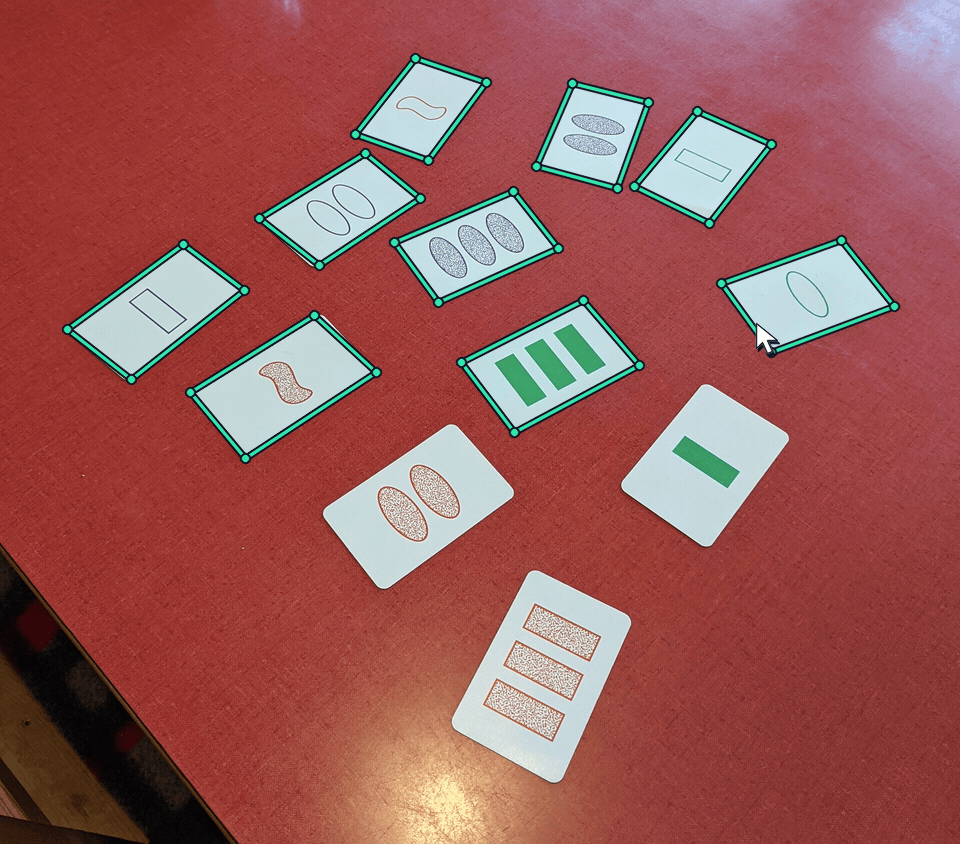
Manual annotation process
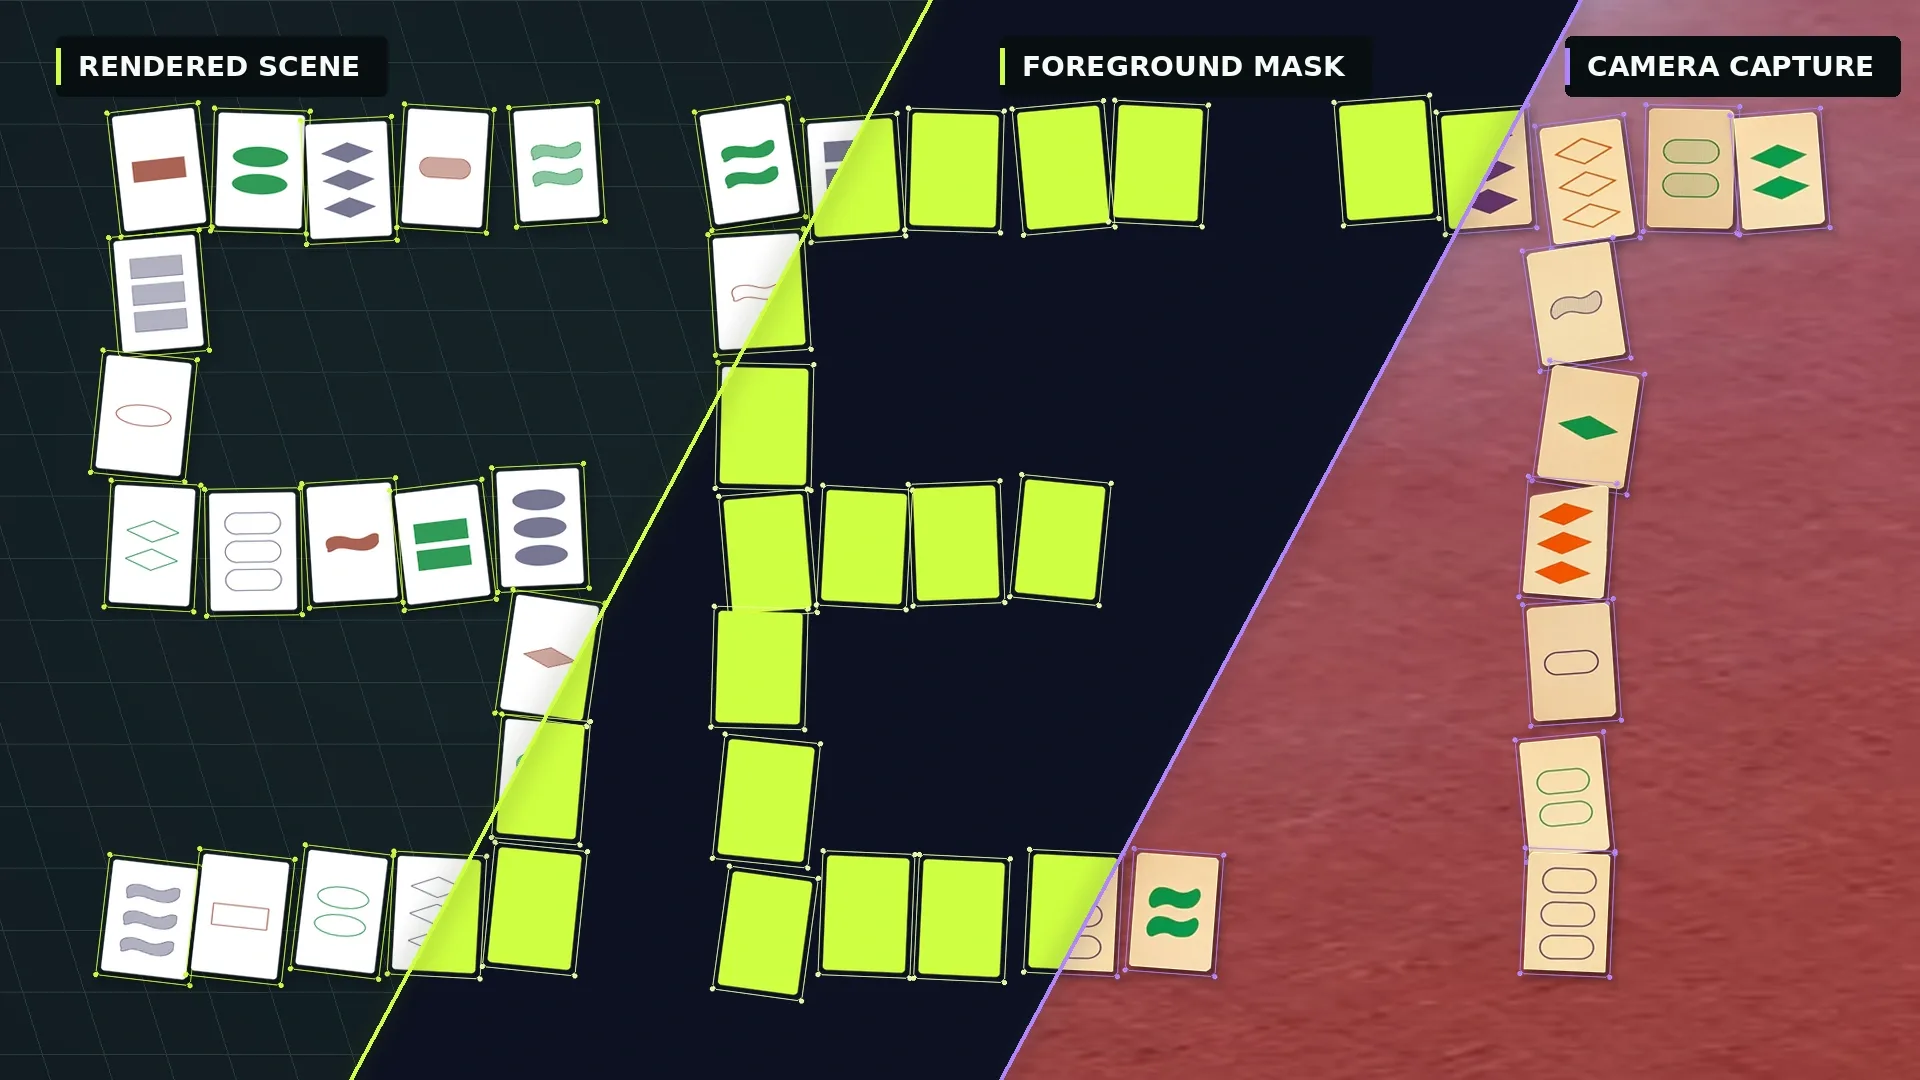
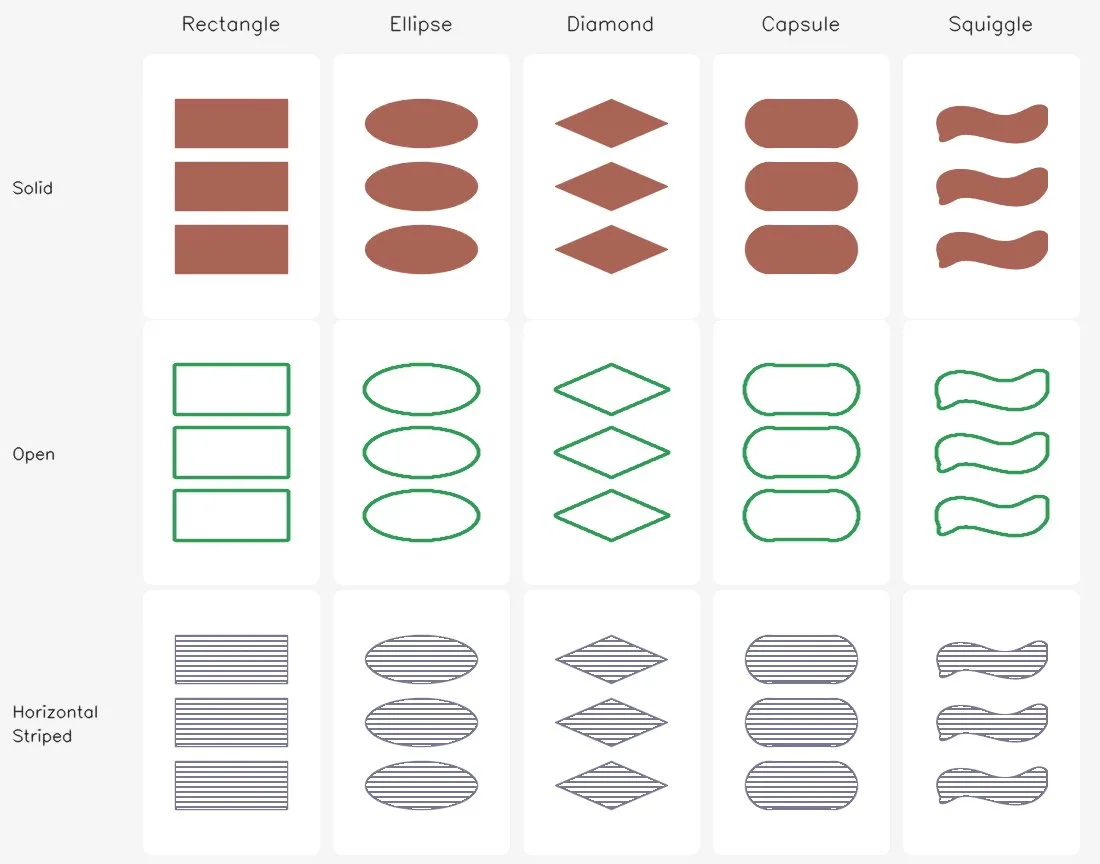
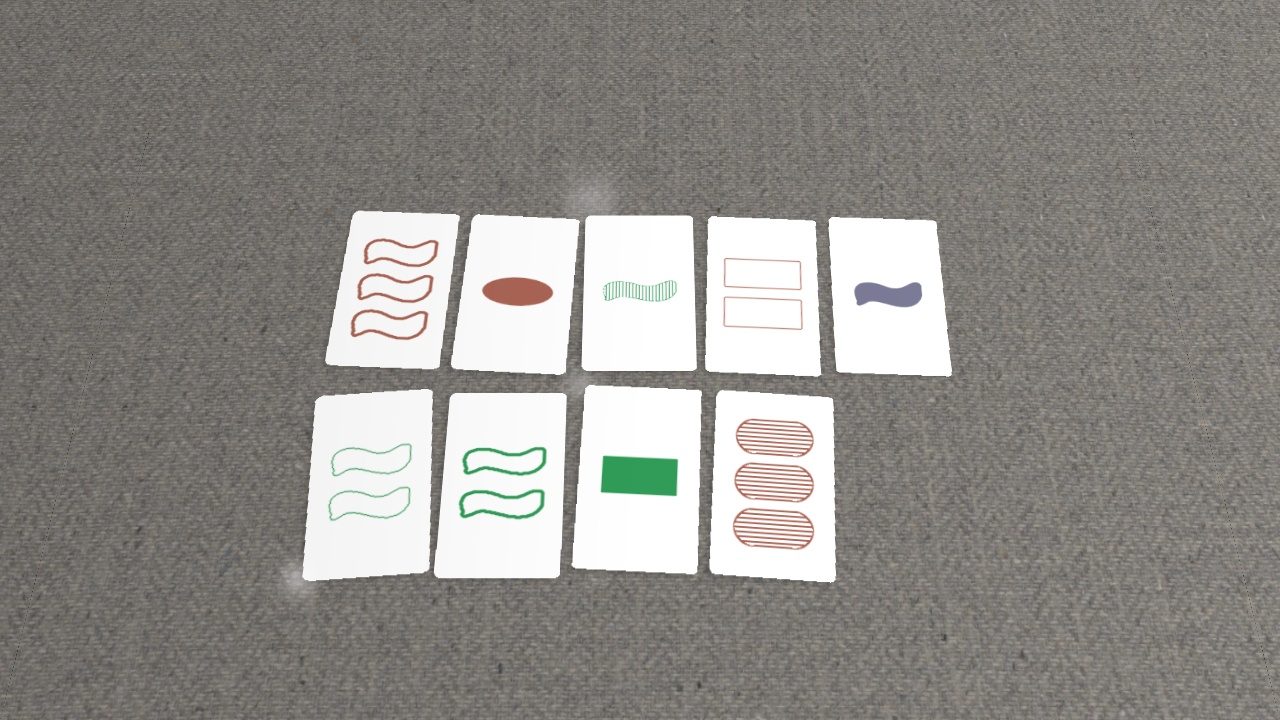
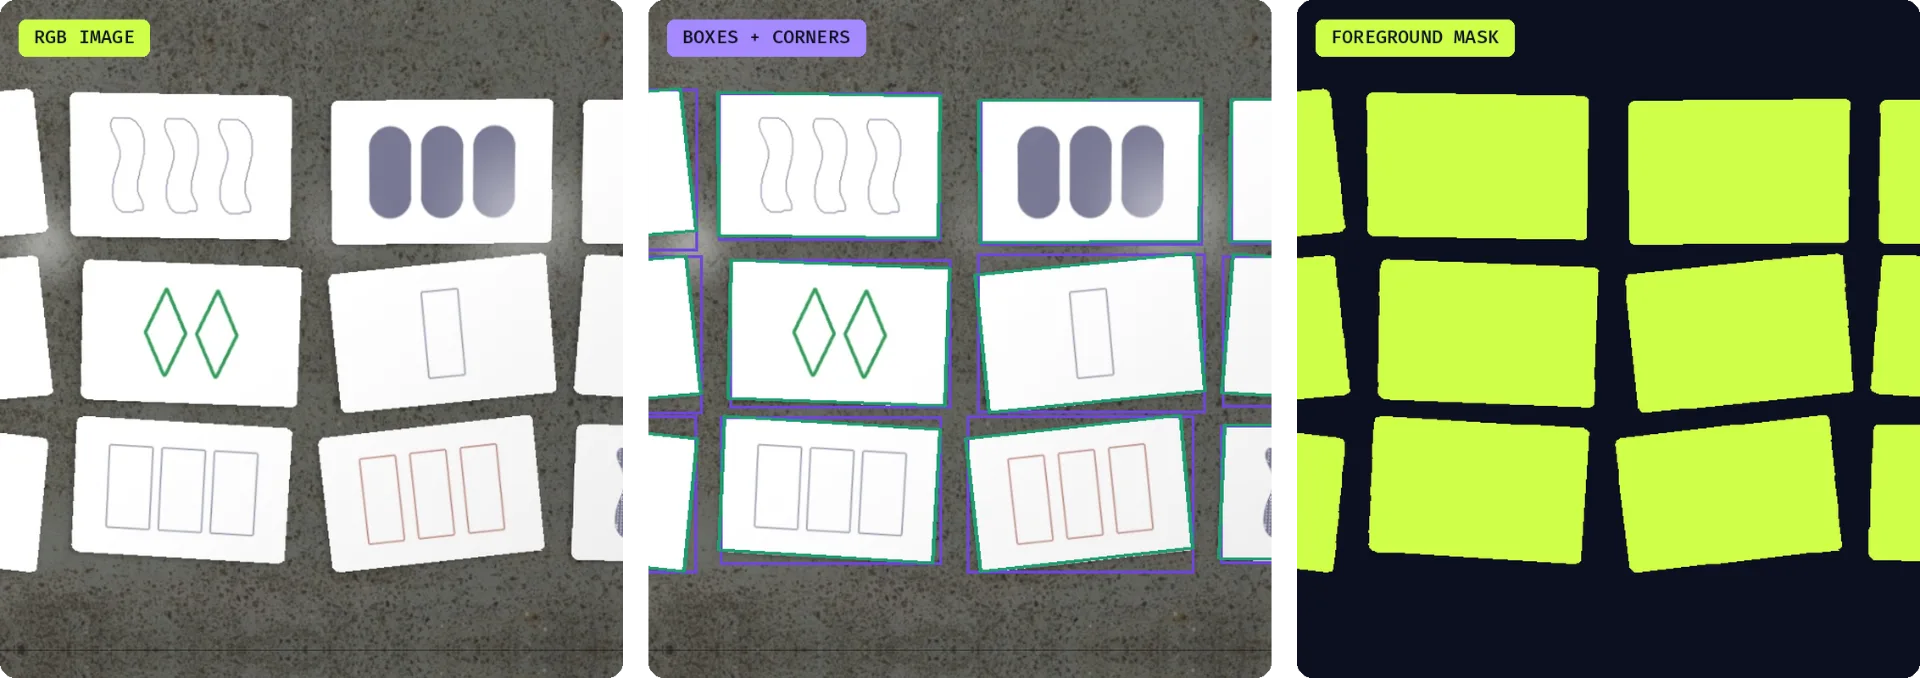
A great way to get to a lot of data with perfect labels is to synthetically generate the data. This way, you can already have the ground truth annotation by design. A big challenge with doing this for computer vision tasks is how well this synthetic data can be used to train models that generalize to real-world data.…