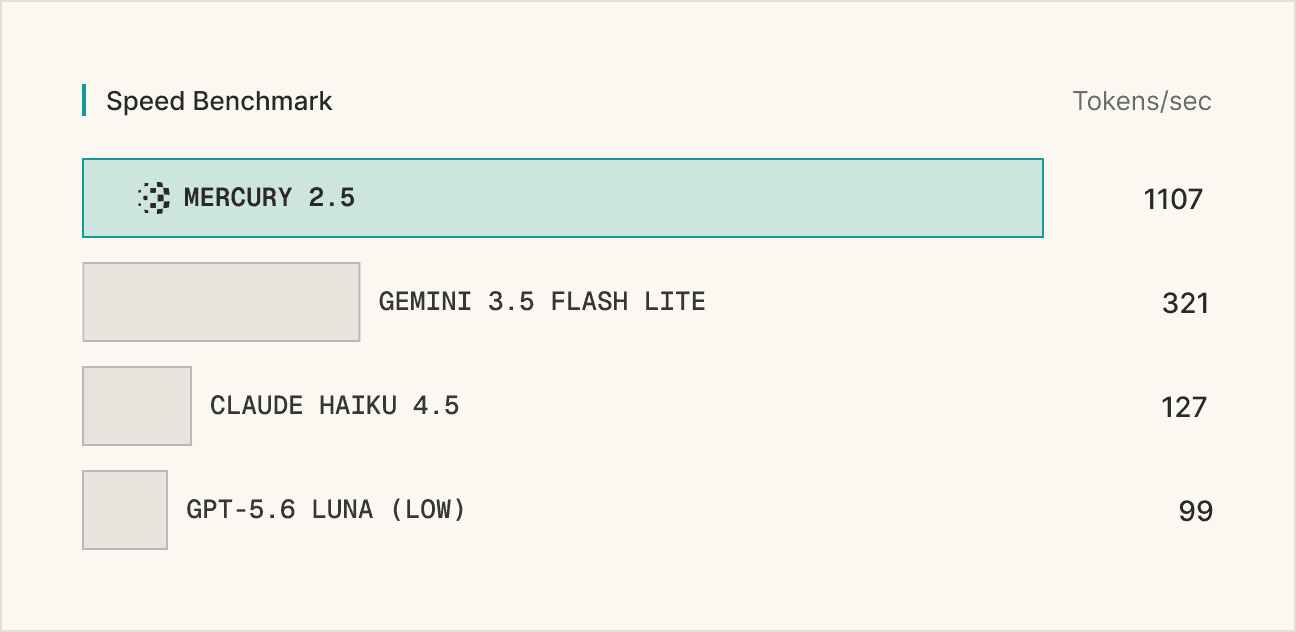
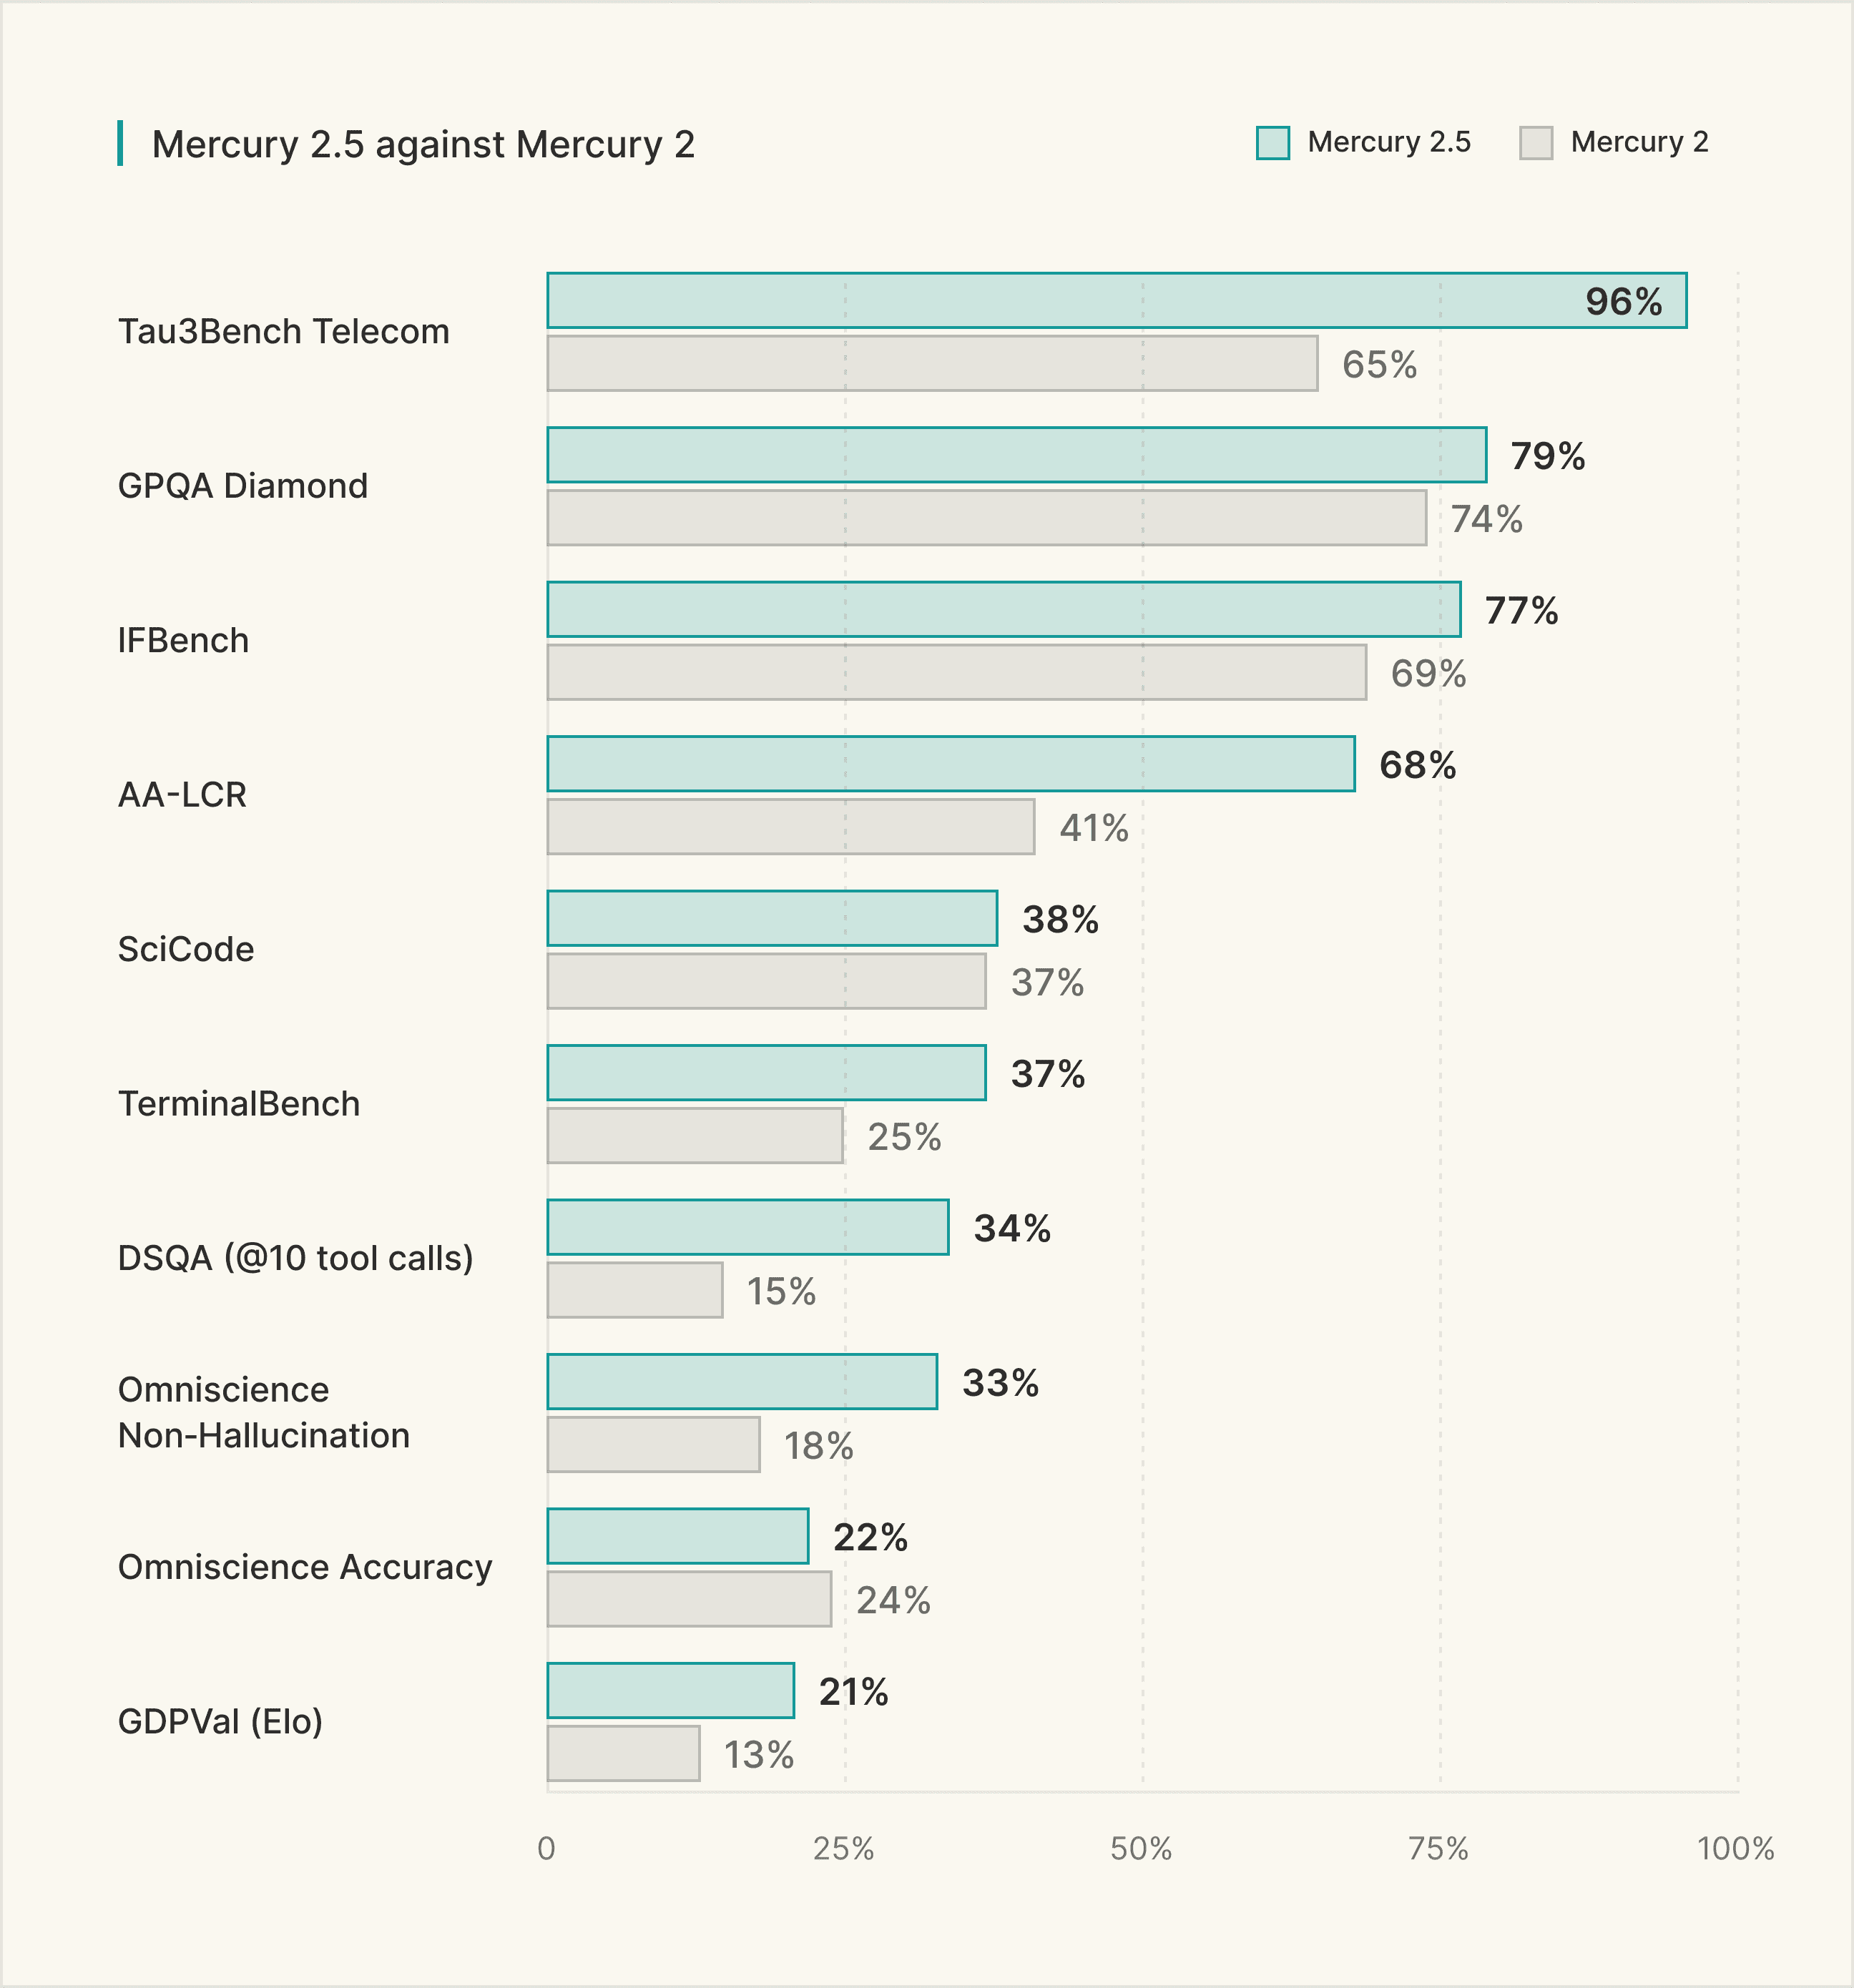
Today, we’re releasing Mercury 2.5, our most capable production model yet. It is a significant step up in quality over Mercury 2, with the same low-latency, low-cost serving profile. Since Mercury 2’s launch, thousands of developers have built with it, dozens of enterprises have put it into production, and usage has grown over an order of magnitude. It now serves latency-sensitive workloads across search, voice, and coding products. Those workloads gave us a clearer signal than benchmarks alone. We used customer feedback and production failure cases to sharpen the evals and focus training. Mercury 2.5 is the first result of that loop. What changed Mercury 2.5 is the most capable diffusion LLM on the market. To our knowledge, it is the largest diffusion language model ever trained. Quality: 40% increase in intelligence from Mercury 2.…