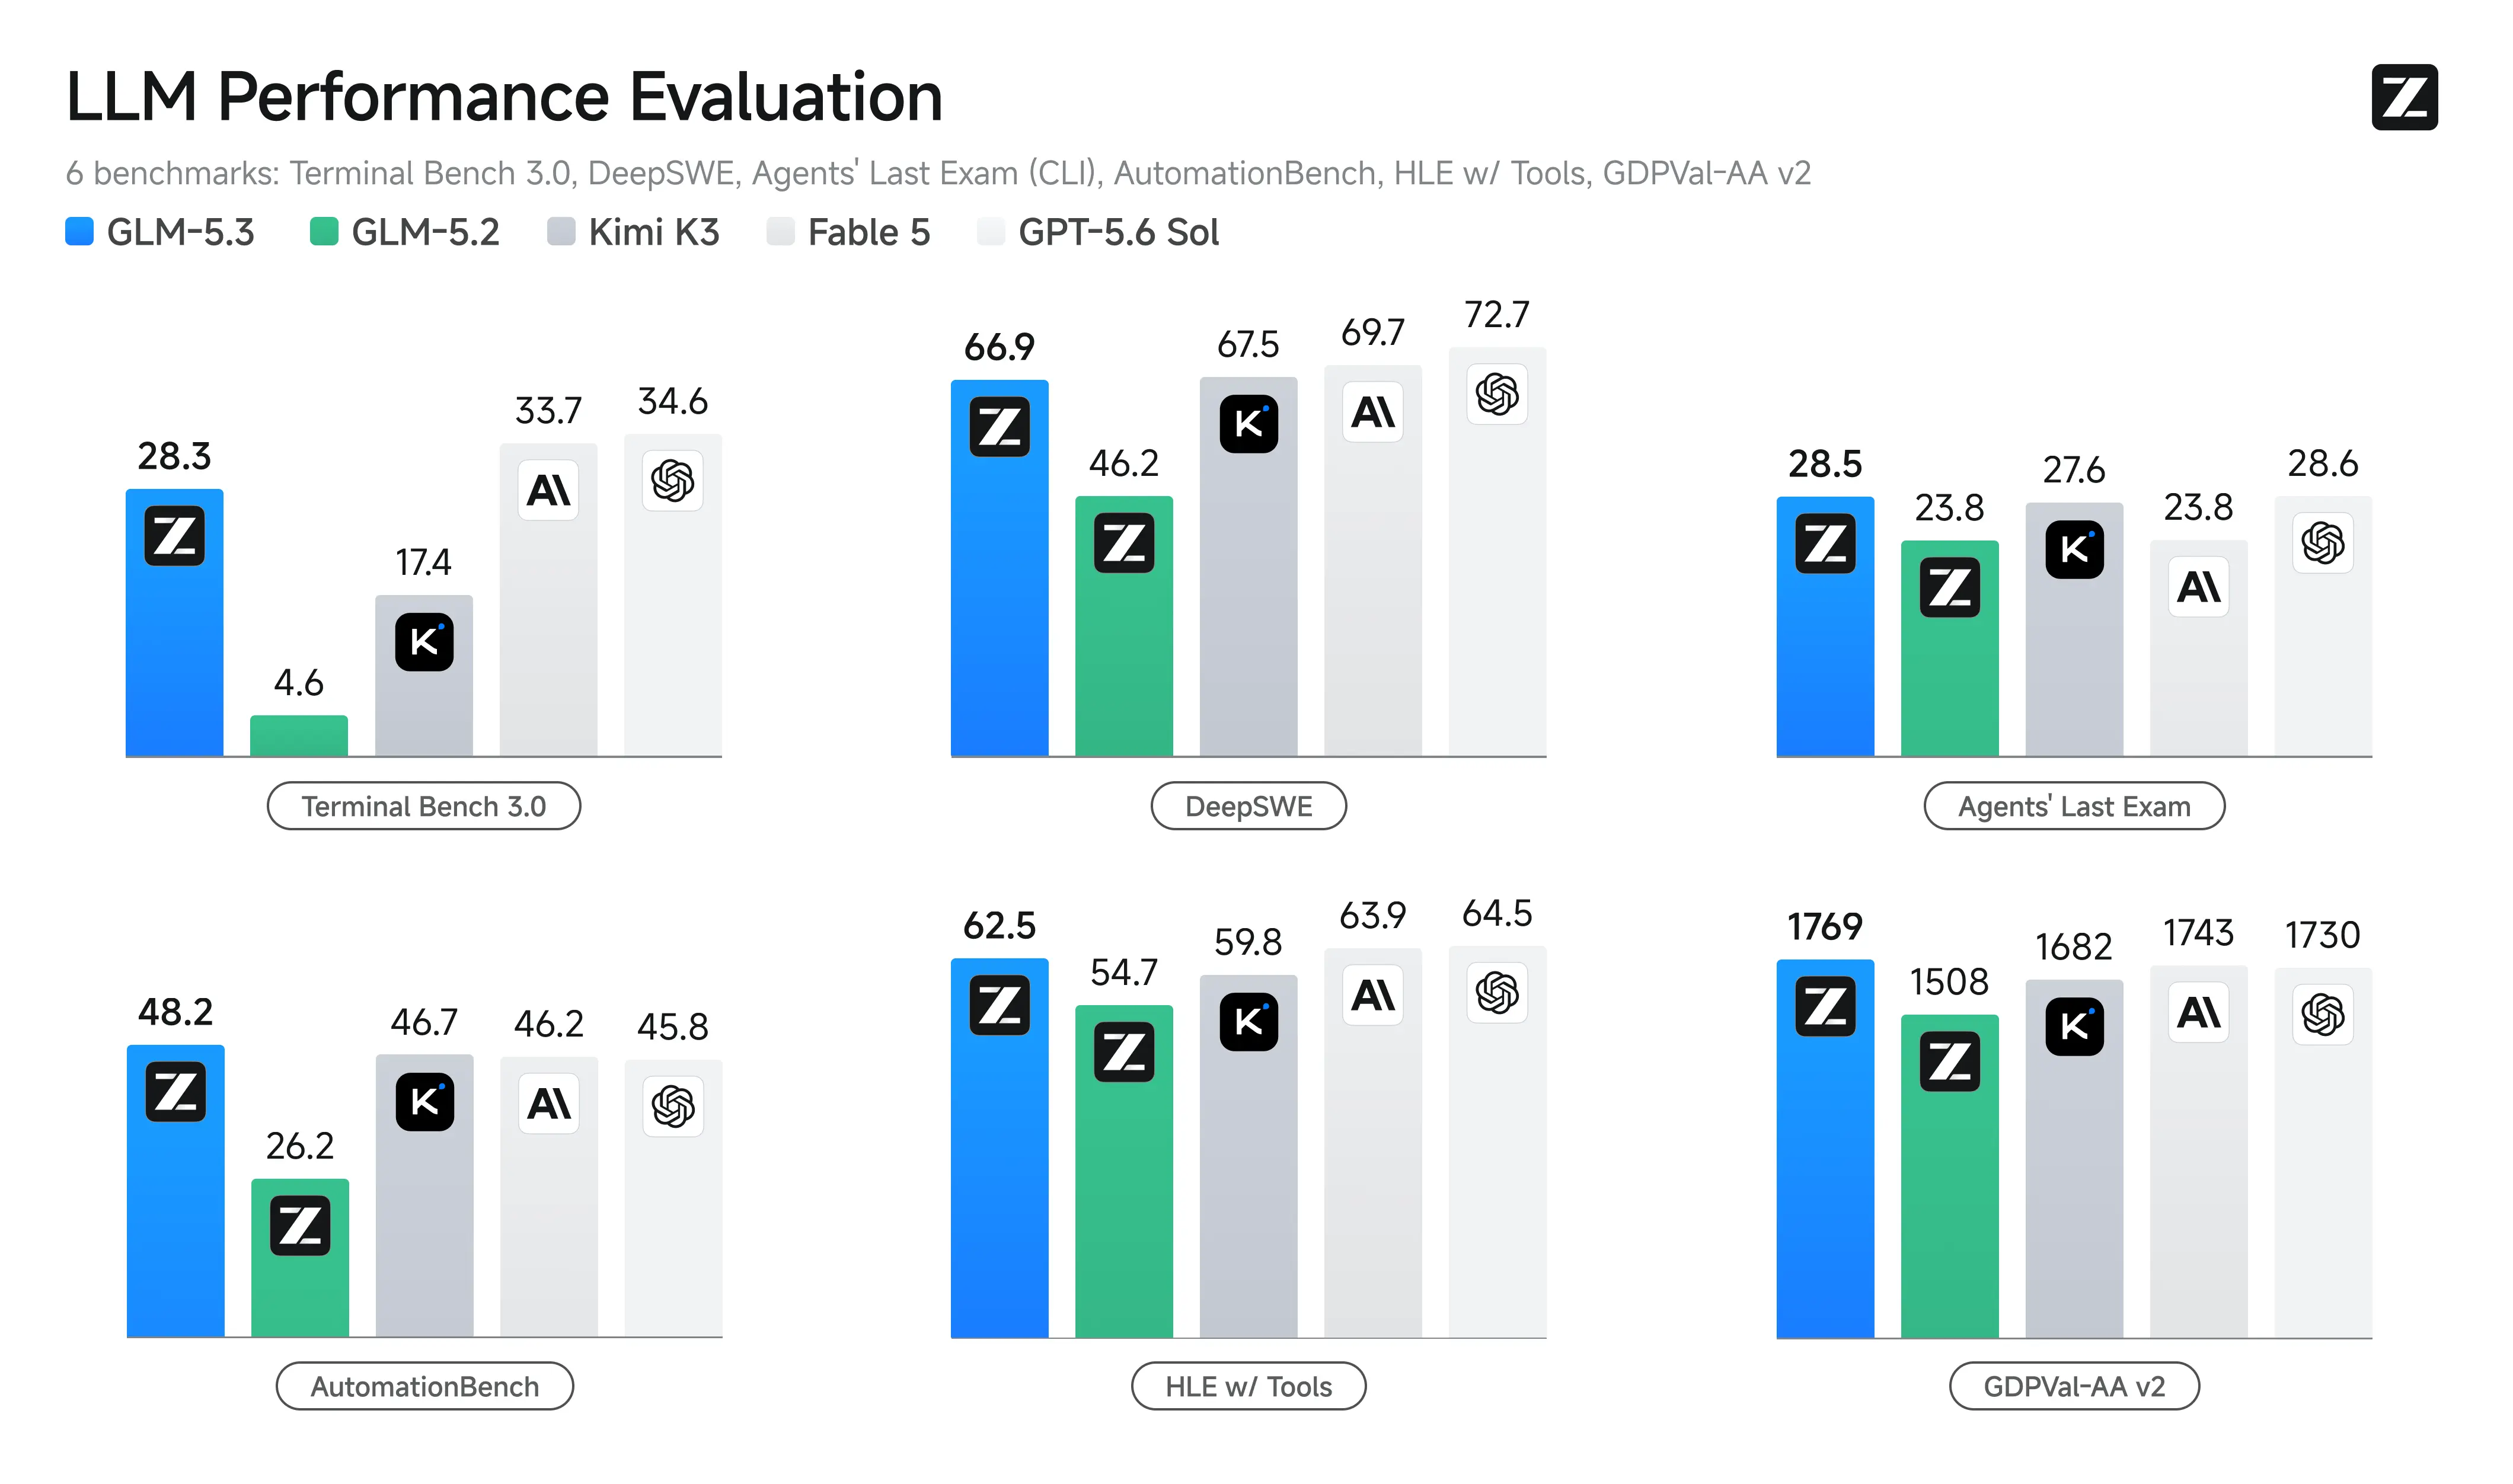
GLM-5.3 uses the same base model as GLM-5.2 — every gain comes from post-training. Compared with GLM-5.2, it is much better at complex coding and long-horizon tasks:
Stronger Coding: GLM-5.3 is the most capable open-weights model for coding, with a 50% improvement over GLM-5.2 on our in-house Z.ai Code Bench. It also achieve open-source SOTA on public benchmarks including Terminal Bench 3.0 and Agents' Last Exam.
Emergent Cyber Capability: As we scaled post-training, cyber capability developed faster than we expected. GLM-5.3 is state of the art on CyberGym for vulnerability discovery, and its gains are largest further up the exploitation chain, where it more than doubles GLM-5.2 on exploitation benchmarks.
Benchmark
Benchmark GLM-5.3 GLM-5.2 Kimi K3 DeepSeek-V4 Pro-0813 Qwen3.8-Max Opus 4.8 Fable 5 (w/ fallback) GPT-5.6 Sol
Terminal Bench 2.1 88.2 81.0 88.3 87.9 86.6 85.0 88.0 88.8
Terminal Bench 3.0 28.3 4.6 17.4 – – 21.1 33.7 34.6
DeepSWE (v1.1) 66.9 46.2 67.5 62.7 56.6 58.0 69.7 72.7
NL2Repo 58.0…