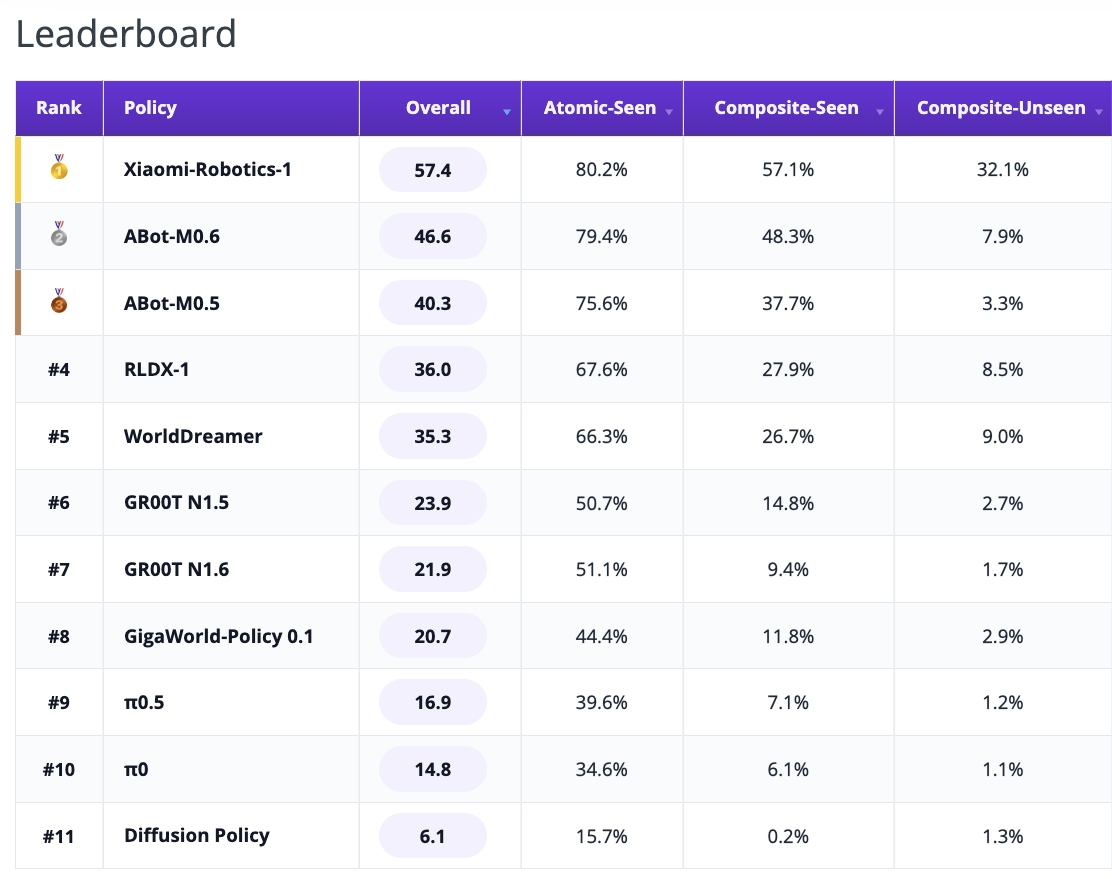
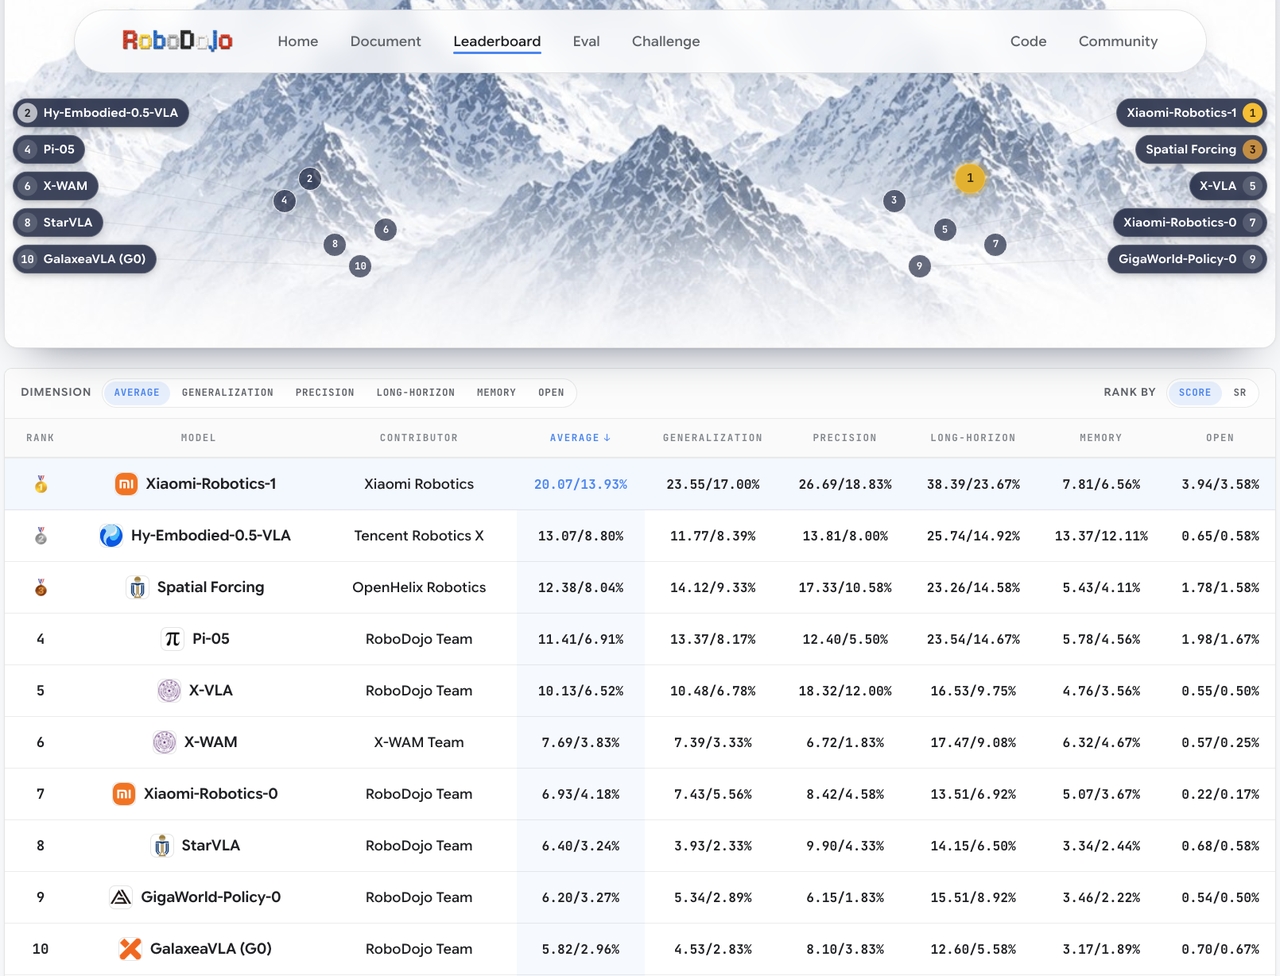
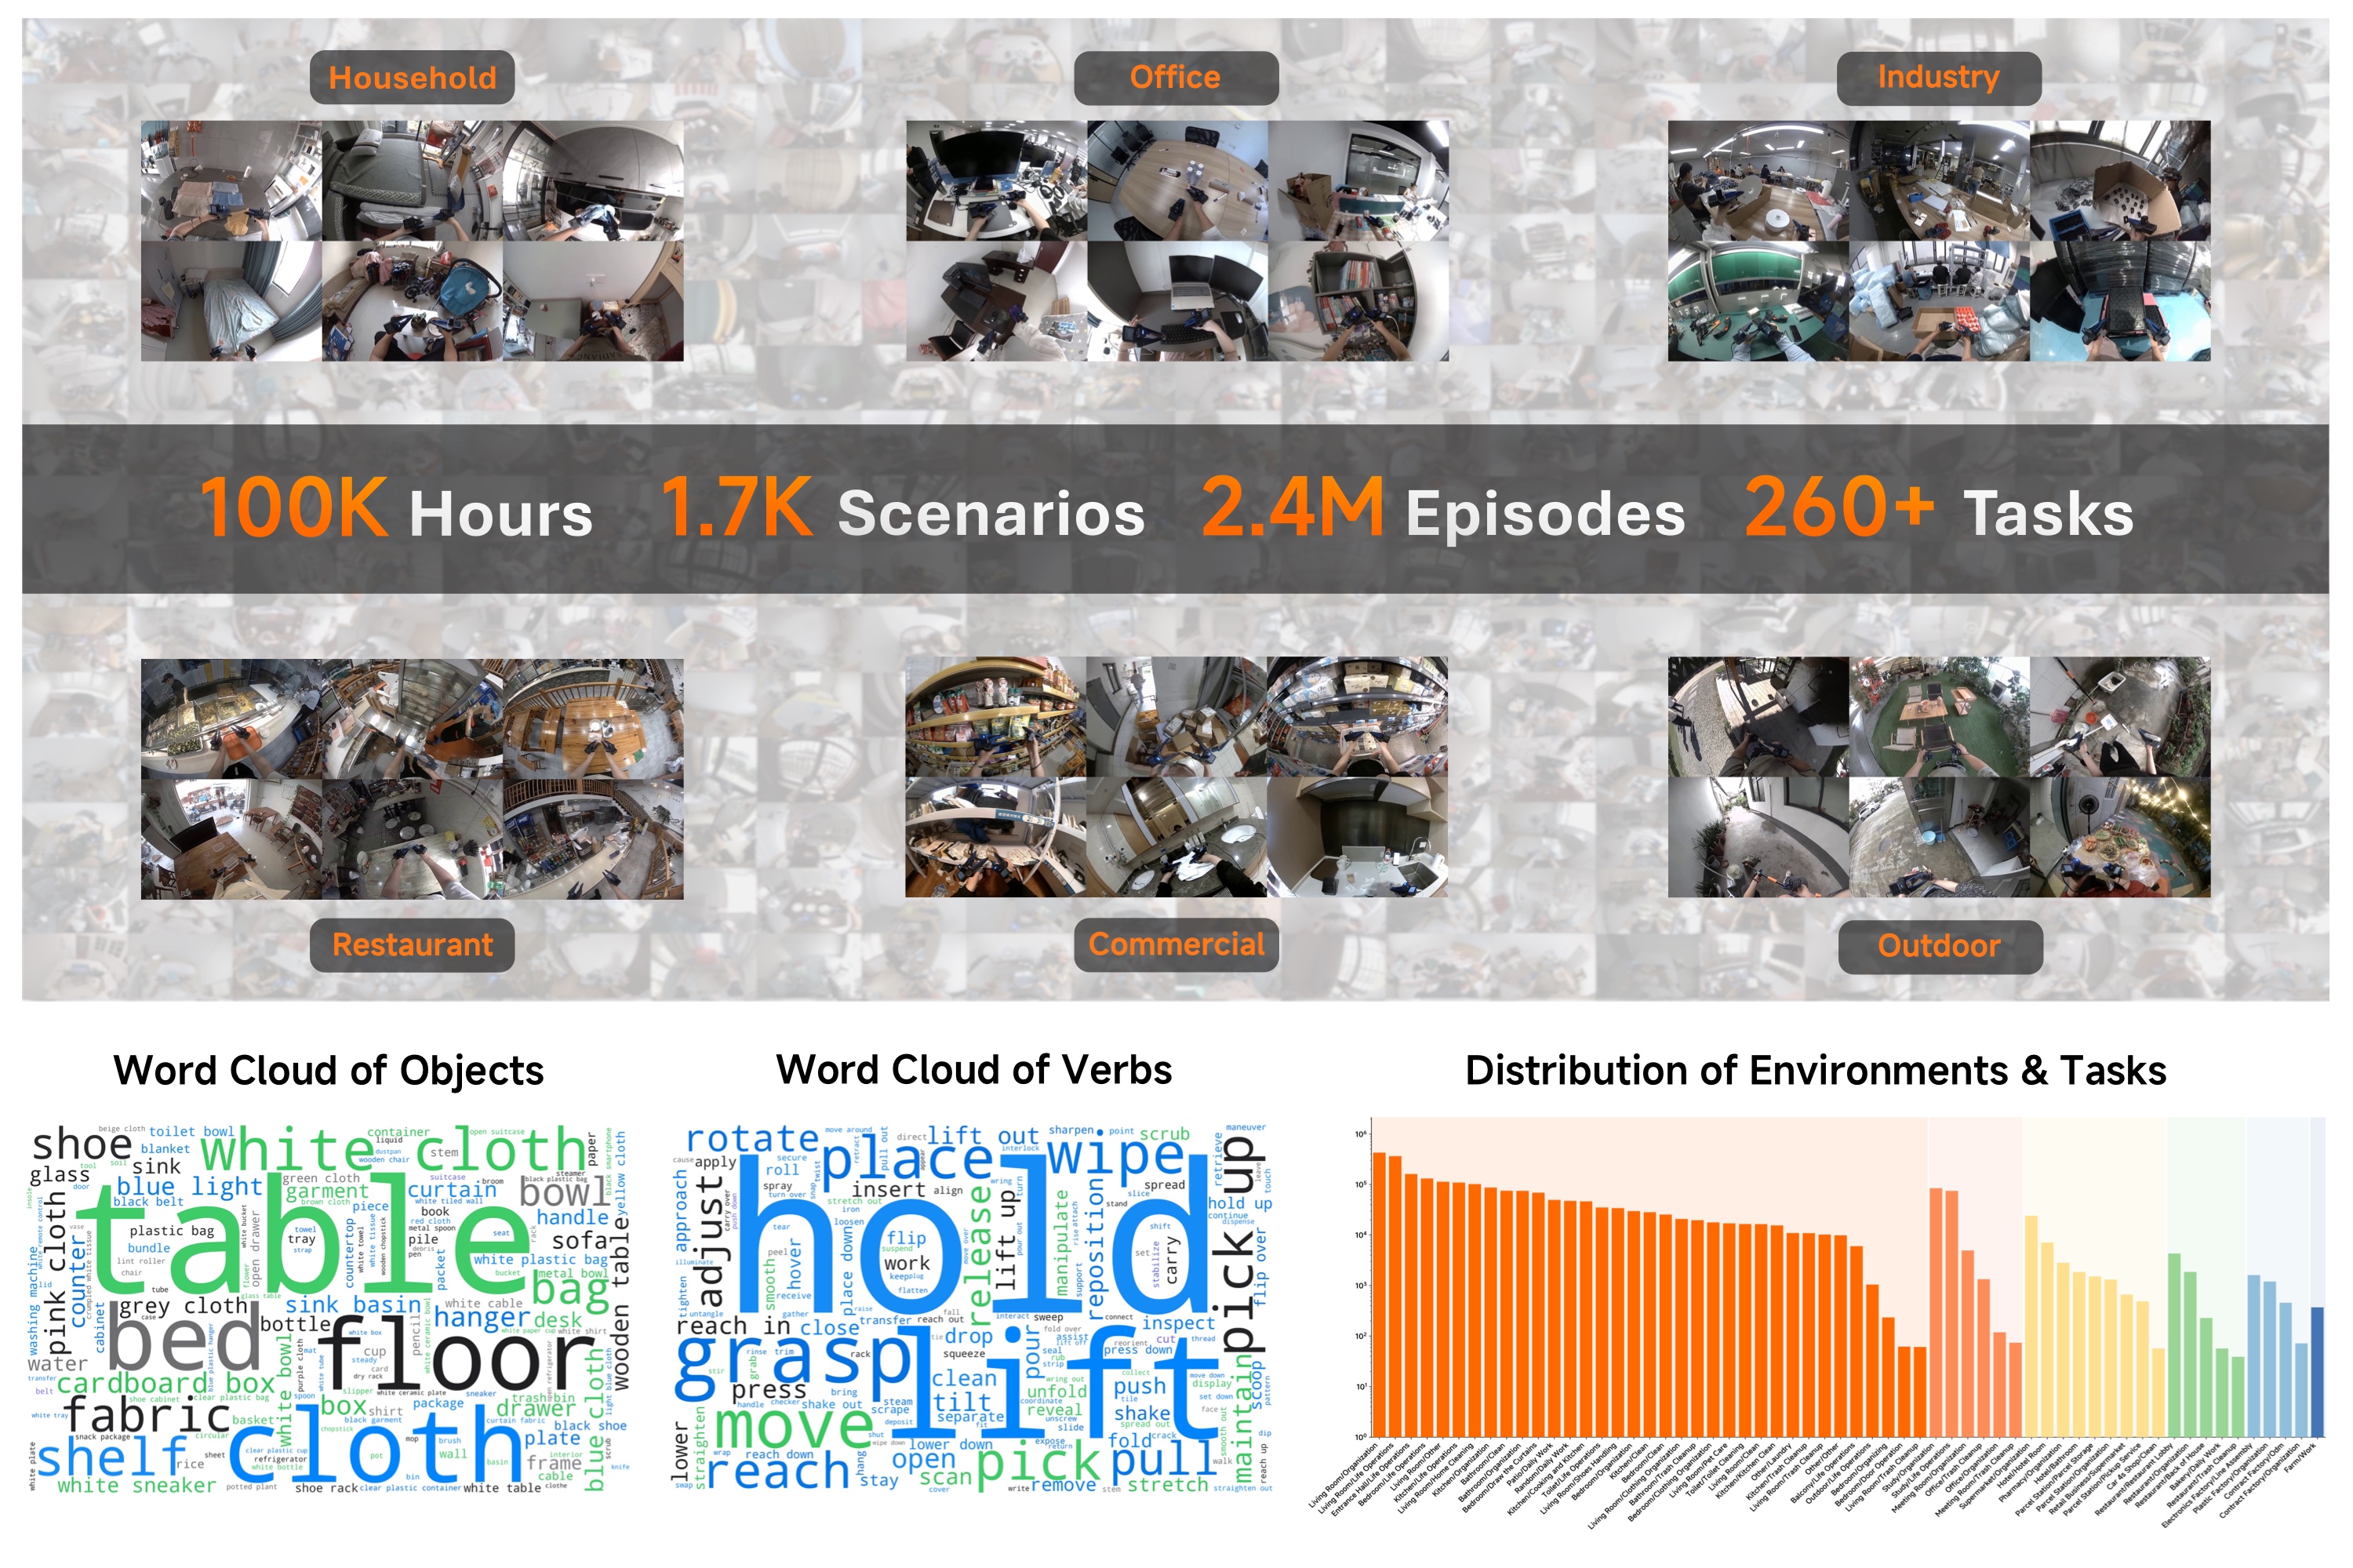
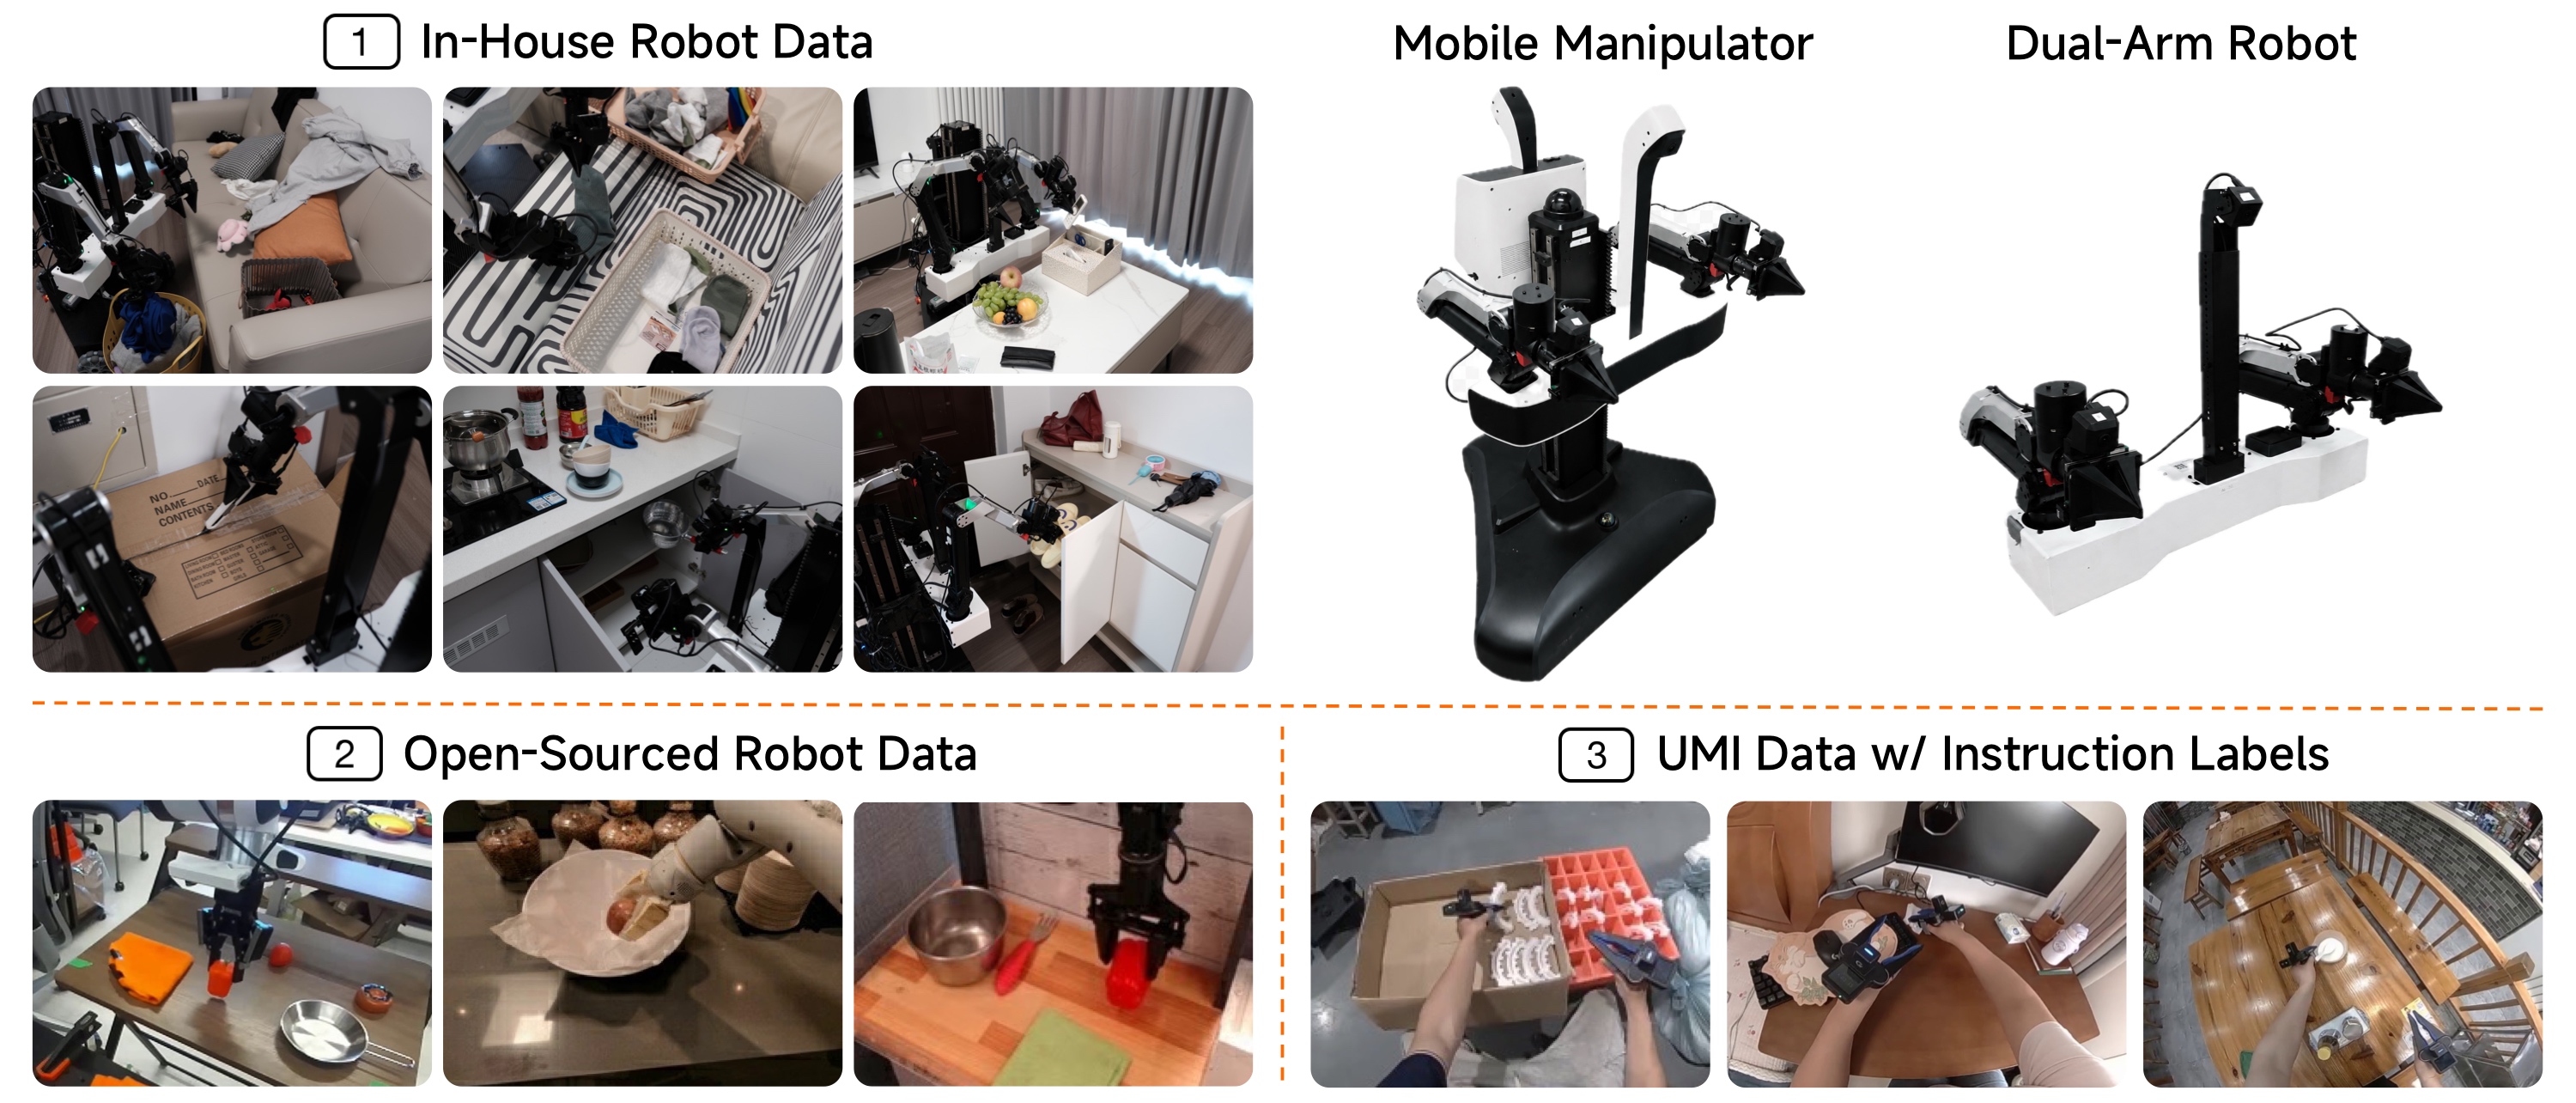
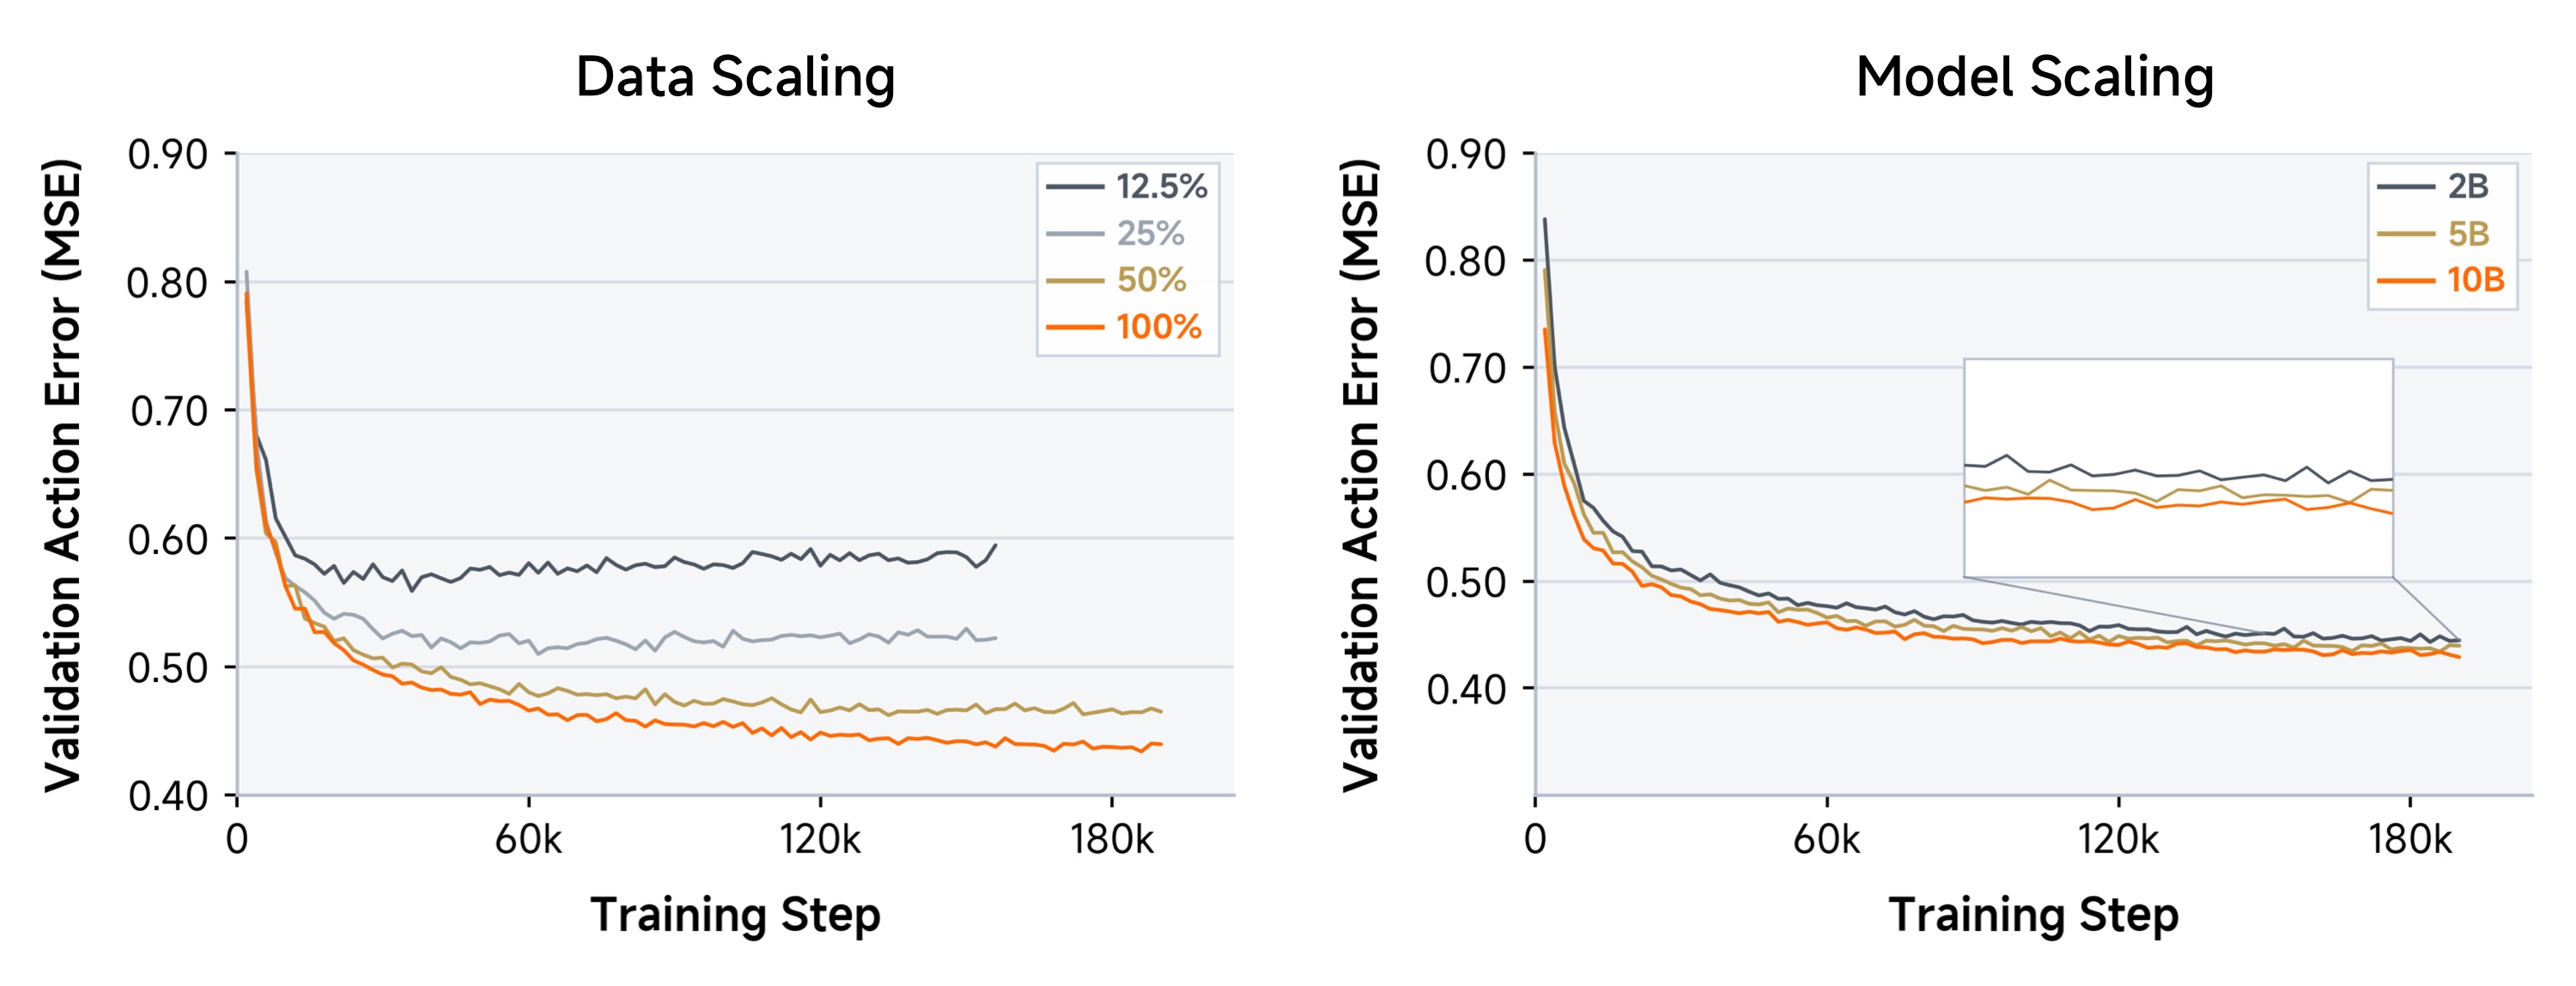
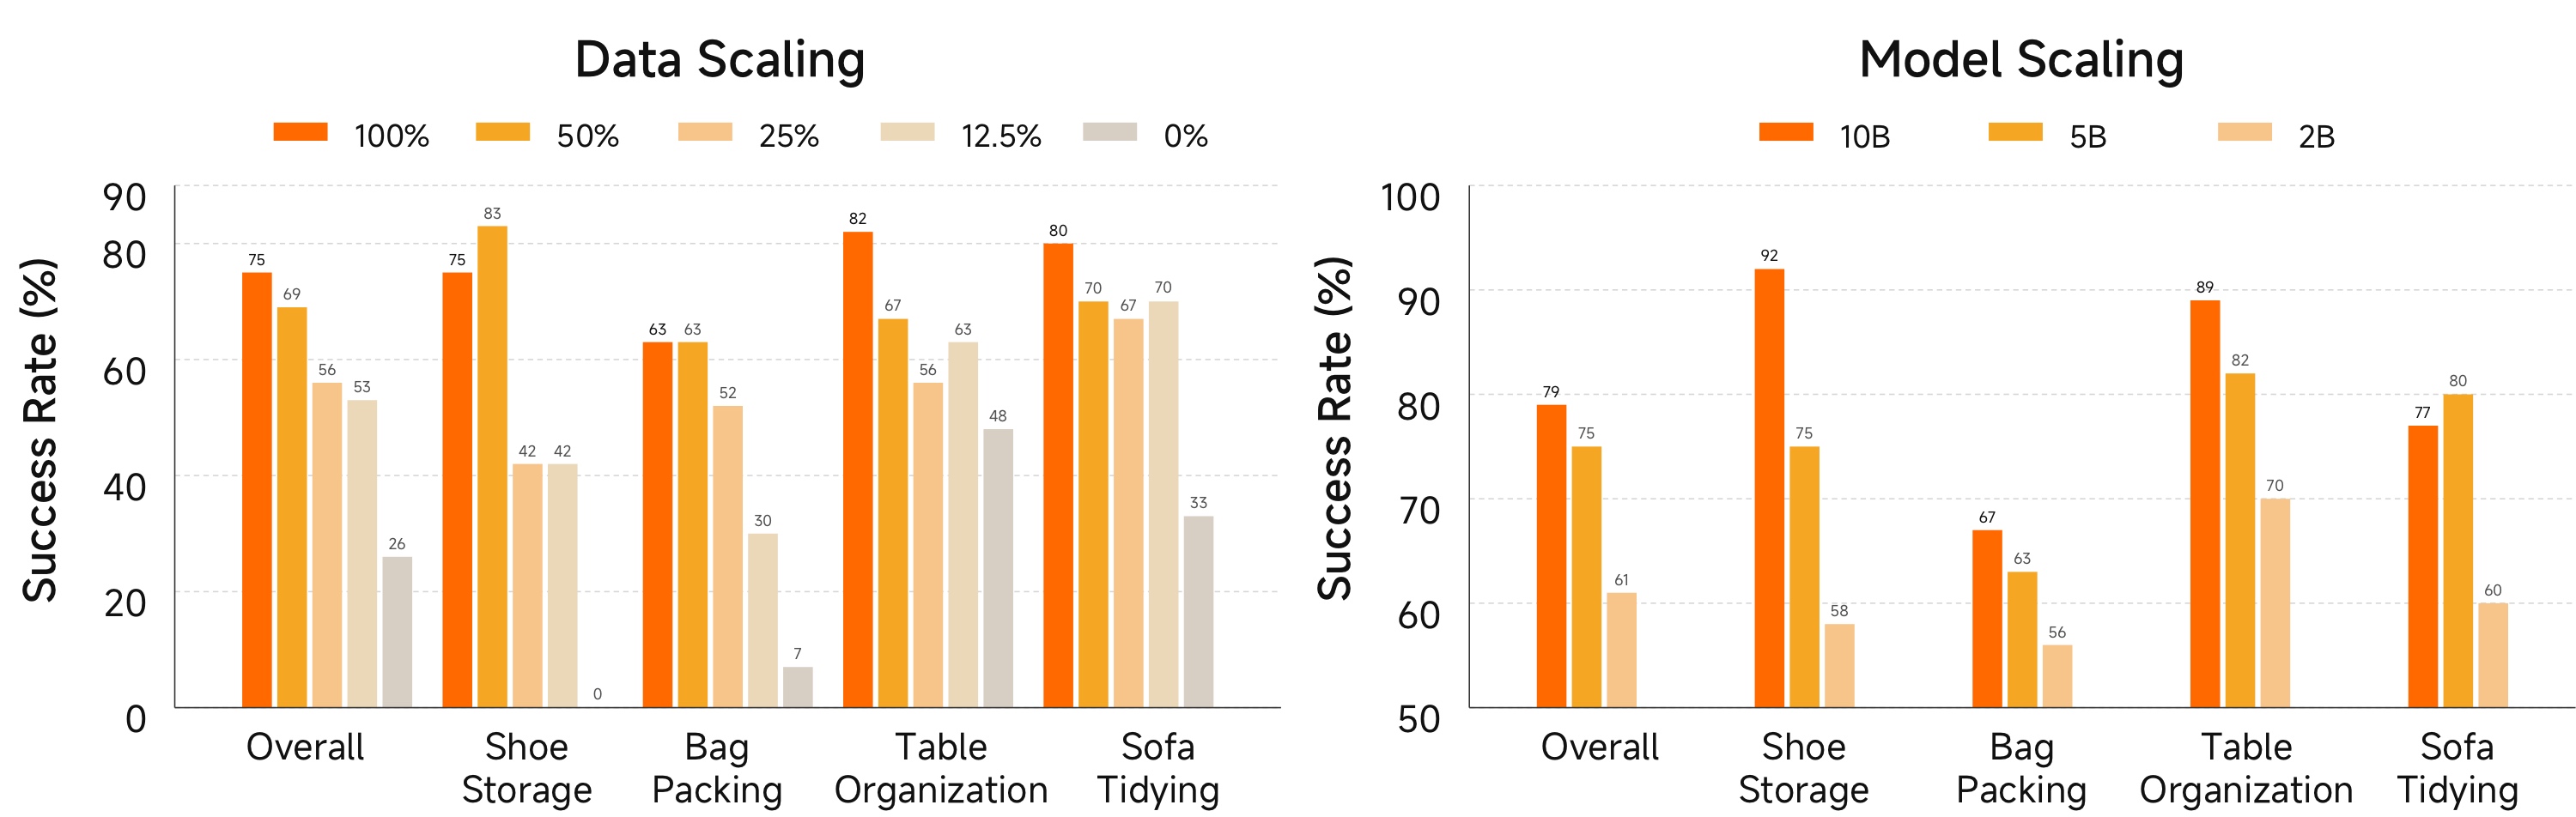
Breaking the data barrier. Scaling robot policy models with embodiment-free pre-training. Foundation models in language and vision keep moving the frontier by riding empirical scaling laws: capability tracks data, parameters, and compute. Robotics has missed out. Large-scale, high-quality data is hard to come by, and that scarcity, more than anything else, has capped how far policy models could scale. What robots can do under genuinely large-scale training remained largely an open question. We take a step toward answering it. Xiaomi-Robotics-1 combines large-scale embodiment-free (UMI) pre-training with a modest amount of real-robot data in a post-training stage. We study how the model behaves as it scales. Data Everything Xiaomi-Robotics-1 can do starts from data. For pre-training, we use 100,000 hours of embodiment-free (UMI) trajectories spanning more than 1,700 scenarios (household, commercial premises, industrial sites, and outdoor spaces), covering a diverse range of tasks.…