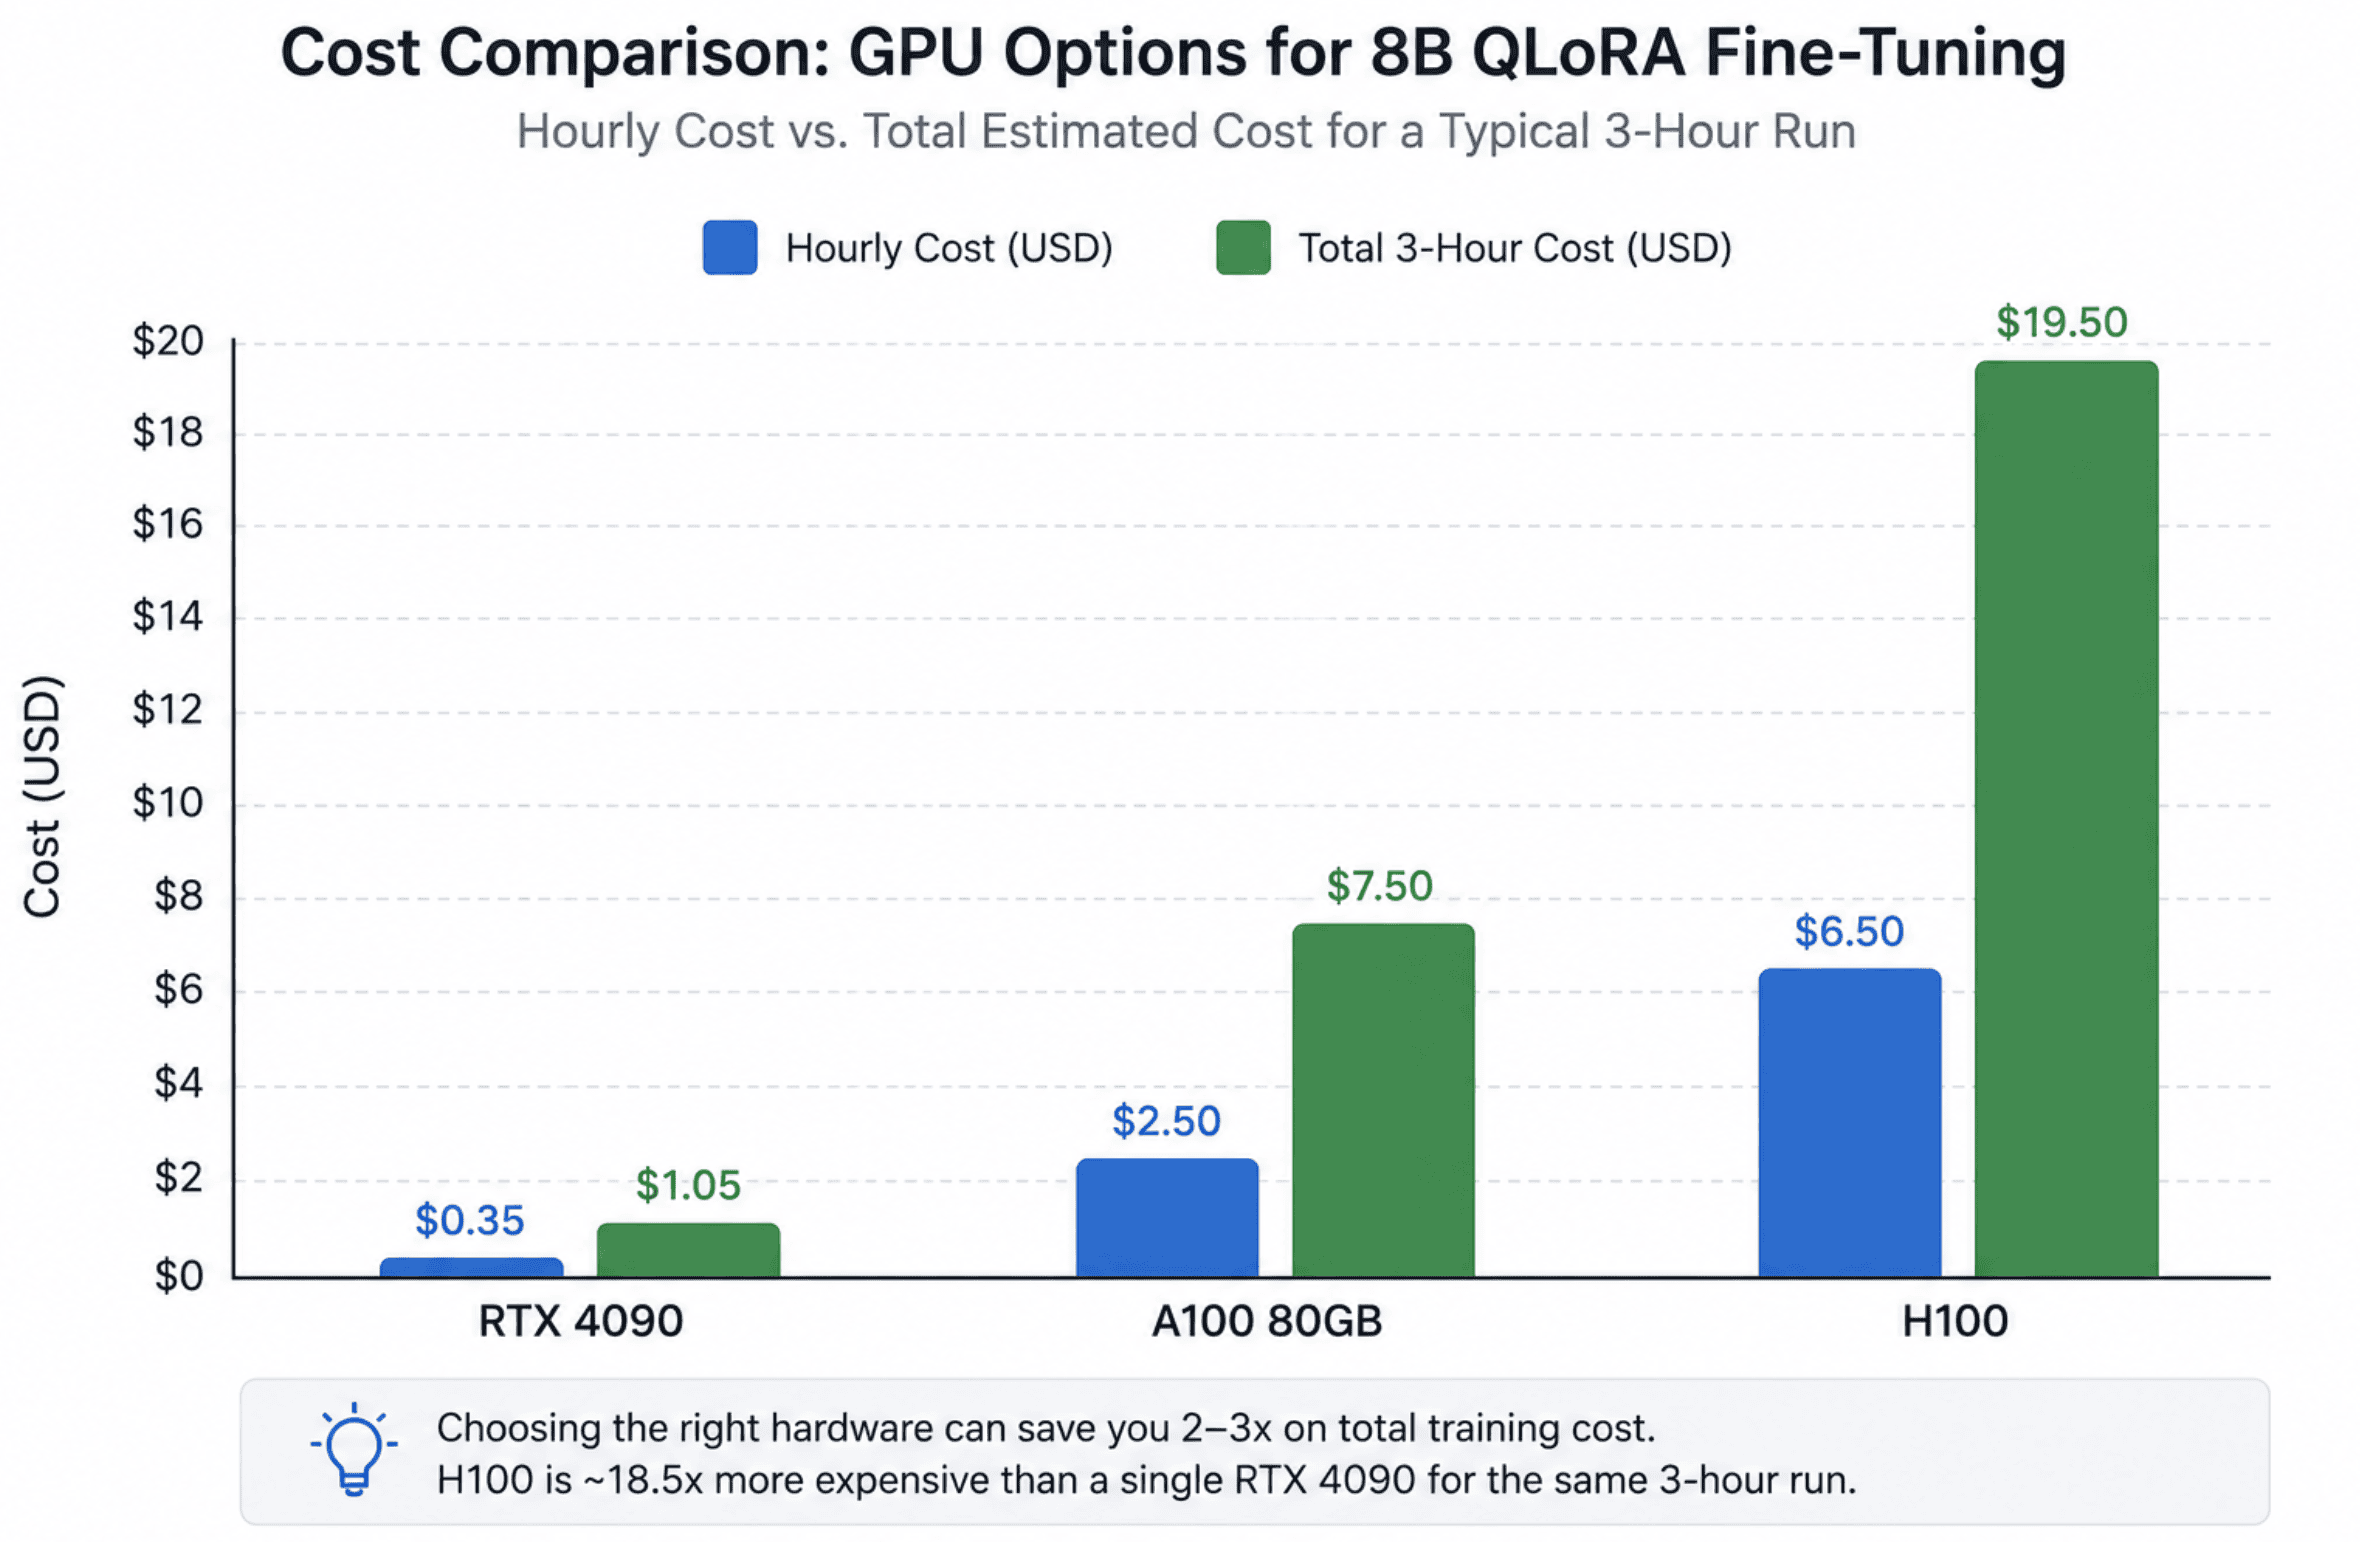
A team gets a quote from a vendor: fifty thousand dollars to build them a " custom AI model " trained on their support tickets. Someone on the team, skeptical, spends a weekend testing the actual technique that quote was based on. The real GPU bill comes out under ten dollars.
That gap isn't a rounding error, and it isn't unusual. Fine-tuning large language models (LLMs) has a reputation as a research-lab-only activity, and for full fine-tuning of a frontier model from scratch, that reputation is earned: training runs at that scale really do cost tens or hundreds of millions of dollars. But adapting an existing open-weight model to a specific task is a completely different cost category now, and most of the guides explaining that gap either stop at one technique or never show real, runnable code.
This article does both.…