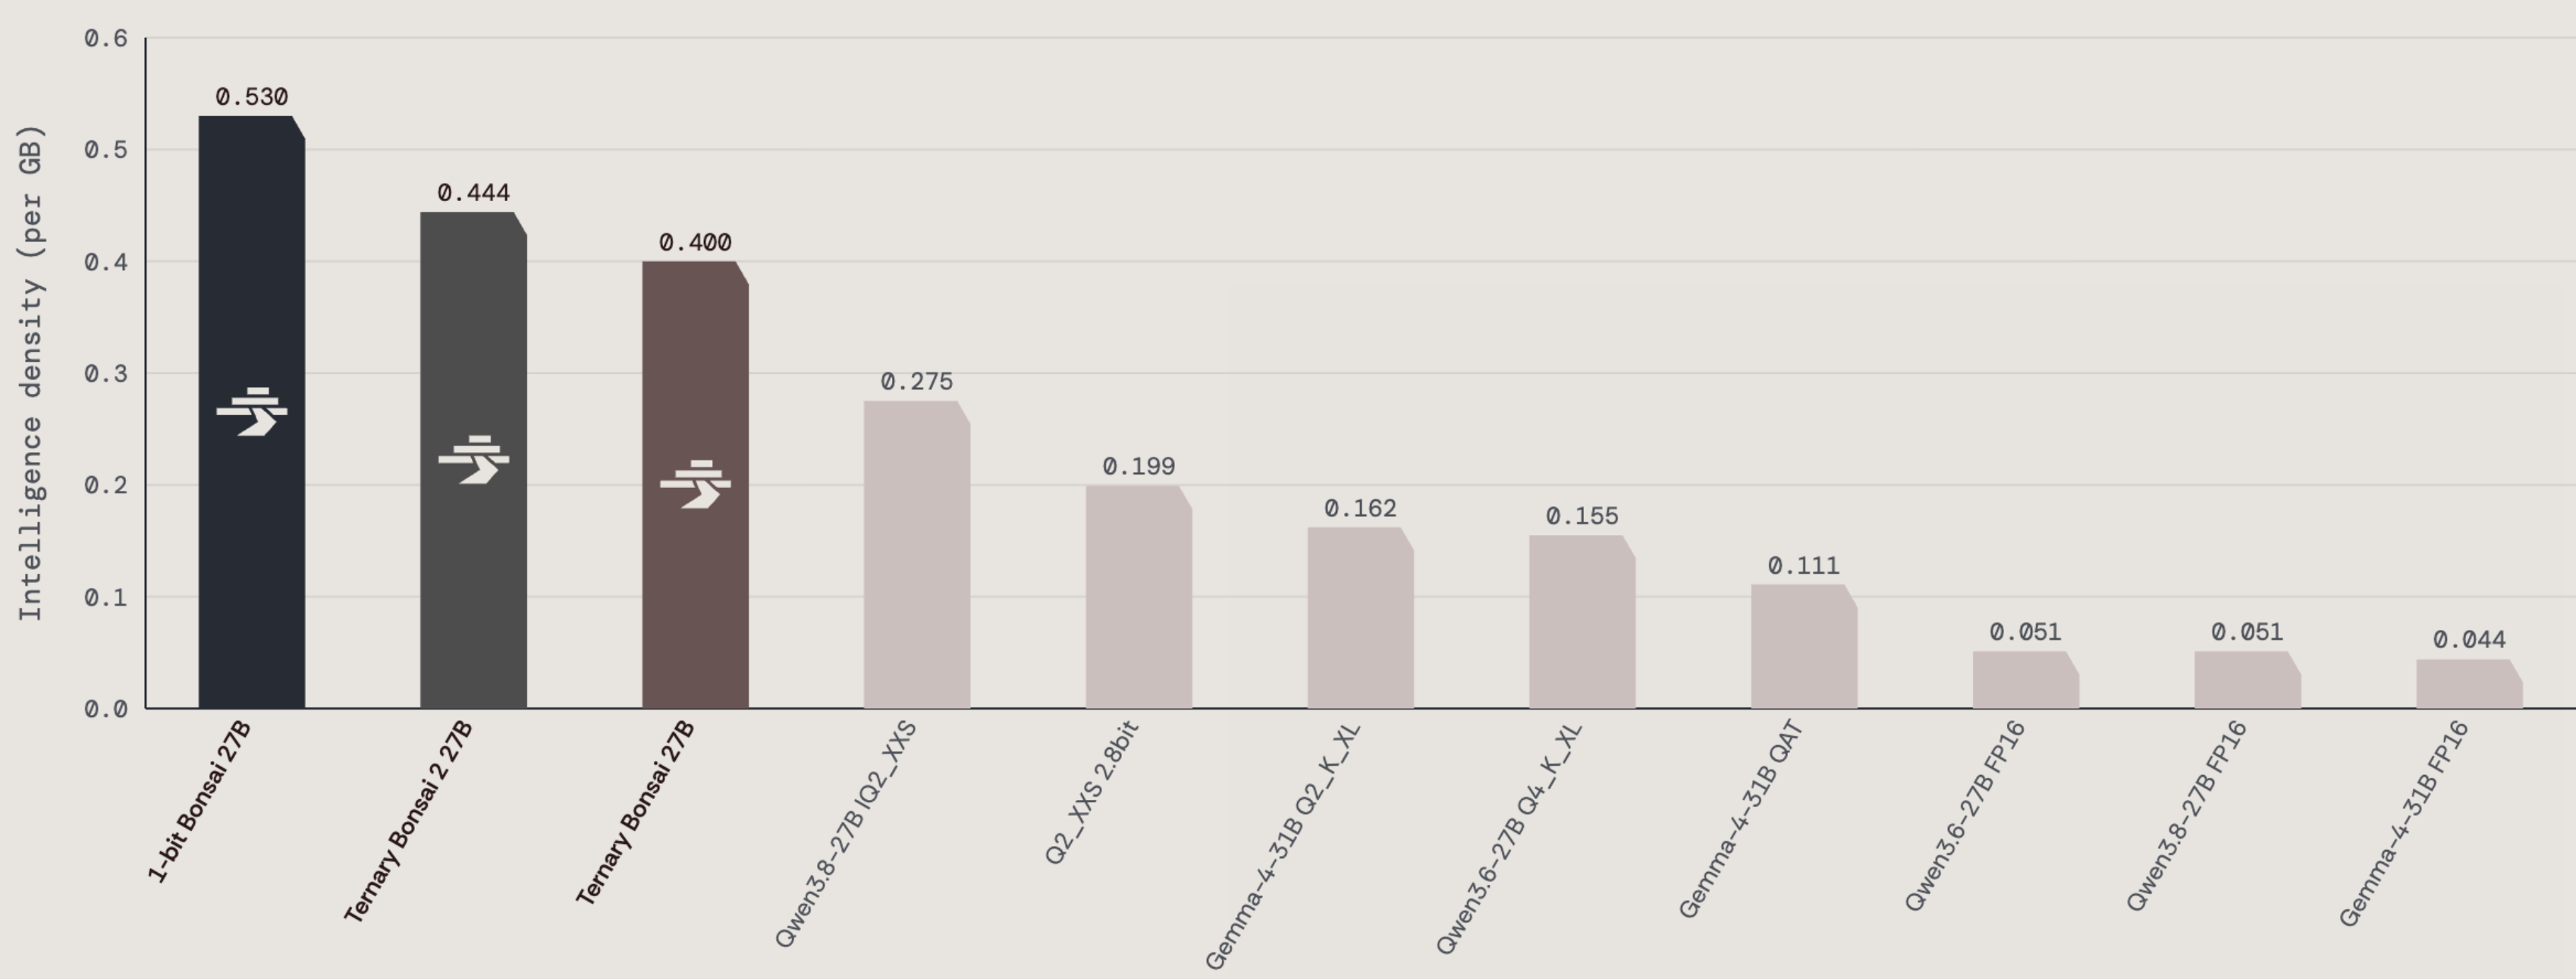
Two months ago, we released our first Bonsai 27B models and showed that a 27B-class multimodal model could be compressed enough to run efficiently on a local device. Today, we’re releasing Ternary Bonsai 2 27B, our most capable model yet. Based on Qwen3.8 27B, Ternary Bonsai 2 27B brings stronger reasoning, coding, vision, and agentic capability to the Bonsai series while preserving the deployment profile that defines it: a dramatically smaller memory footprint, high local throughput, and better energy efficiency. Ternary Bonsai 2 27B uses ternary {−1, 0, +1} weights with FP16 group-wise scaling, for 1.76 effective bits per weight and a total model footprint of 5.9GB . The low-bit representation is applied end to end across the language model. It supports a 262K-token context window , multimodal text-and-image input, and is released under the Apache 2.0 license. Against its full-precision counterpart, Ternary Bonsai 2 27B is more than 9x smaller while retaining 98.2% of aggregate benchmark performance .…