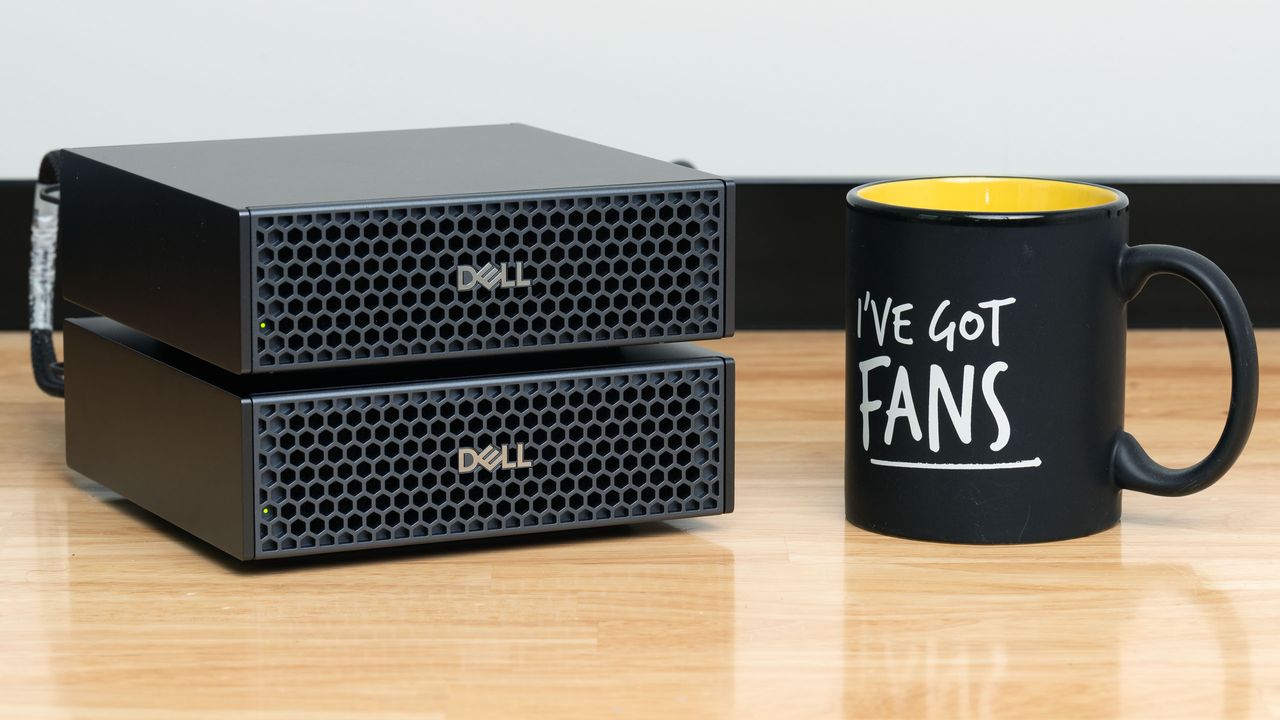
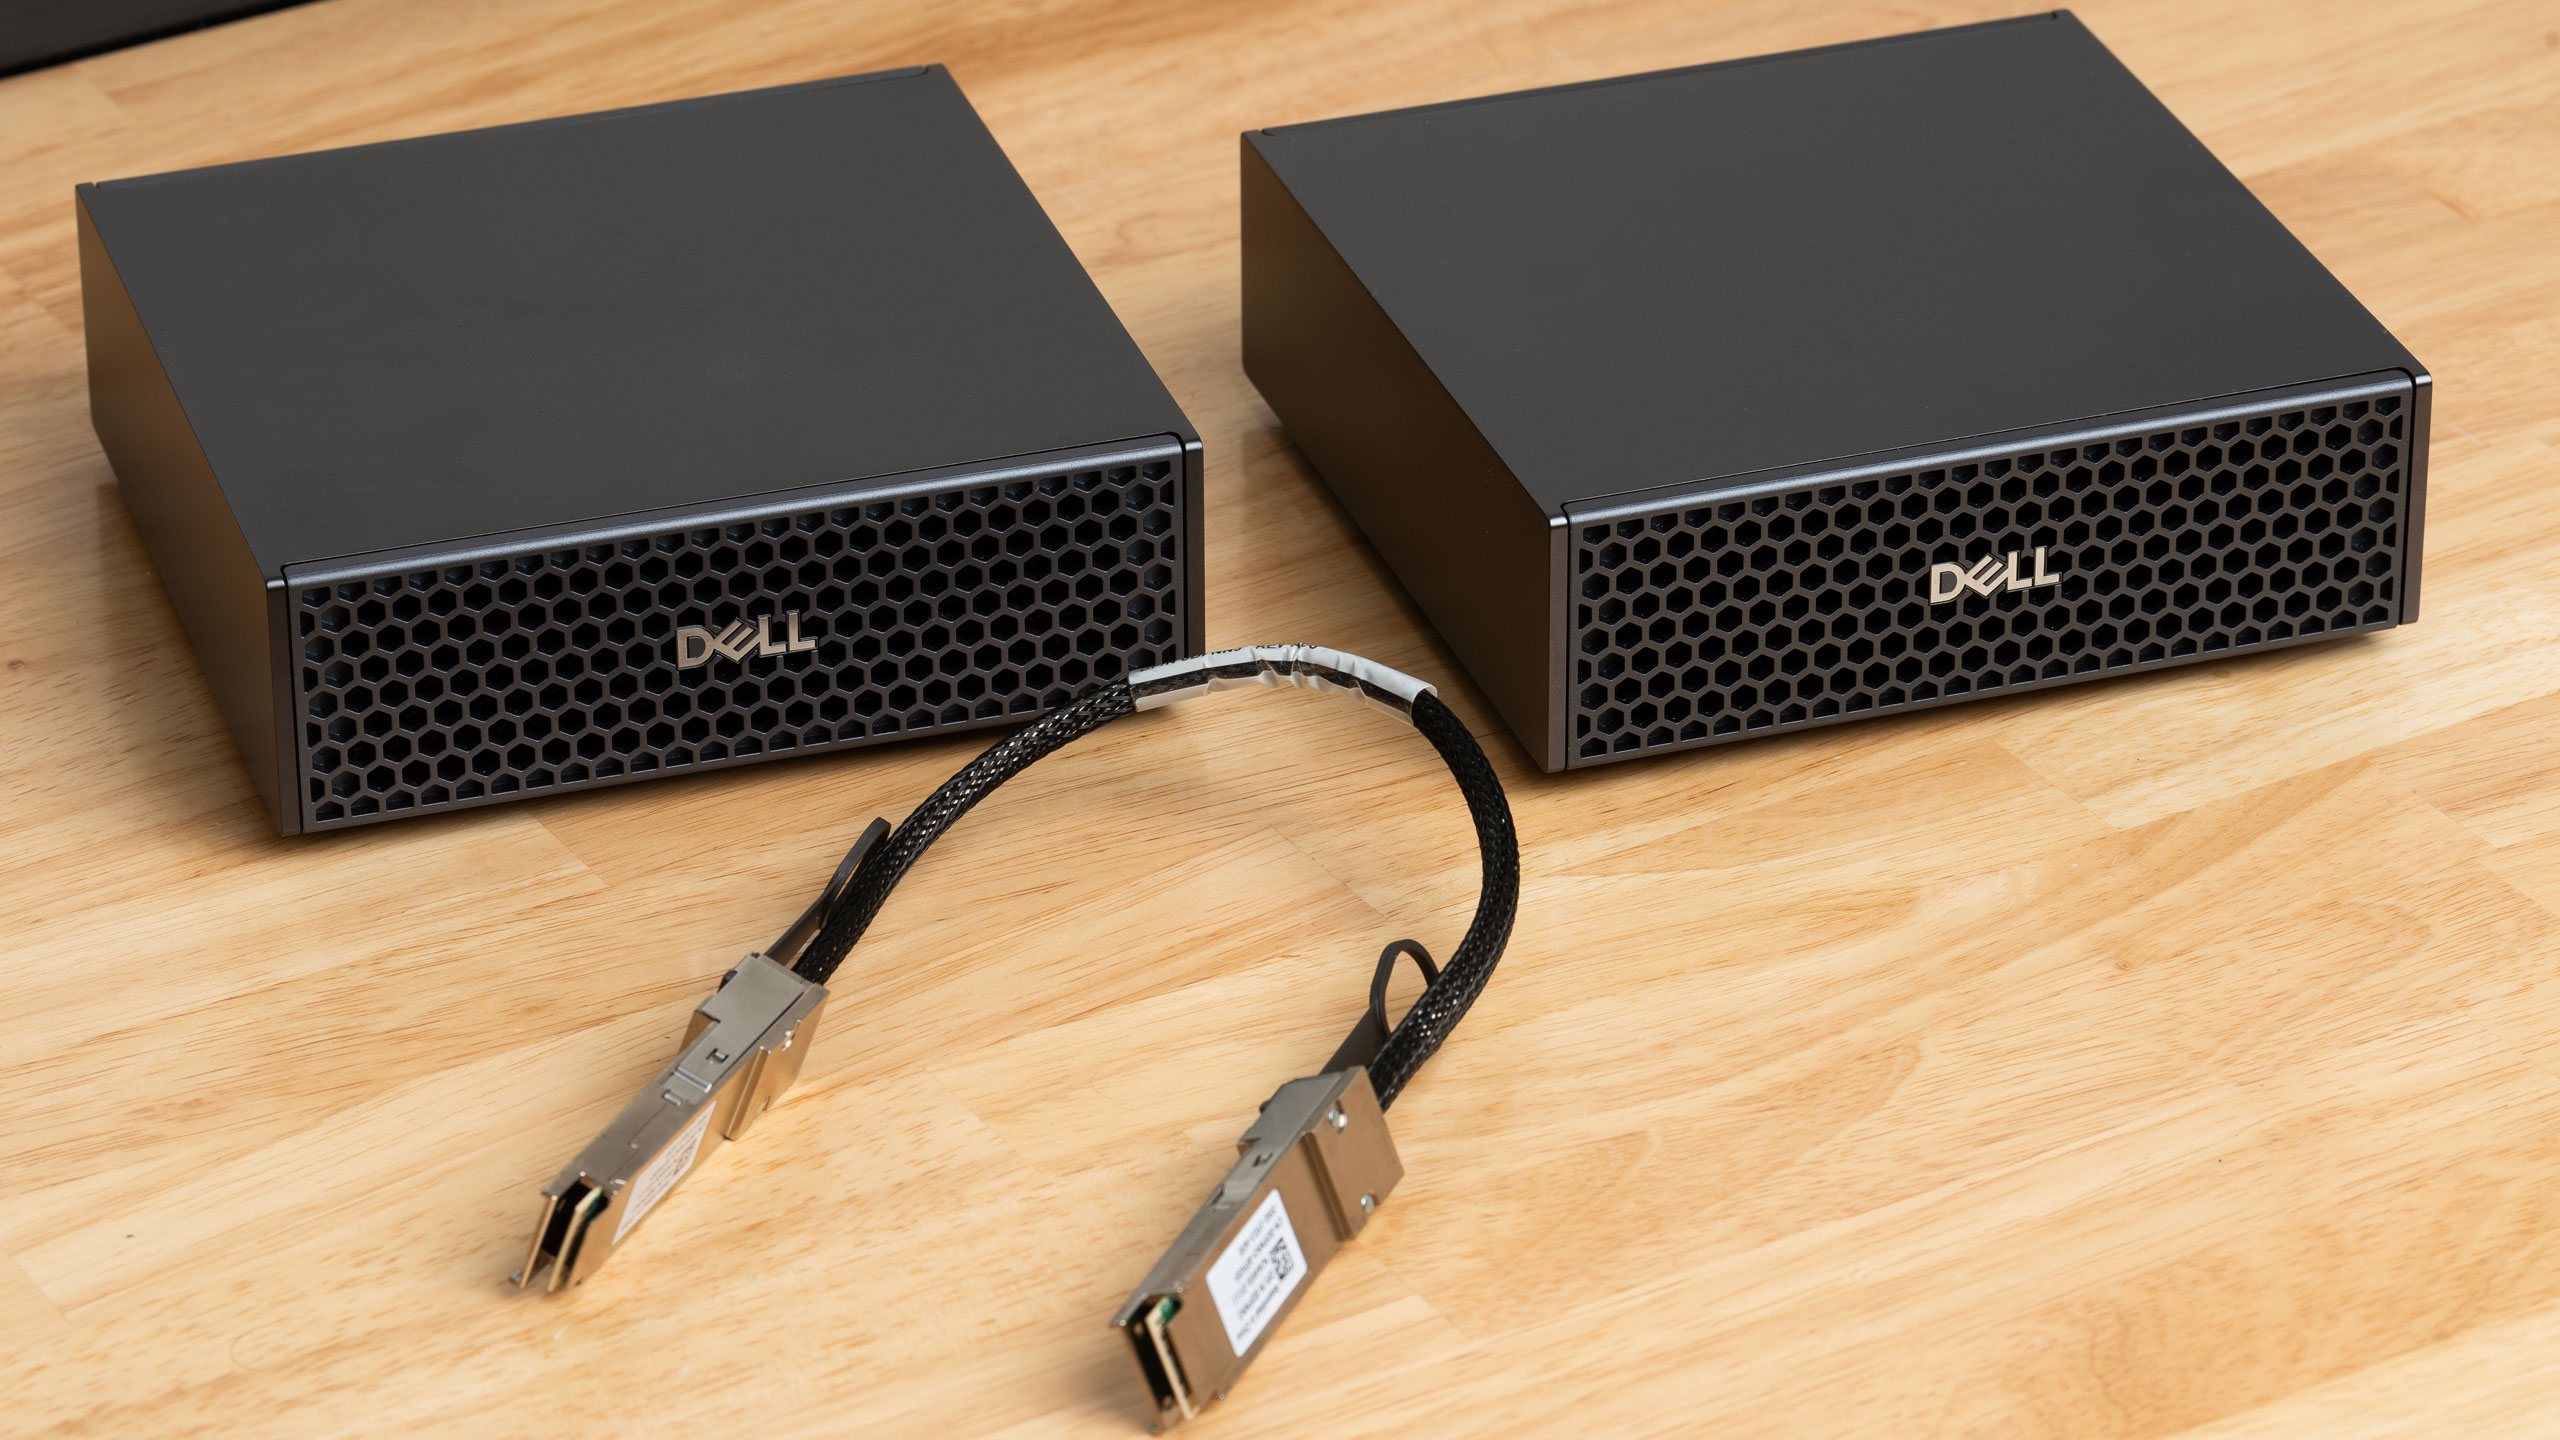
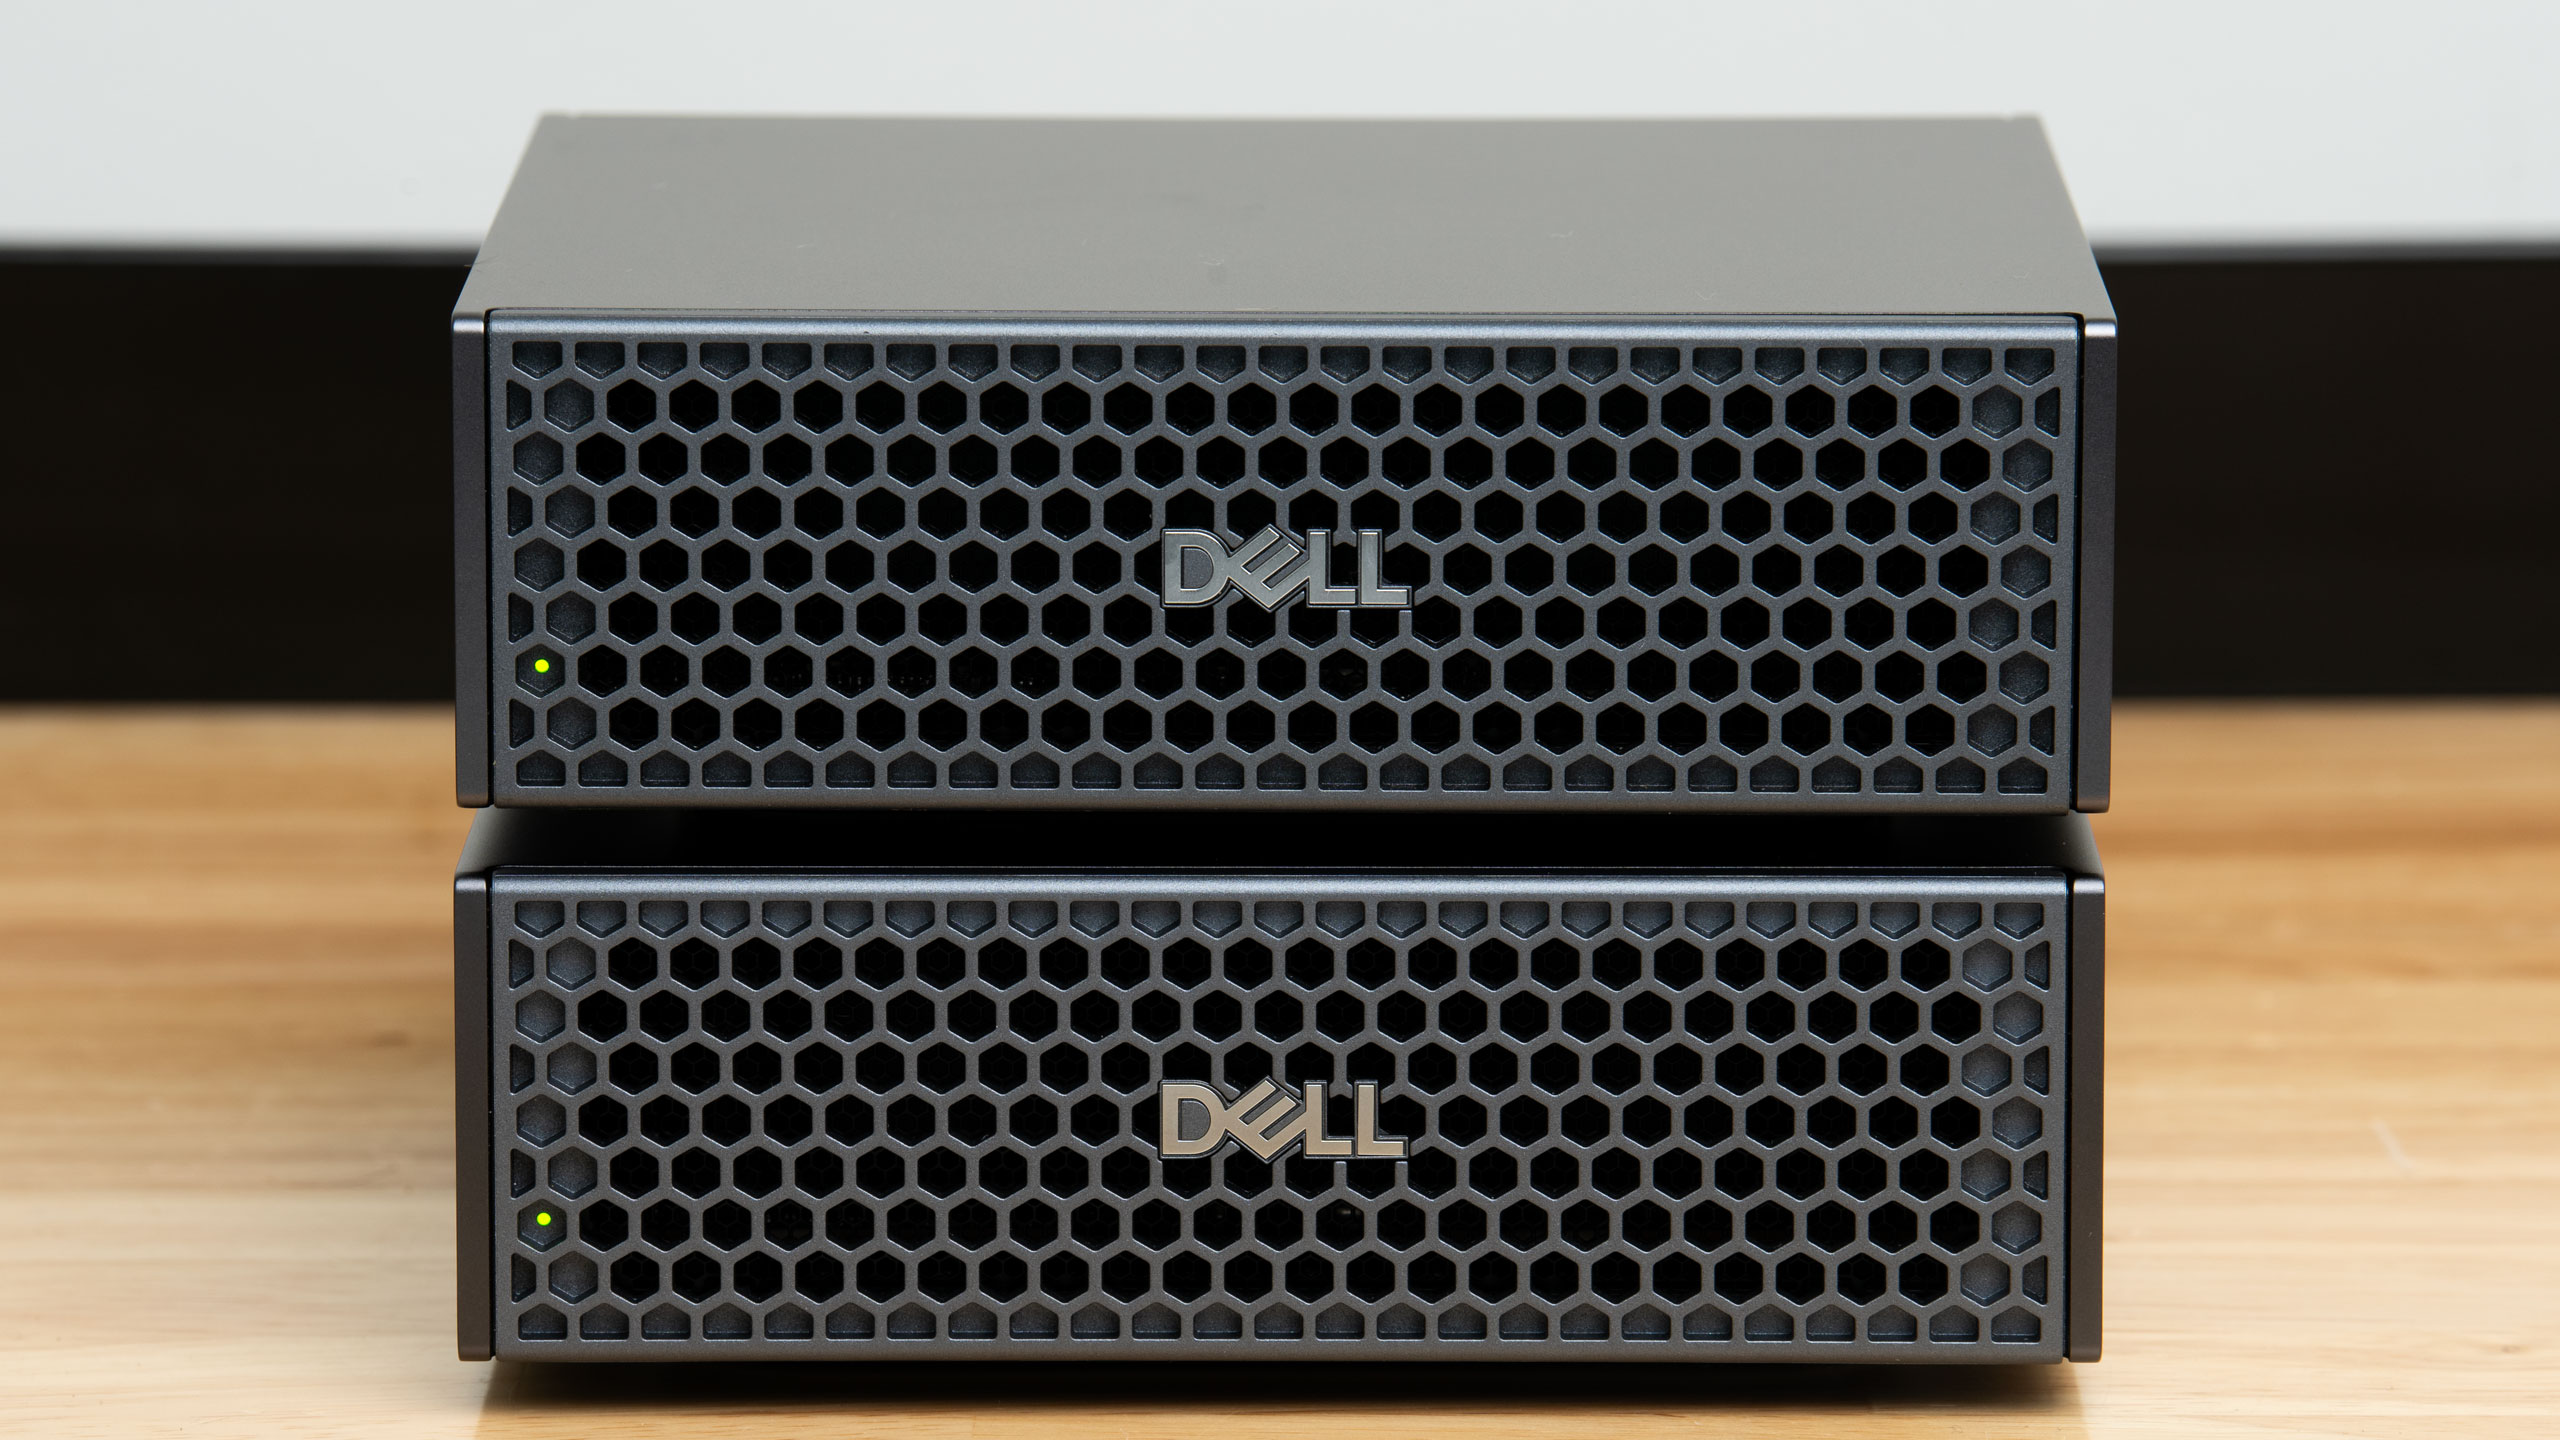
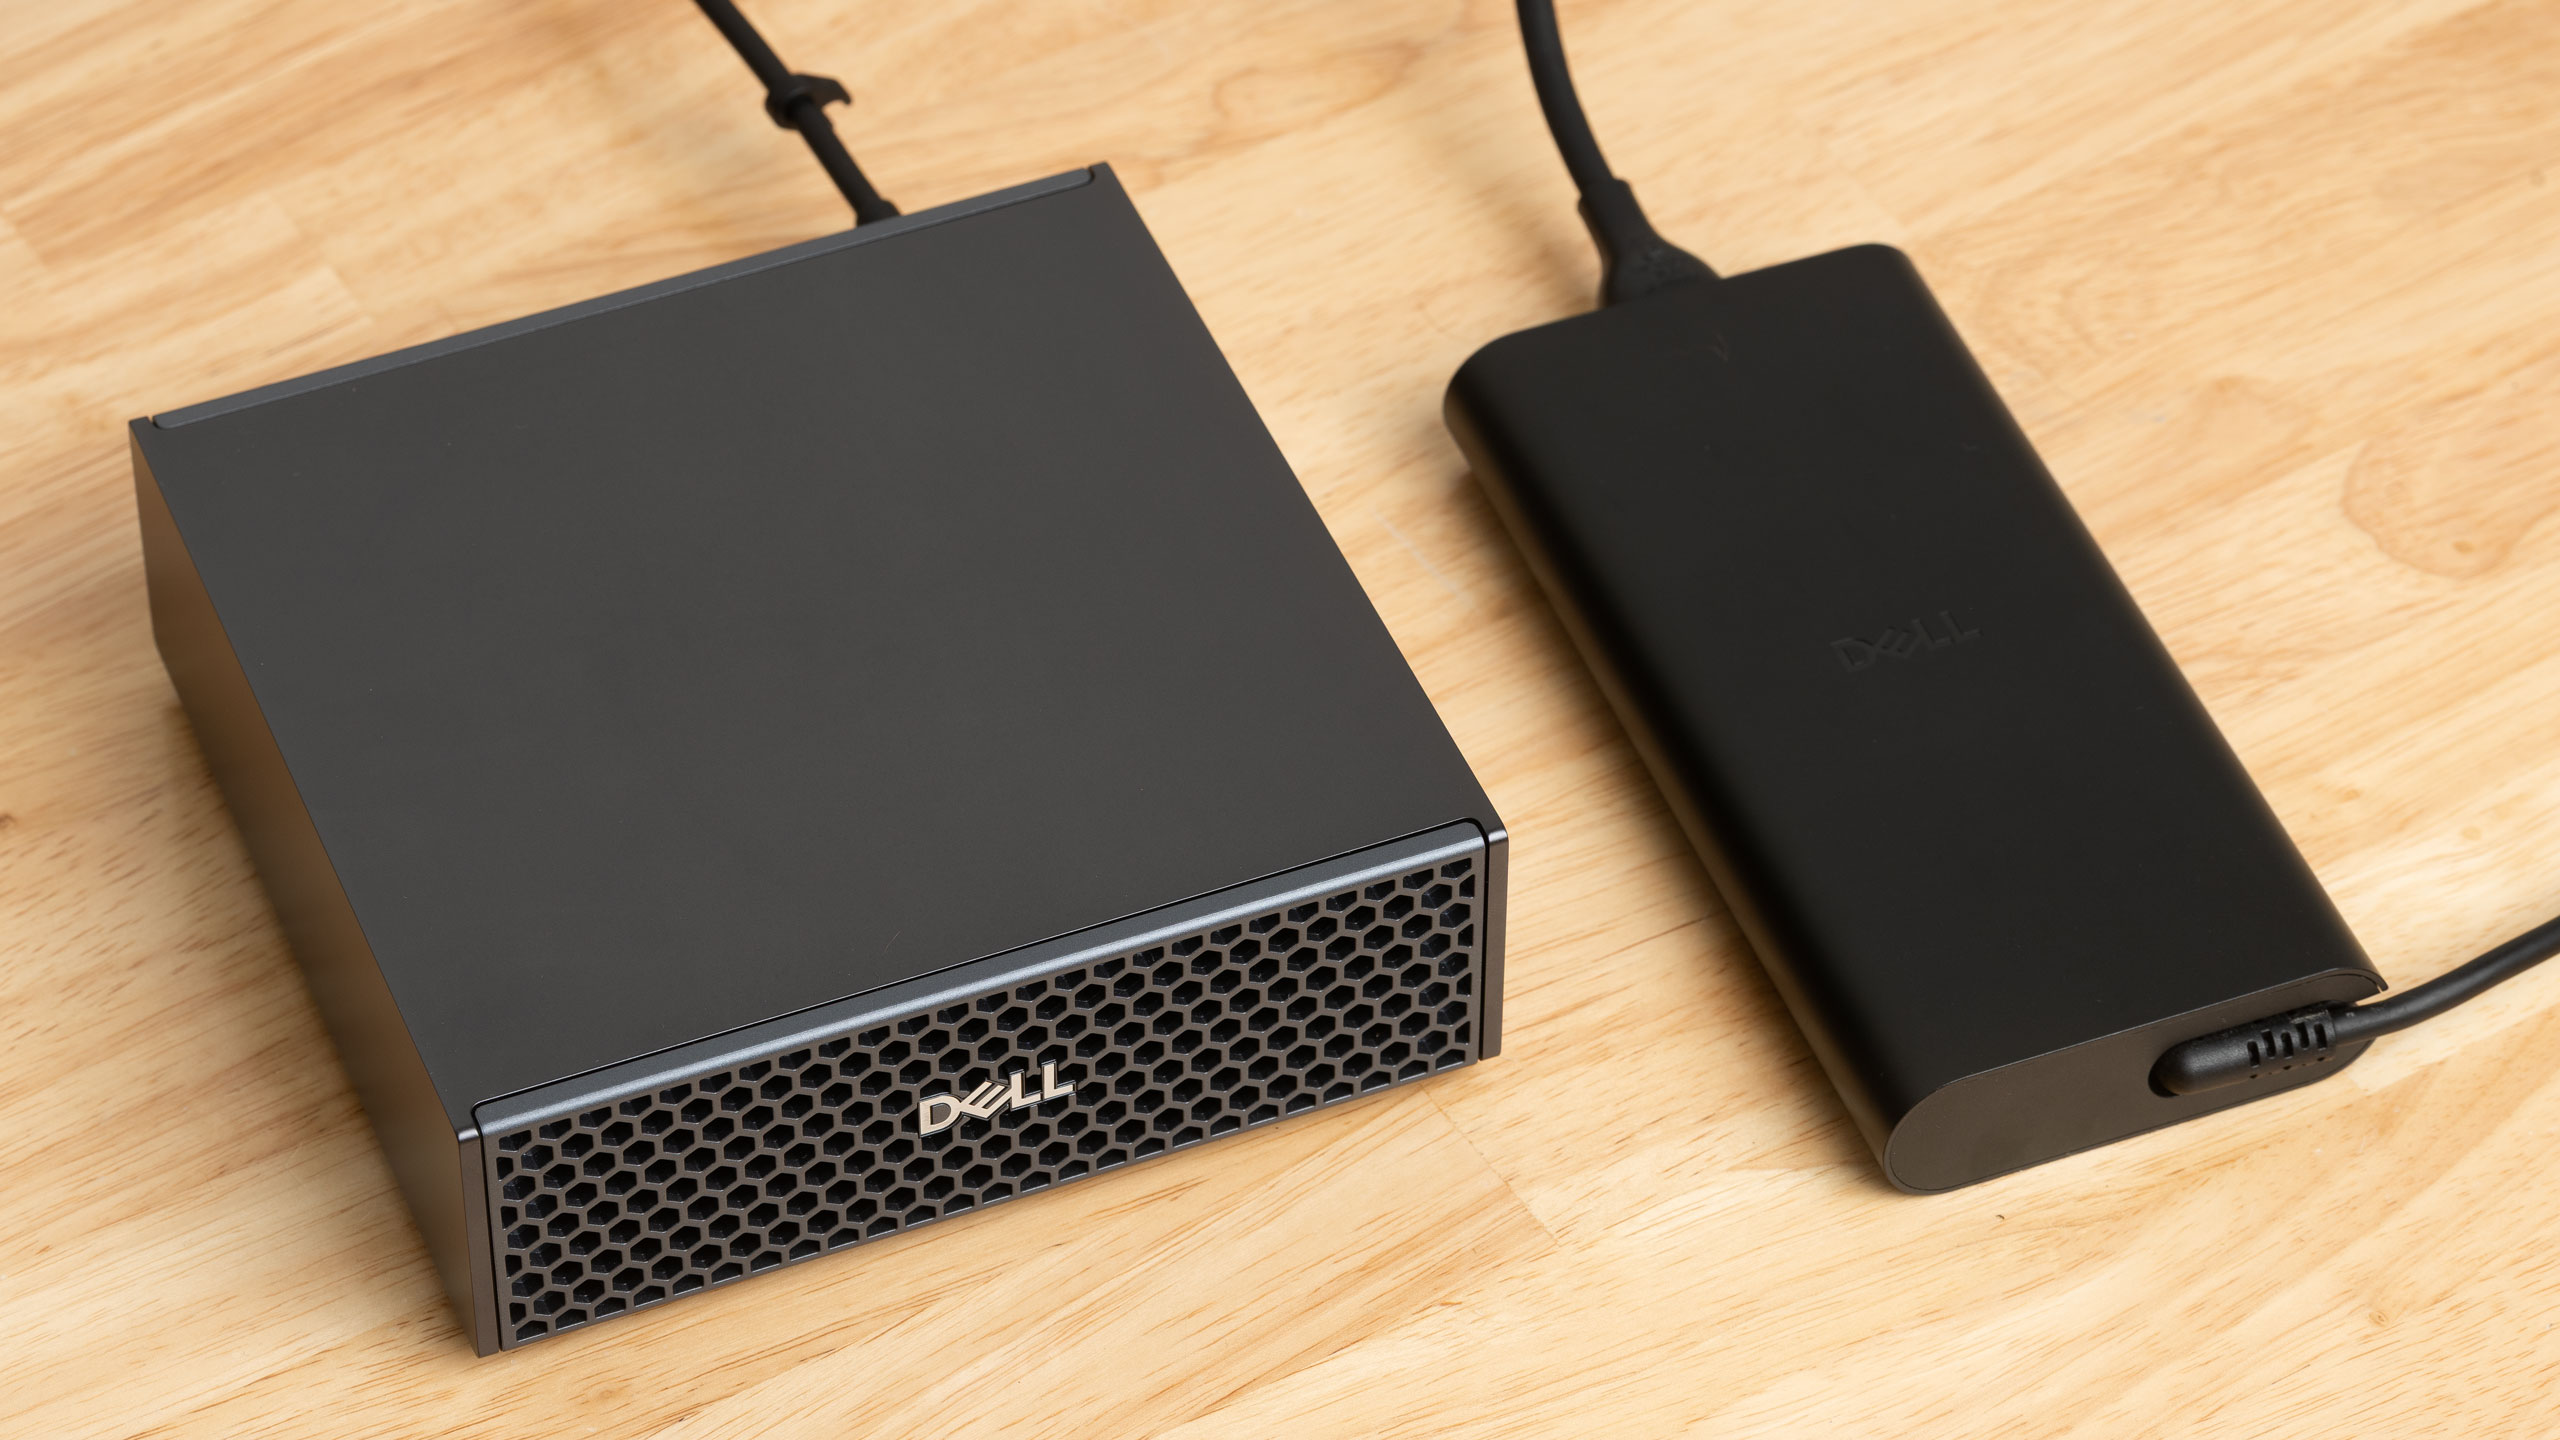
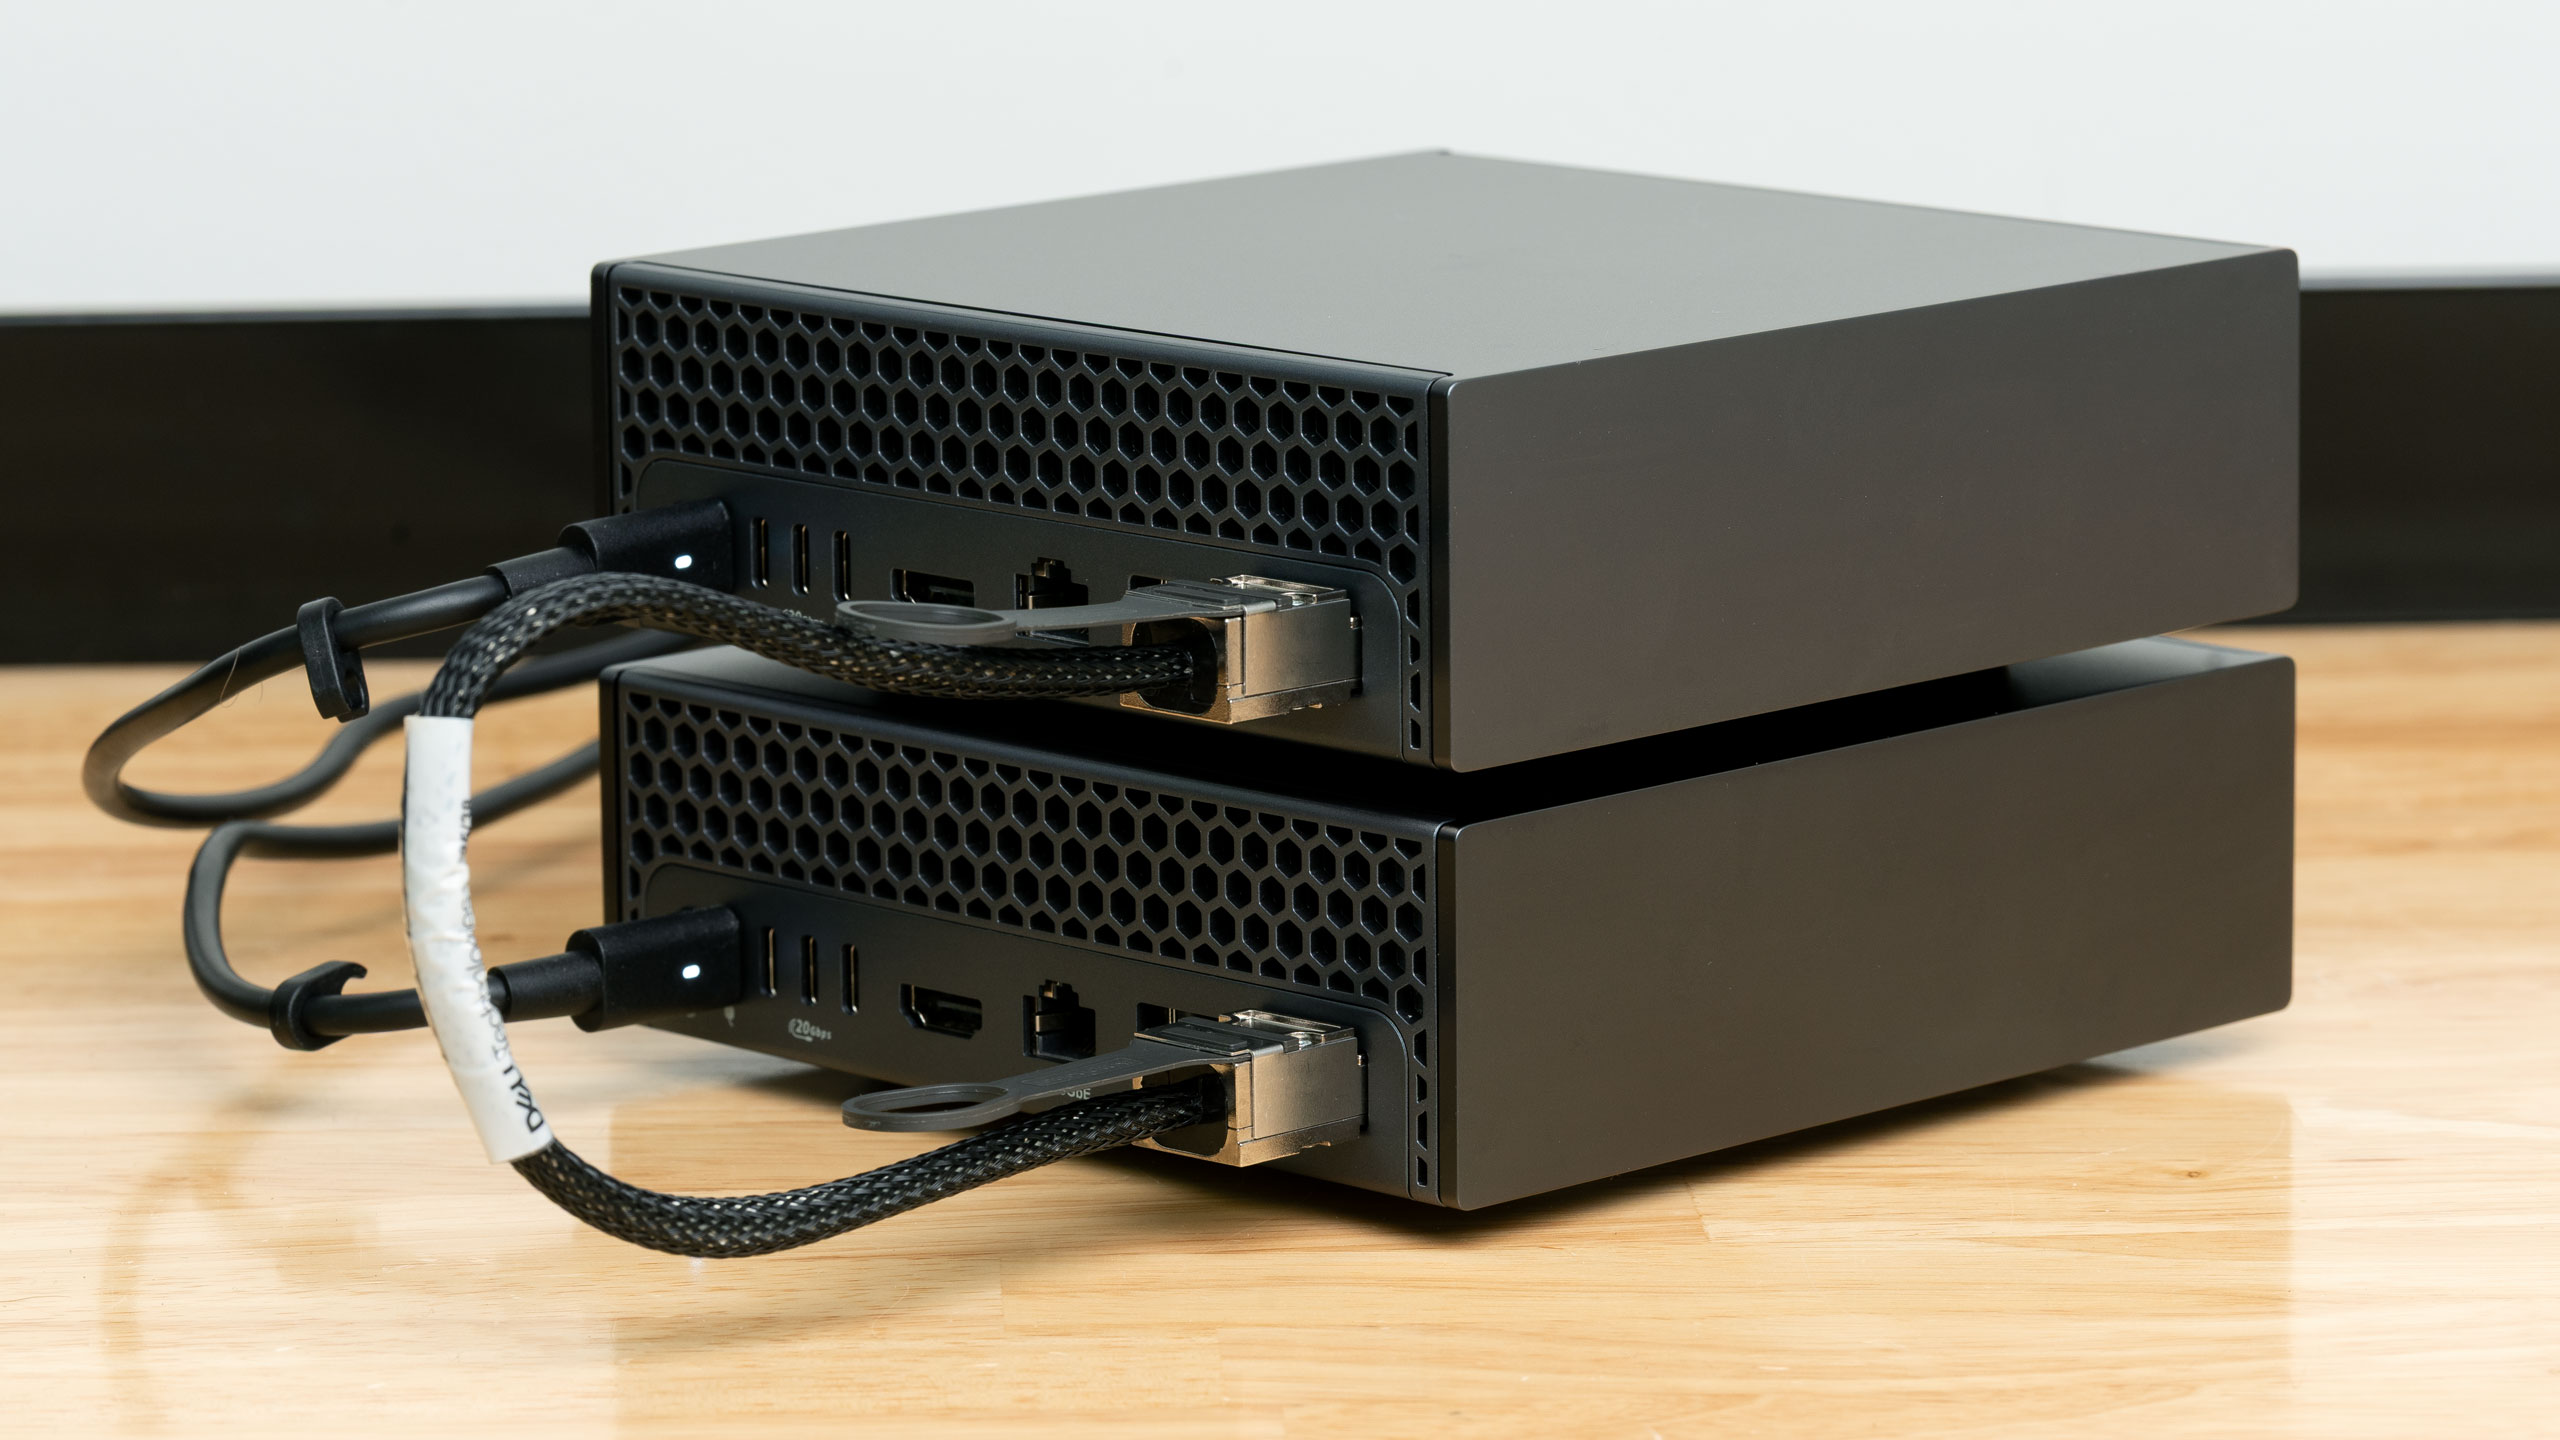
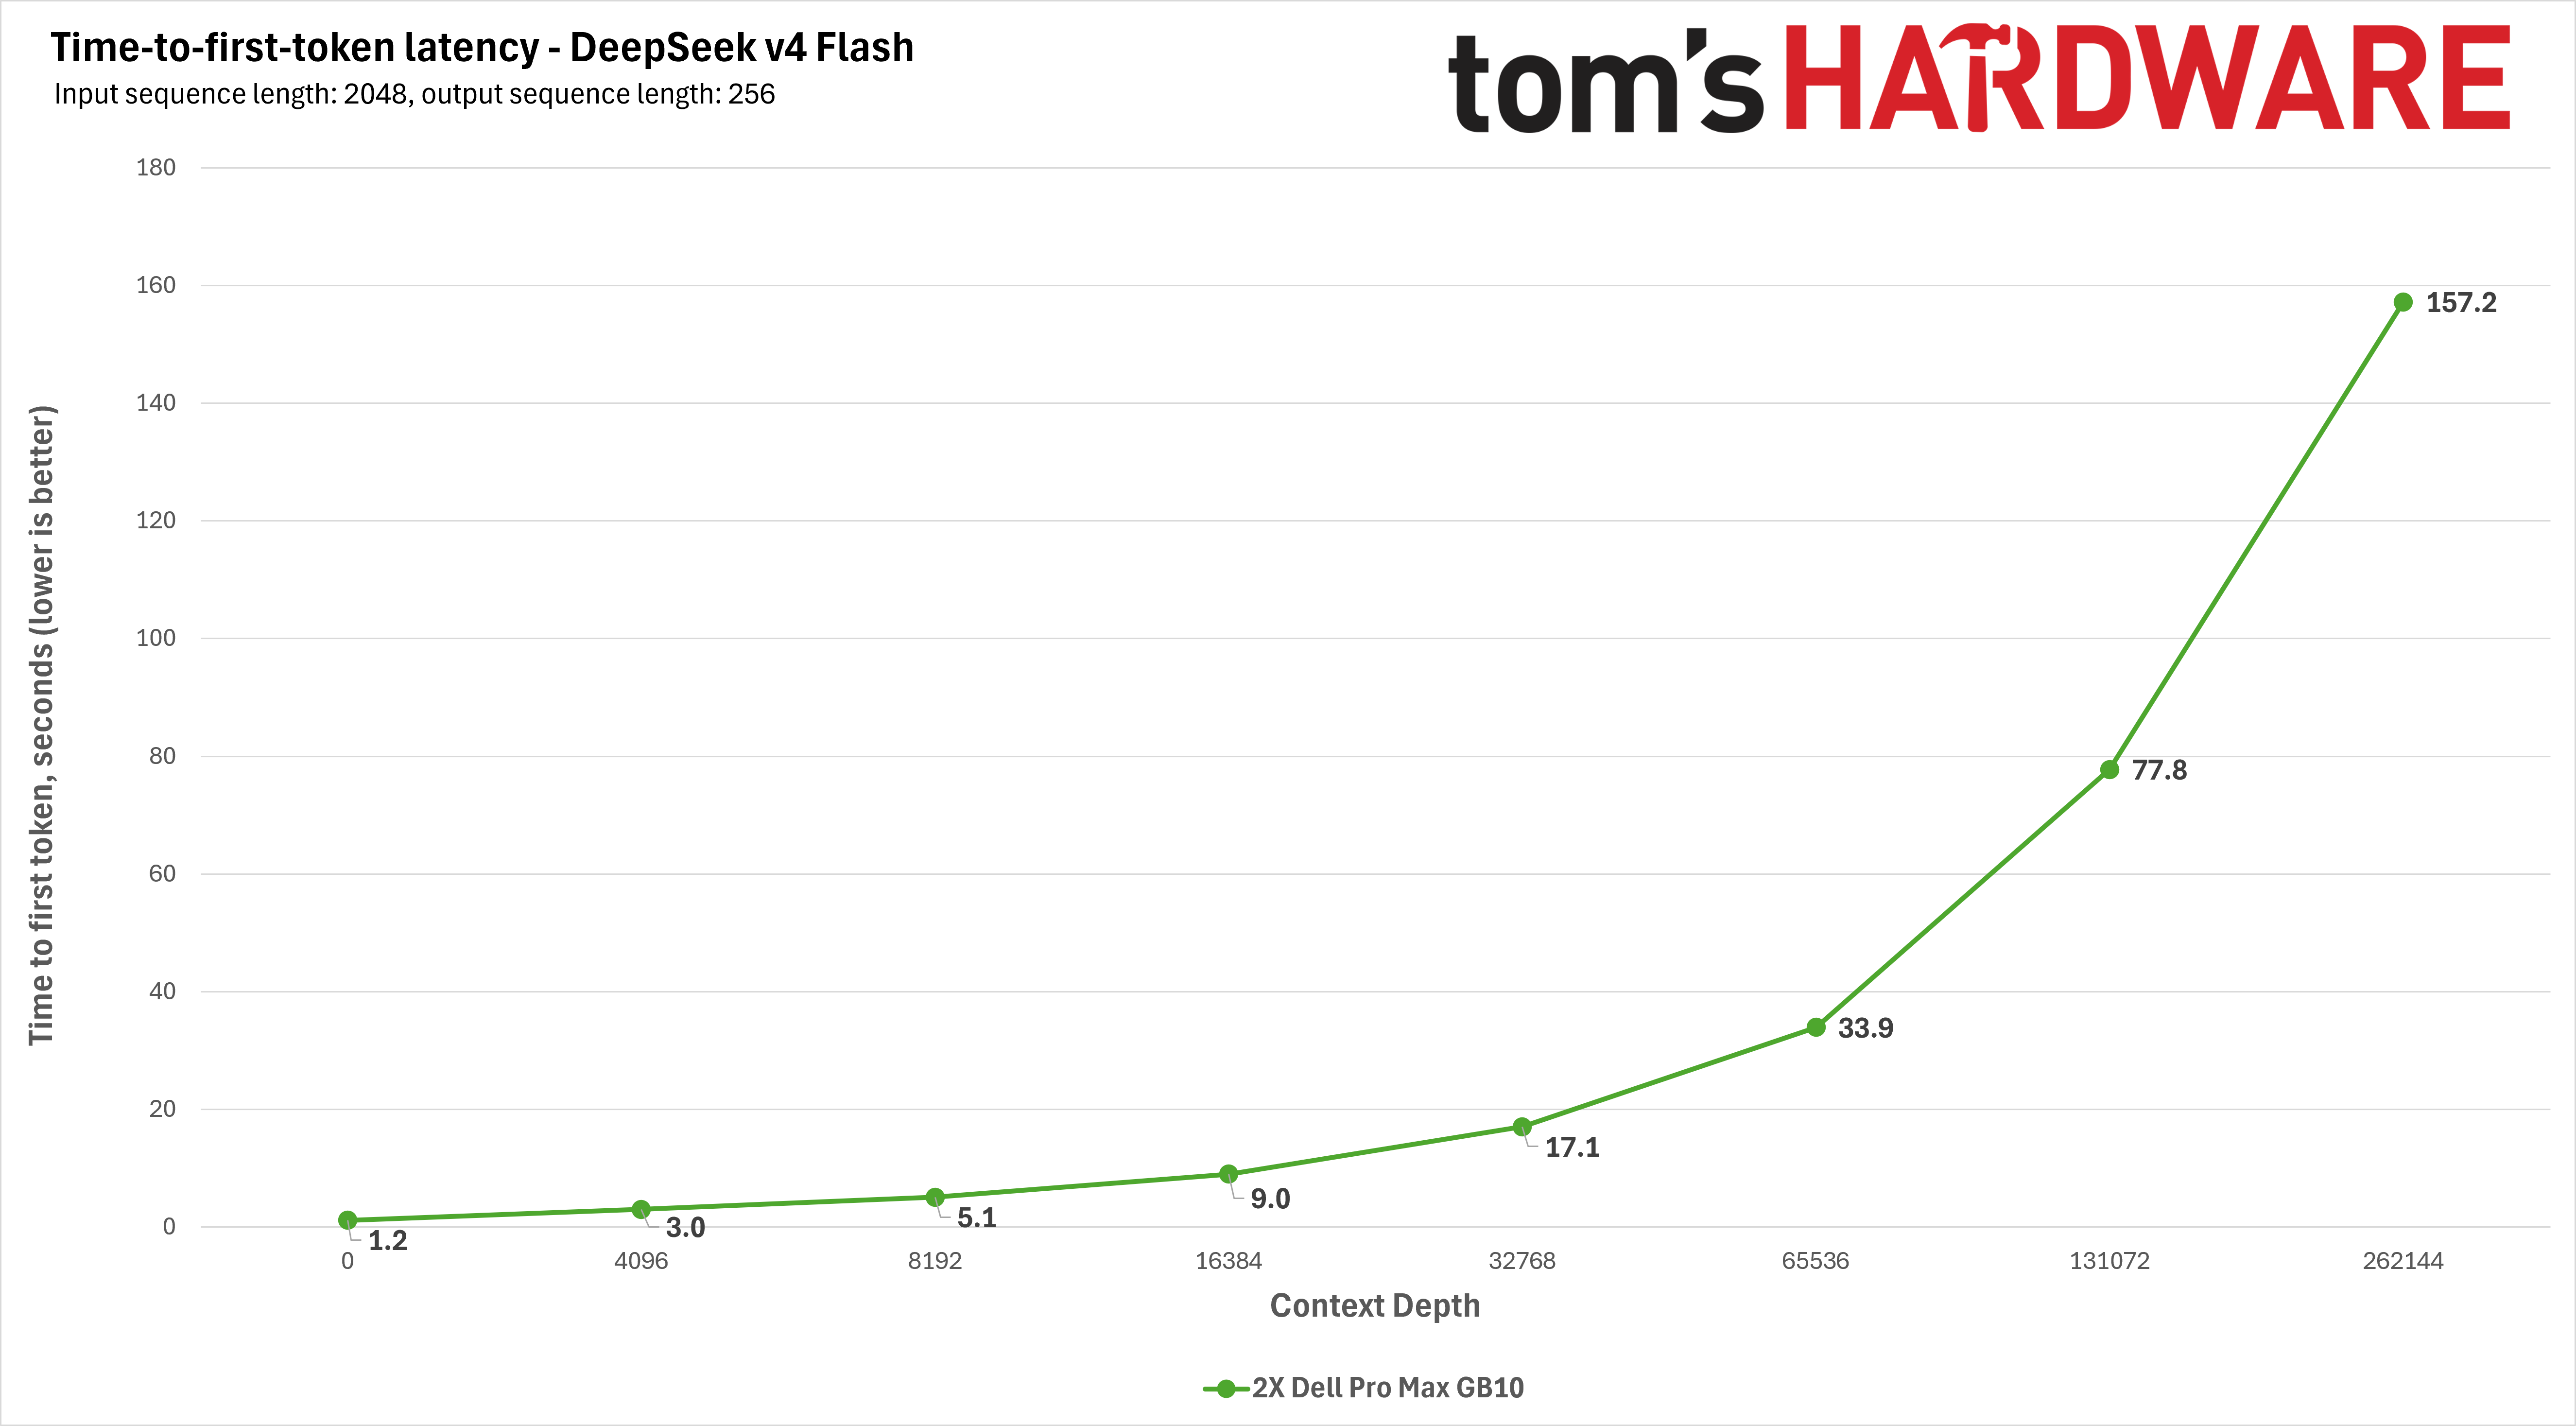
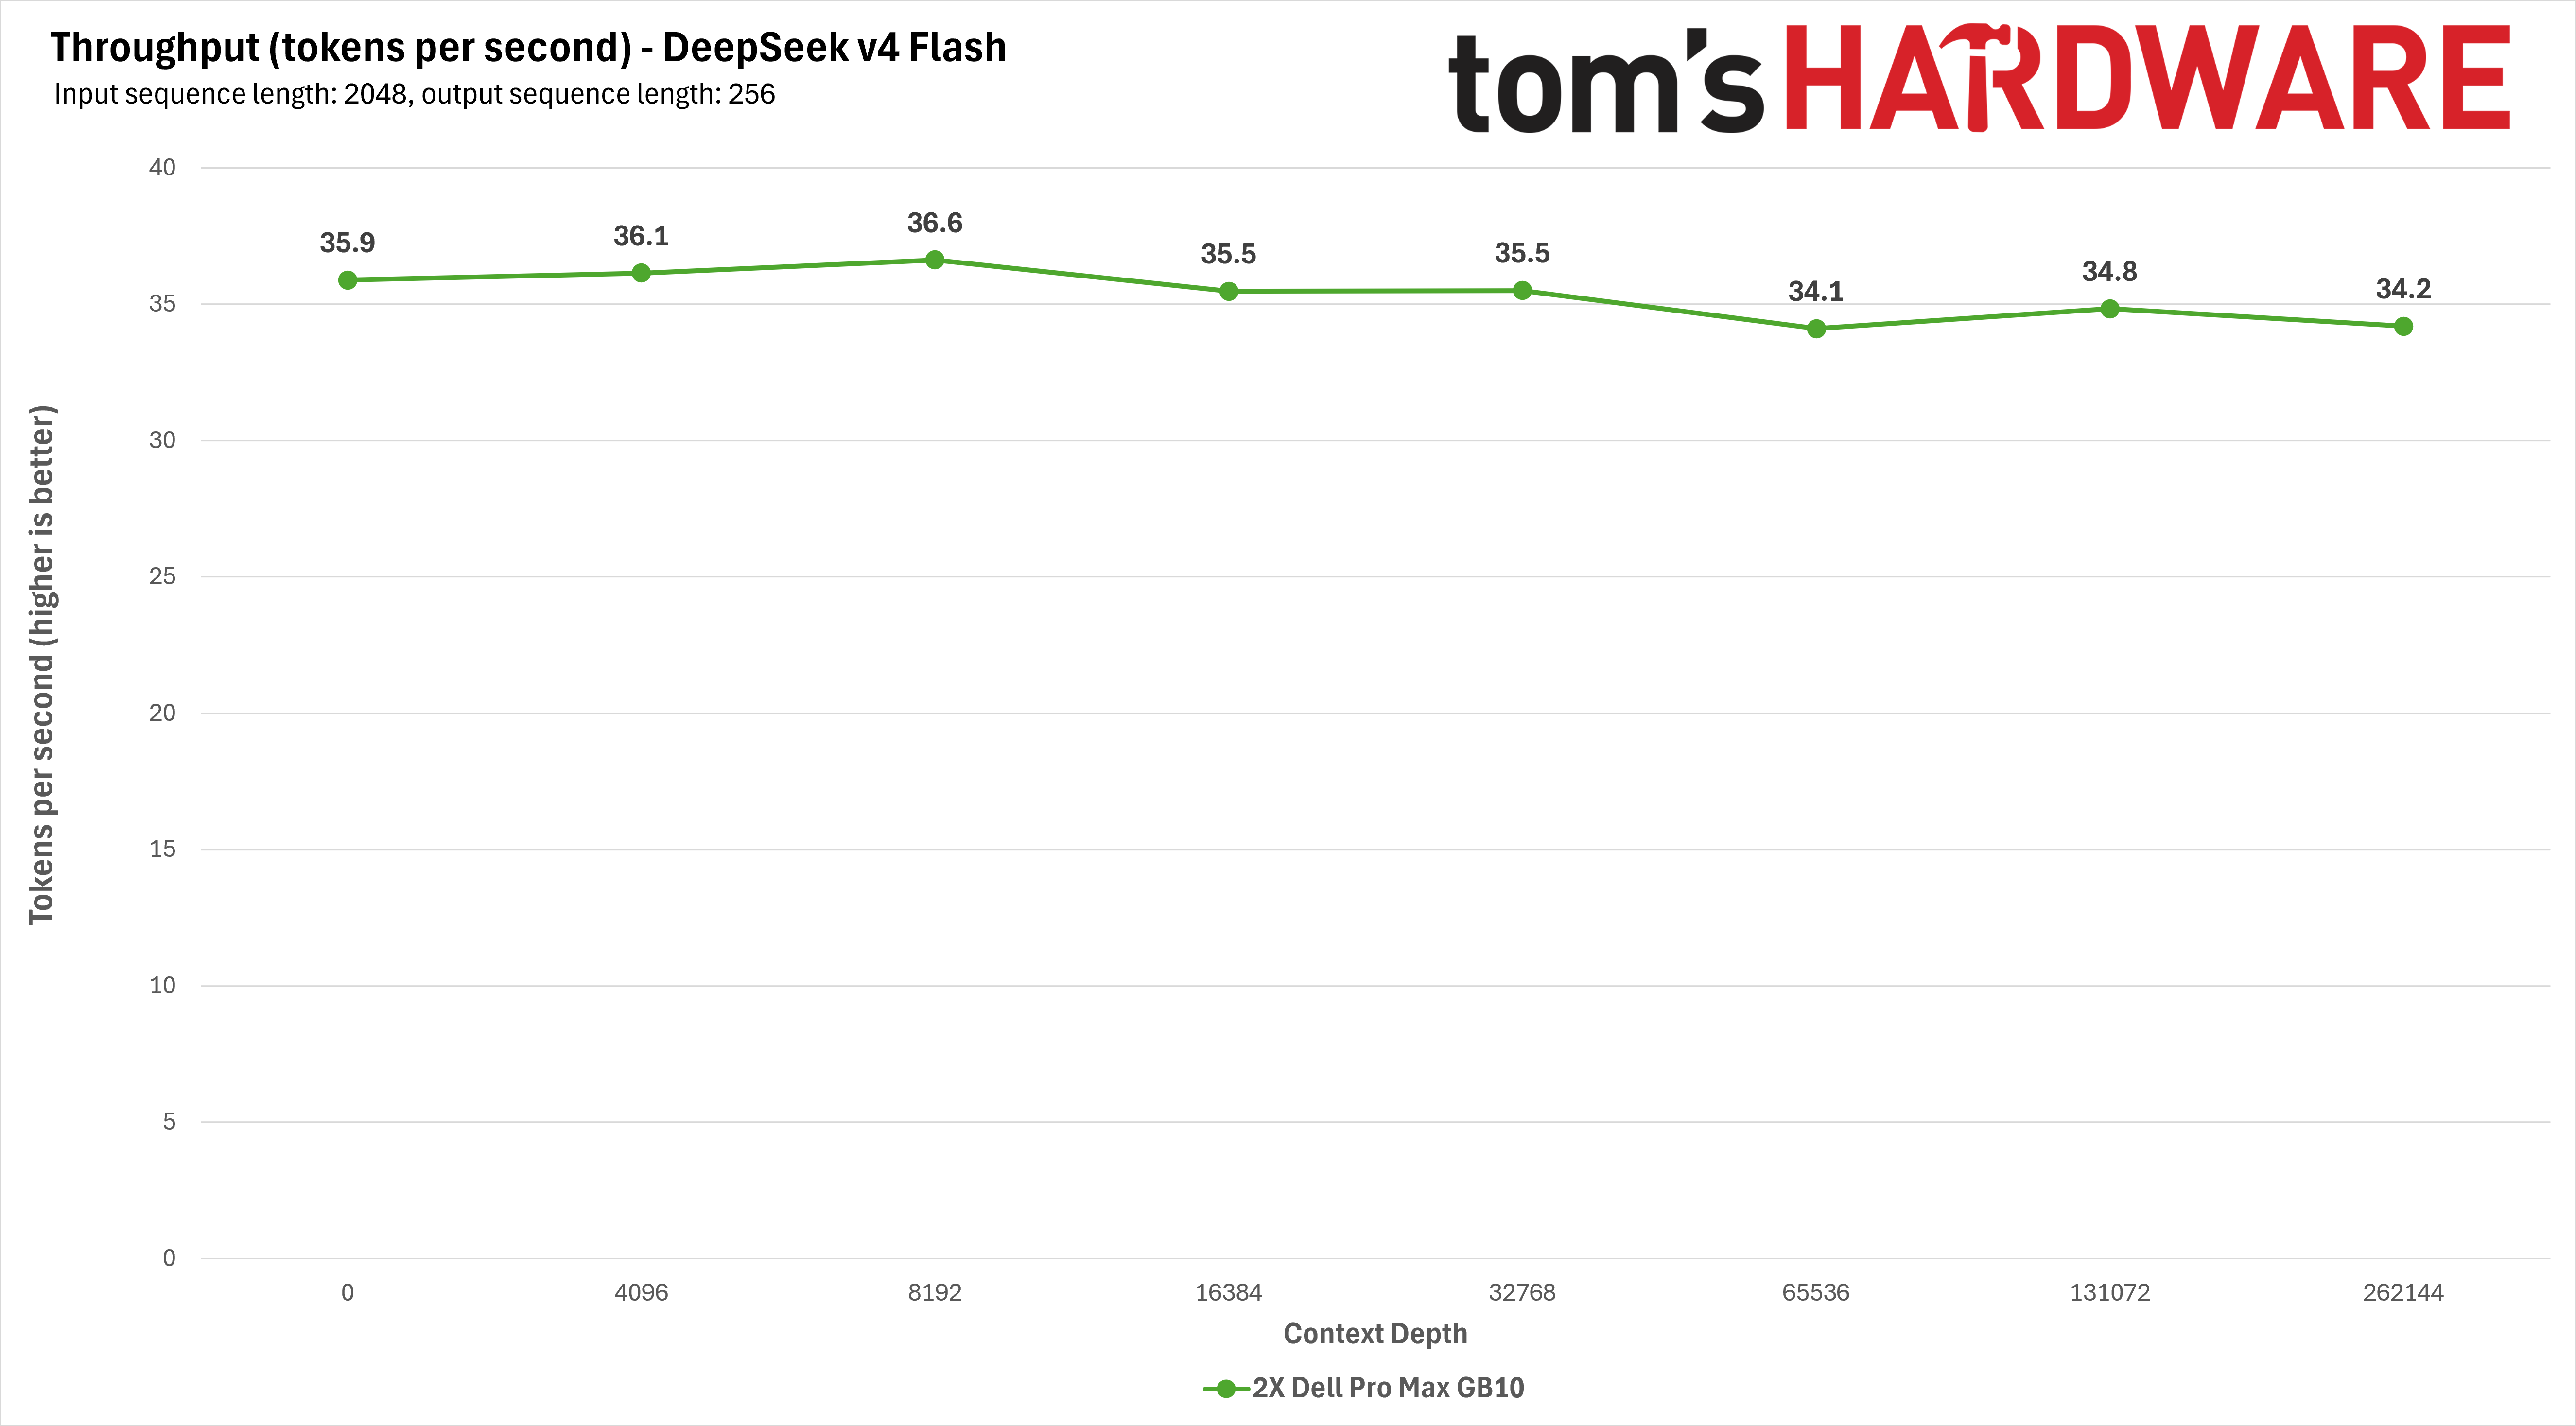
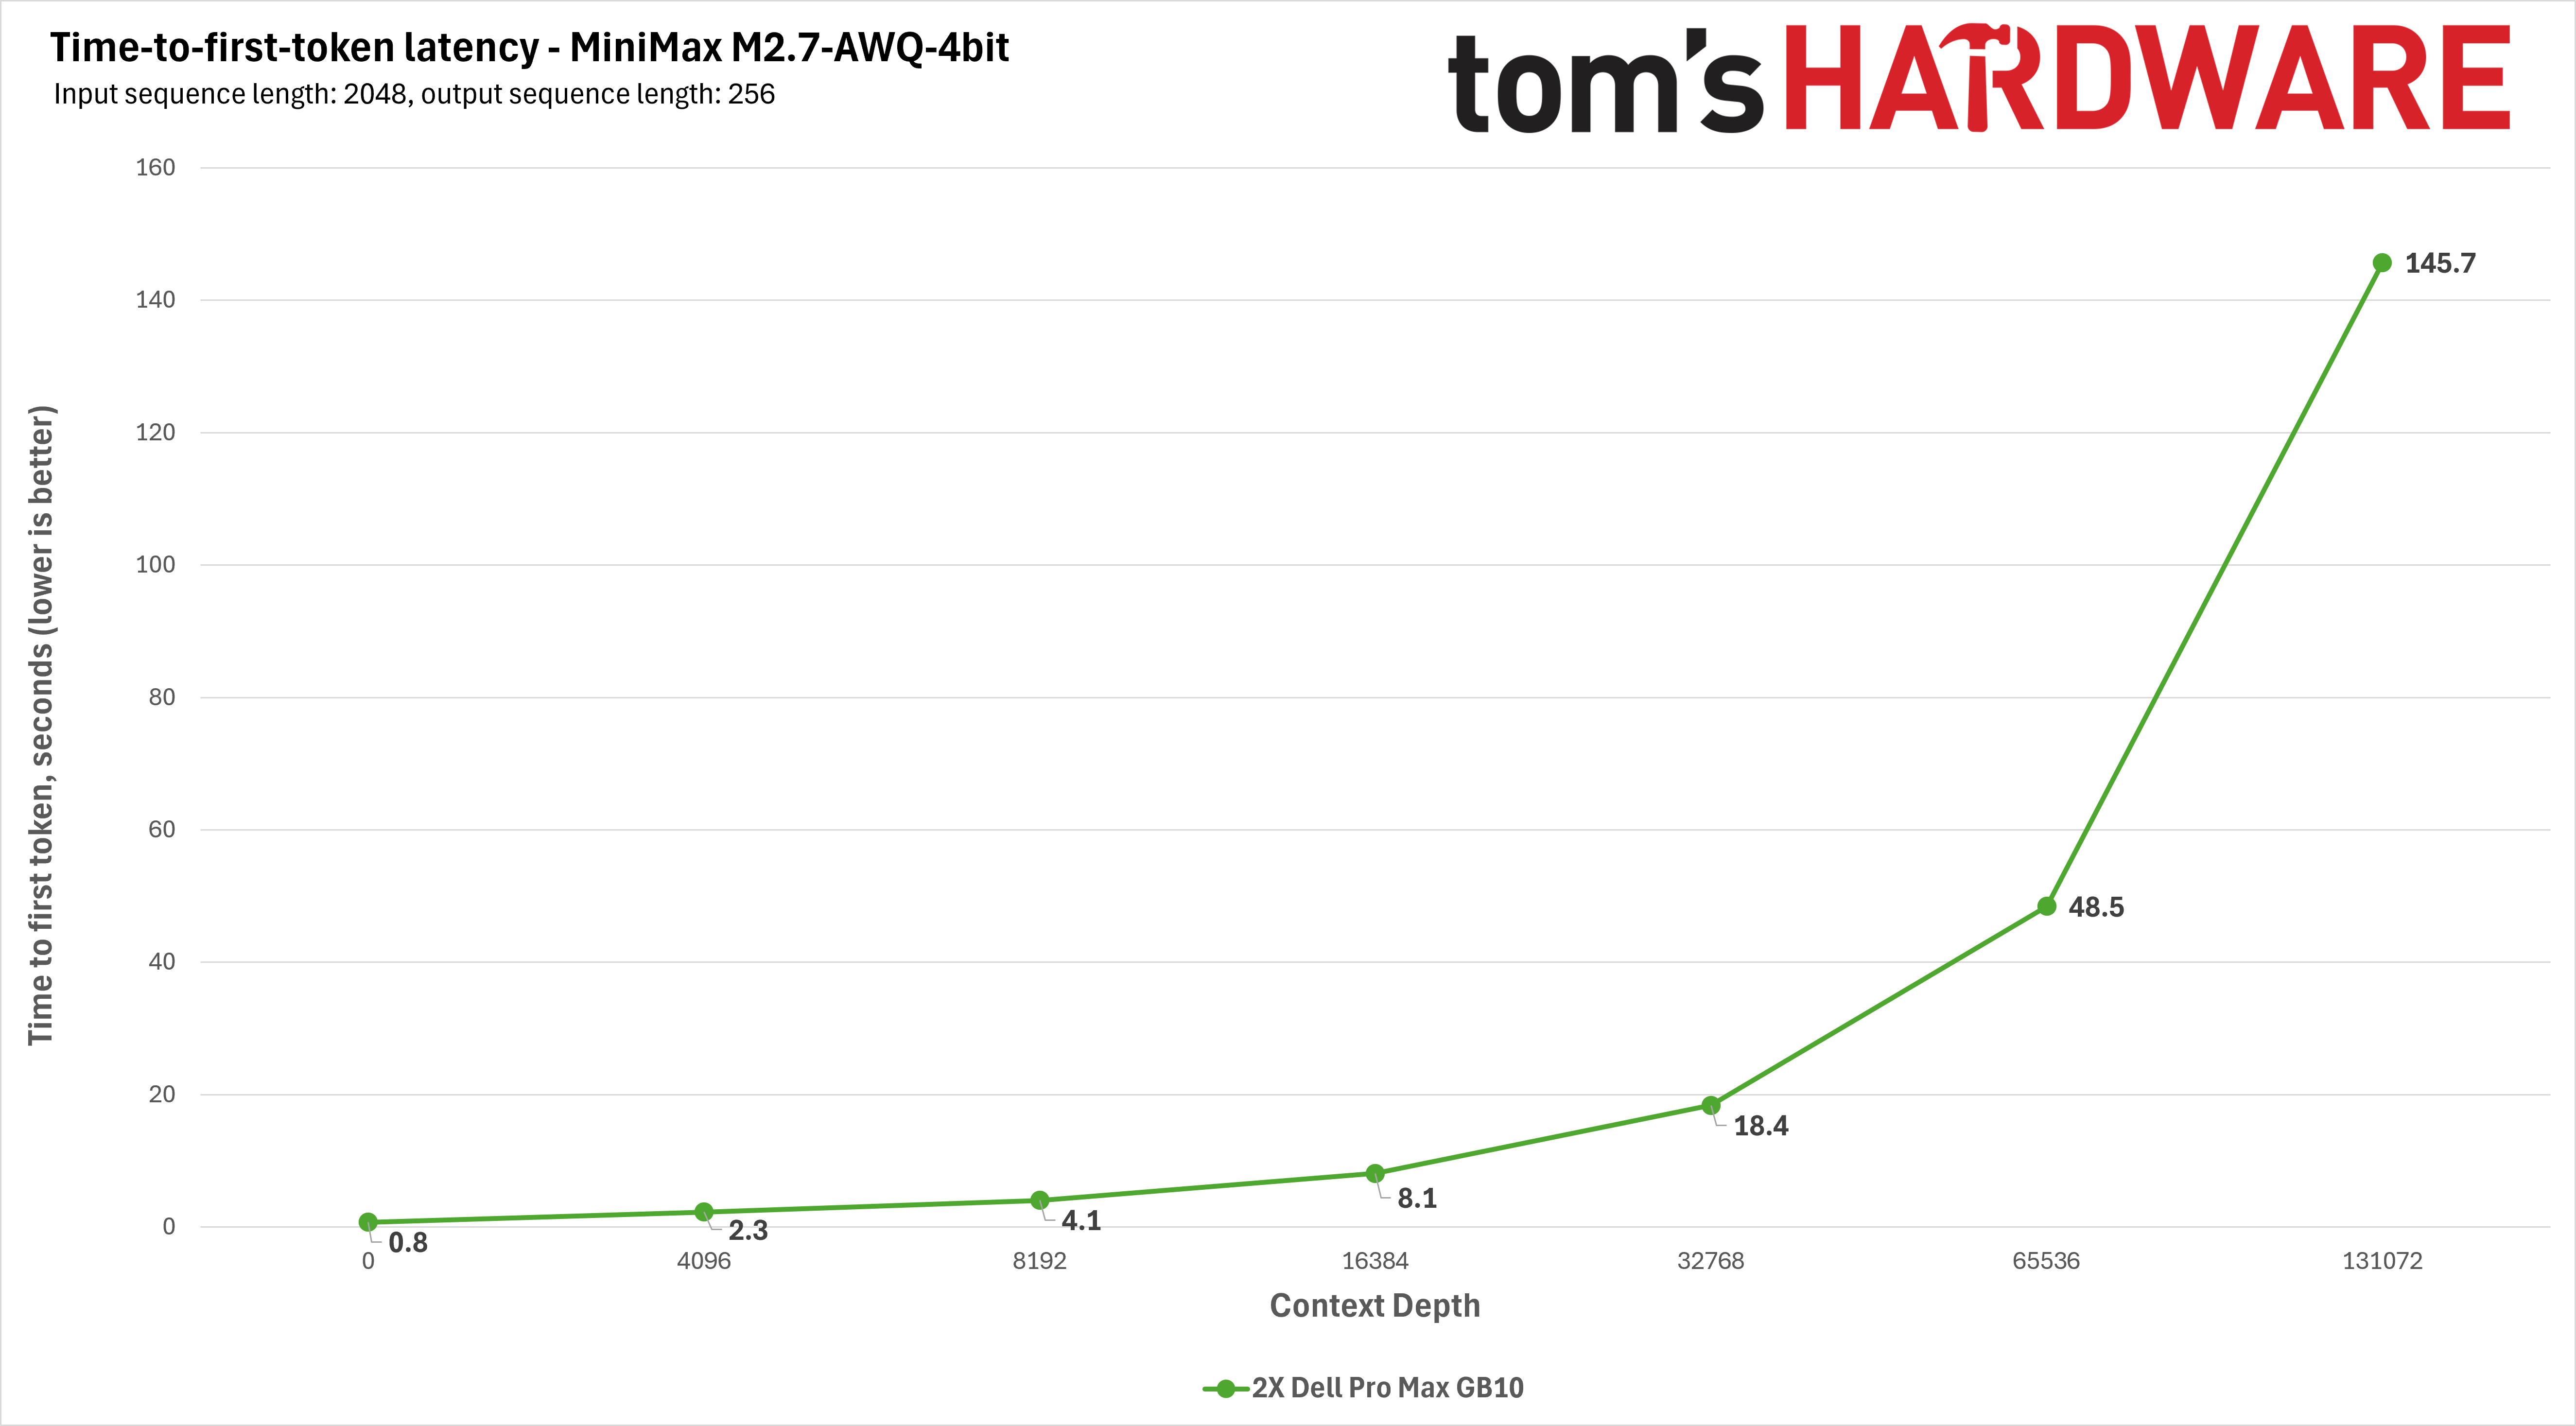
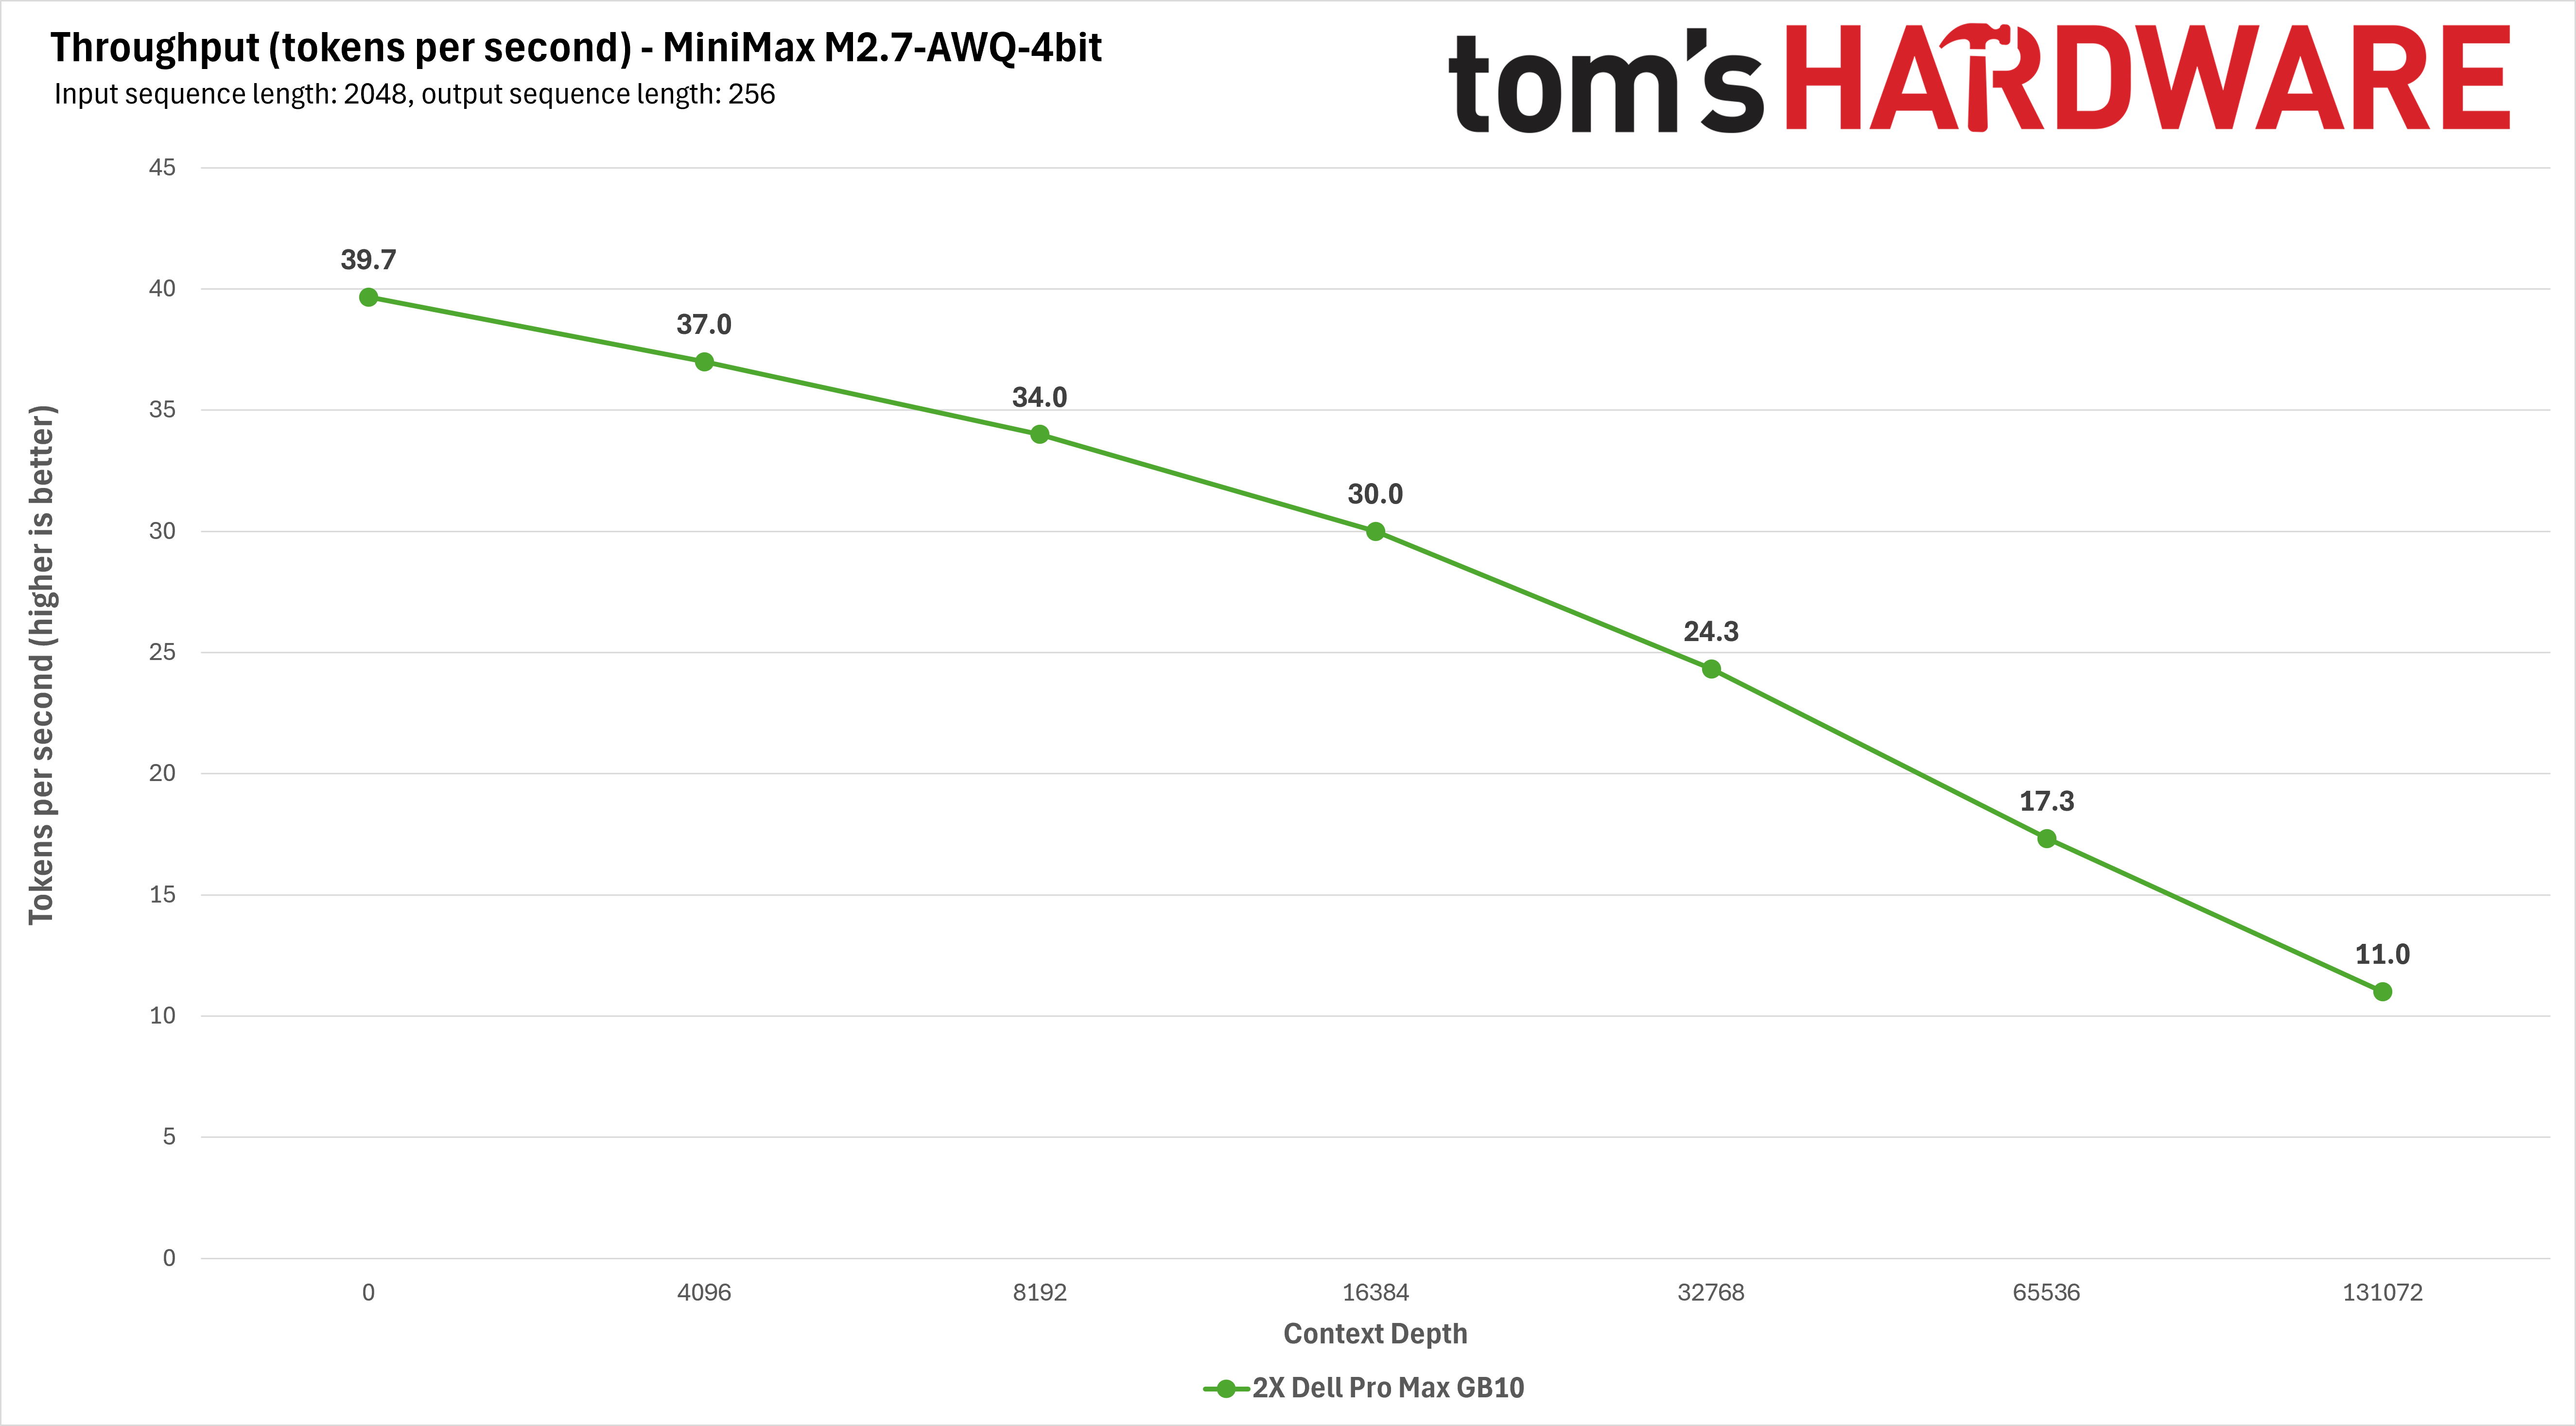
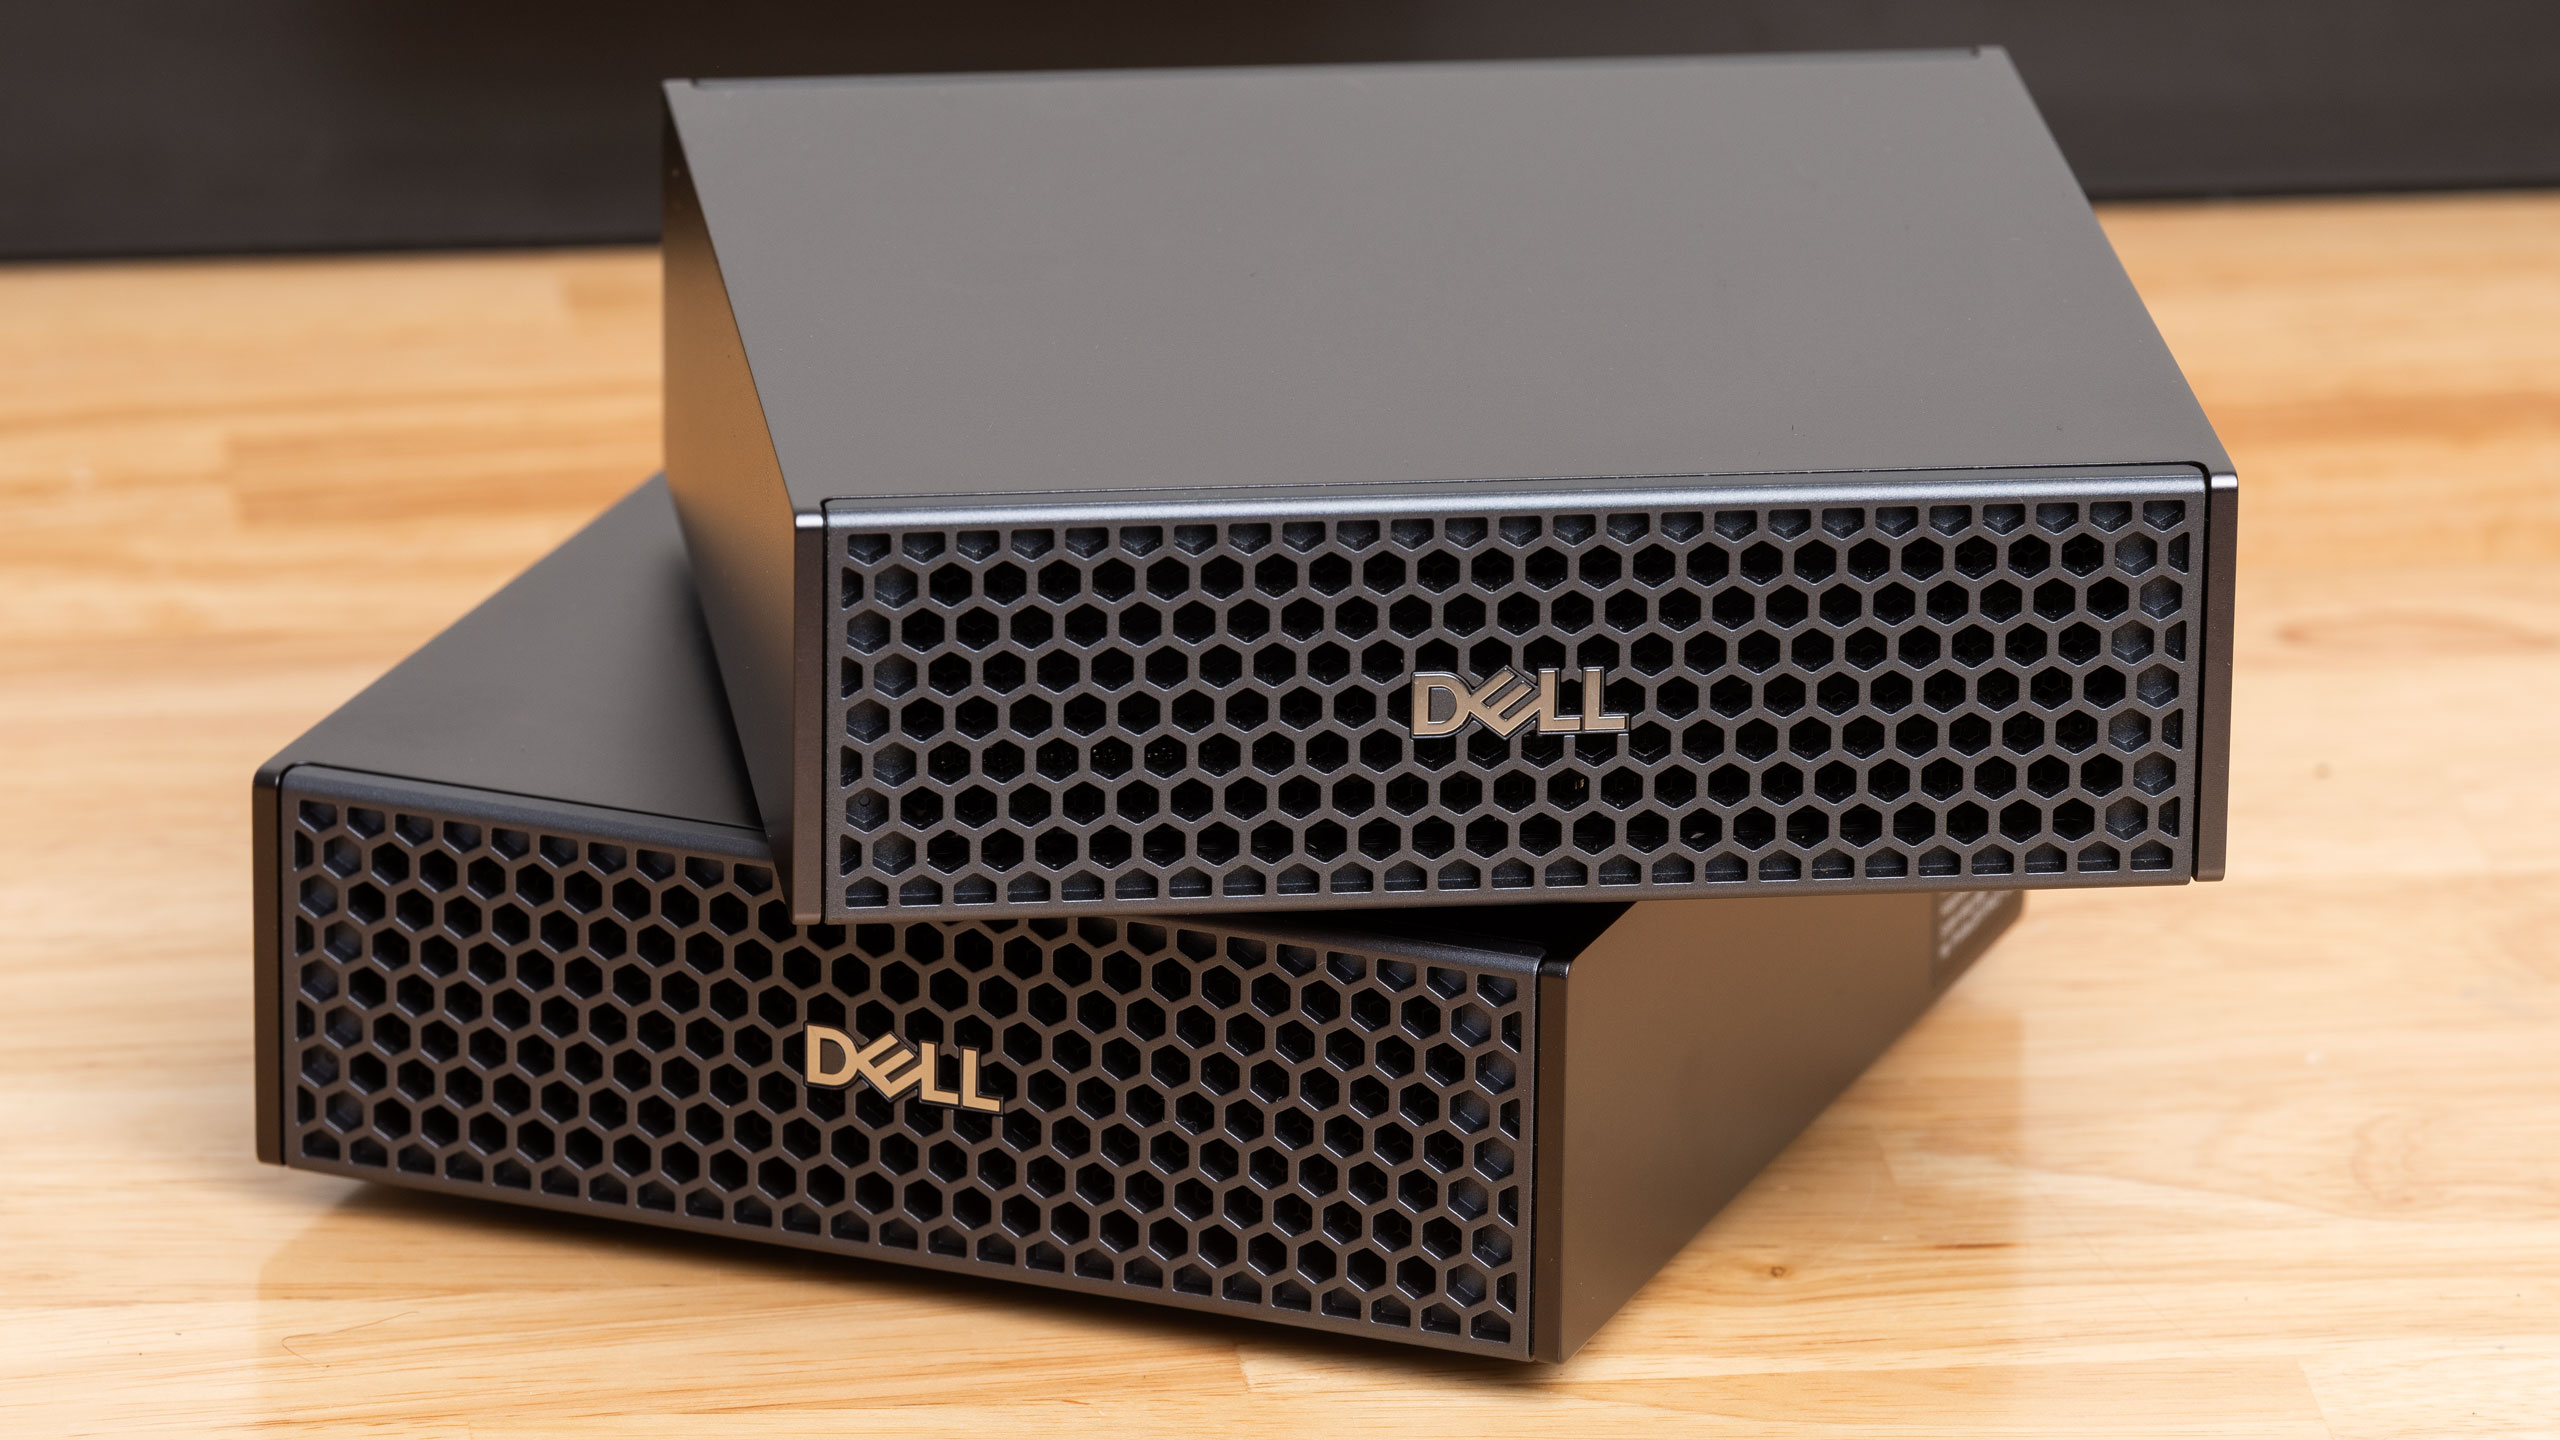
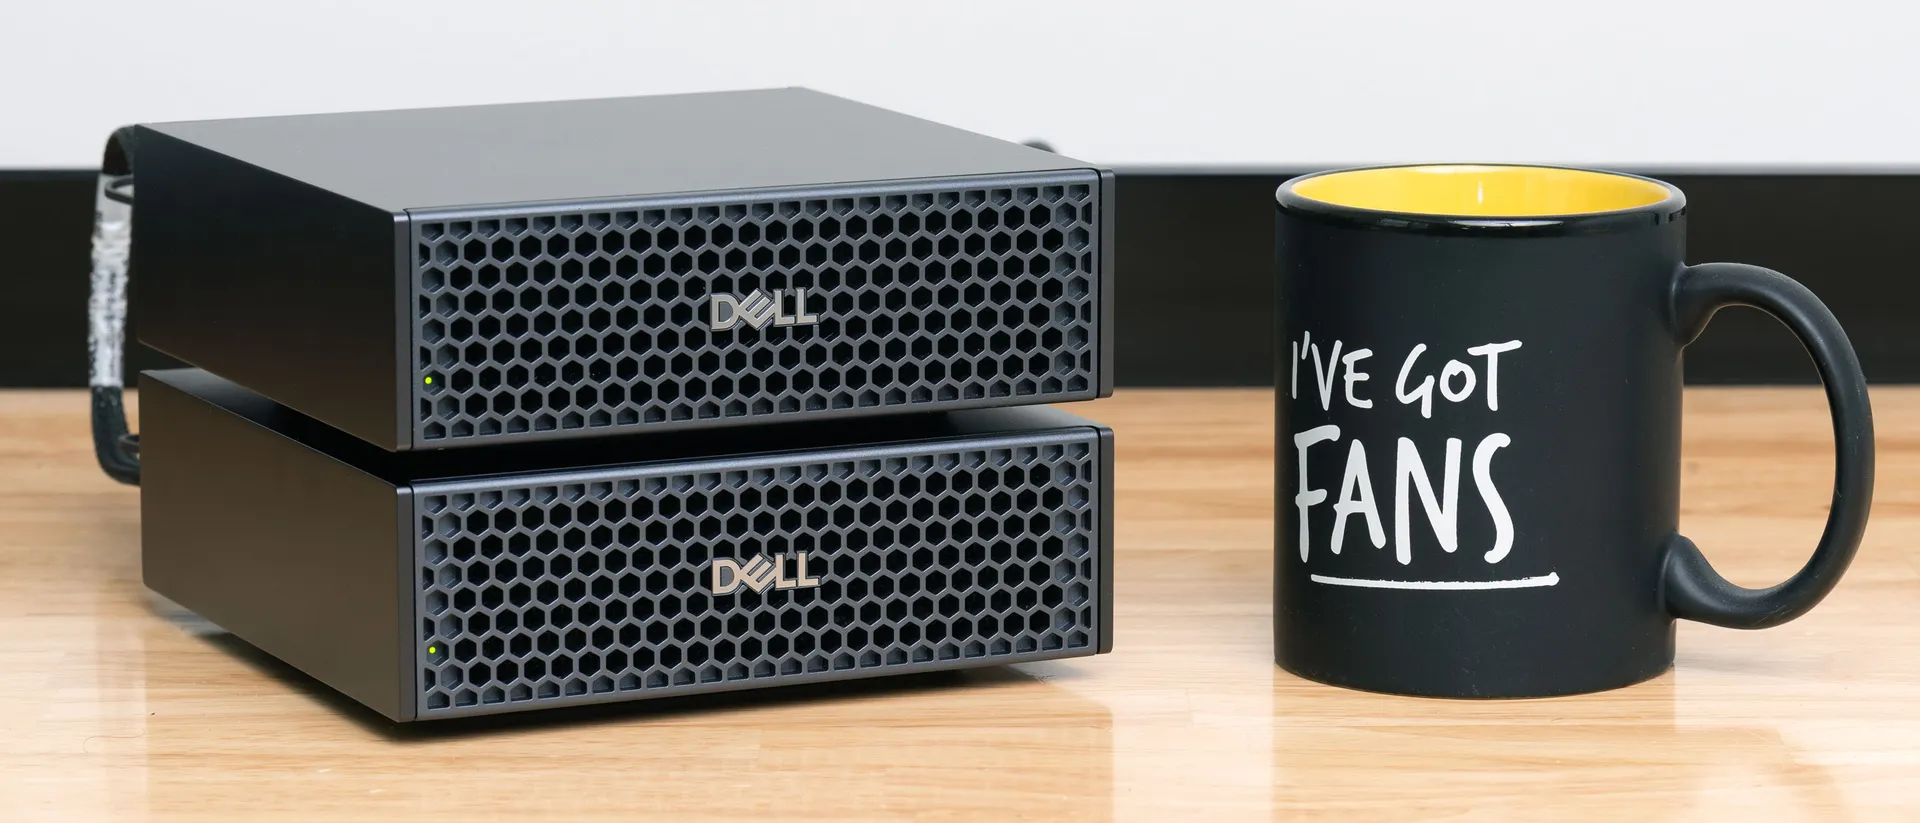
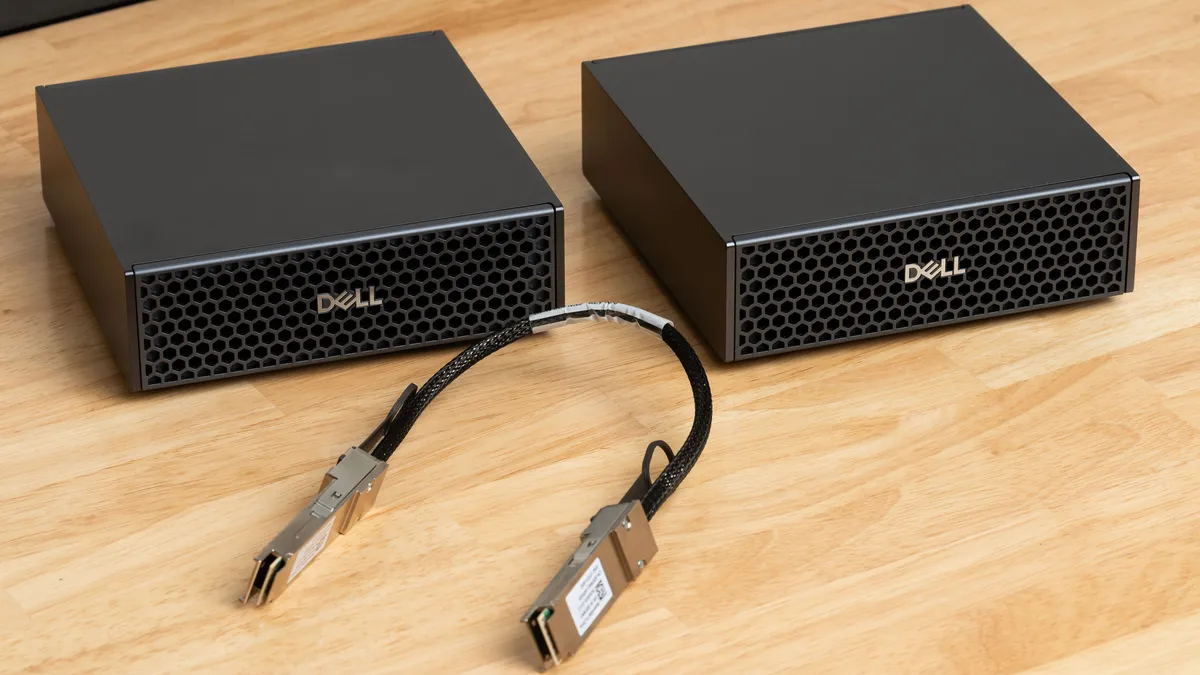
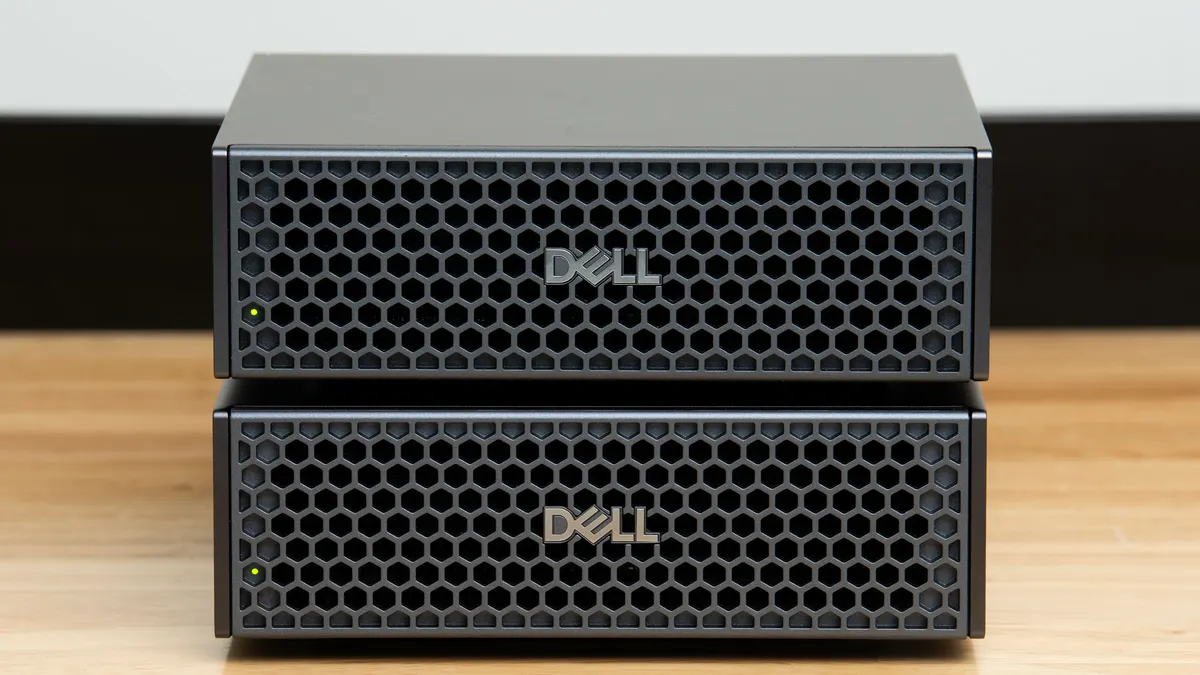
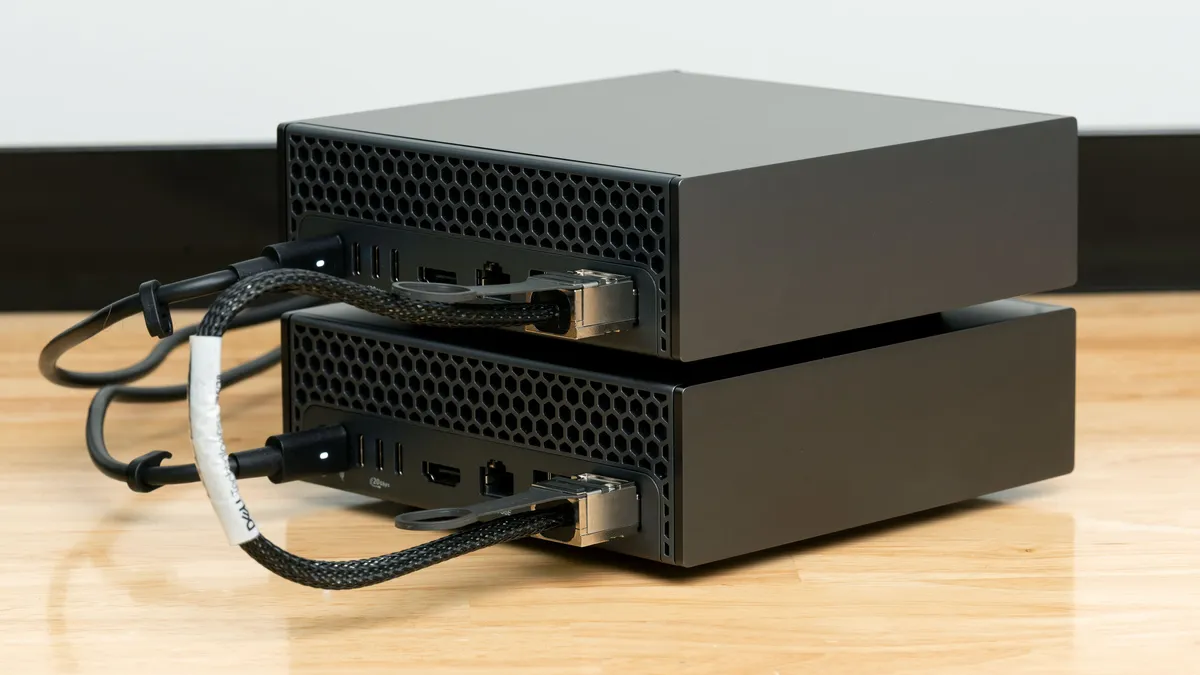
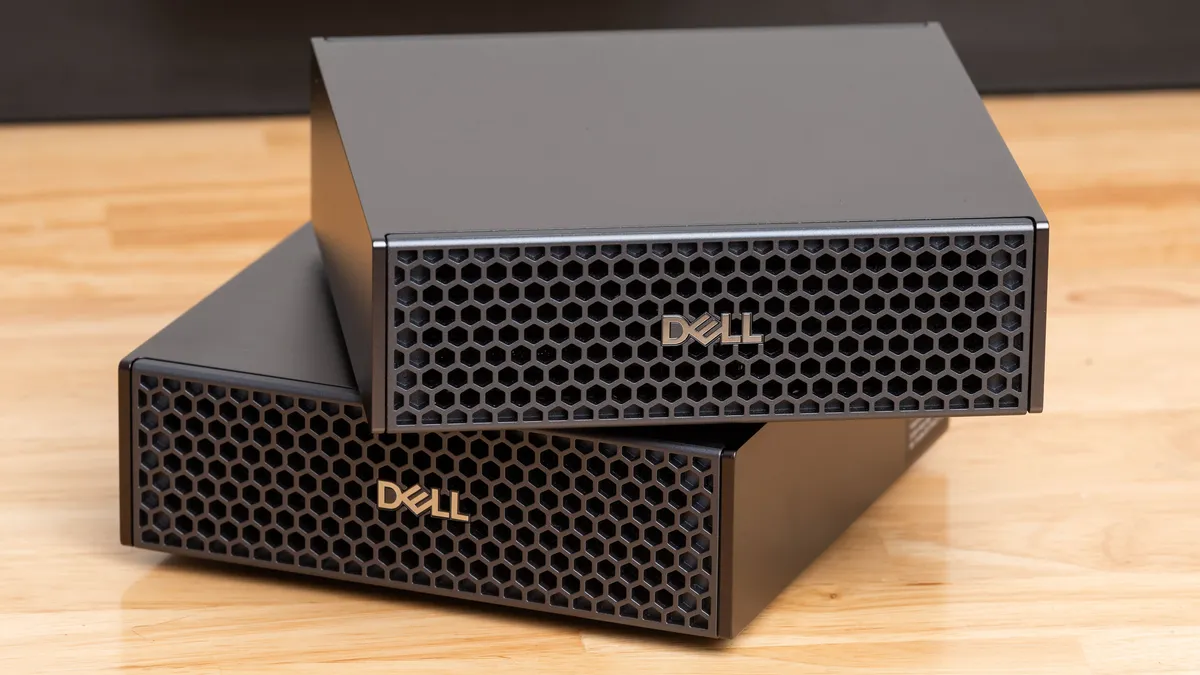
(Image credit: Tom's Hardware) Our local AI testing in 2026 has focused on large language models that can fit entirely into the 128GB of unified memory on Nvidia GB10 and AMD Strix Halo systems. Useful as those smaller open models can be, there is sometimes no replacement for displacement. Today, we’re exploring what’s possible from a local AI cluster with a pair of Nvidia GB10 systems, namely Dell’s Pro Max with GB10 (henceforth Pro Max), which gives us 256GB of RAM for a local AI sandbox. Quantizing an AI model from higher-precision to lower-precision data types involves tradeoffs for performance and accuracy. And even in quantized form, some advanced open models are still too large to fit within 128GB. But those models can be distributed across multiple local systems using the network as a scale-out backbone, just as they are in the data center. Why scale out GB10 systems (or Strix Halos, or Macs)? Local token factories with large VRAM pools built up from discrete GPUs can get crazy, fast.…