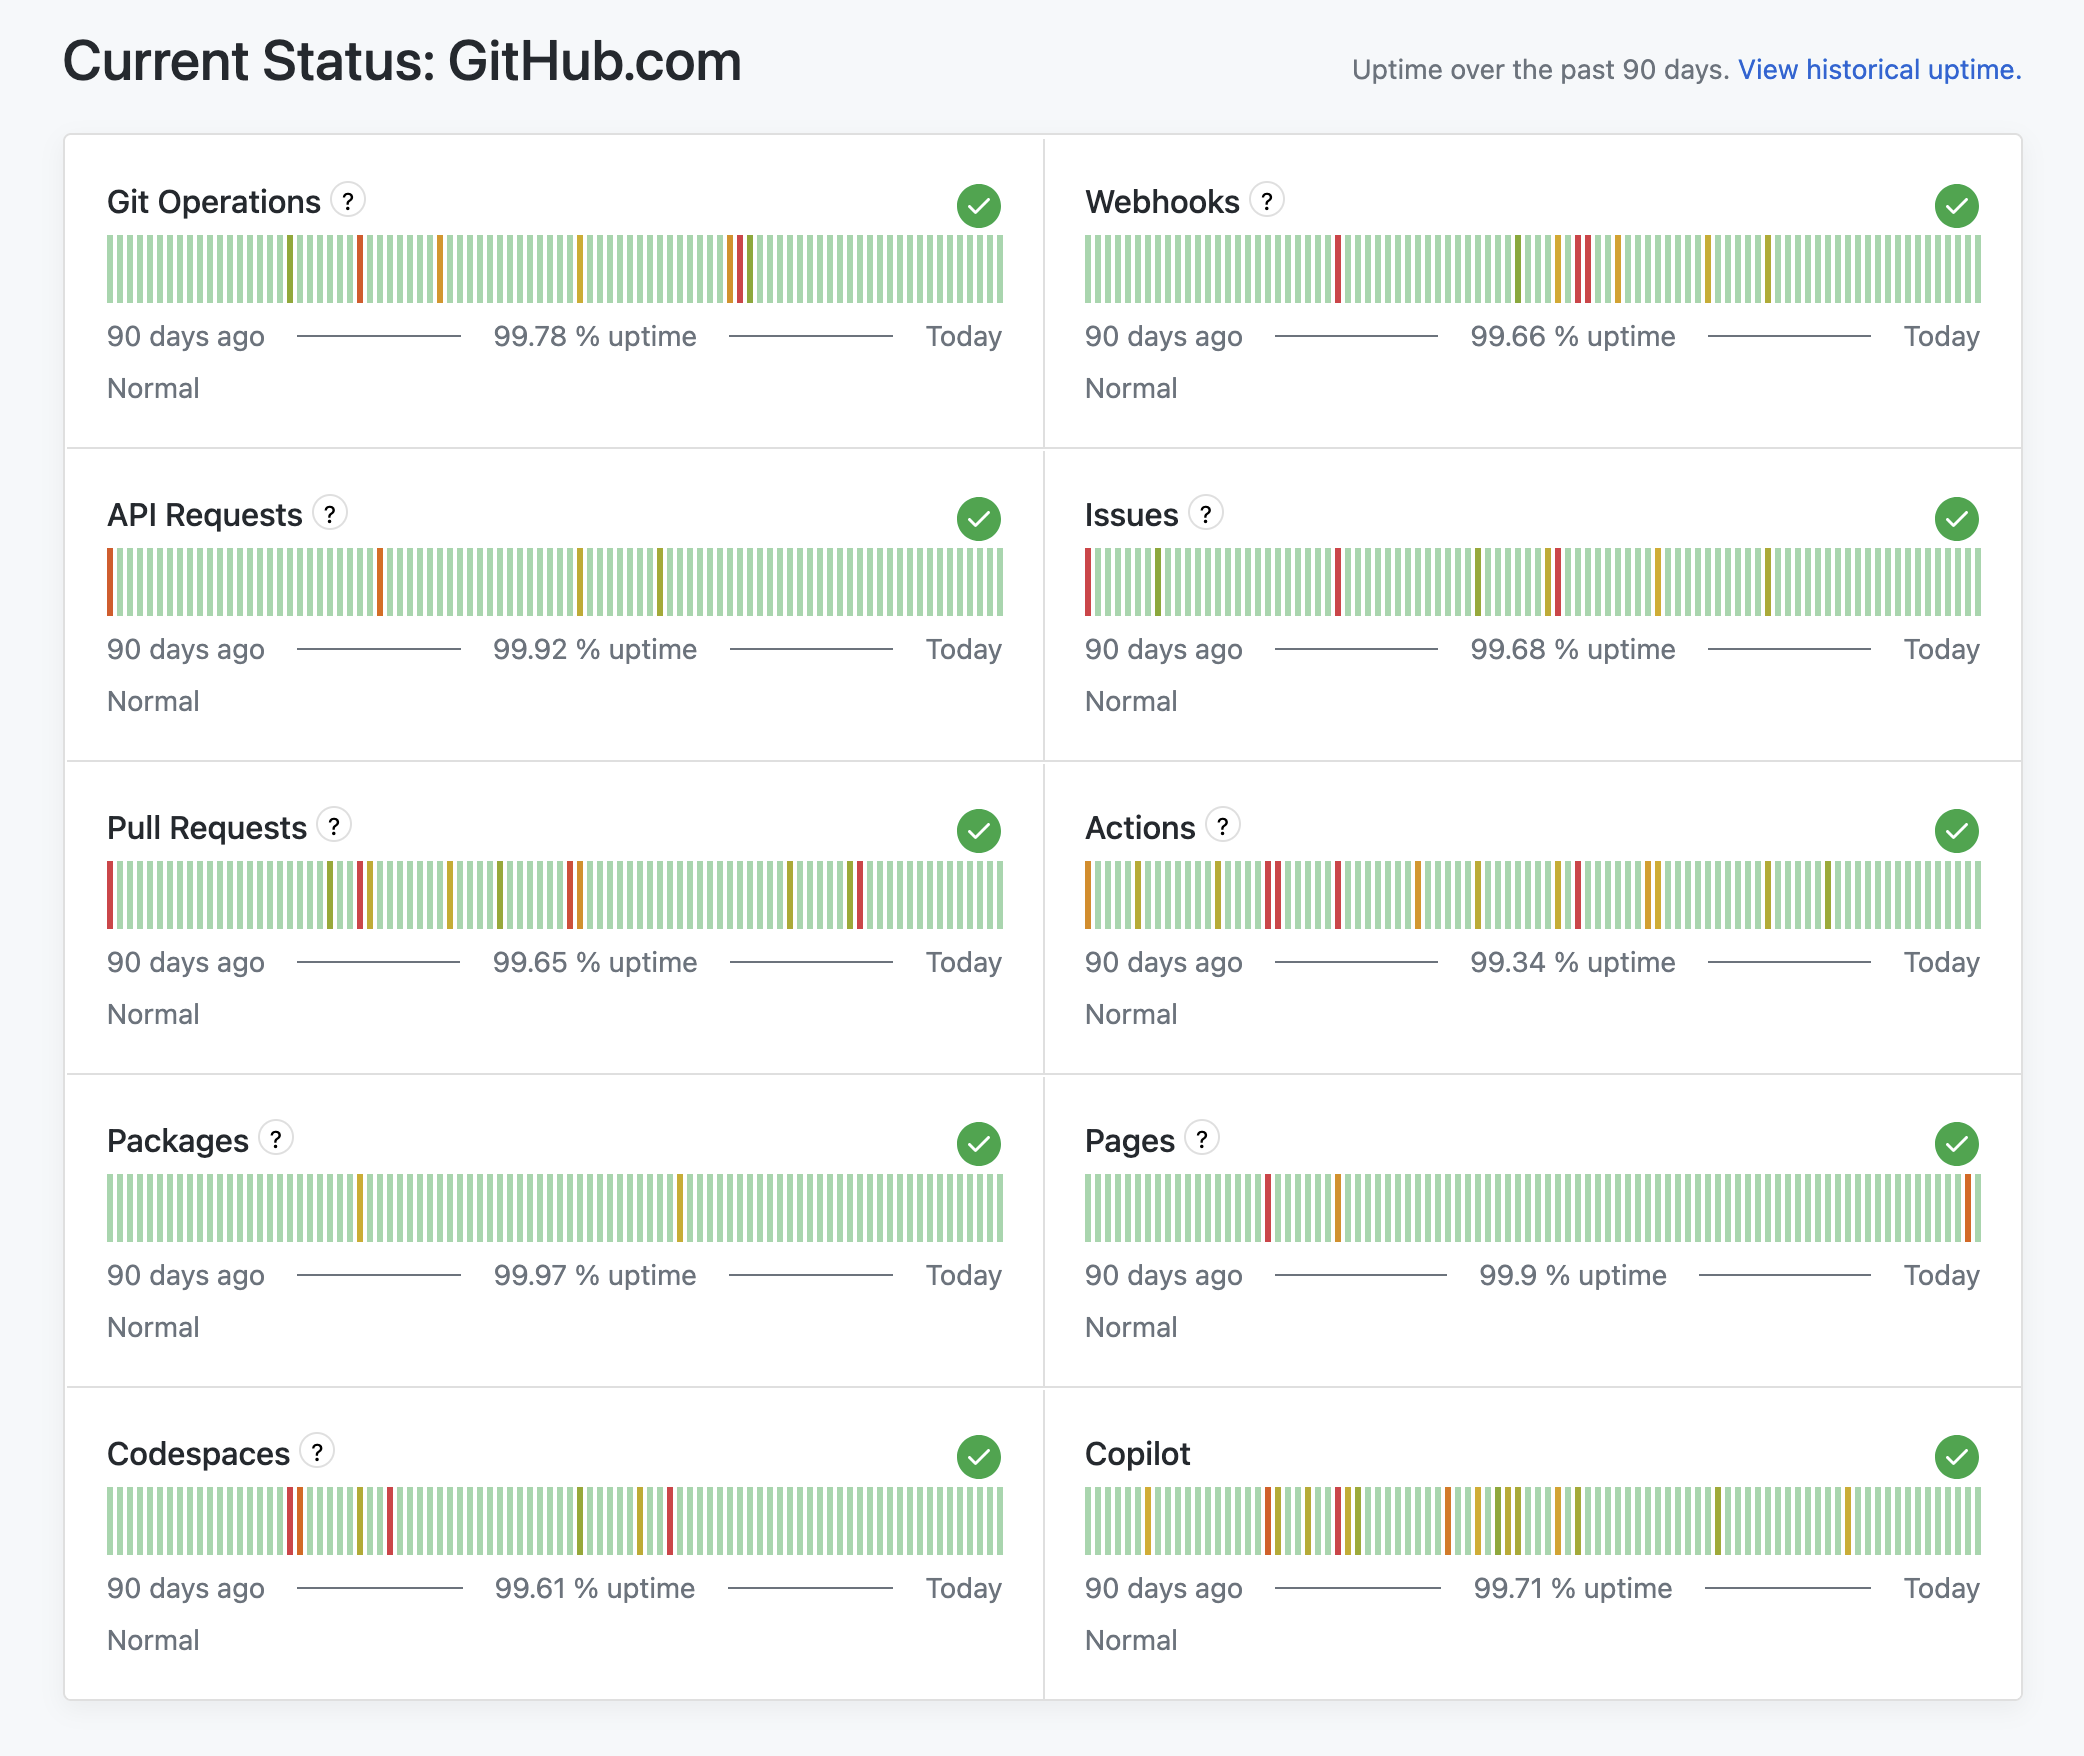
GitHub is where millions of developers do their most important work, and that comes with a responsibility we take seriously. Earlier this year, we shared an update on GitHub’s recent availability issues and the work we’re doing to address them. Alongside those reliability investments, we have prioritized improving how we communicate during and after incidents, increasing the specificity of the data we provide and giving better insight into the platform’s health overall.
Guided by transparency, accuracy, and timeliness, we’re rolling out three changes to how we communicate service health—outlined below.
A new “Degraded Performance” state for more accurate incident classification
Per-service uptime metrics published for each service
More granular insights on service disruptions, starting with a dedicated “Copilot AI Model Providers” component for clearer communication around model provider availability
Improving accuracy
We’re adding a new incident severity level: Degraded Performance .…