TLDR
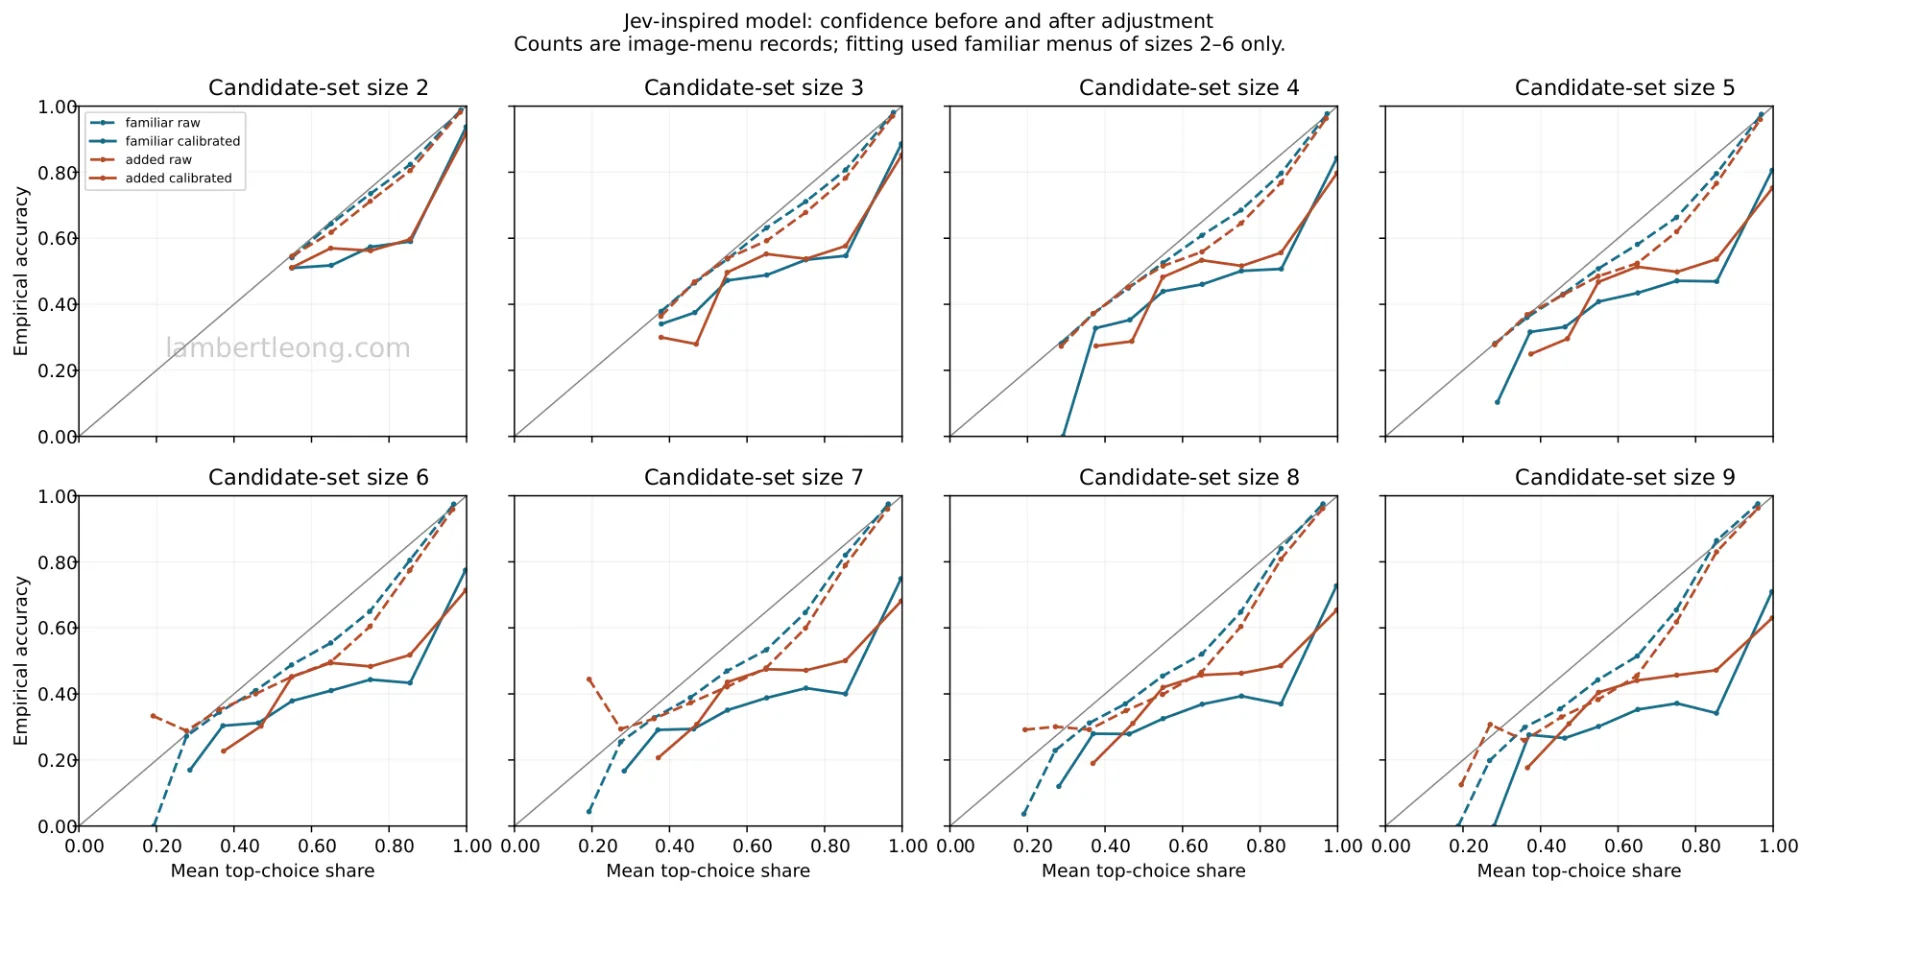
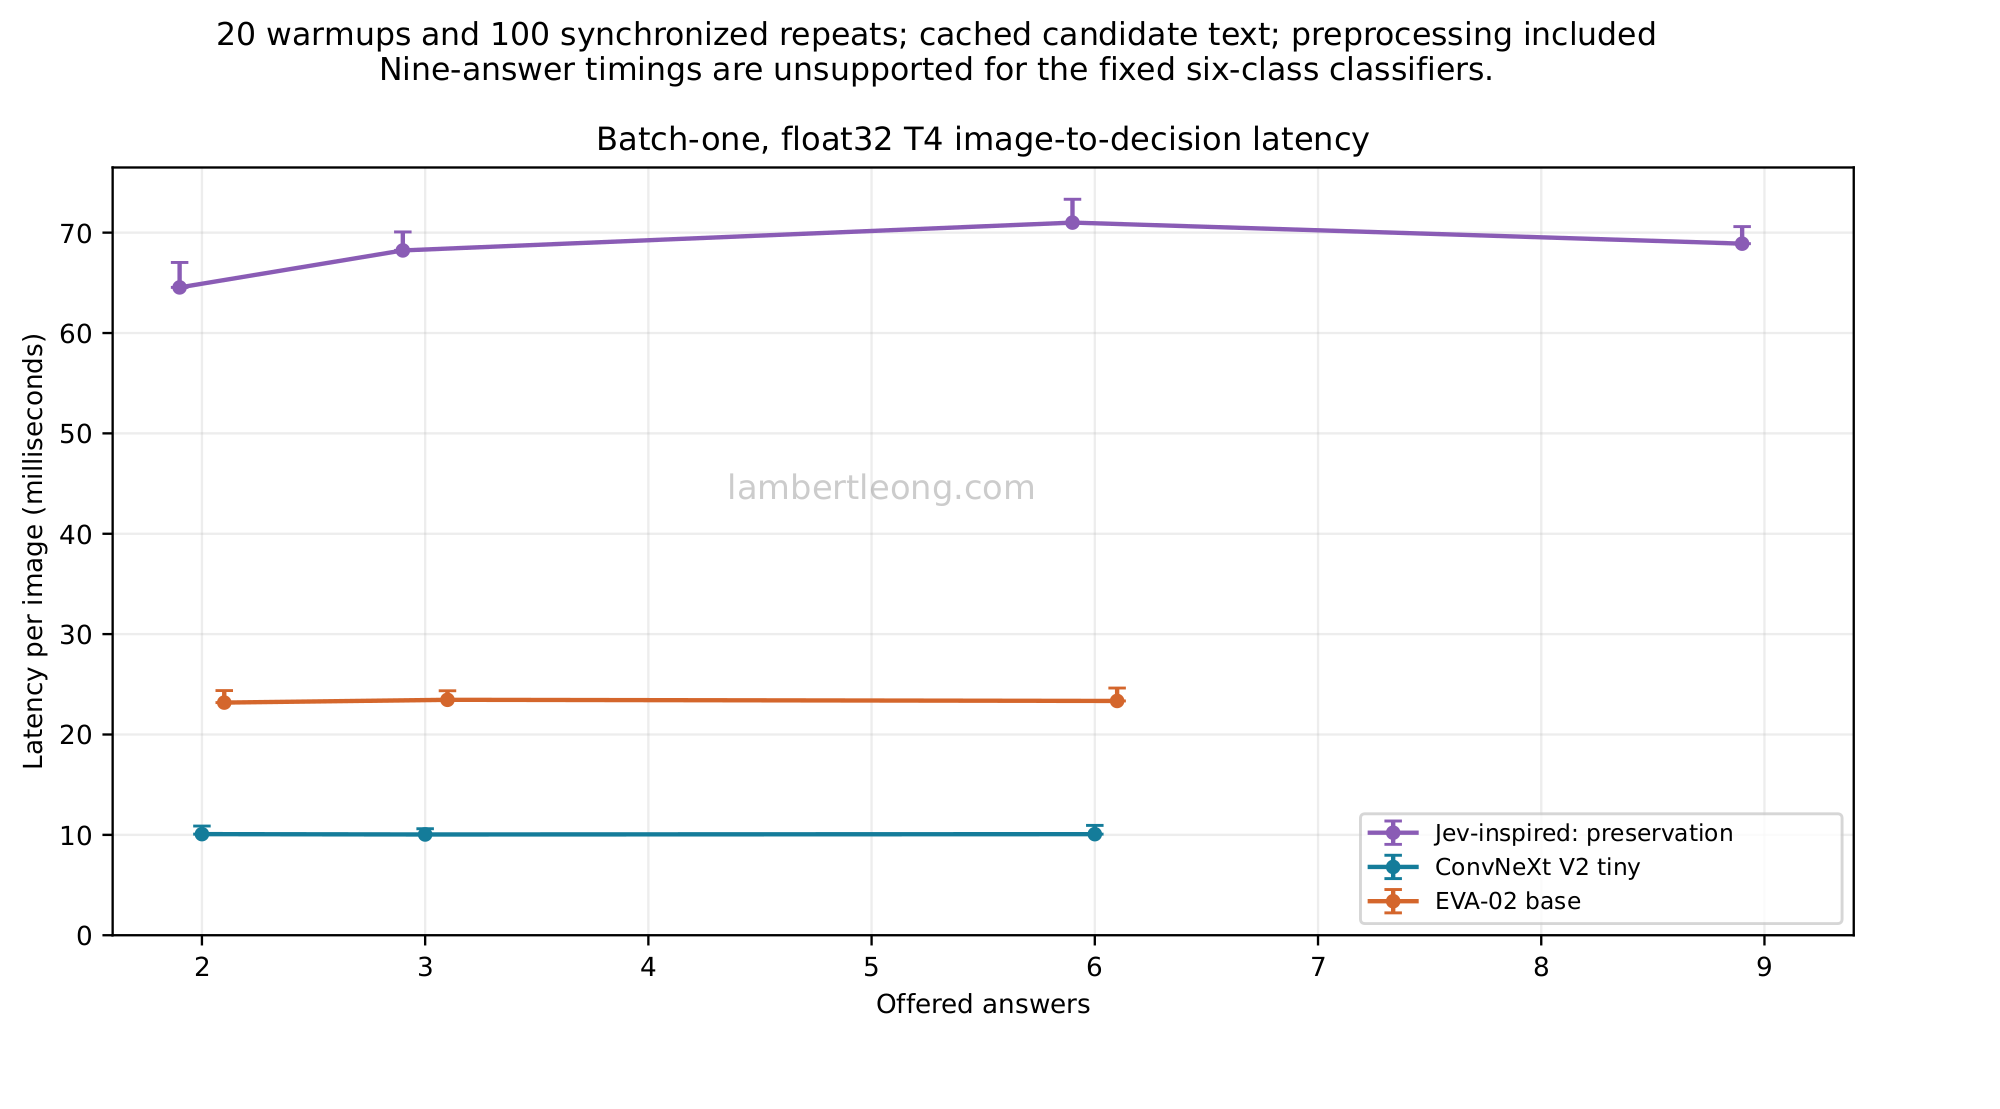
Build a Jev-inspired model that compares images with the answer options. We use an existing pathology image–text model and train a small adjustment to the image representation, called an adapter. The tutorial shows how to build and evaluate that interface.
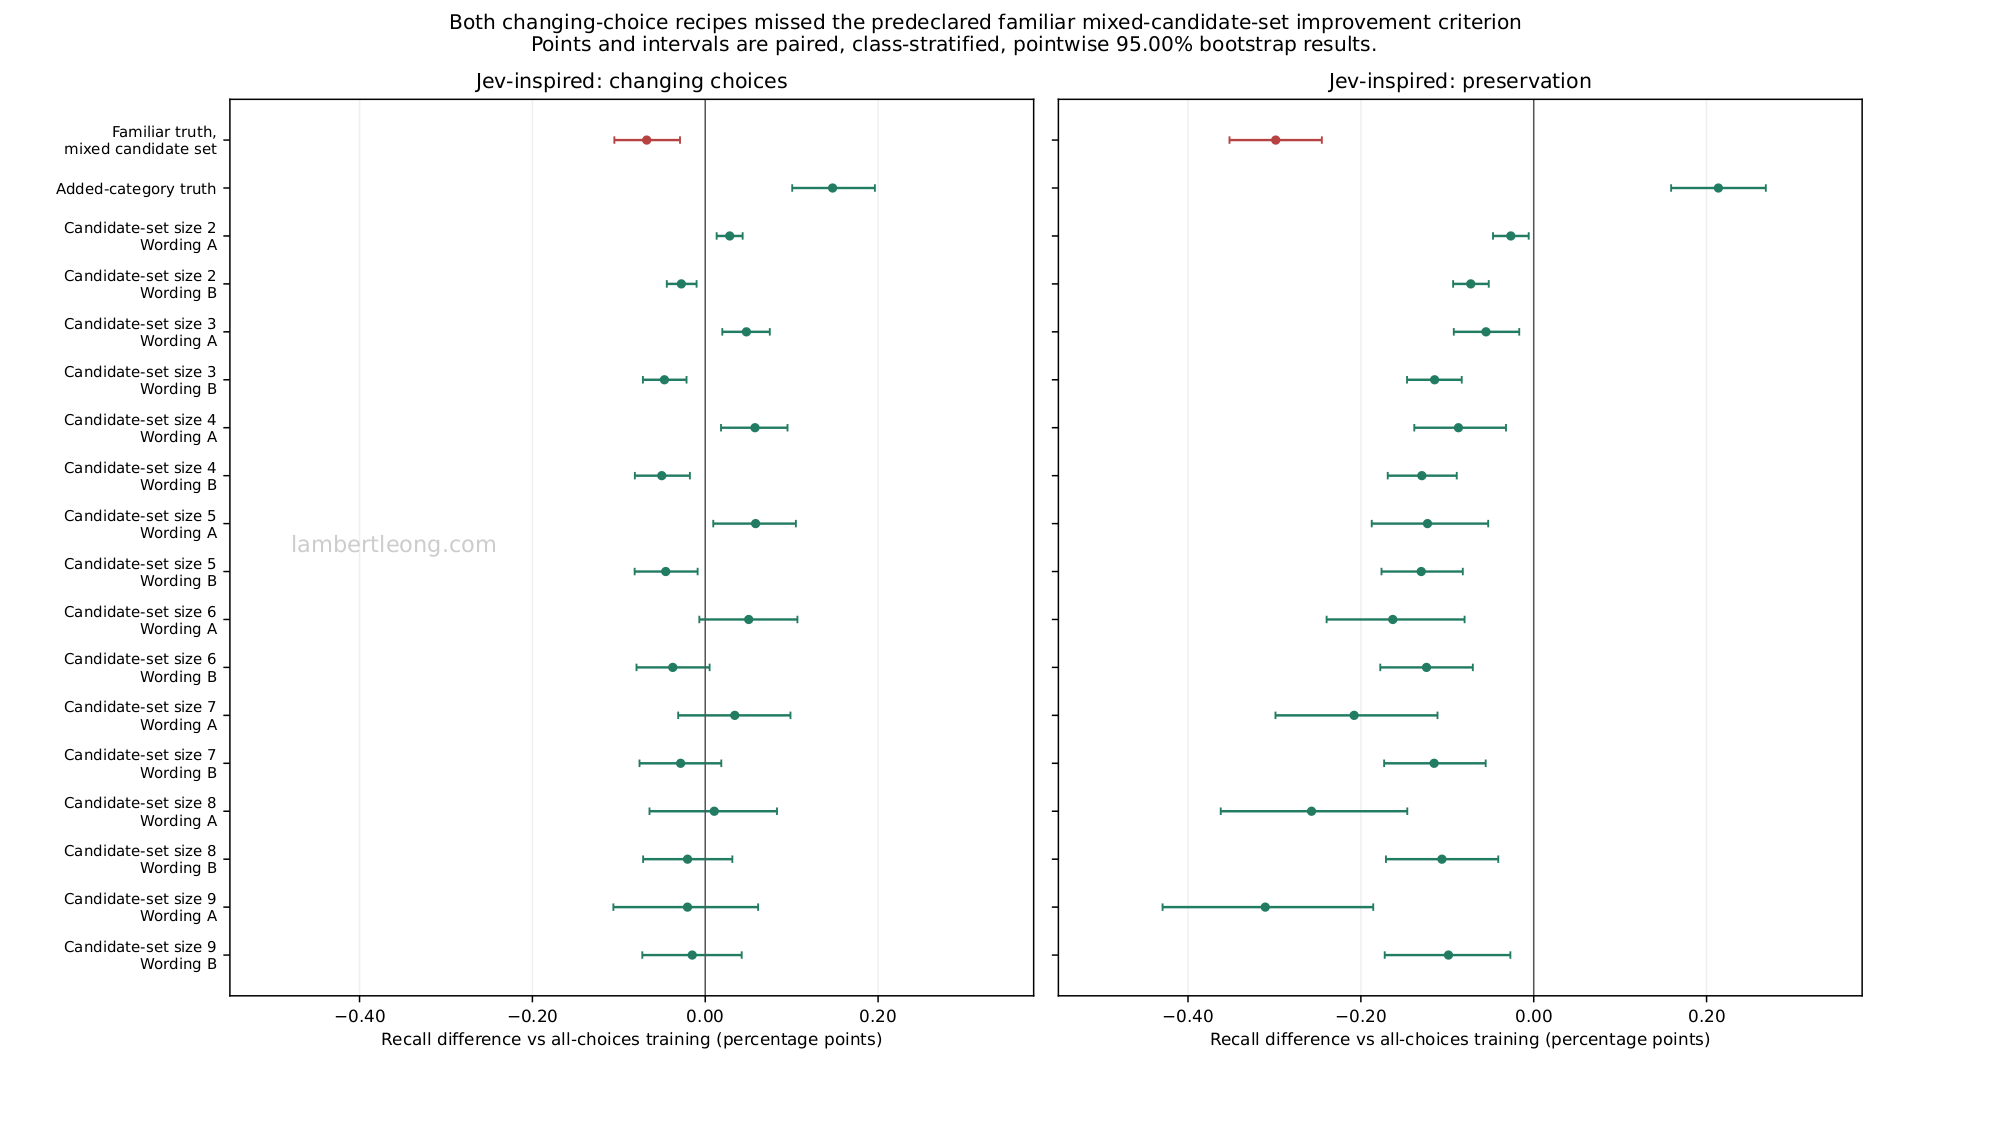
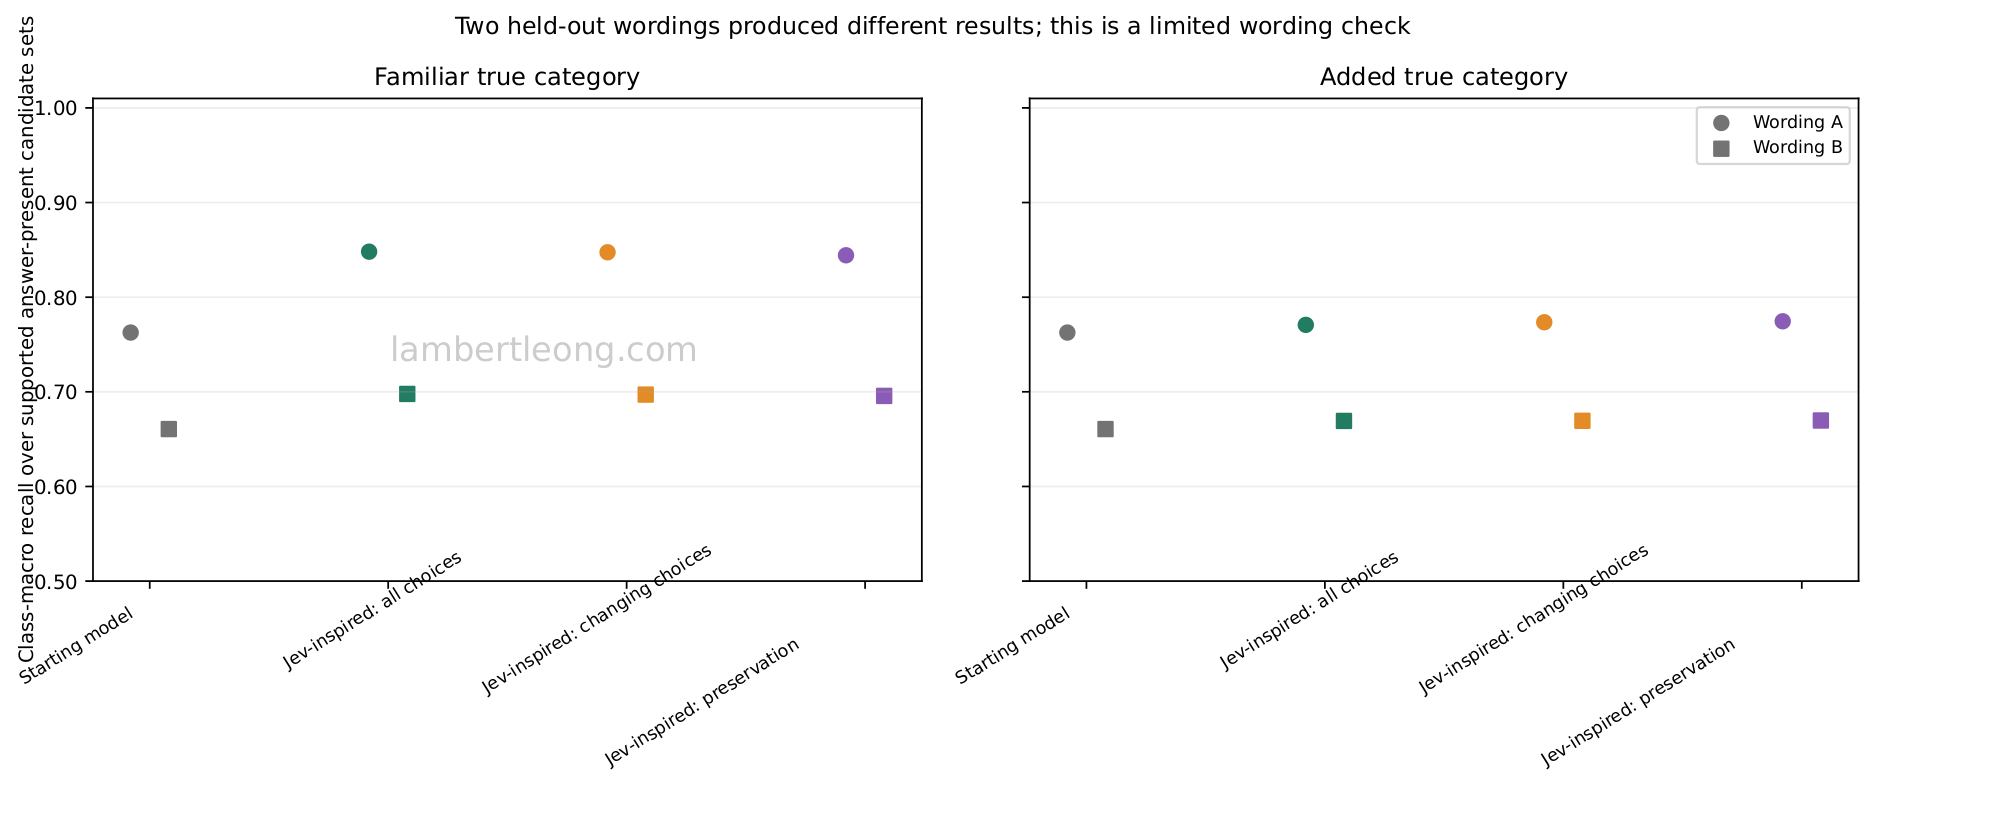
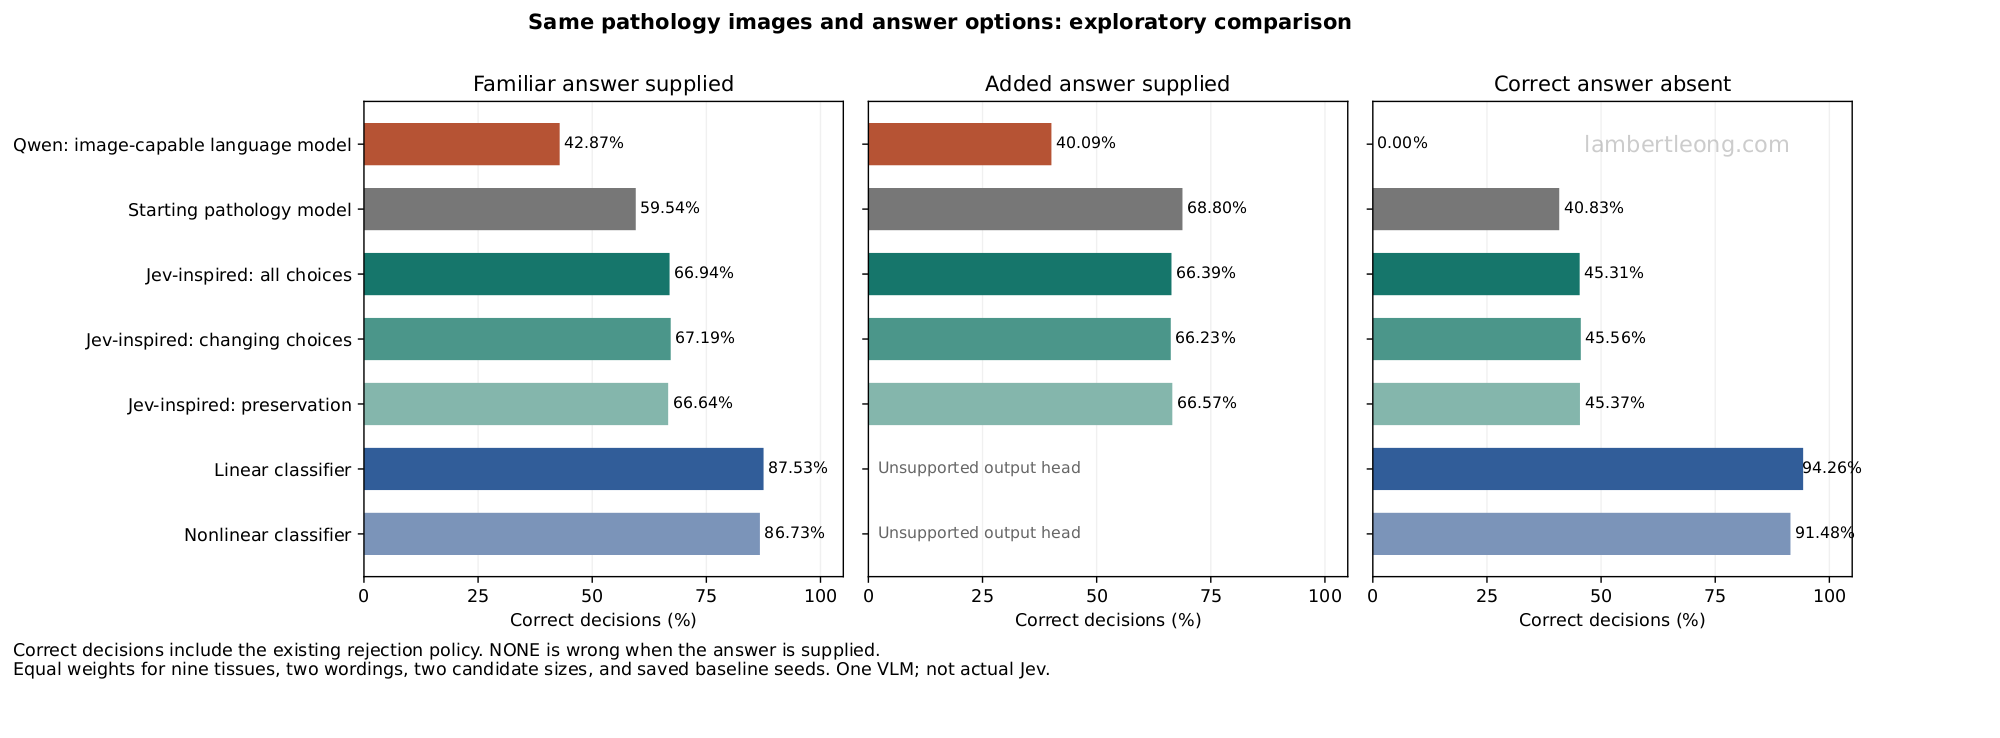
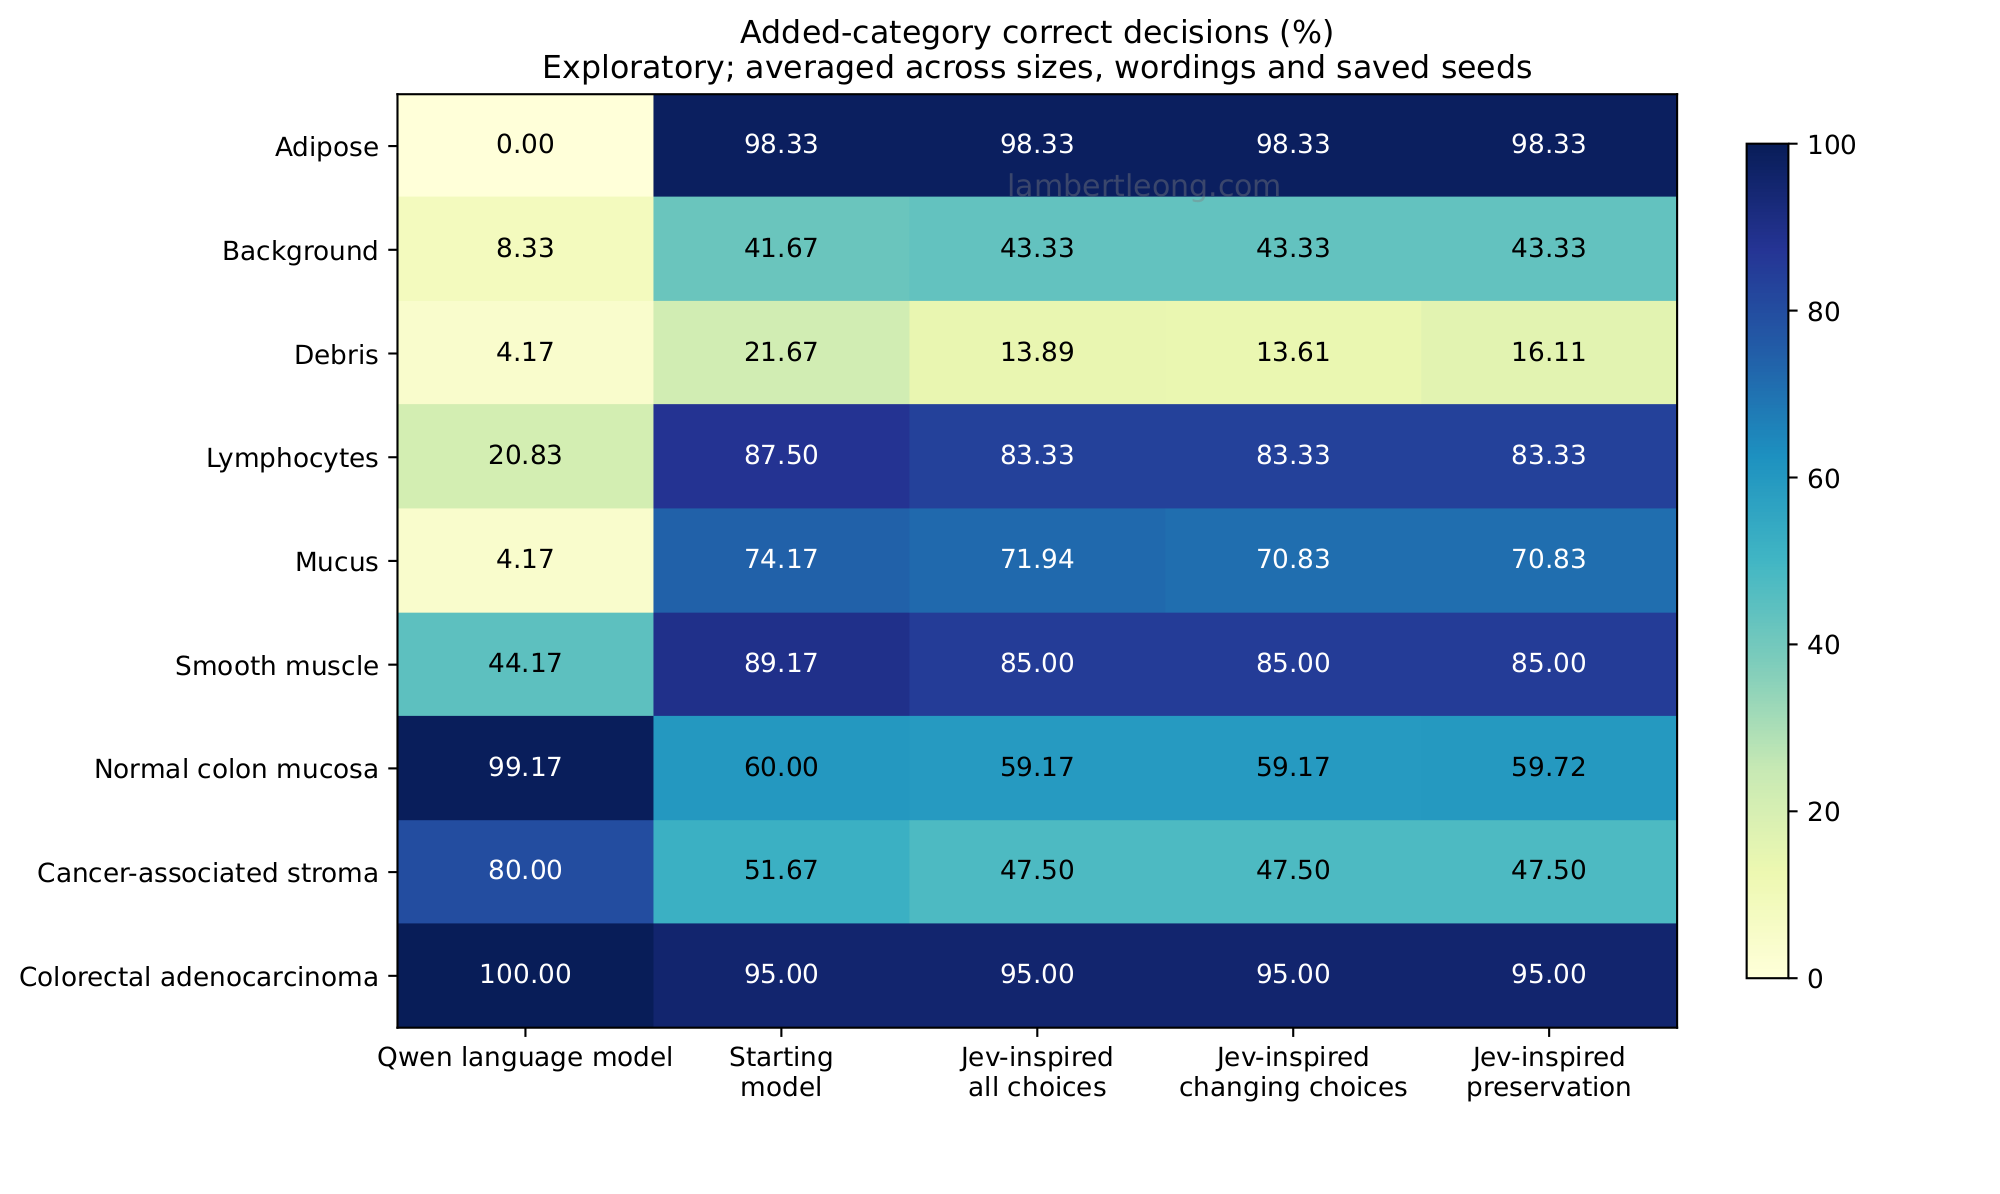
Our Jev-inspired model beat the Qwen model we tested on the same pathology questions. Correct final decisions were about 67.00% versus 43.00% for familiar categories, and 66.00–67.00% versus 40.00% for added categories. The image-capable language model we tested was Qwen2.5-VL-3B-Instruct; we did not benchmark Jev itself.
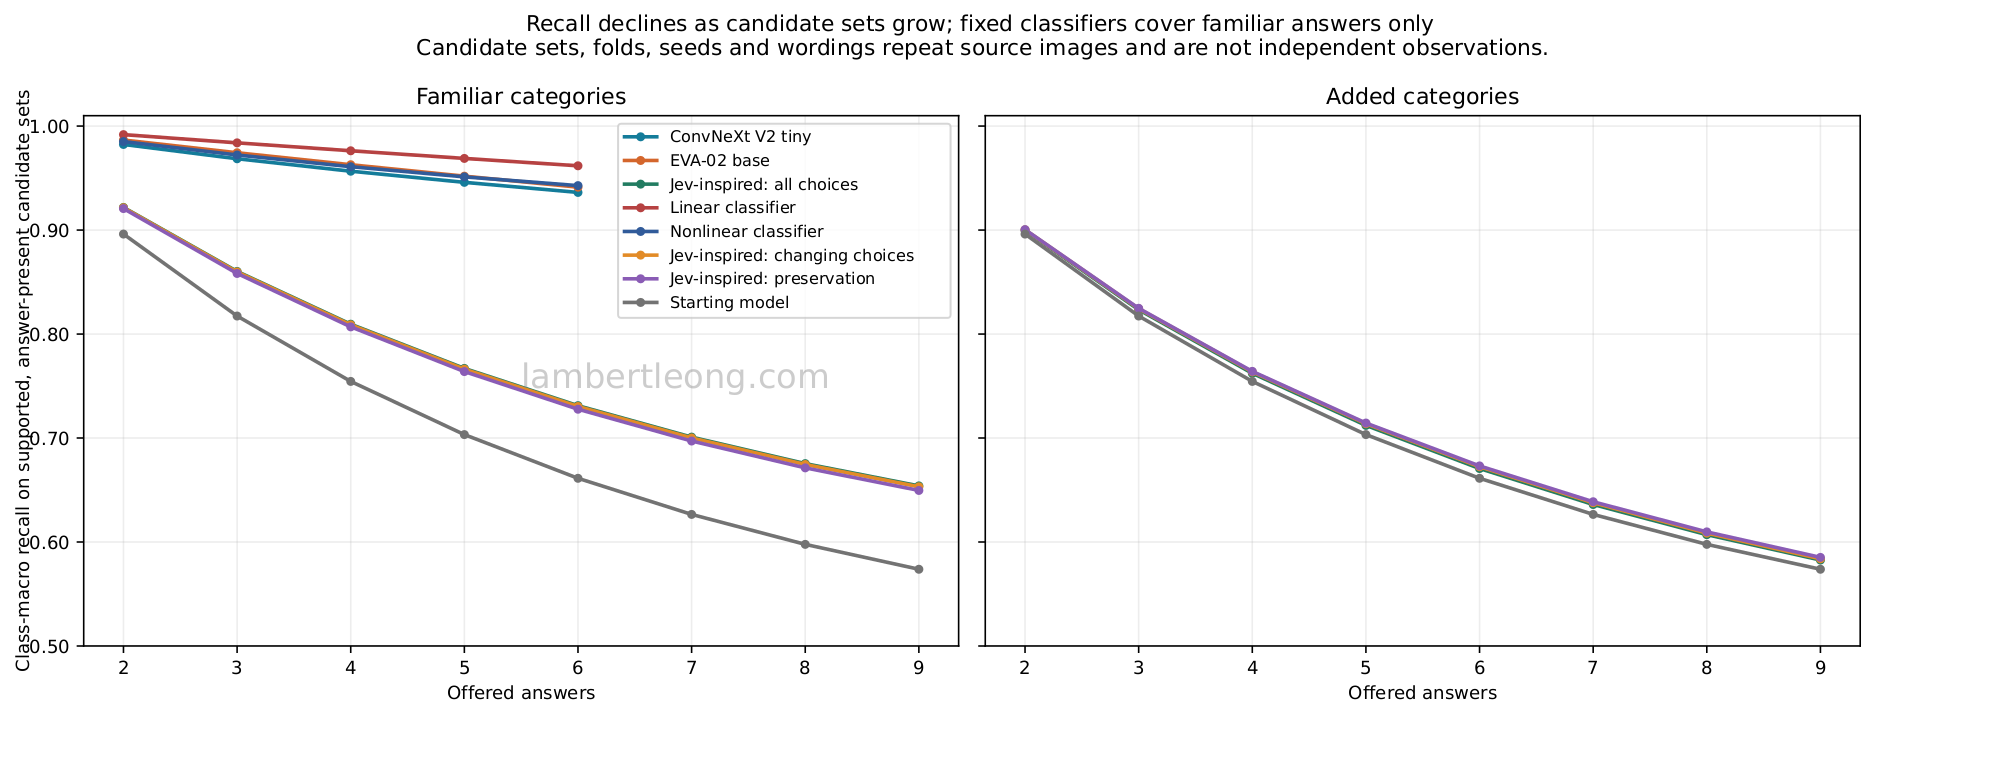
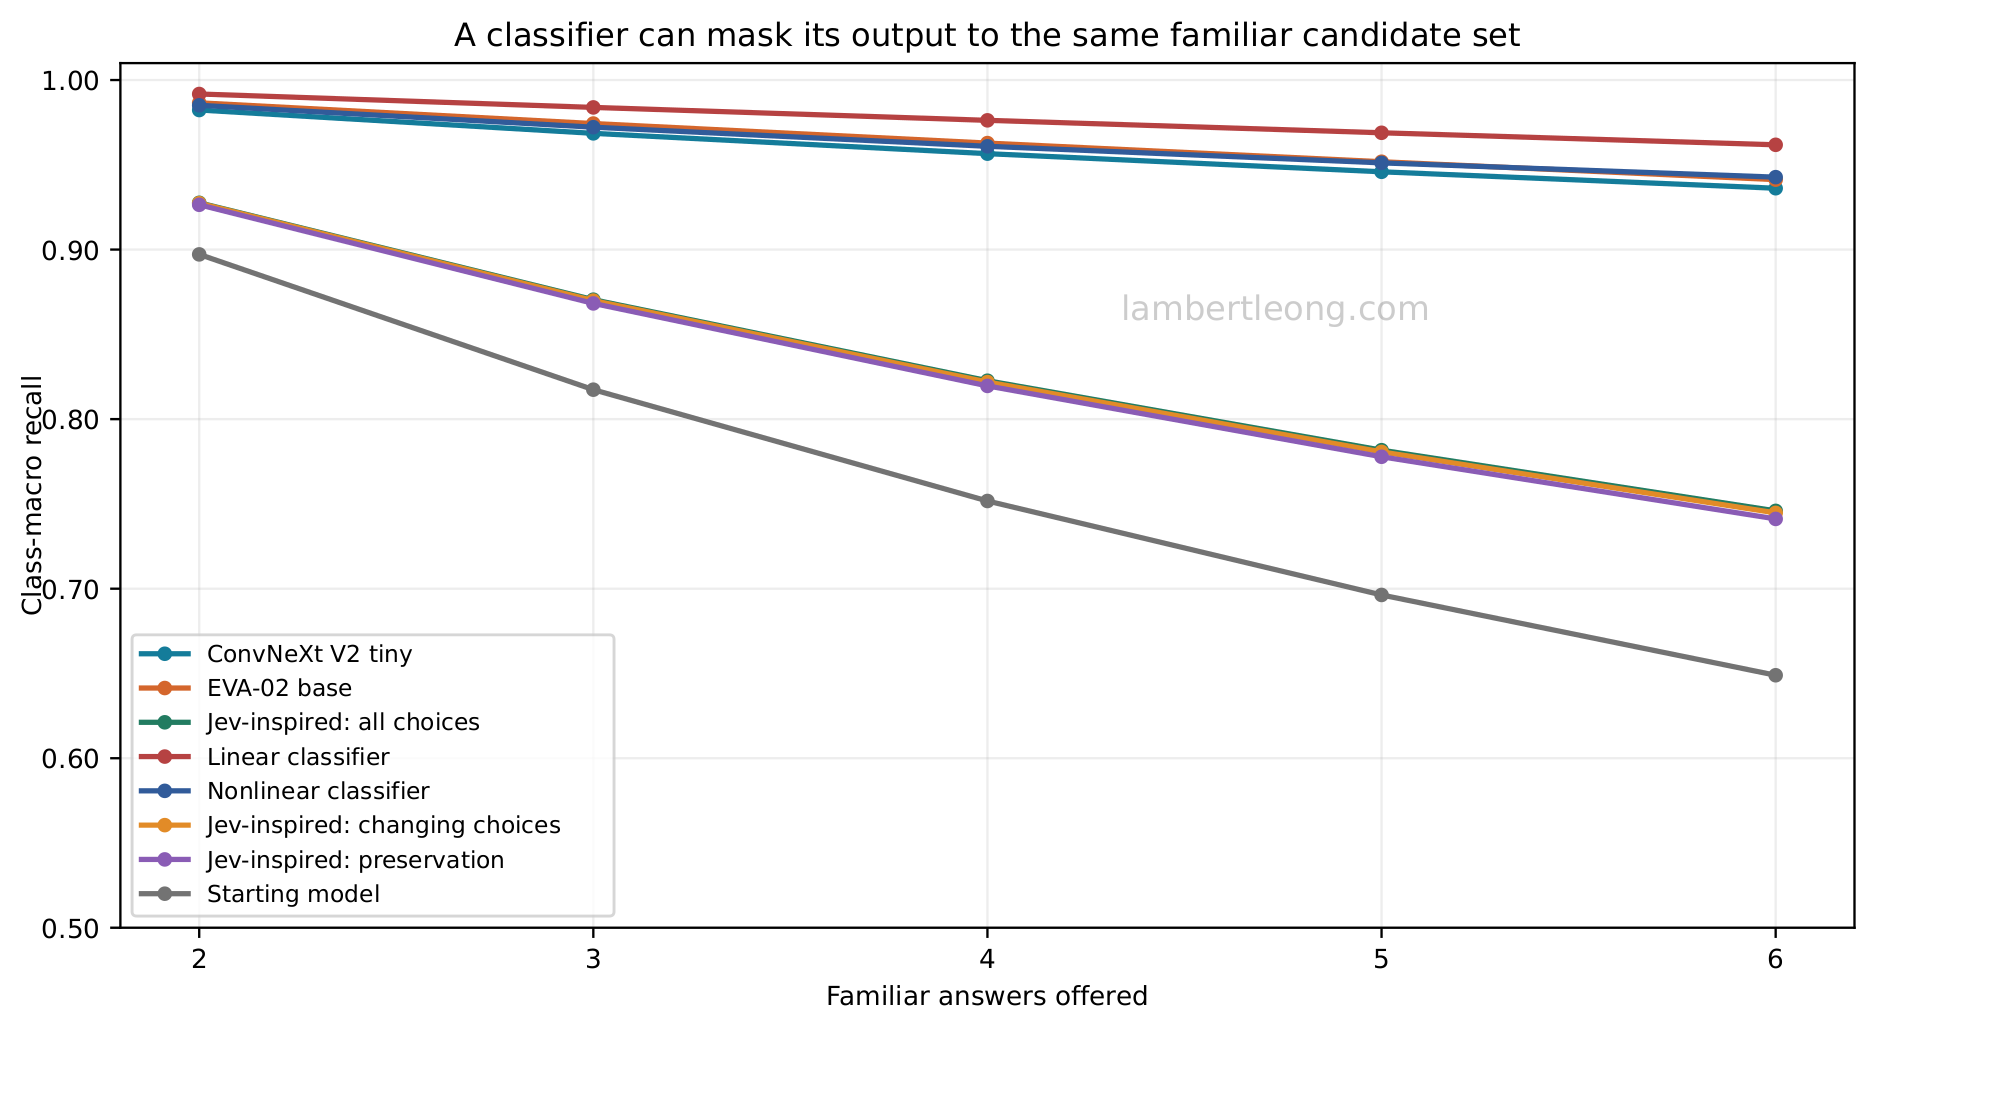
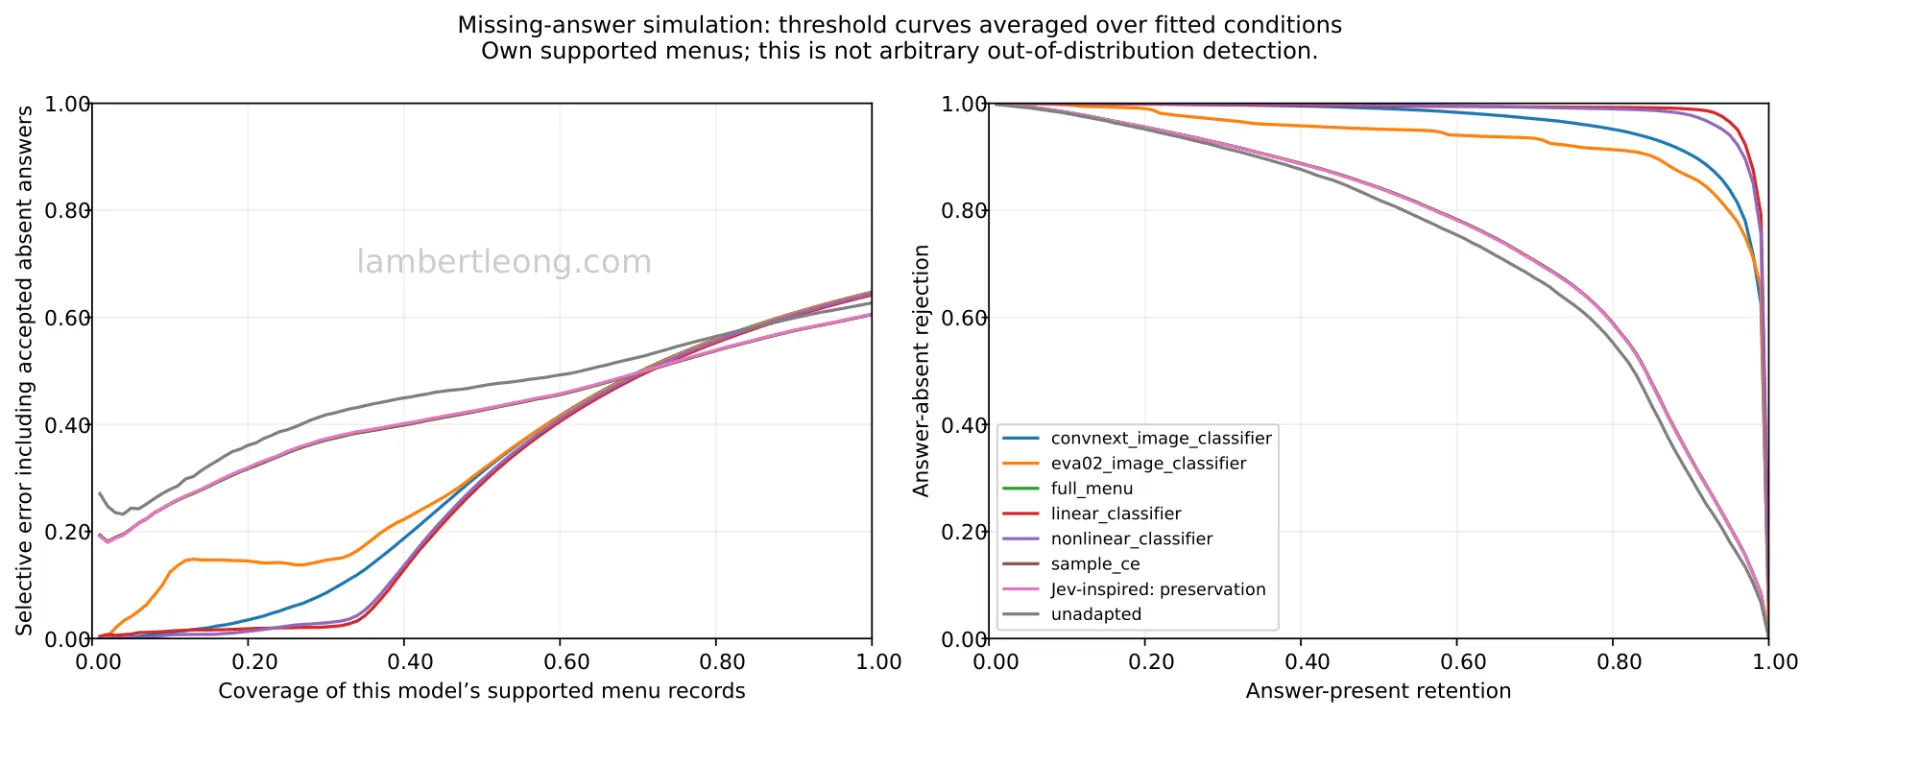
A classifier trained for the familiar tissues was stronger there. The linear classifier chose correctly 98.00% of the time and made correct final decisions 88.00% of the time after rejection. Its fixed output head has no output for an added category.
The starting pathology model was already a strong reference point. Before our extra training, it reached 69.00% correct final decisions on added categories.…