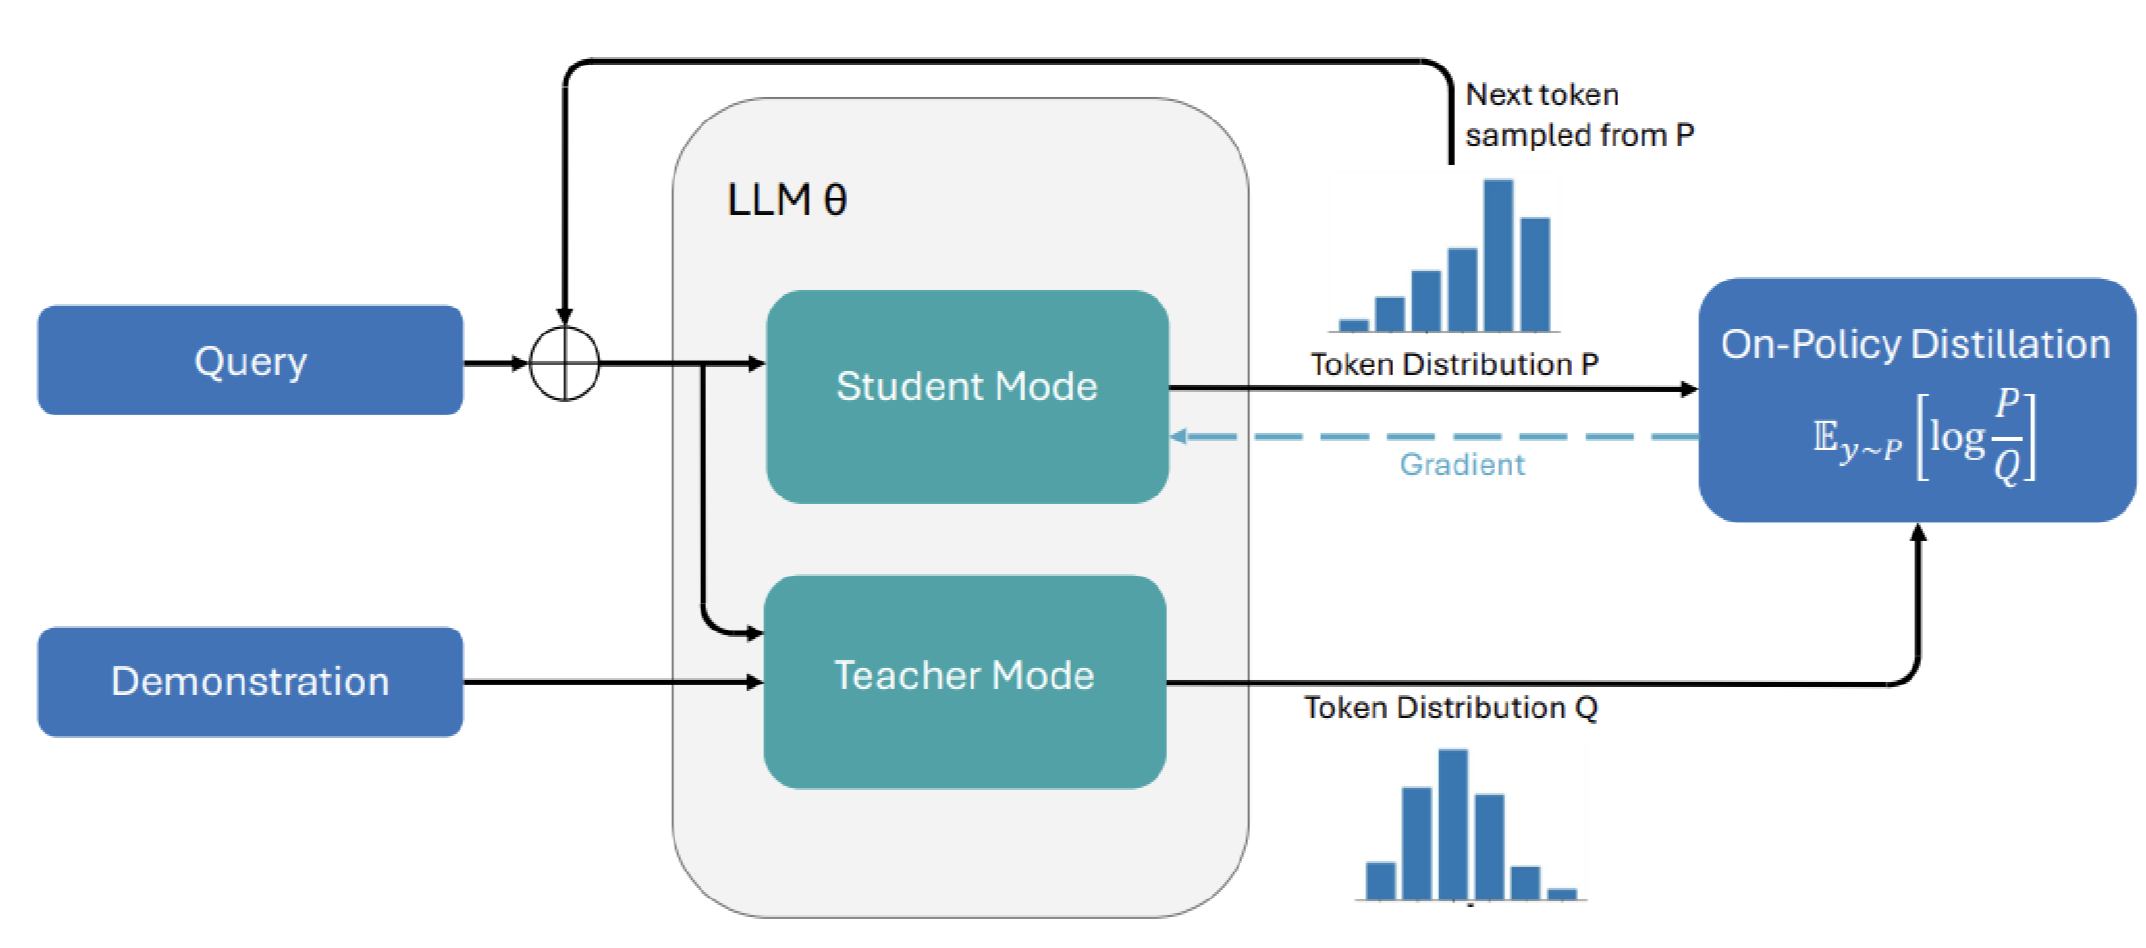
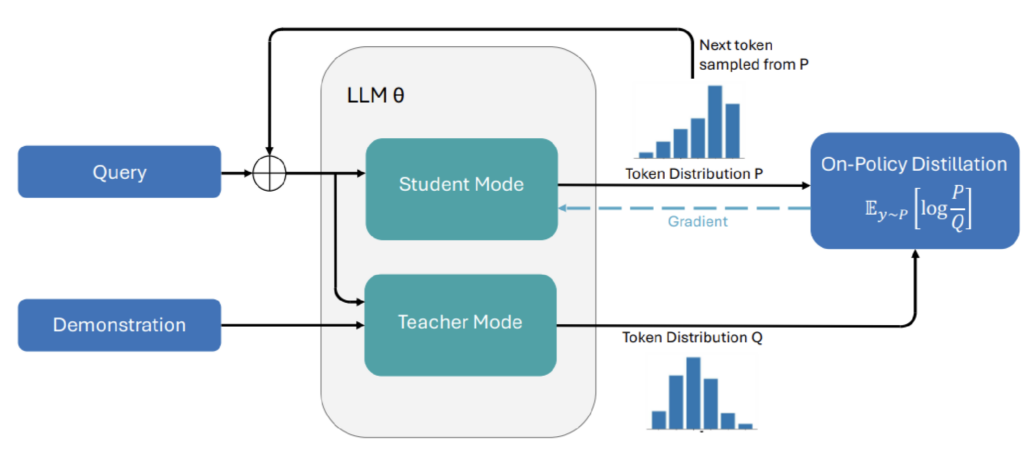
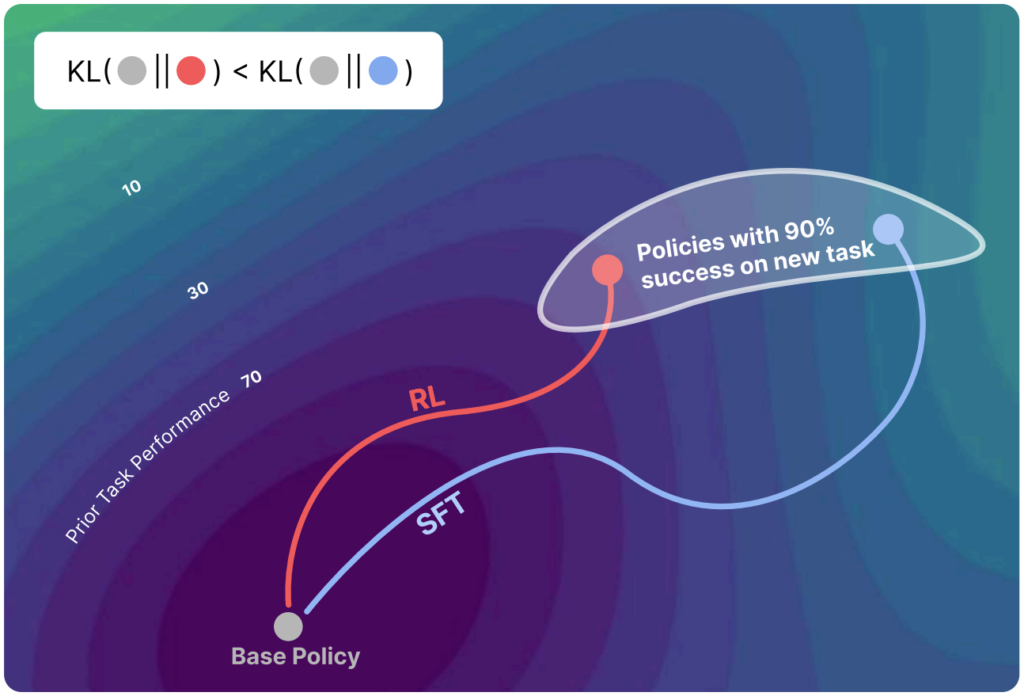
On-policy self-distillation (OPSD) (1) has taken the world of machine learning research by storm. Although OPSD frameworks rely heavily on older, more established approaches, the first papers on the topic were only submitted in late January 2026, just under nine months ago at the time of writing this article [1, 2]. Several dozen papers have followed within that brief timespan [3], covering everything from extensions [3] to limitations [4, 5].
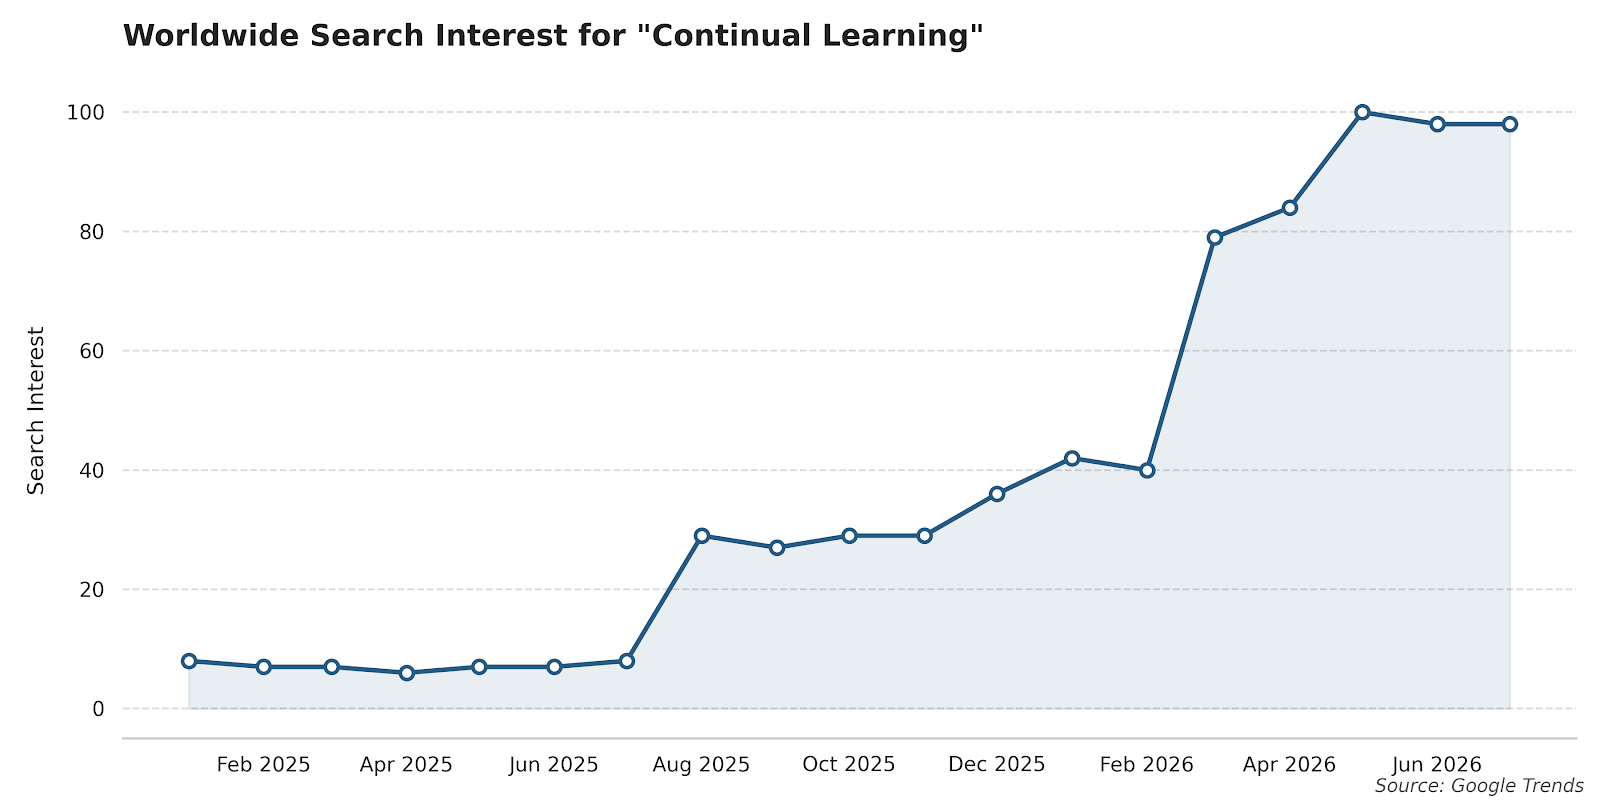
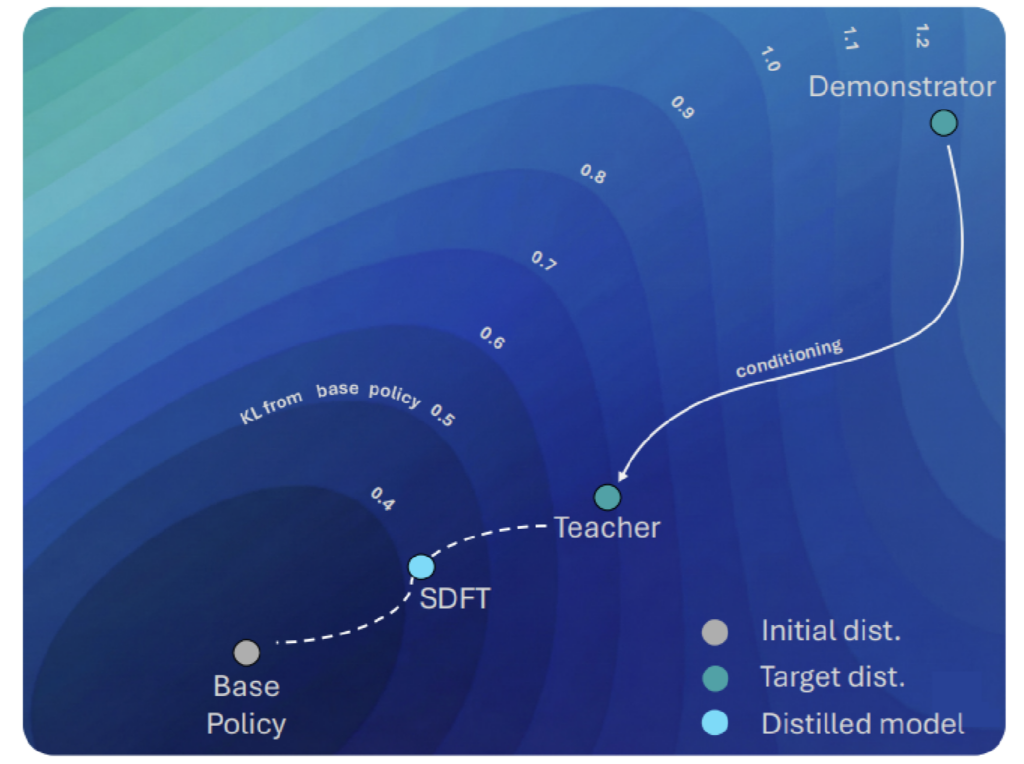
In this article, we'll explore the literature on OPSD, mainly through the lens of the Self-Distillation Fine-Tuning (SDFT) framework introduced by Shenfeld et al. in Self-distillation enables continual learning [1]. As we'll see, the term "continual learning" in the paper's title refers to a model's ability to effectively and dynamically learn from a datastream. We'll start by examining the problem OPSD frameworks set out to solve and the approaches they build on.
After that, we'll look at how SDFT works and the theoretical explanations for its success.…