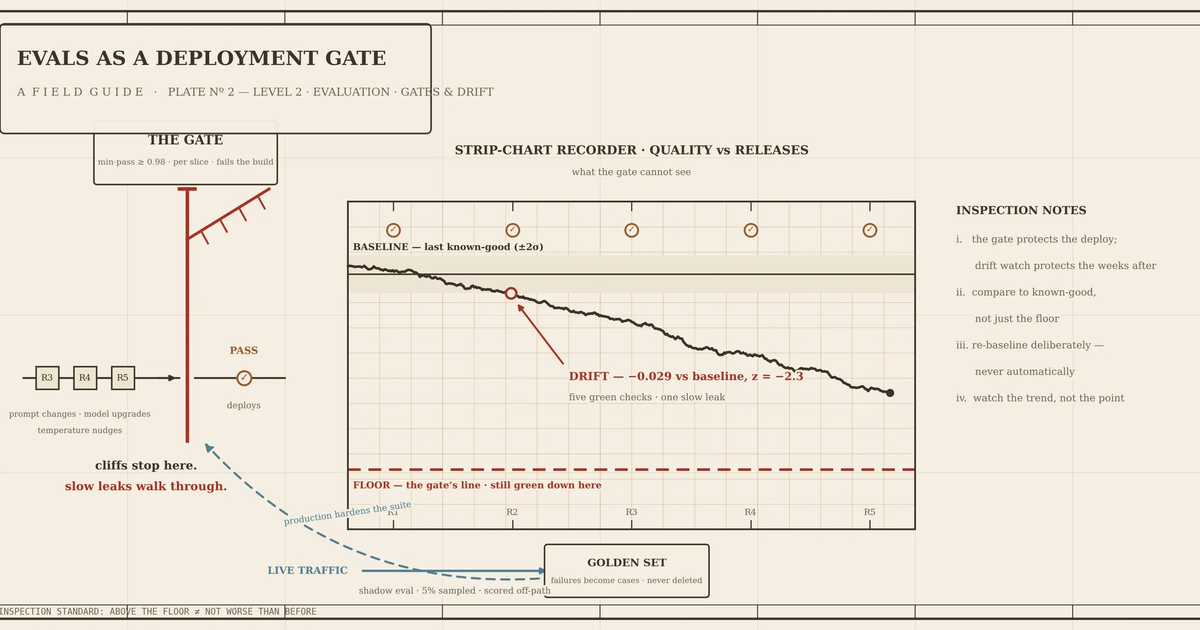
If you can deploy a prompt change without an eval failing the build, you don’t have evals — you have a notebook. And once the gate is green, the slow leaks are still coming for you. Here’s the gate, the baseline, and the shadow- eval loop that catch both.
This is Level 2 of the maturity model: evaluation . The principle is short — you don’t ship on hope, you ship on a gate, and then you watch for drift afterward. A gate protects the moment of deploy. Drift detection protects the weeks in between. You need both, and they’re built from different machinery.
Most teams “do evals” the way they once “did tests” before CI: occasionally, manually, in a notebook, after something already went wrong. For LLM systems that’s not enough, because the thing most likely to silently break your product isn’t a code change — it’s a prompt tweak, a model upgrade, or a temperature nudge that looks harmless and quietly tanks quality on 8% of inputs.…