1. Introduction
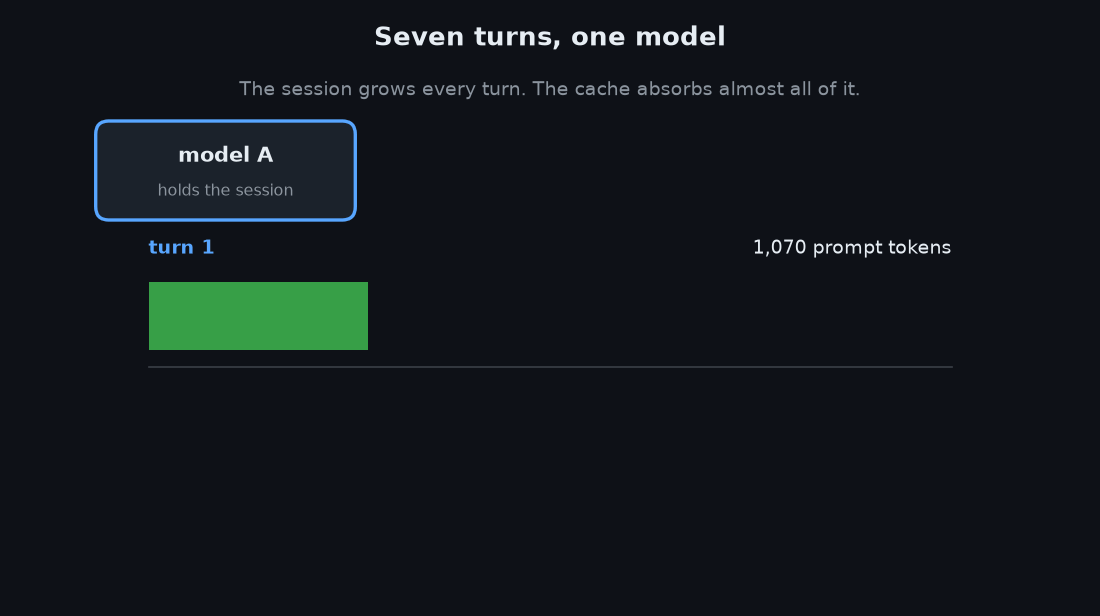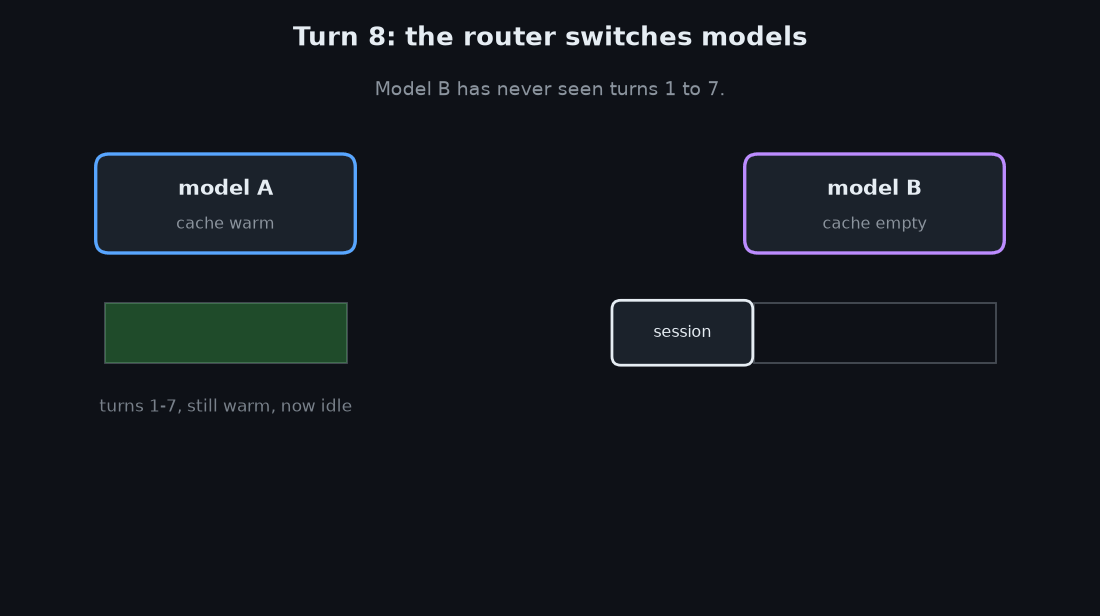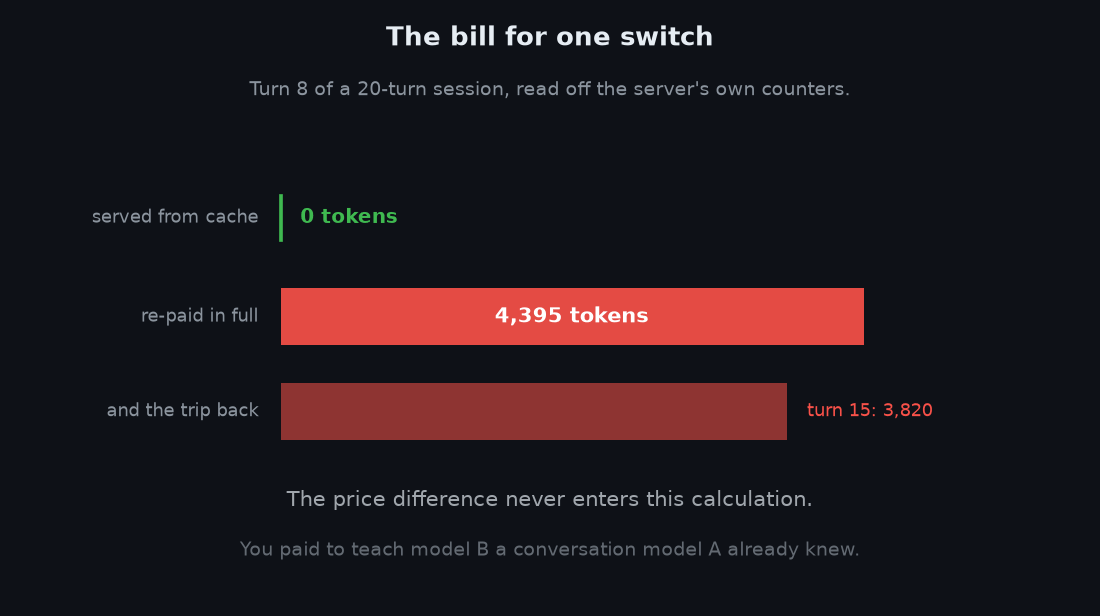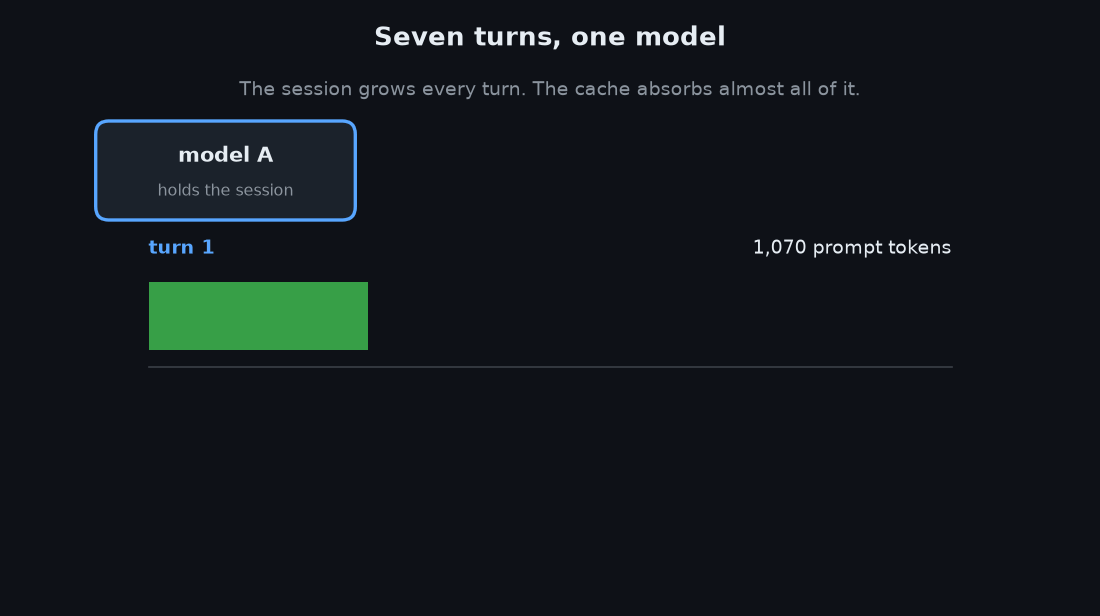
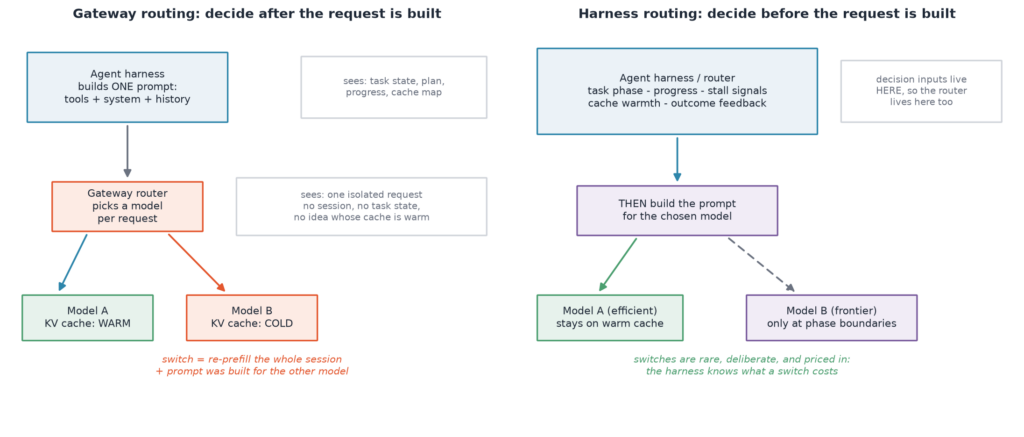
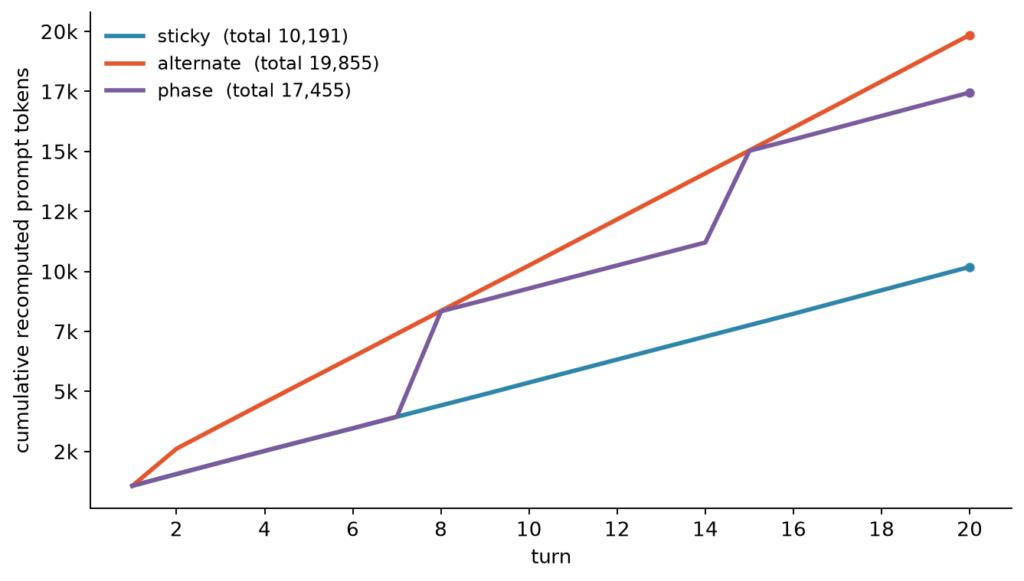
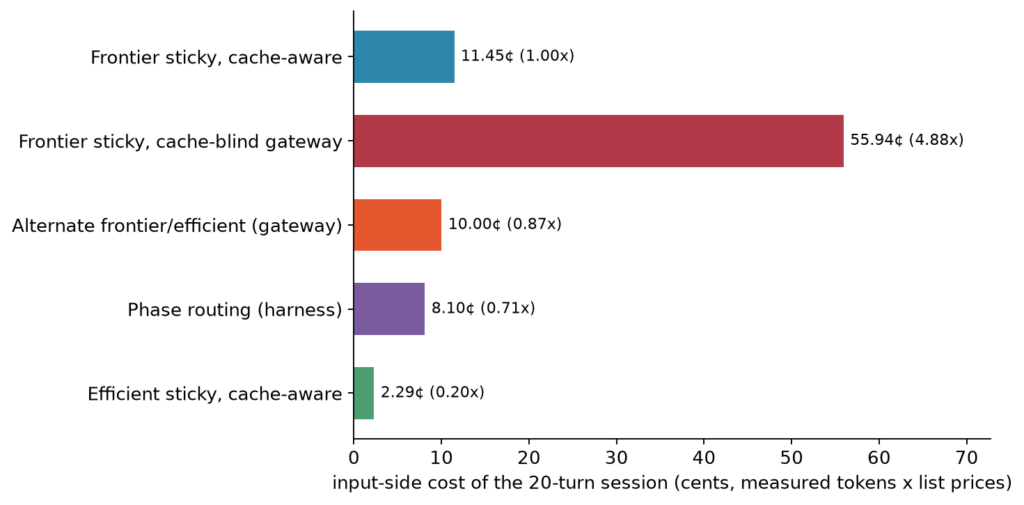
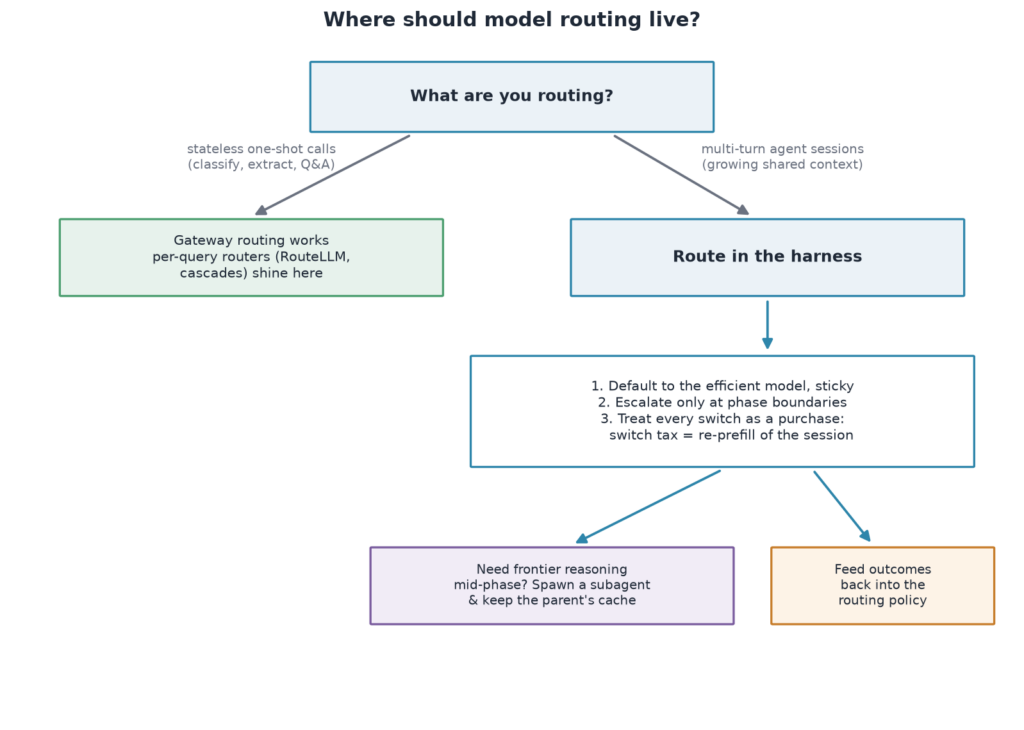
Ever since I started working with LLMs, the question of how to use them efficiently has always lingered in my mind. One of the solutios that seems most effective: when the quota for one model is about to run out, or when I want to save my budget on a task, I route part of it to another, cheaper LLM. The hope is that eventually, it would cost less than the original model. This is because capable models can differ in price by 5× to 50×, so why not drop a smart proxy at the gateway, send the easy requests to the cheap model, and the hard ones to the frontier model? At first, I thought this idea was brilliant. Then I tried to apply it, and one question immediately popped up: what does the switch itself cost? Not the per-token price difference — the switch .
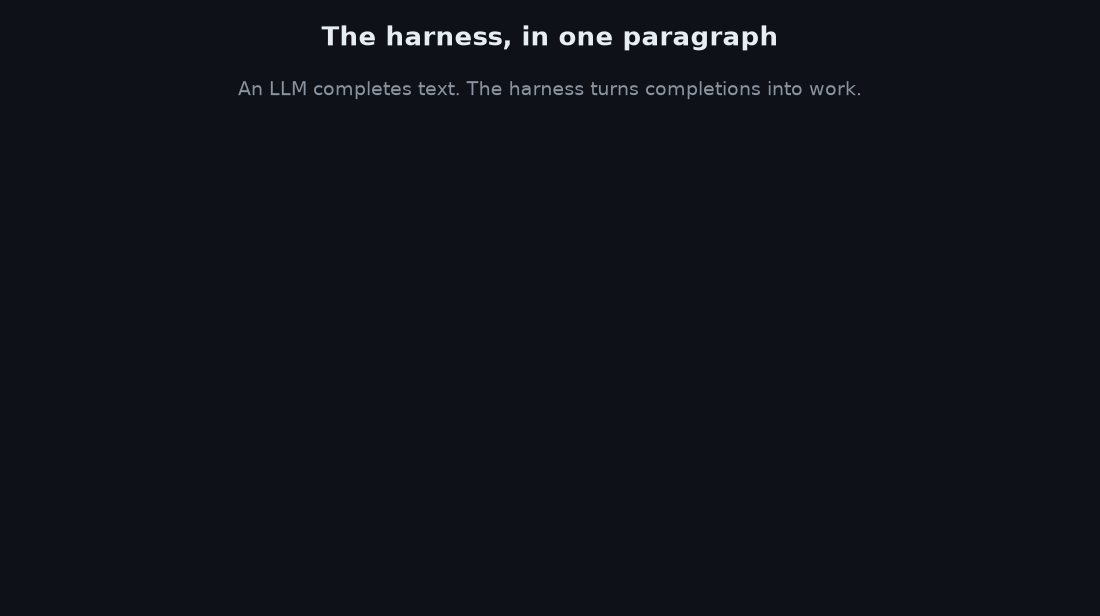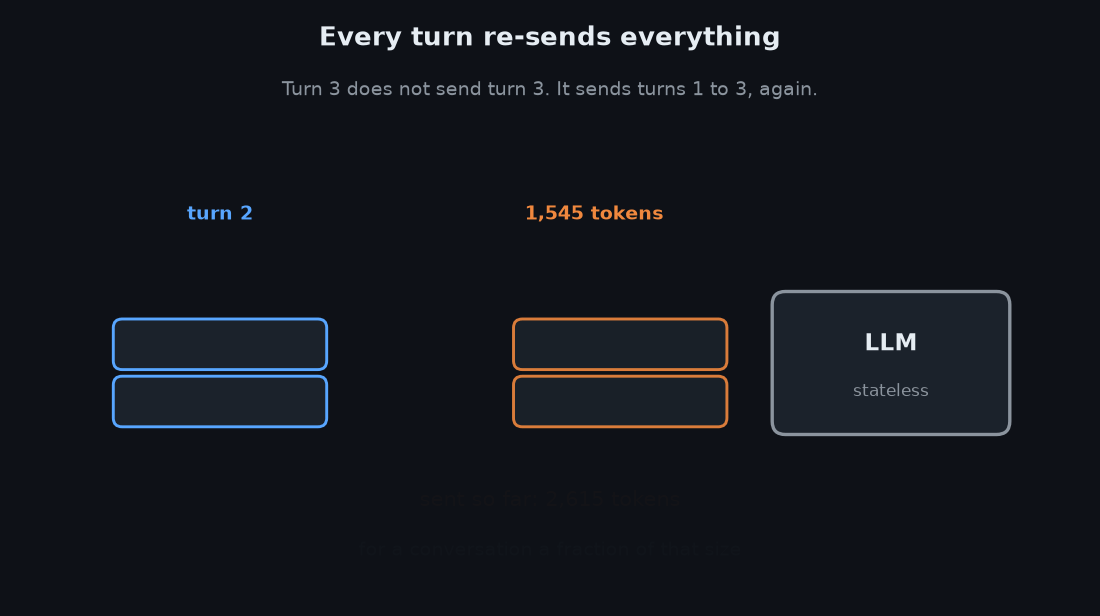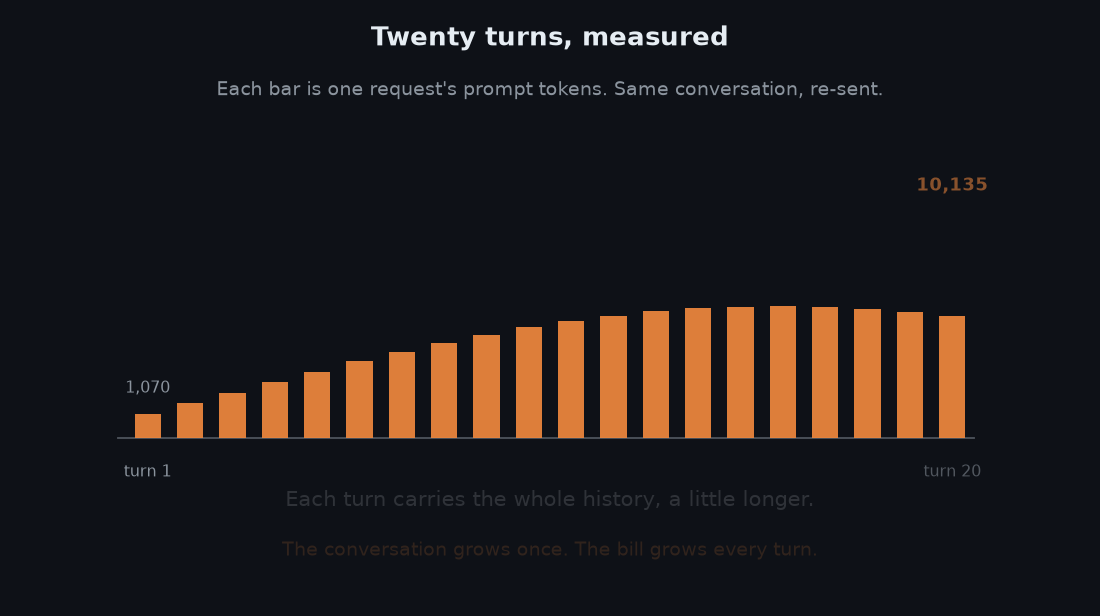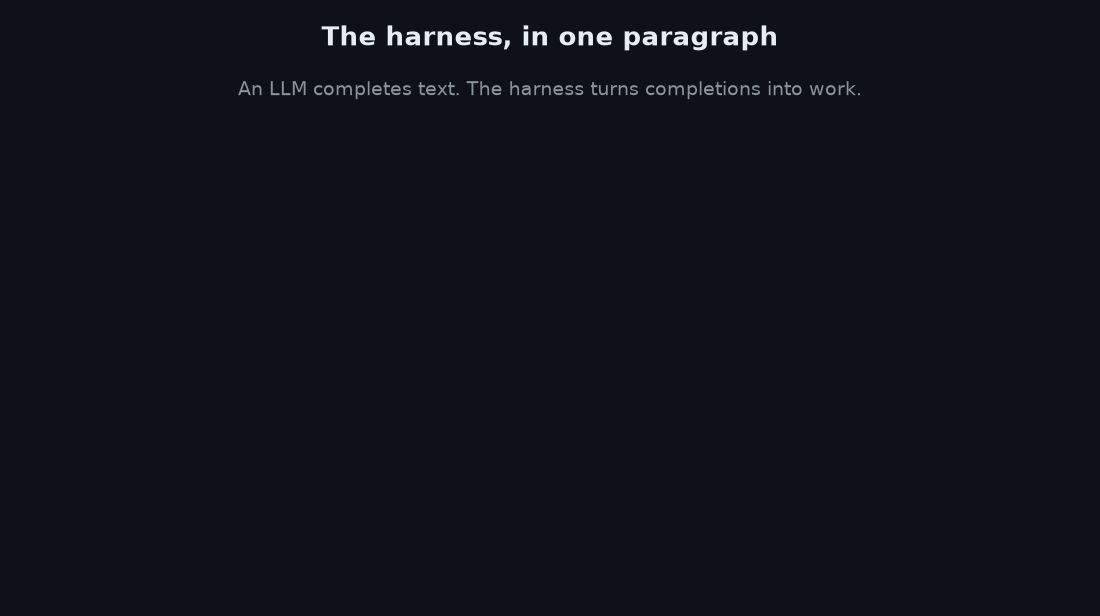
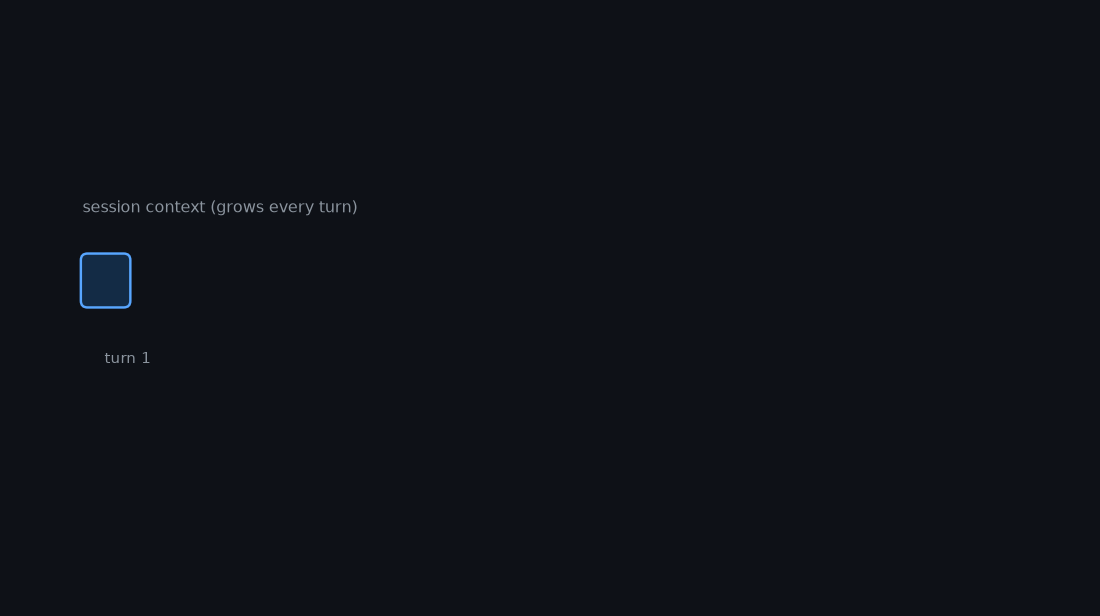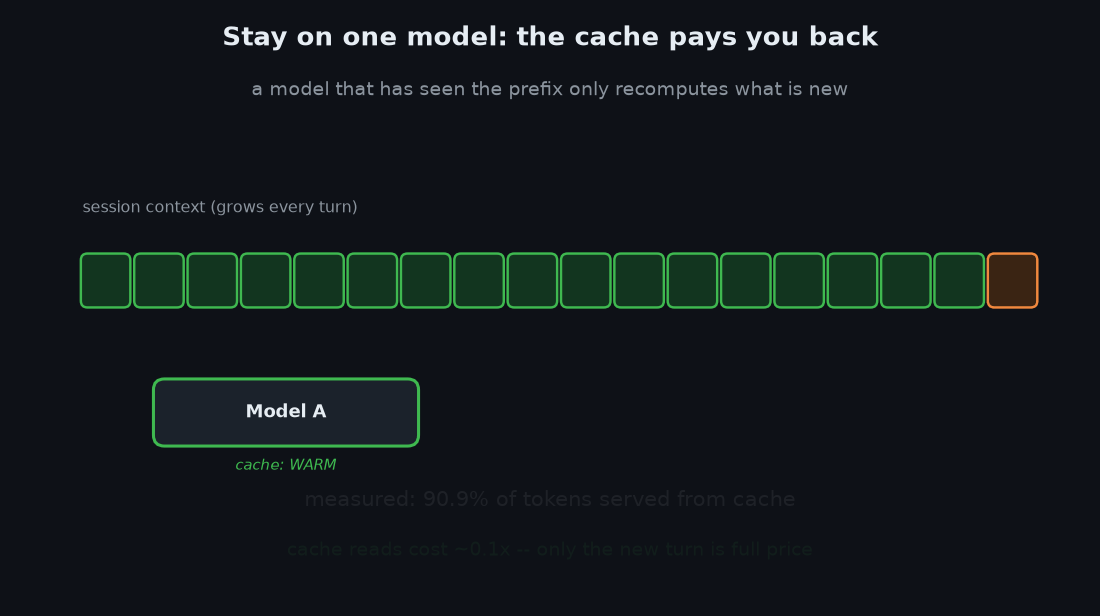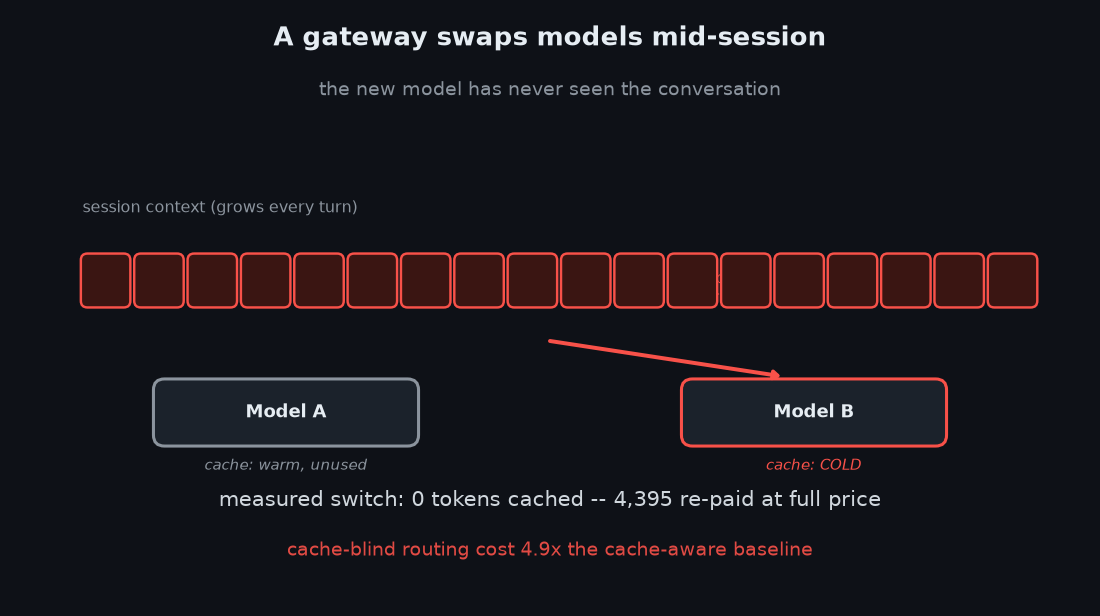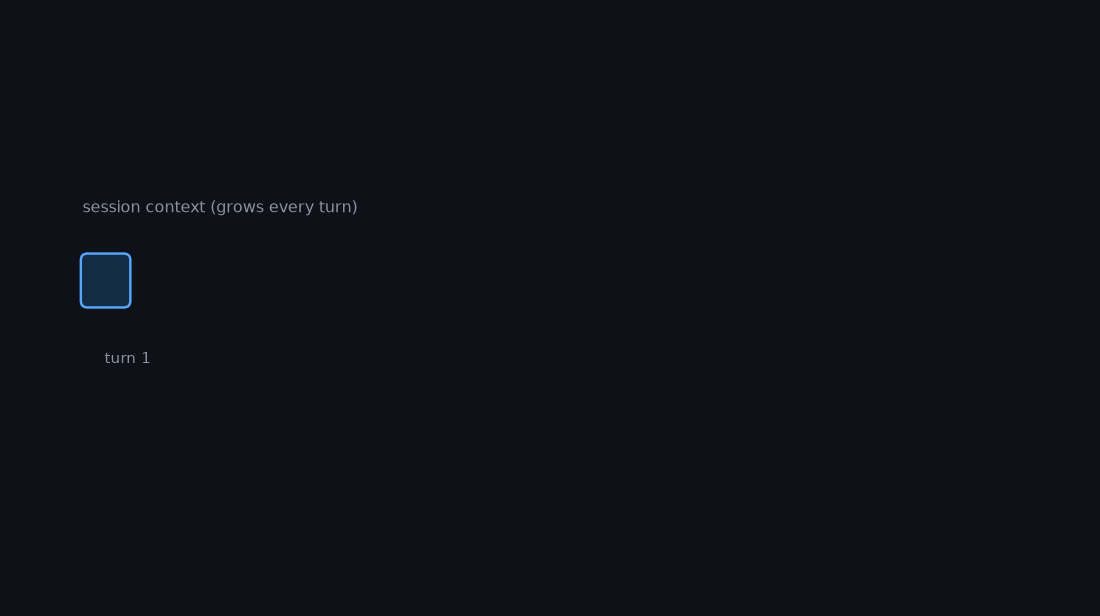
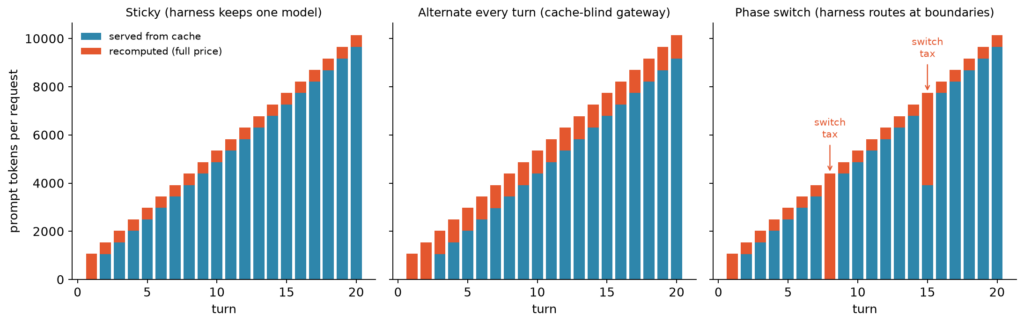
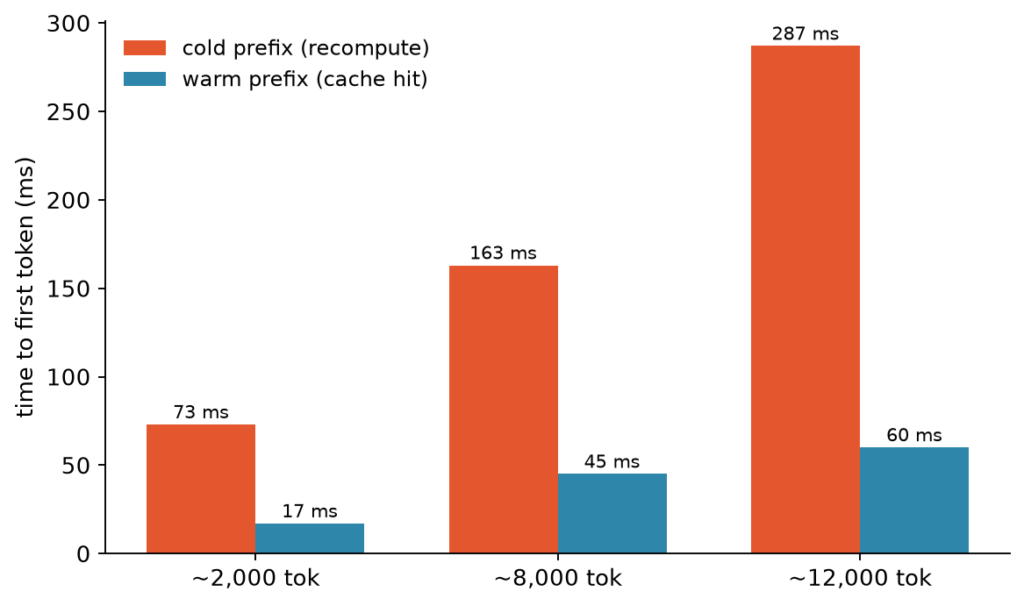
Suppose a router moves turn 8 of a conversation from model A to model B. Model B has never seen turns 1 through 7. Before it can generate a single new token, it has to process the entire conversation history from scratch, at full price.…