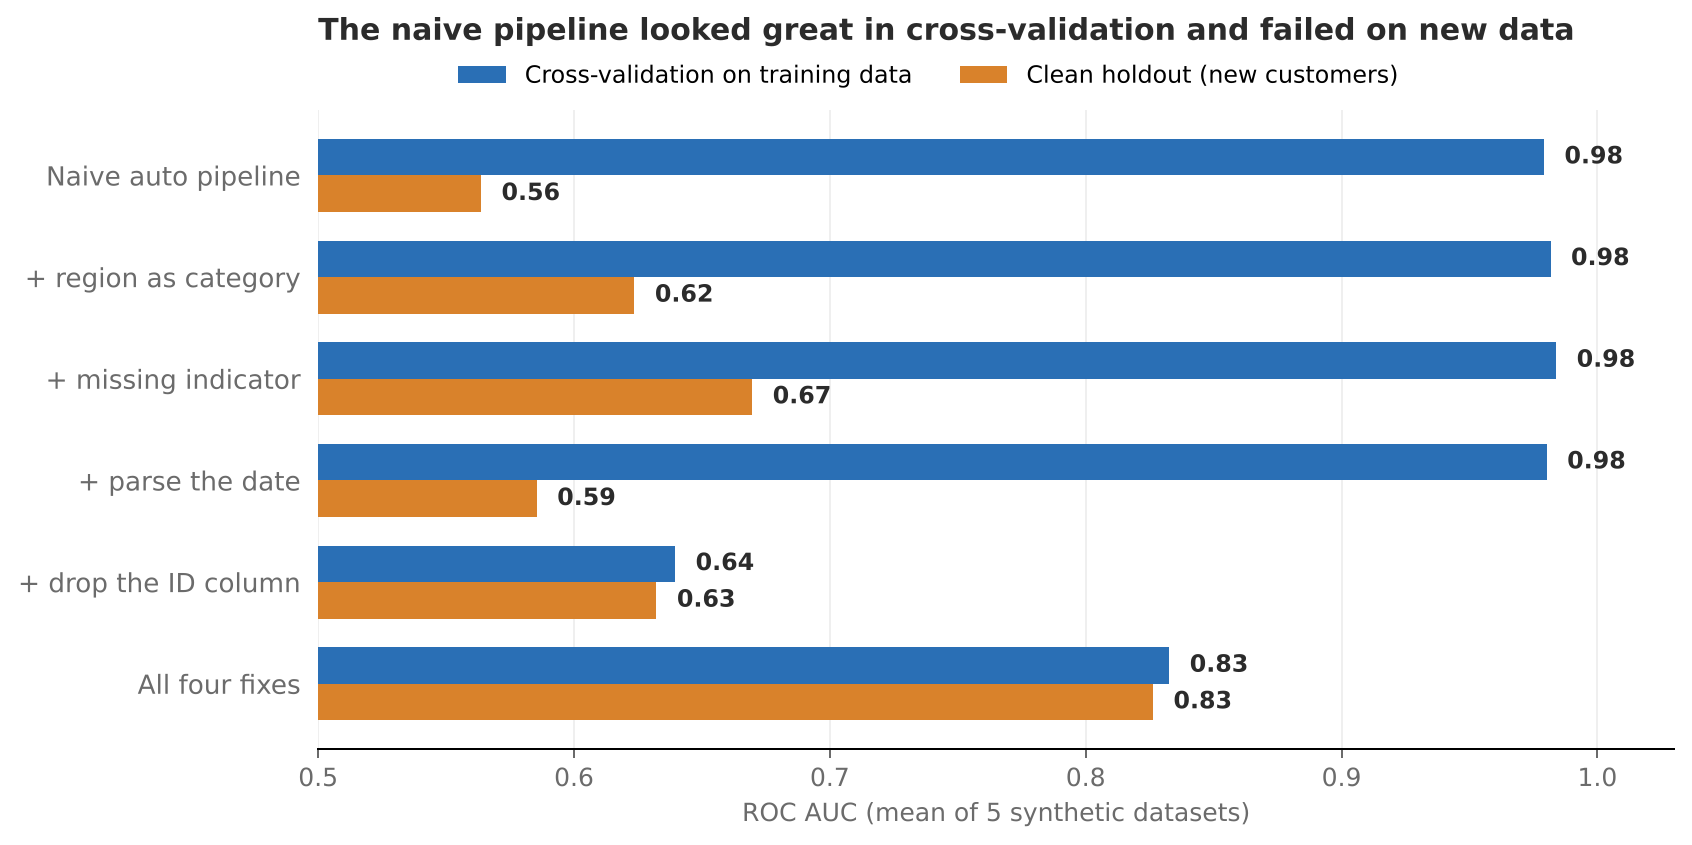
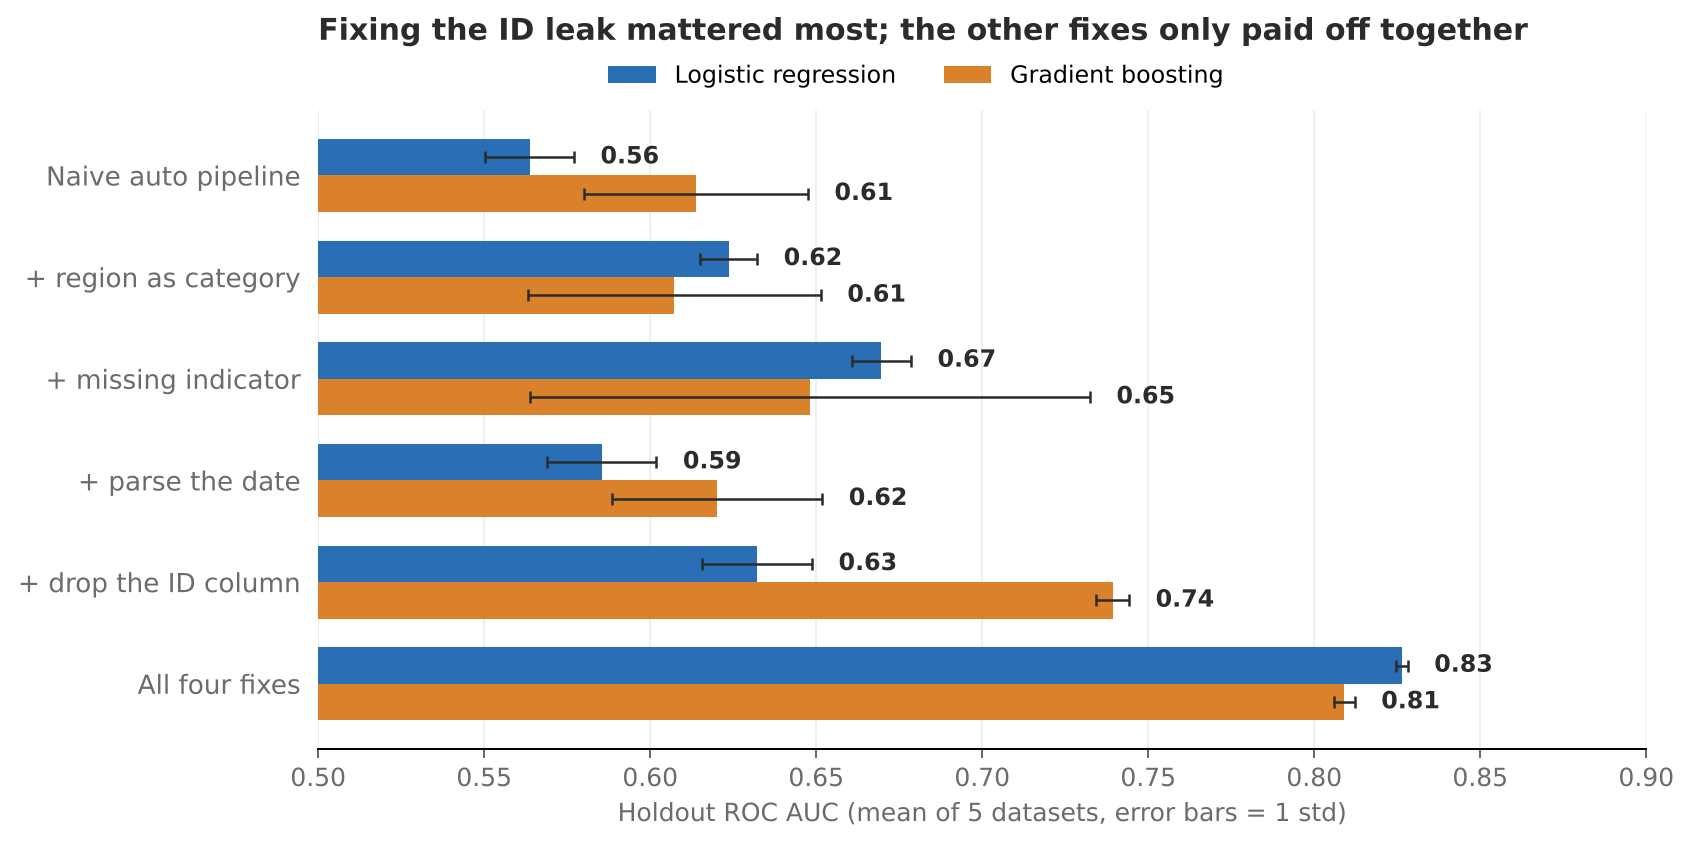
The Pipeline We All Write
If you have used scikit-learn for a while, you have probably written this pipeline. Numeric columns get imputed and scaled. Everything else gets imputed and one-hot encoded. Columns are routed by dtype, so it works on almost any table without you looking at it.
It is short, reusable, and easy to trust. That is the problem. I wanted to find out what it silently gets wrong, so I tried to break it on purpose.
Four Traps I Planted
Data. Everything here is synthetic. I generated it myself with a Python script: a customer-churn table with 8,000 rows per dataset (6,000 for training, 2,000 as a clean holdout of "new customers"). I generated 5 independent datasets (seeds 0 to 4) and report the mean across them.
I planted four traps that a dtype-based pipeline cannot see:
Region as a number. region_code holds the integers 1 to 12, but each region affects churn differently and not in order. The pipeline scales it like a measurement.
Informative missing values.…