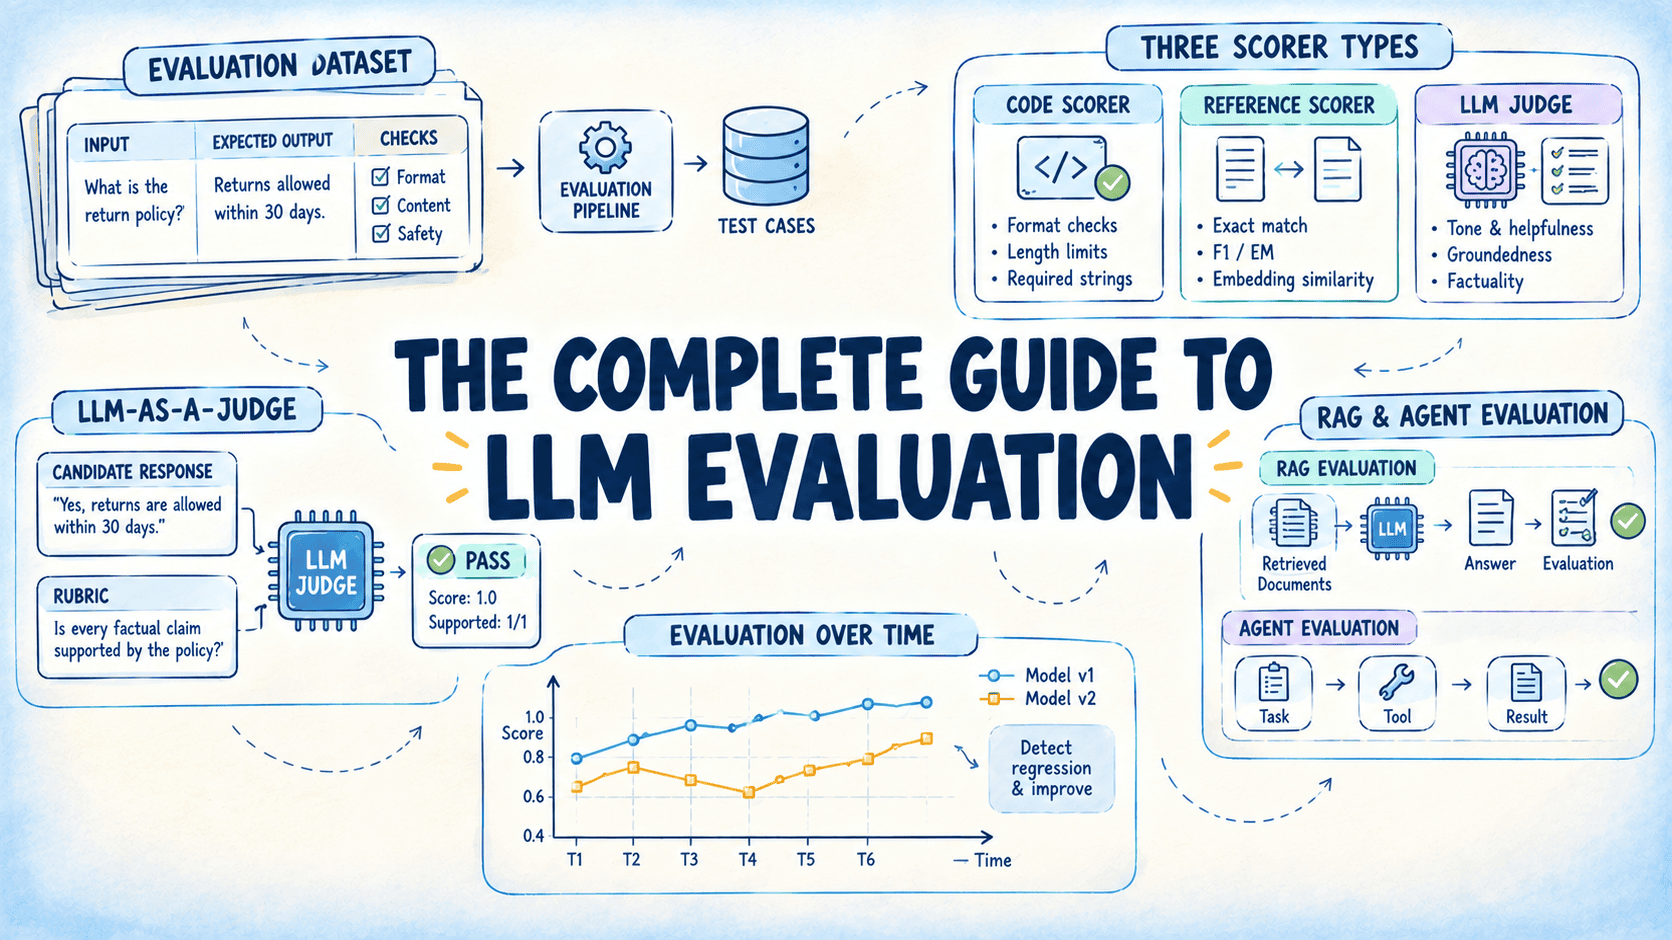
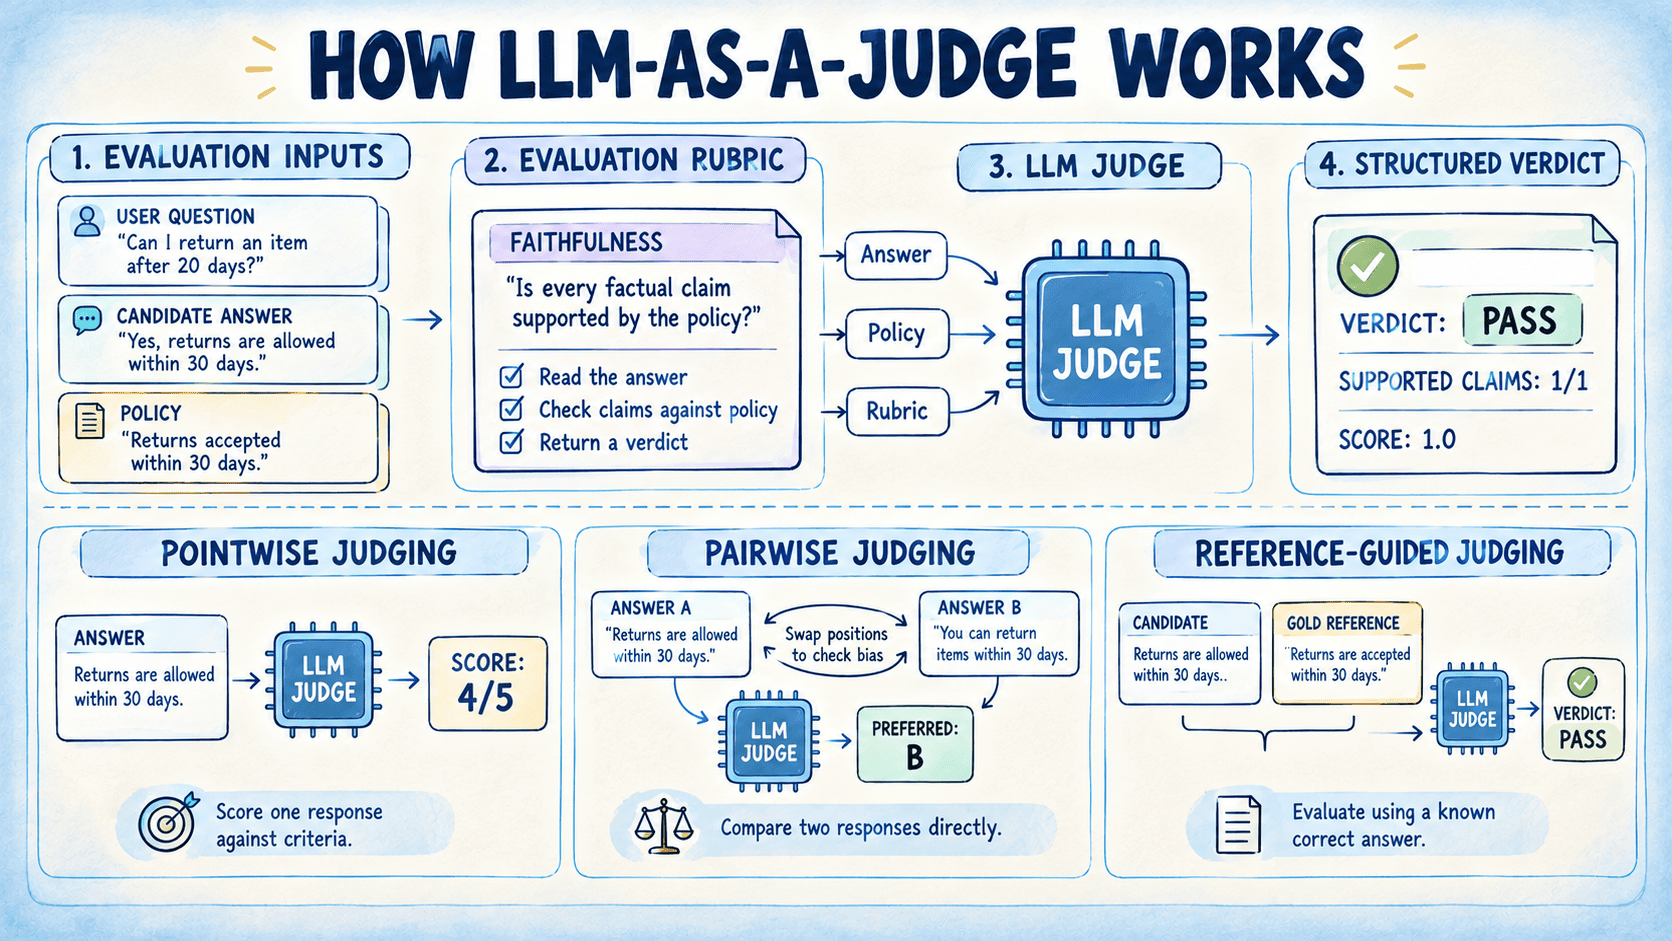
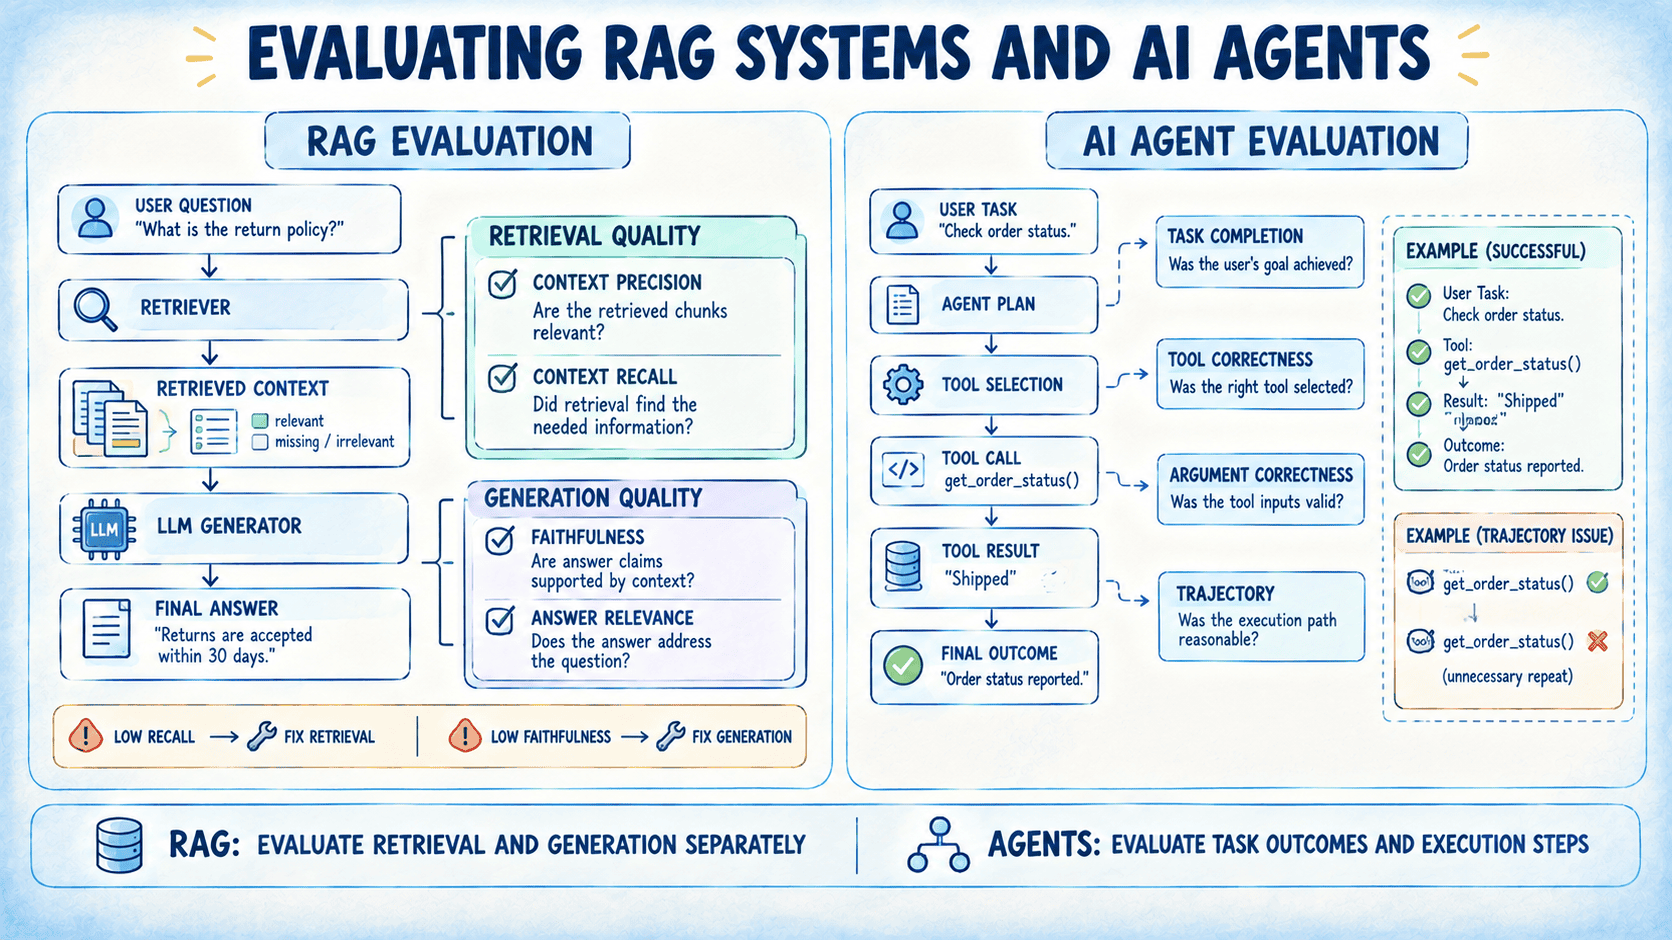
In this article, you will learn how to evaluate LLM applications systematically, from choosing scorers and designing reliable LLM judges to evaluating RAG systems and agents across the release cycle.
Topics we will cover include:
How code, reference-based, and LLM-judge scorers differ, and how to write, score, and calibrate an LLM judge with rubrics, QAG, G-Eval, pairwise comparison, and Cohen’s kappa.
How to score RAG systems and agents component by component, so you can tell which part failed.
How to run offline evals before release and online evals on live traffic.
Introduction
You test most LLM apps by reading a few outputs and deciding they look fine. A prompt edit, a model swap, or a retrieval change then breaks something you never checked. And by then you can’t quite tell which change caused it.
LLM evaluation catches these breaks before users do. You build test cases, score each output against written criteria, and compare scores before and after every change.…