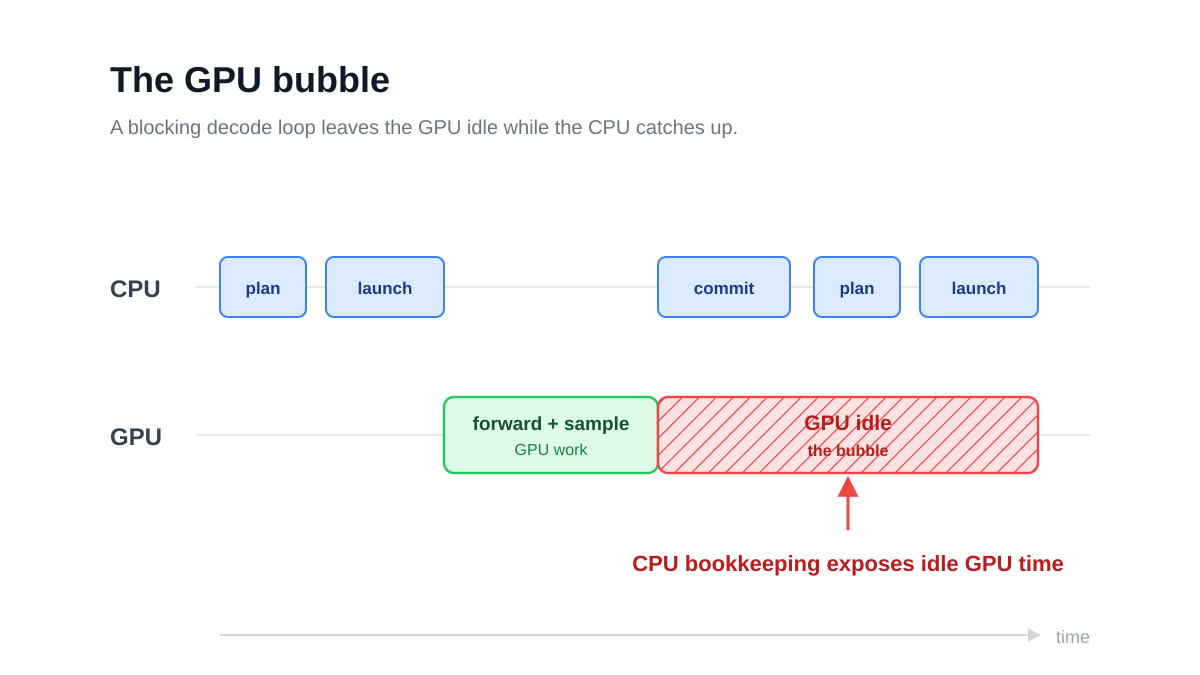
Moondream Engineering Photon, Moondream's inference engine, achieves near-realtime VLM inference (~33ms on NVIDIA B200). This is a peek into how it delivers up to 35% higher decode throughput by optimizing how the GPU works. June 4, 2026 How do you make an AI model run as fast as possible? This is a question we obsess over at Moondream HQ. The GPU handles all the math involved in model inference, so at first glance it doesn't seem like there's much to it: just tell it what to do and wait for the answer. But if you start looking at how it actually works under the hood, you find that the GPU often sits idle, not for lack of work, but because the CPU hasn't told it what to do next yet. This phenomenon is called a GPU bubble . When a typical AI model generates text, it produces one token at a time (a token is a chunk of text, roughly a few characters). Each token depends on the tokens before it, a property called autoregressive , so generation is sequential.…