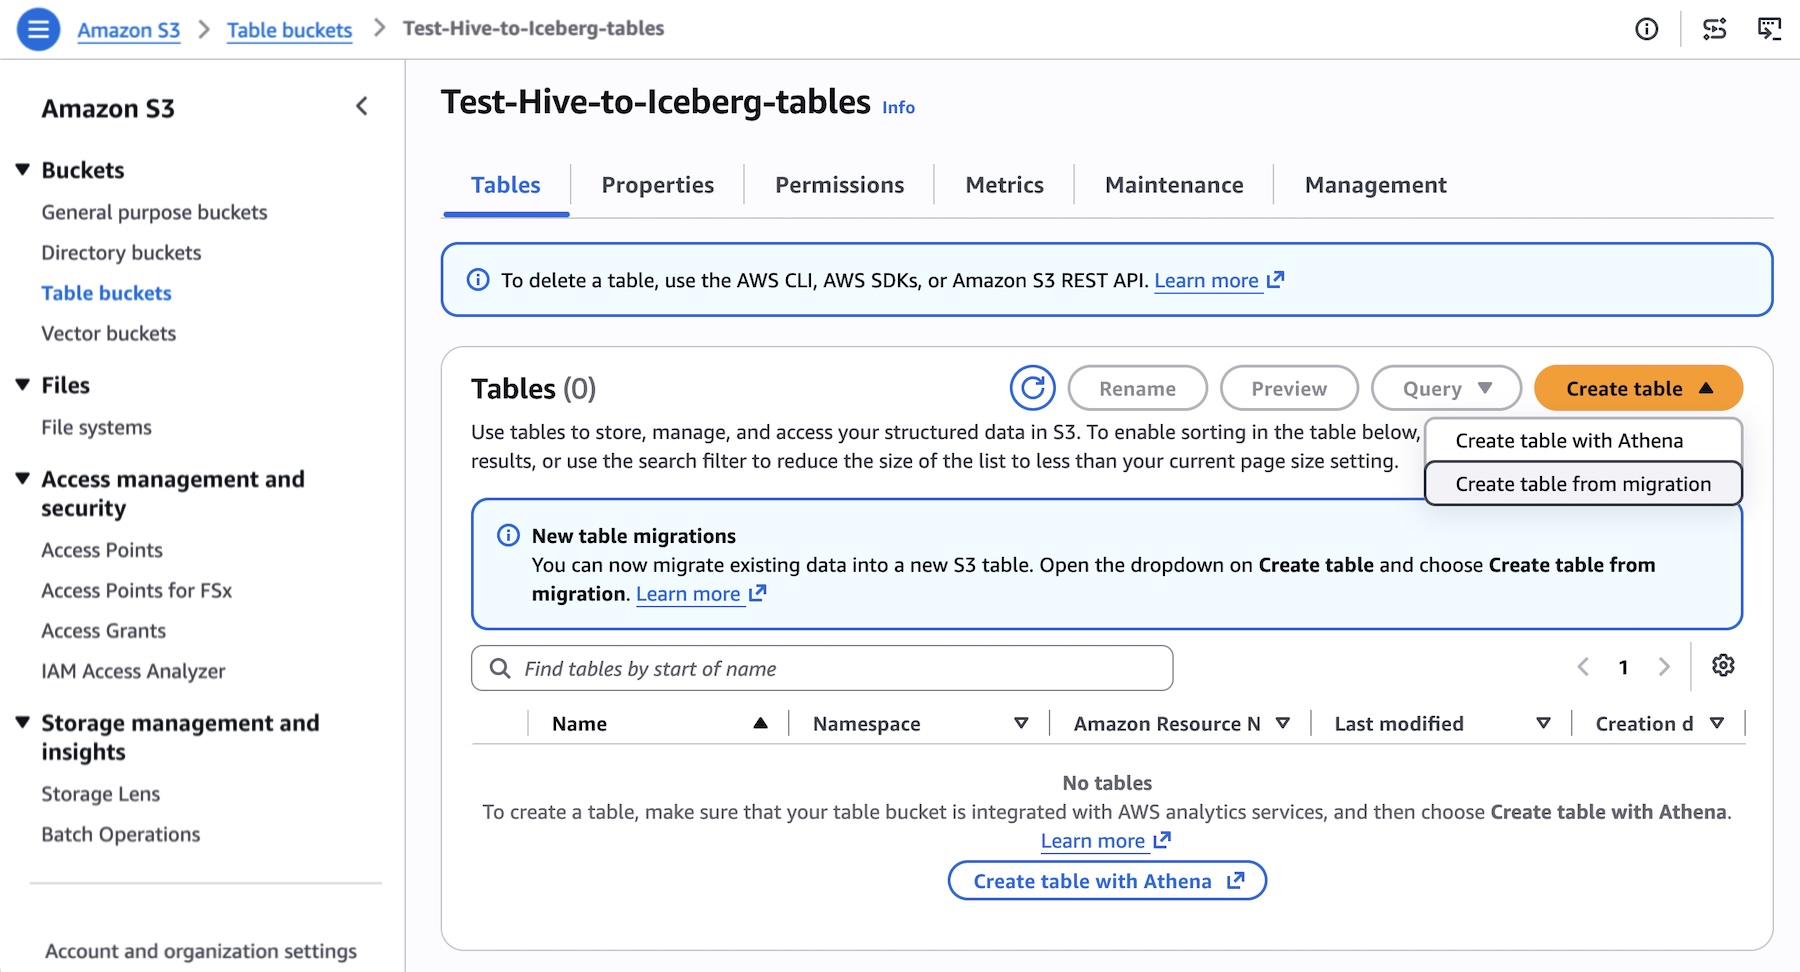
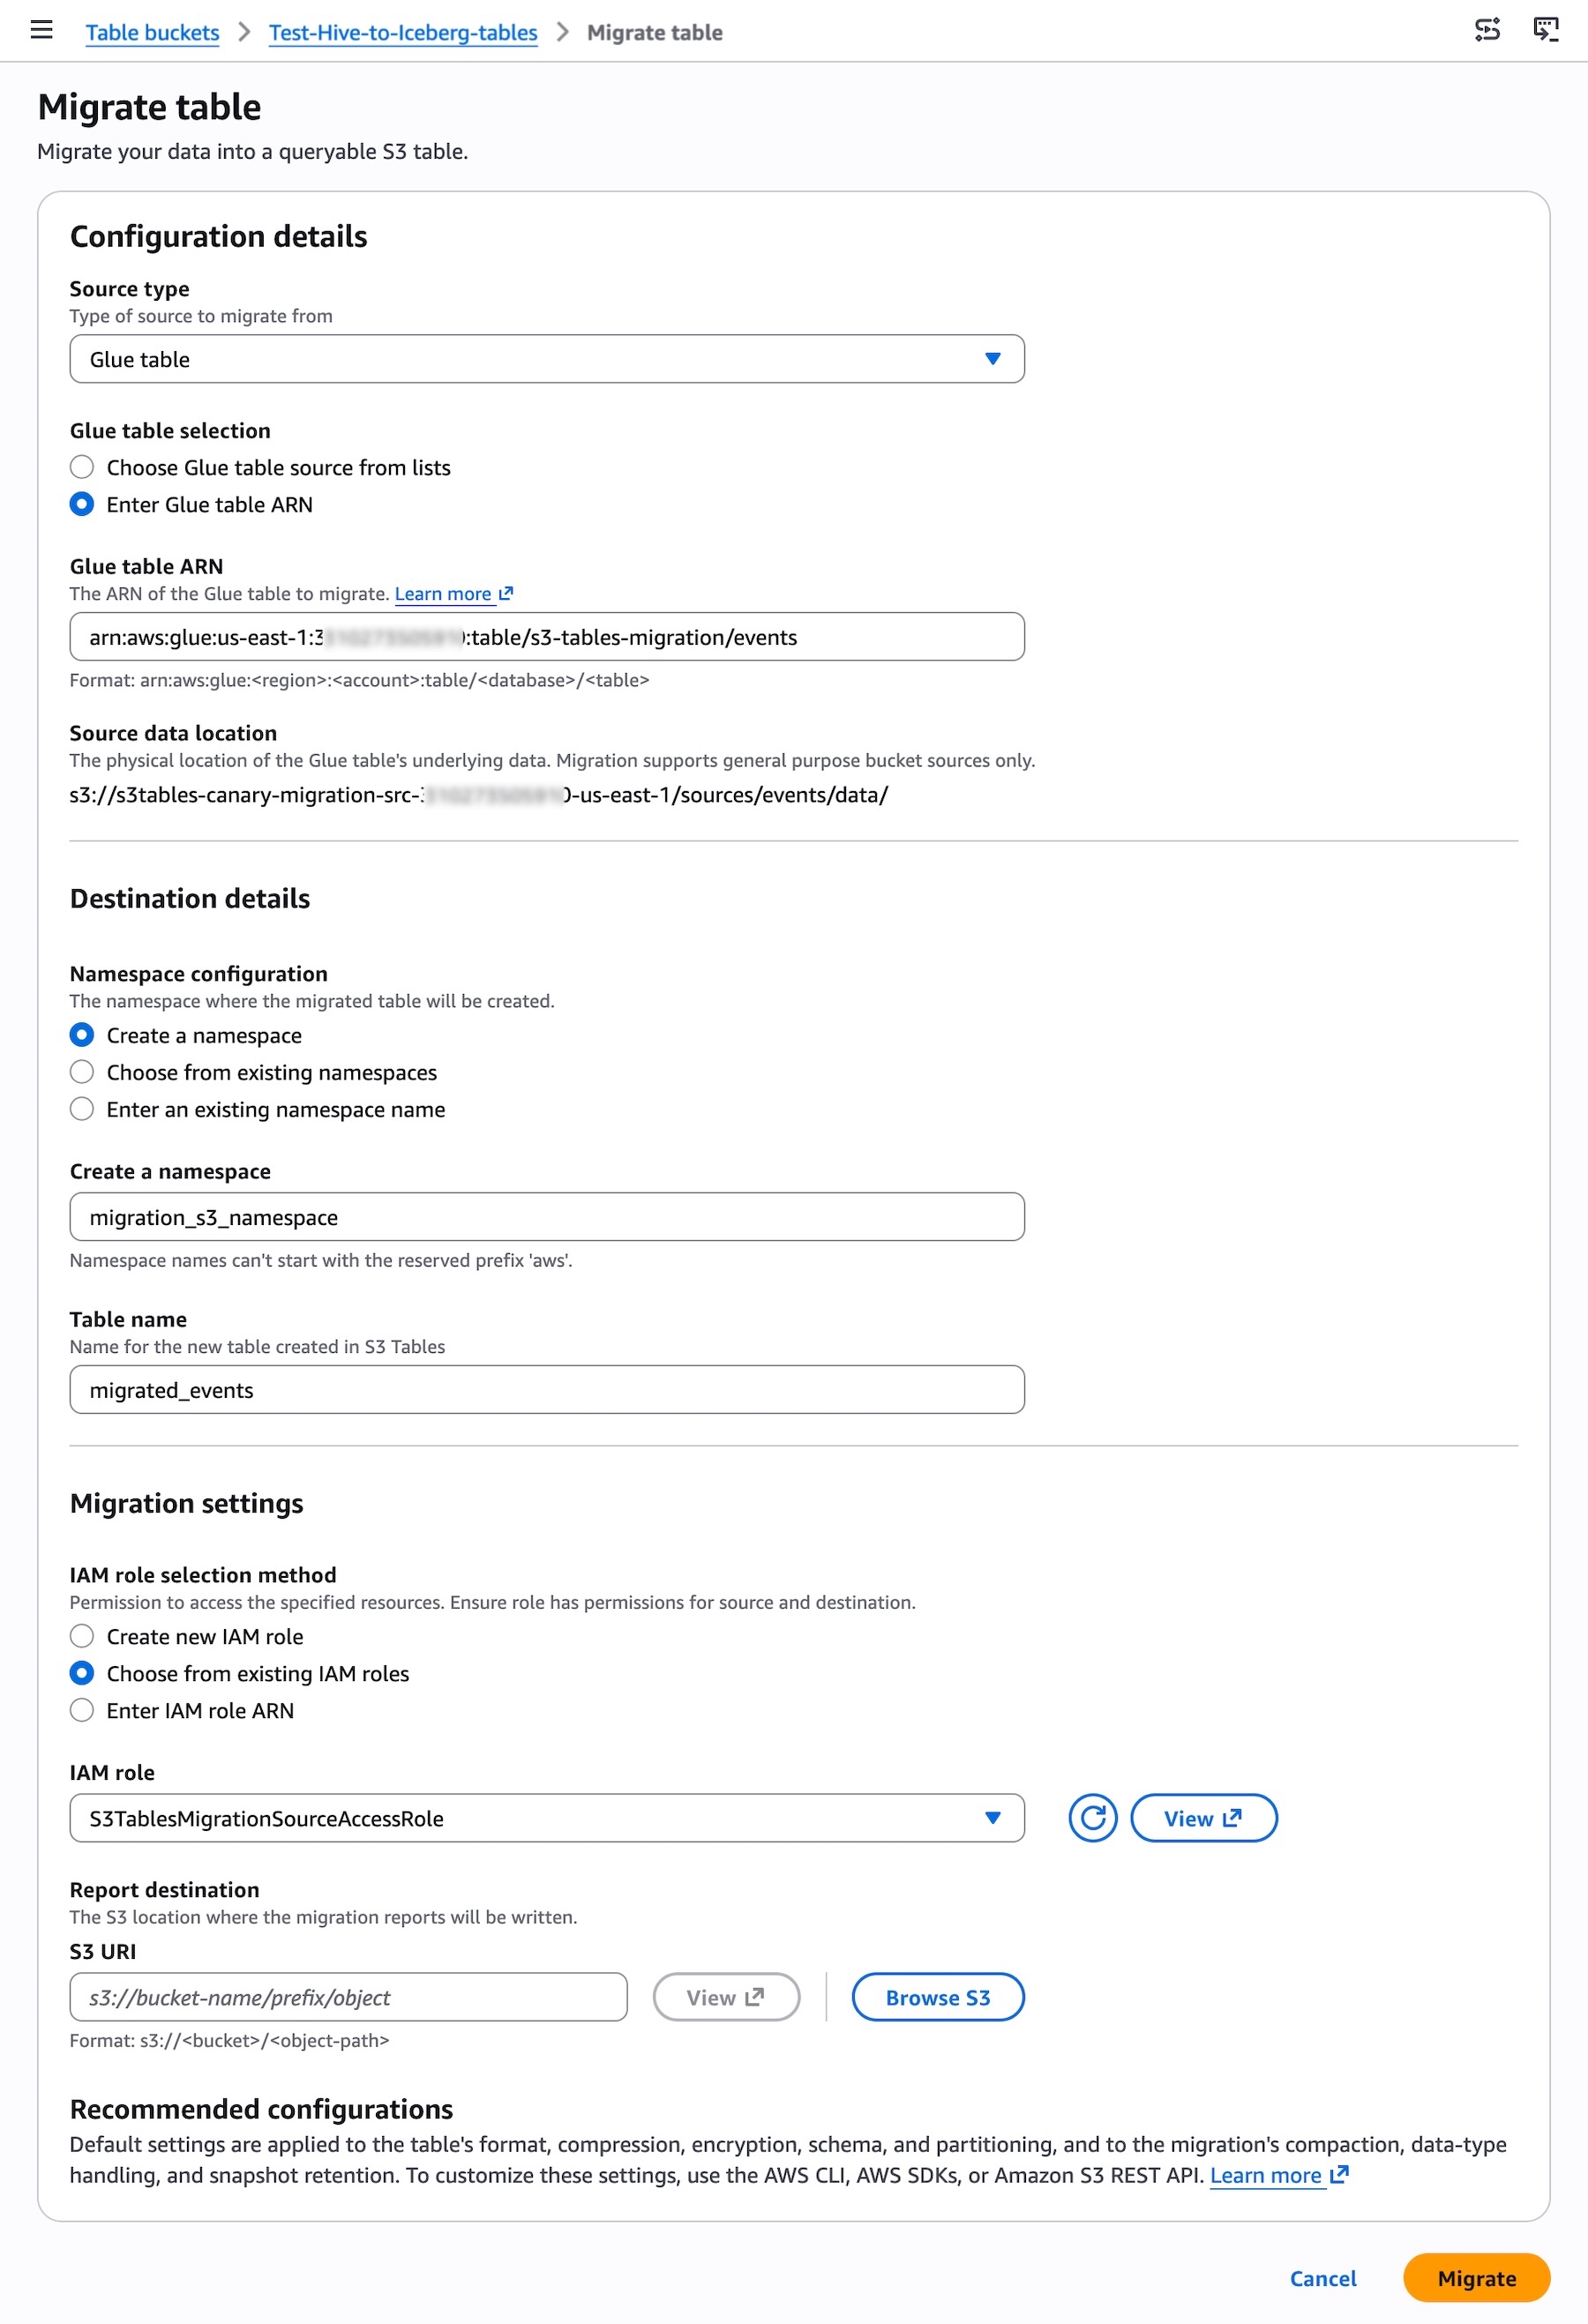
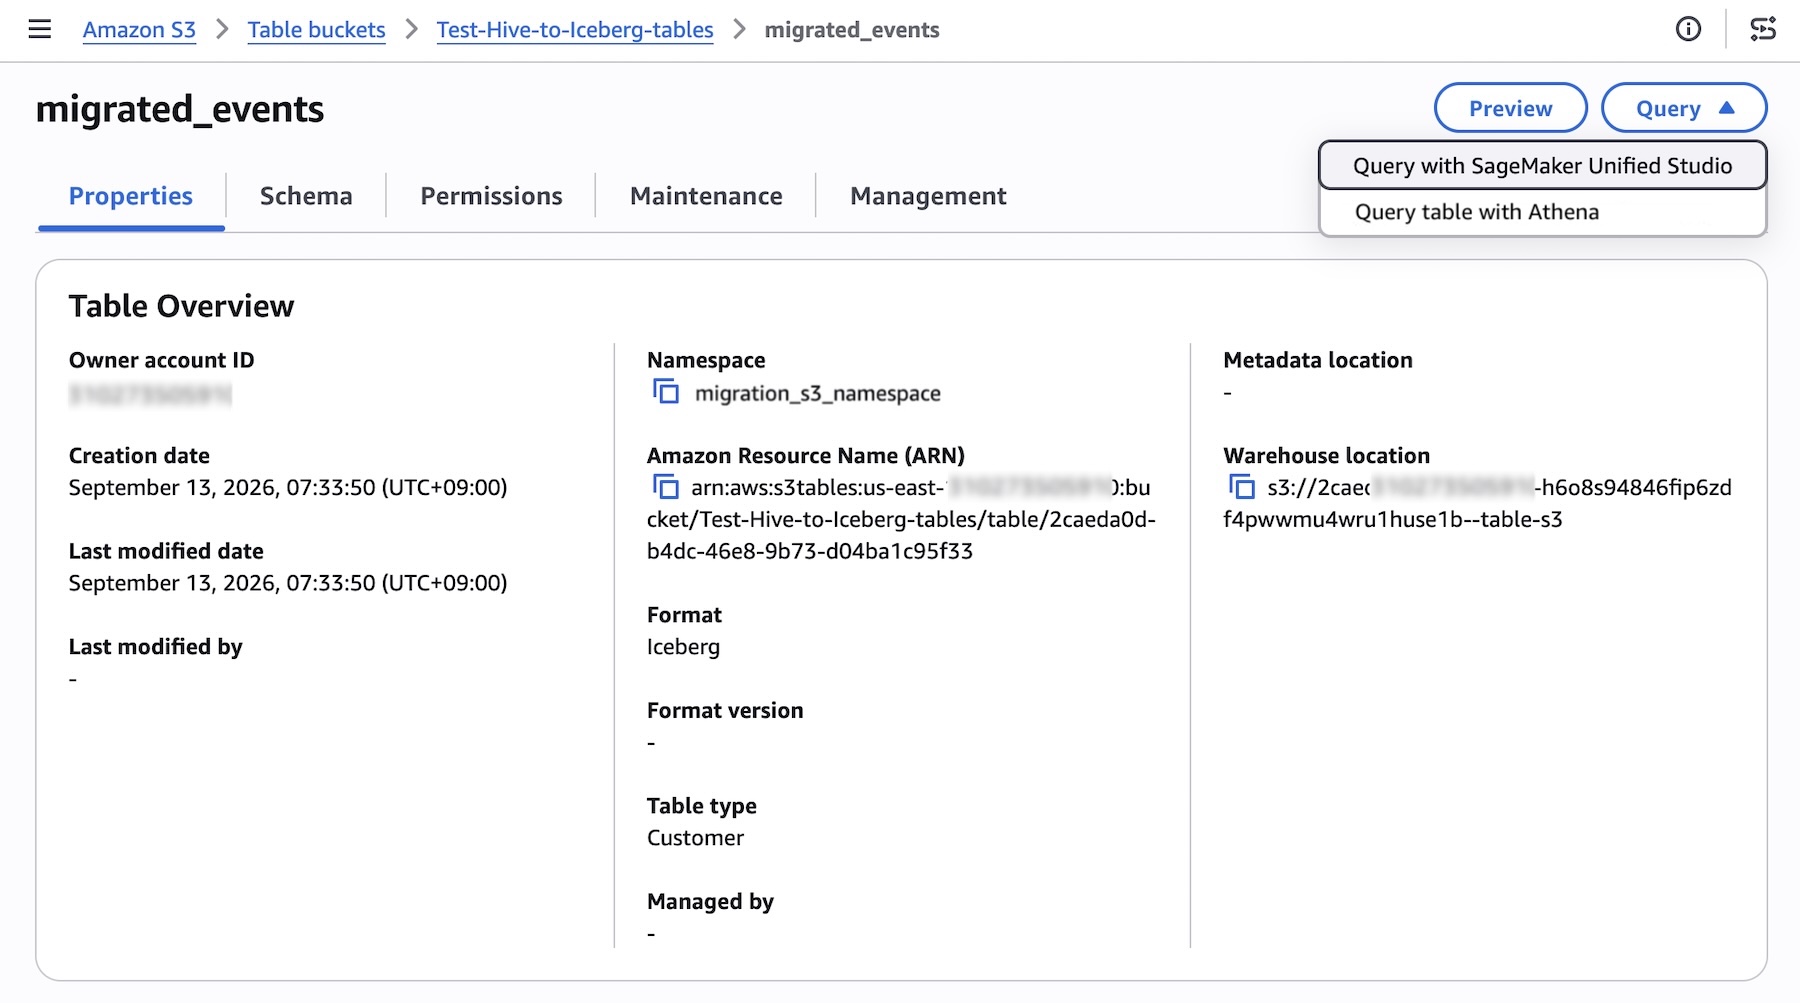
Today, we’re announcing a simple, cost-effective path for data lake modernization. Amazon S3 Tables now support managed migration of your Apache Hive tables to Apache Iceberg . Migration works with Parquet tables in Amazon S3 that are registered in the AWS Glue Data Catalog and allows you to upgrade your data lake with no pipelines to build or compute to provision, while production workloads keep running.
Apache Iceberg has become the open standard for large analytics datasets. It lets you manage petabyte-scale tables with features like schema evolution, hidden partitioning, and time travel queries, while keeping your data open and queryable with any Iceberg-compatible engine.…