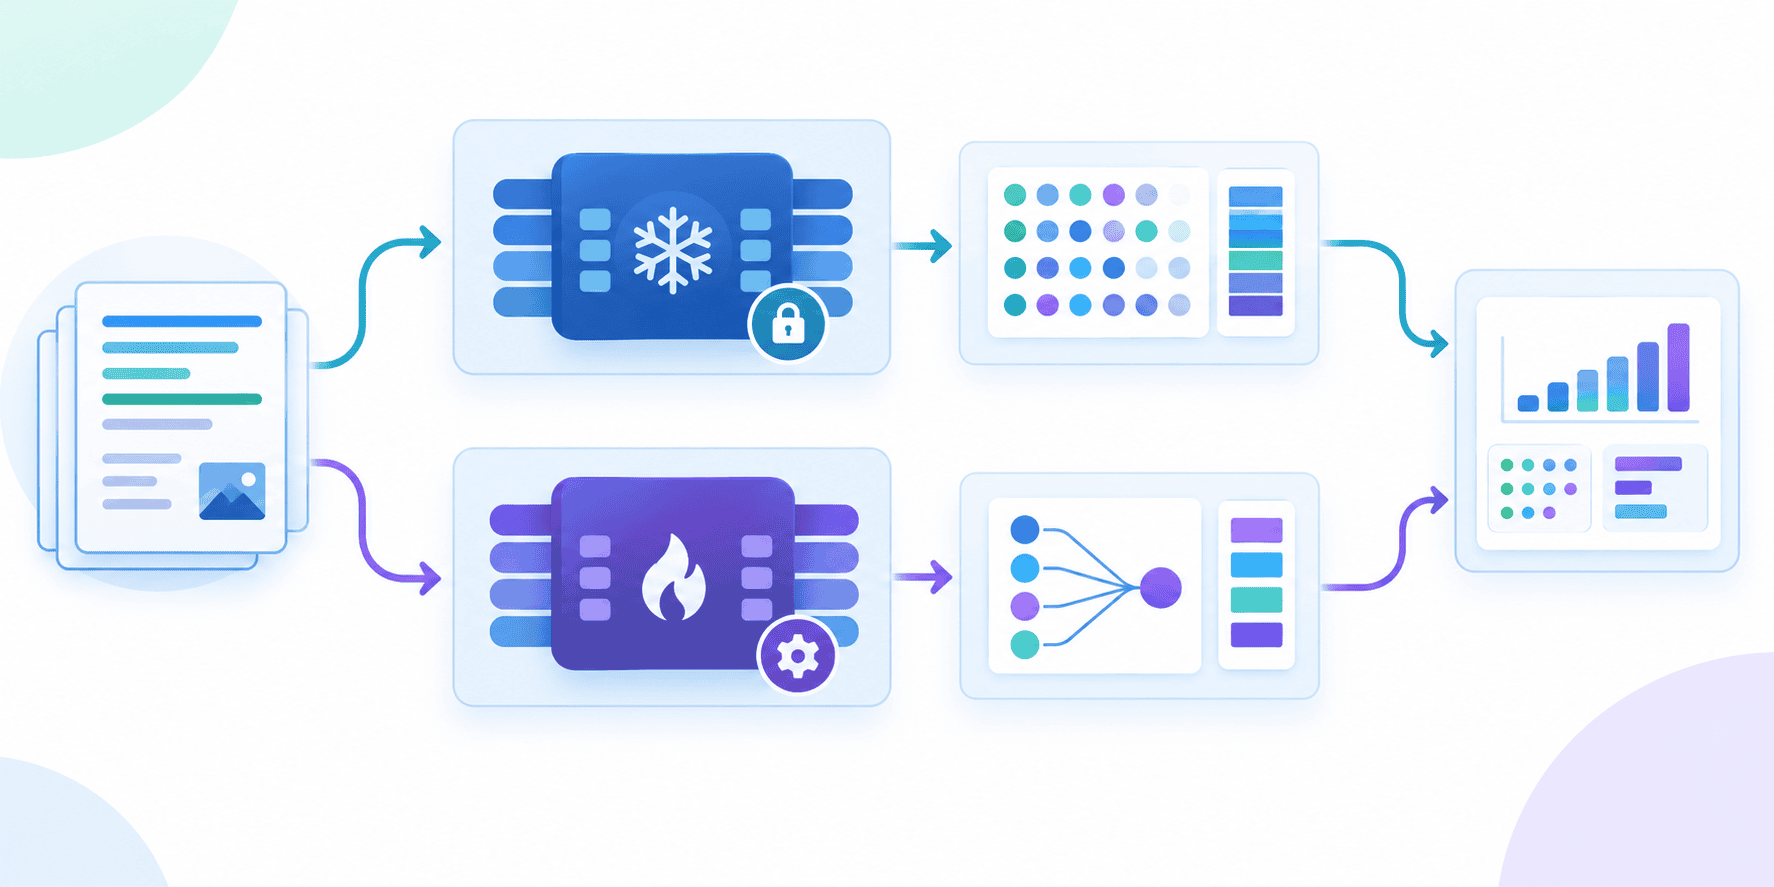
In this article, you will learn how to compare two strategies for adapting a large language model to a specific domain: fine-tuning with LoRA versus training a scikit-learn classifier on frozen embeddings.
Topics we will cover include:
How frozen embeddings work as a lightweight alternative to full model fine-tuning, and when this approach is appropriate.
How to implement QLoRA fine-tuning using the PEFT library with a Hugging Face model and a classification head.
How the two strategies compare in terms of training time and classification accuracy on a real dataset.
Introduction
When adapting an LLM (a large language model) to a specific domain, the classical approach picked by the machine learning community boils down to fine-tuning the model on a domain-specific dataset. But a question arises: is this always necessary?…