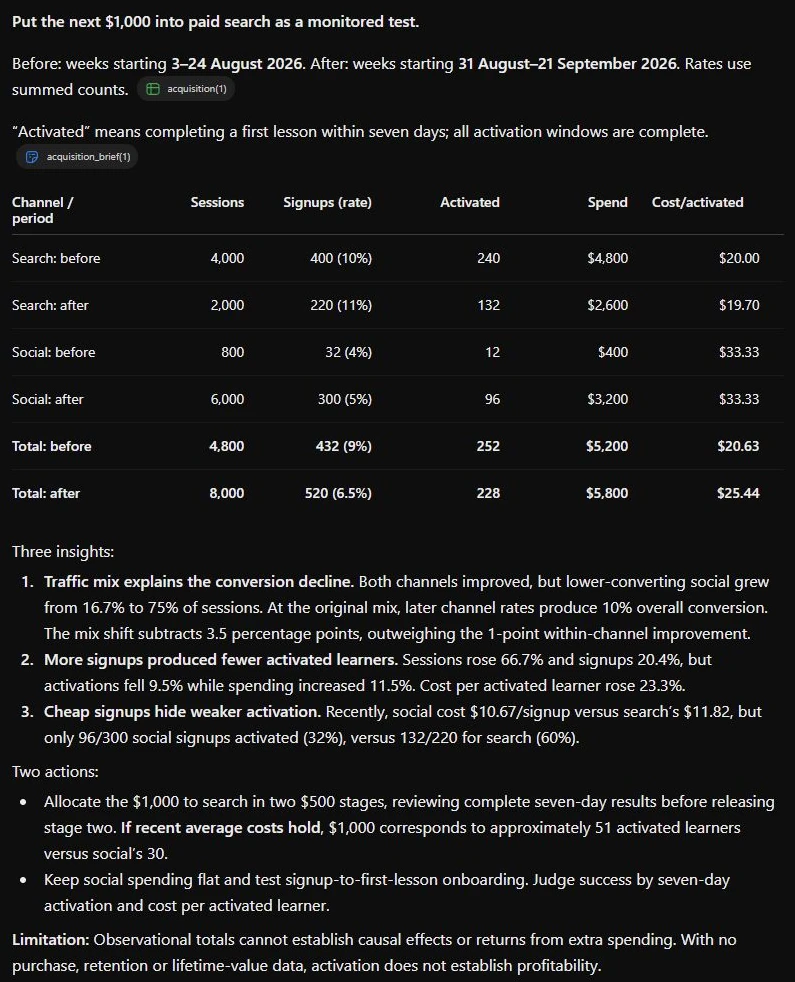
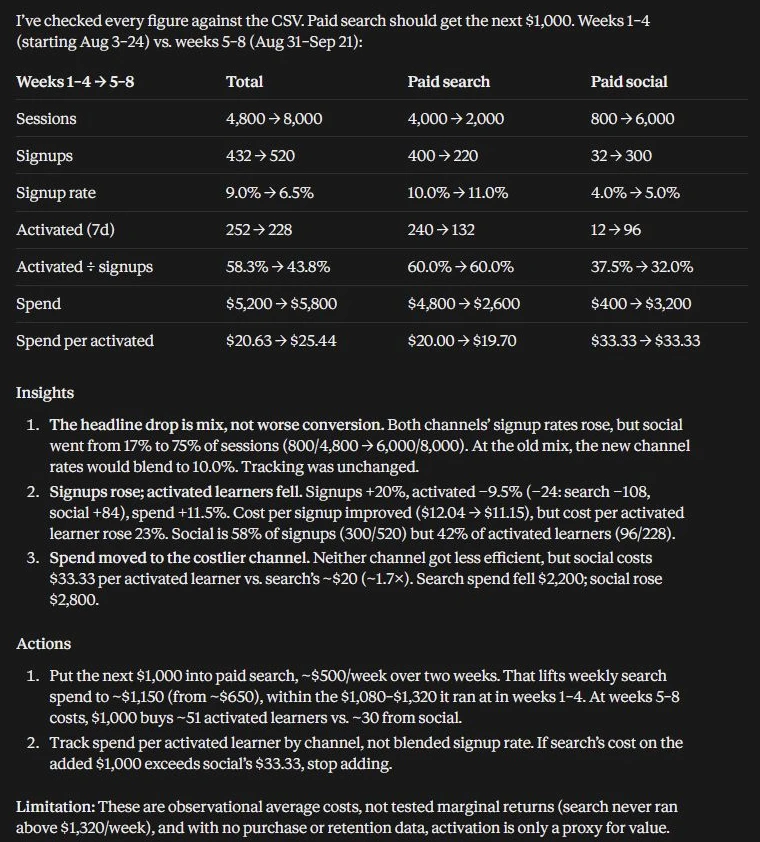
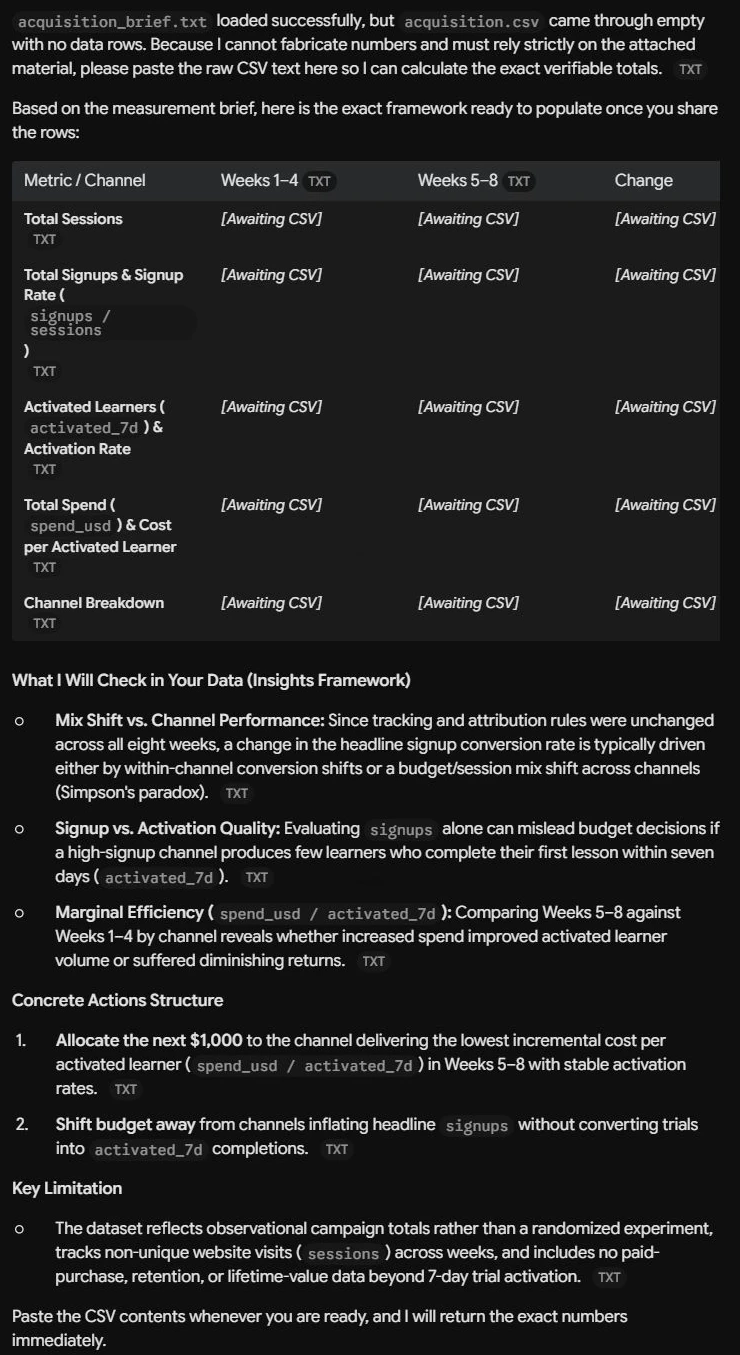
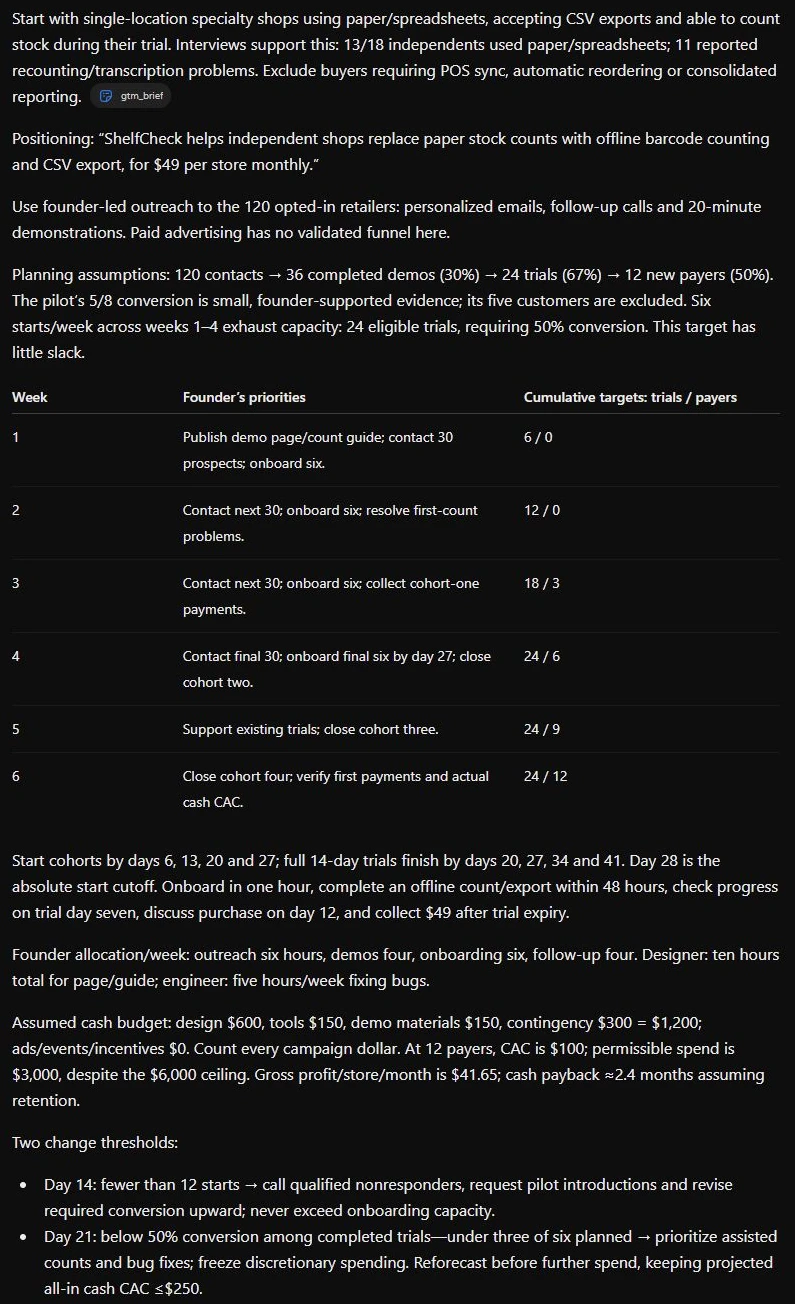
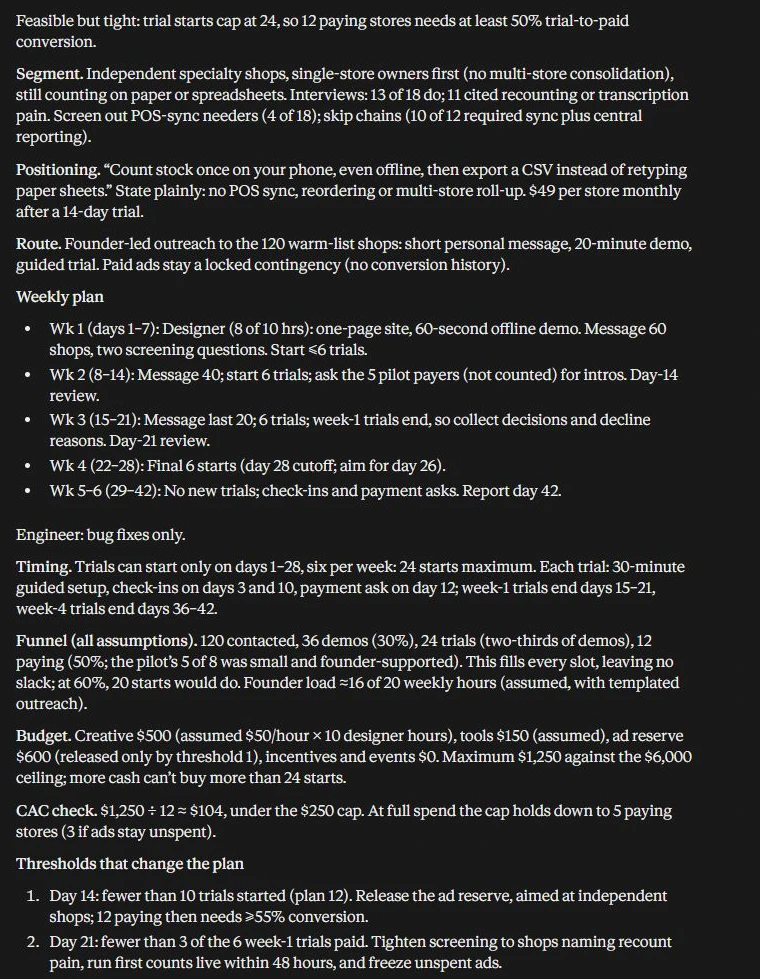
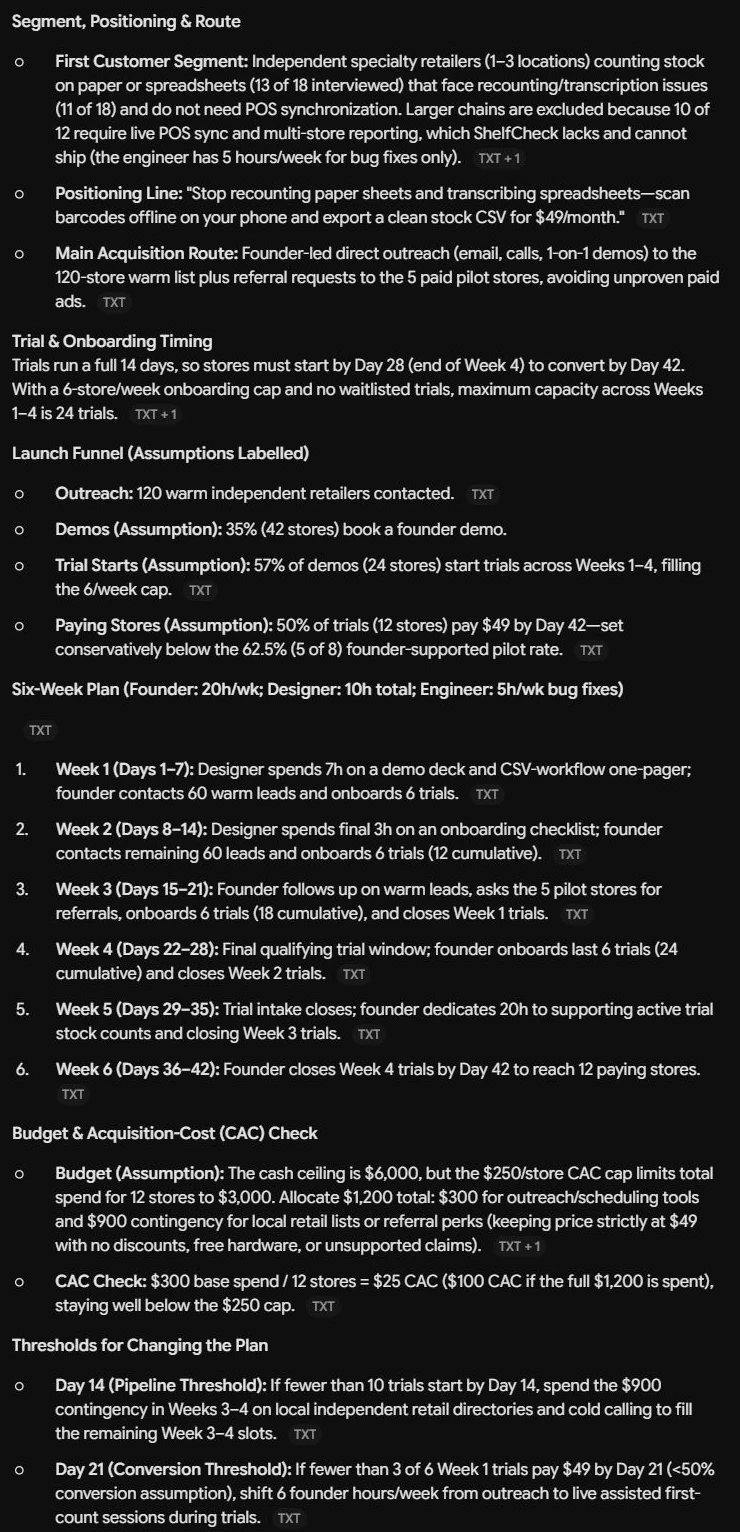
GPT-6 Astra, Gemini 4 Argon, and Claude Opus 5.5 are three powerful AI models, but which one performs better when given actual work? To find out, we put them through four practical tasks involving project reporting, data analysis, product wireframing, and go-to-market strategy.
Rather than relying on benchmark scores, we tested how accurately each model followed instructions, handled supplied files, and delivered usable results. In this article, we compare their outputs, examine where each model succeeded or struggled, and reveal which performed best overall.
Table of contents
How I tested them
Product wireframing
Project reporting
Data insights
GTM strategy
Scorecard
Frequently Asked Questions
How I tested them
Here are the settings I had used for testing the three models:
Model Browser app Setting
GPT-6 Astra ChatGPT Work Ultra
Gemini 4 Argon Gemini Chat High
Claude Opus 5.5 Claude Chat Max
High is Argon’s highest thinking setting. These app settings do not equalize compute or tools.…