Introduction
A high token throughput doesn't necessarily translate to a fast user experience in a large language model (LLM) application. The first token may take too long to arrive, or subsequent tokens may stream too slowly, especially under concurrent load. Throughput alone doesn't capture these differences.
LLM inference metrics help break performance down into measurable components, from the initial response delay to token generation speed and overall system load. This article covers nine key metrics, their formulas, and how to use them to evaluate latency, identify bottlenecks, and track performance over time:
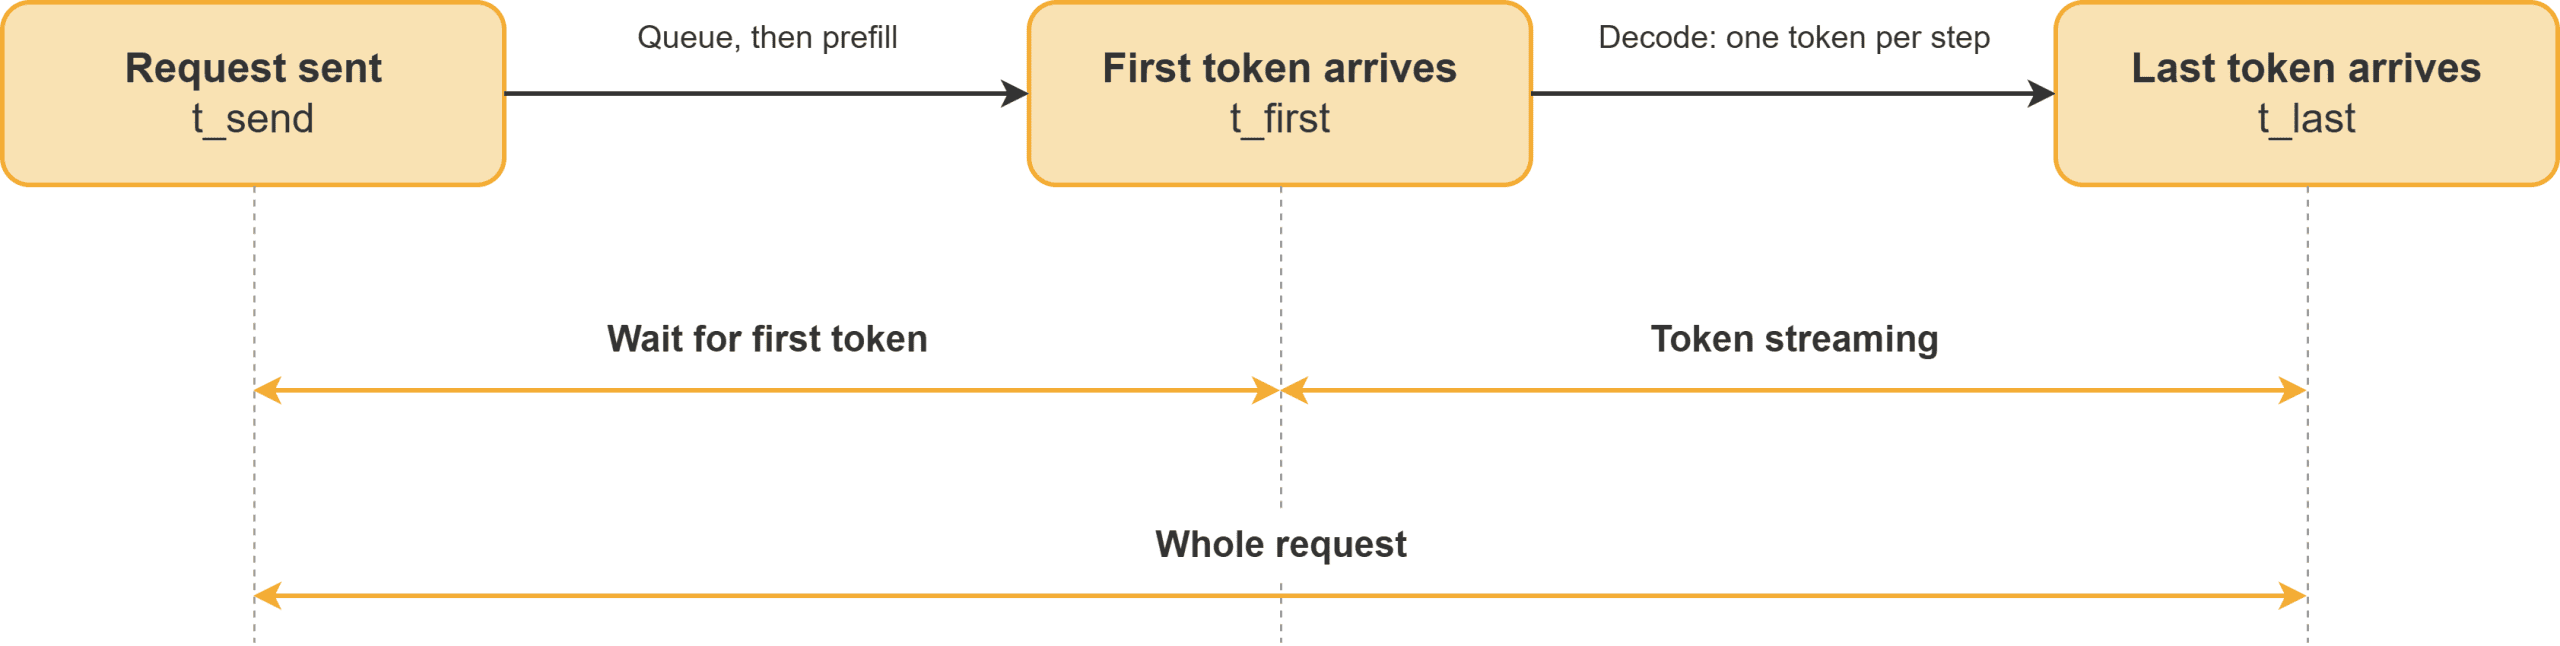
Per-request latency: time to first token (TTFT), end-to-end latency (E2E), token generation time, time per output token (TPOT), and inter-token latency (ITL)
Latency across many requests: mean, median, and tail percentiles
Server load: requests per second (RPS) and tokens per second (TPS)
Service quality: goodput
We start with the timeline of a single request.
Reading a Request…