Modern data pipelines handle massive volumes of structured and unstructured data every day. As datasets grow, poorly optimized Spark jobs become slower, more expensive, and harder to scale. Common issues include long execution times, excessive shuffling, memory bottlenecks, and inefficient joins.
Effective PySpark optimization can significantly improve performance, reduce infrastructure costs, and enhance cluster efficiency. In this article, we’ll explore 12 proven PySpark optimization techniques with practical examples and real-world performance strategies used by data engineers.
Table of contents
How Spark Executes Your Code Understanding Spark Architecture
Lazy Evaluation in Spark
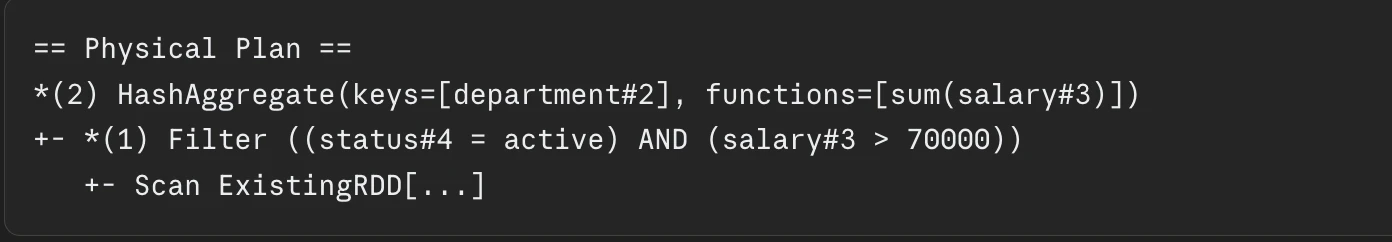
Understanding Spark Transformations and Actions Reading Spark Execution Plans with explain()
Ways to Optimise Your Spark Models Technique 1: Use Columnar File Formats Like Parquet or ORC
Technique 2: Filter Data as Early as Possible
Technique 3: Select Only Required Columns
Technique 4: Optimize Partitioning
Technique…