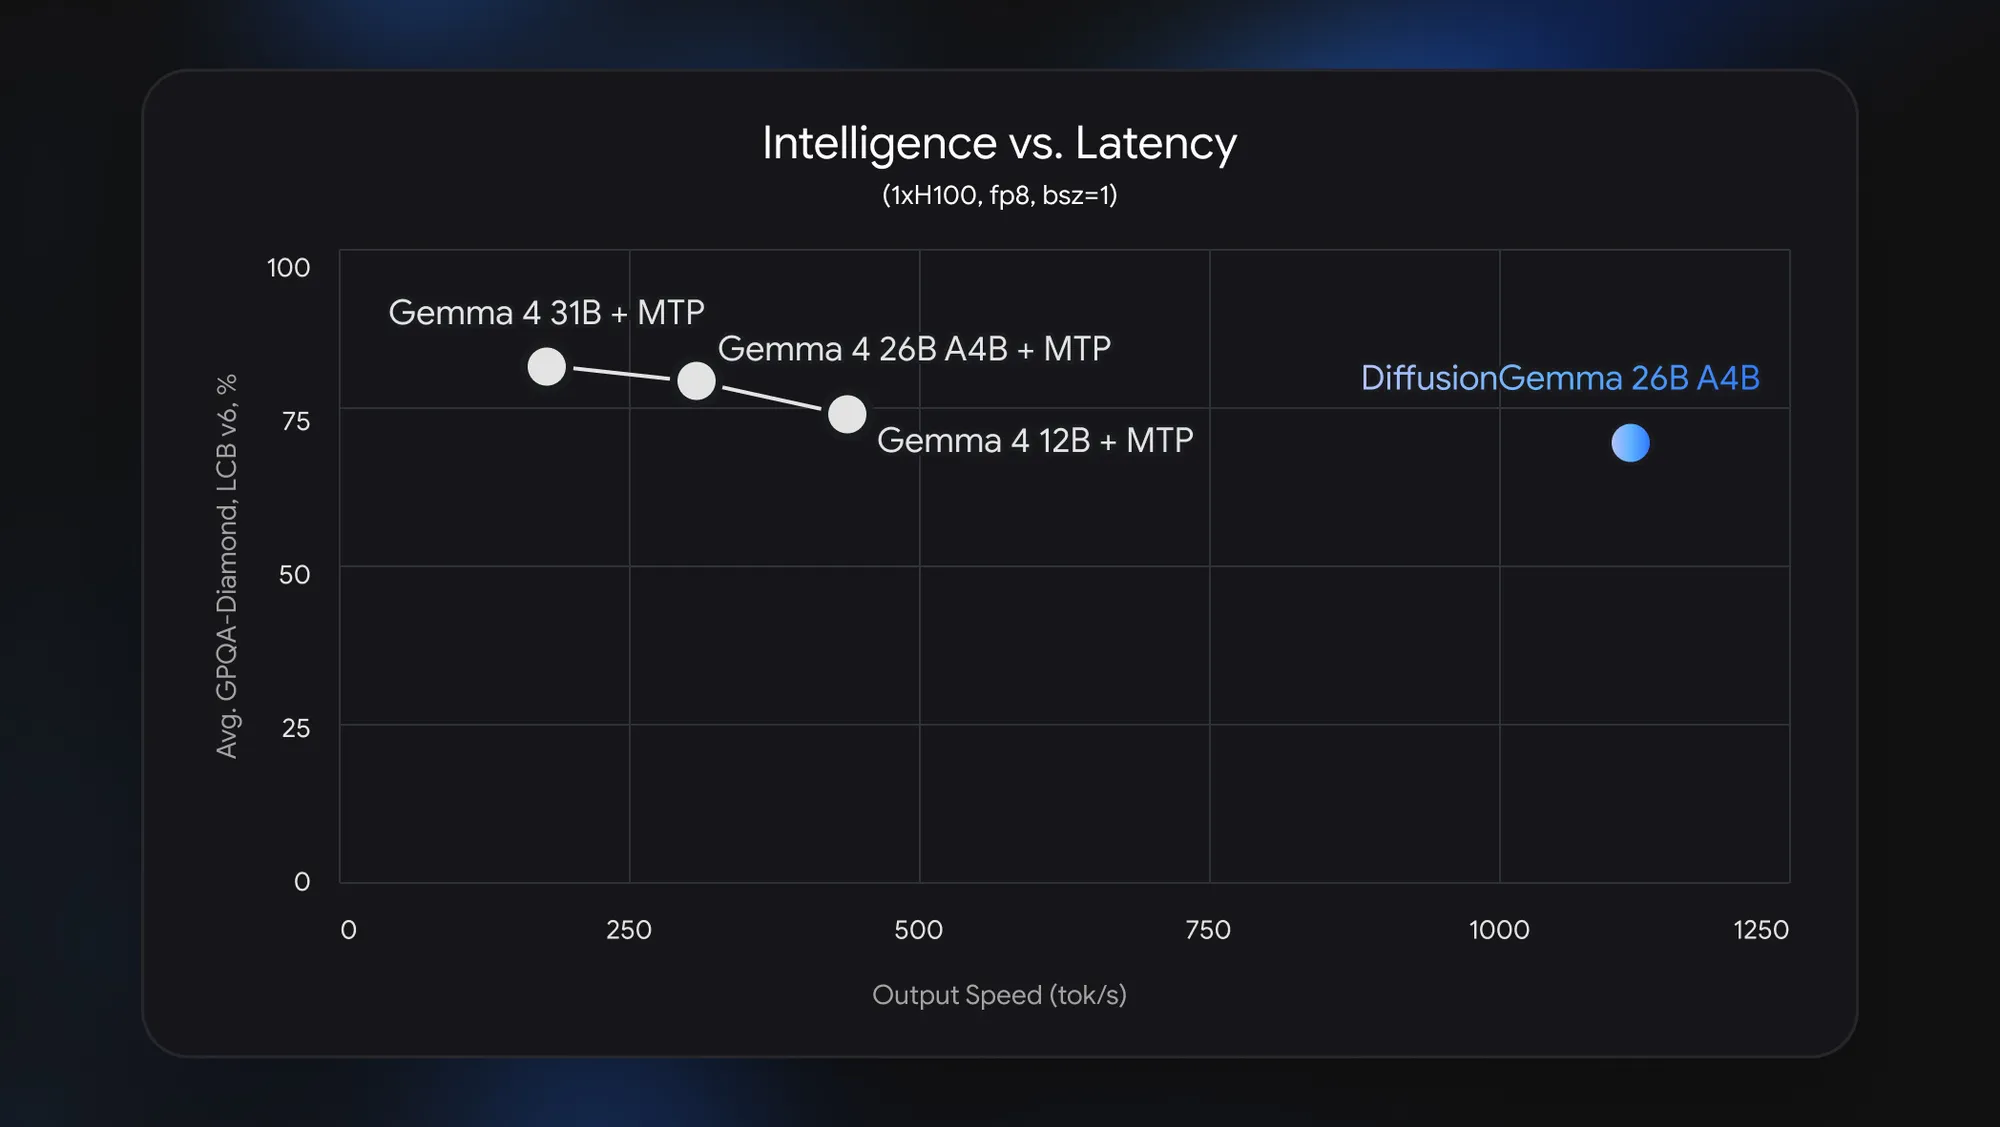
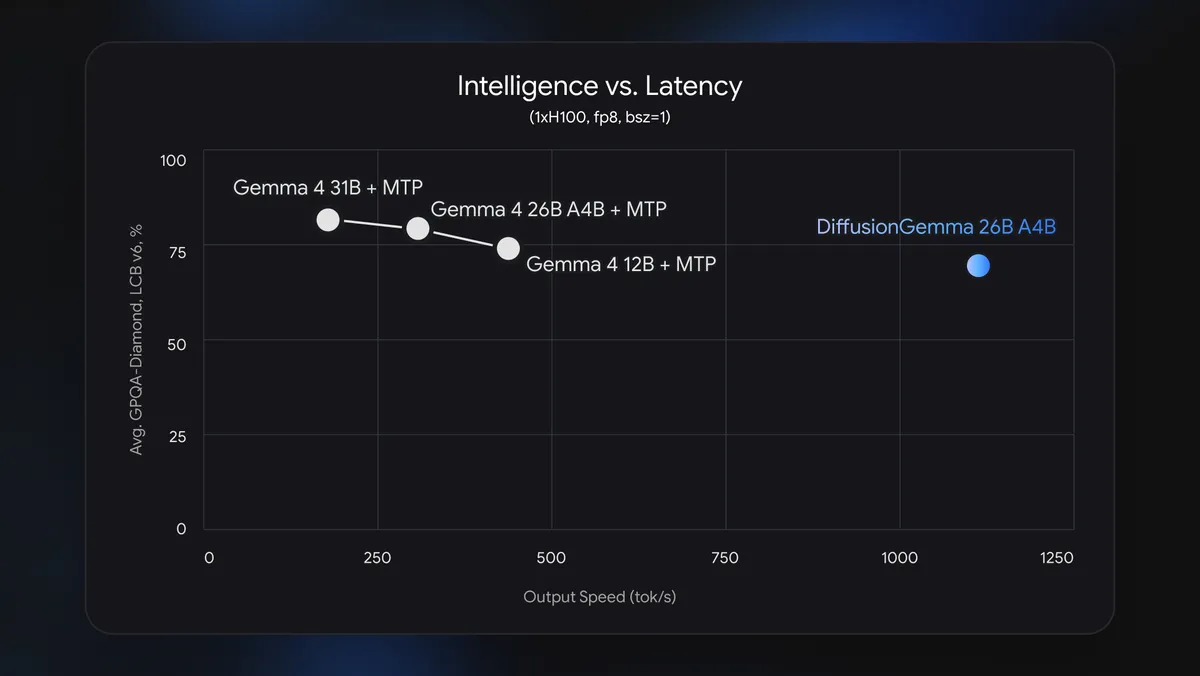
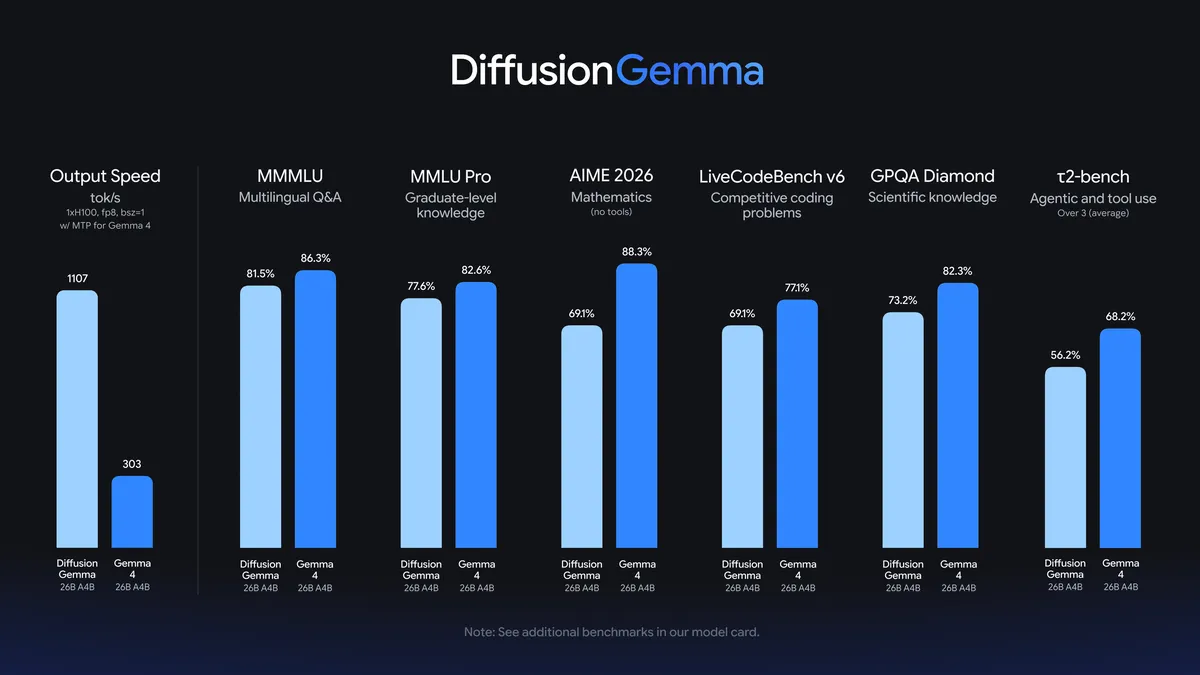
Our newest open experimental model delivers up to 4x faster inference on dedicated GPUs and opens the door to exploring speed-critical, interactive local workflows.
Sebastian Flennerhag
Research Scientist
Today, we’re introducing DiffusionGemma, an experimental open model that explores text diffusion, an exceptionally fast approach to text generation. Released under an Apache 2.0 license, this 26B Mixture of Experts (MoE) model moves beyond the sequential token-by-token processing of typical autoregressive Large Language Models (LLMs). Instead, it generates entire blocks of text simultaneously, delivering up to 4x faster text generation on GPUs.
Built upon the industry-leading intelligence-per-parameter of our Gemma 4 family and cutting-edge Gemini Diffusion research , DiffusionGemma integrates a novel diffusion head designed to maximize generation speed.…