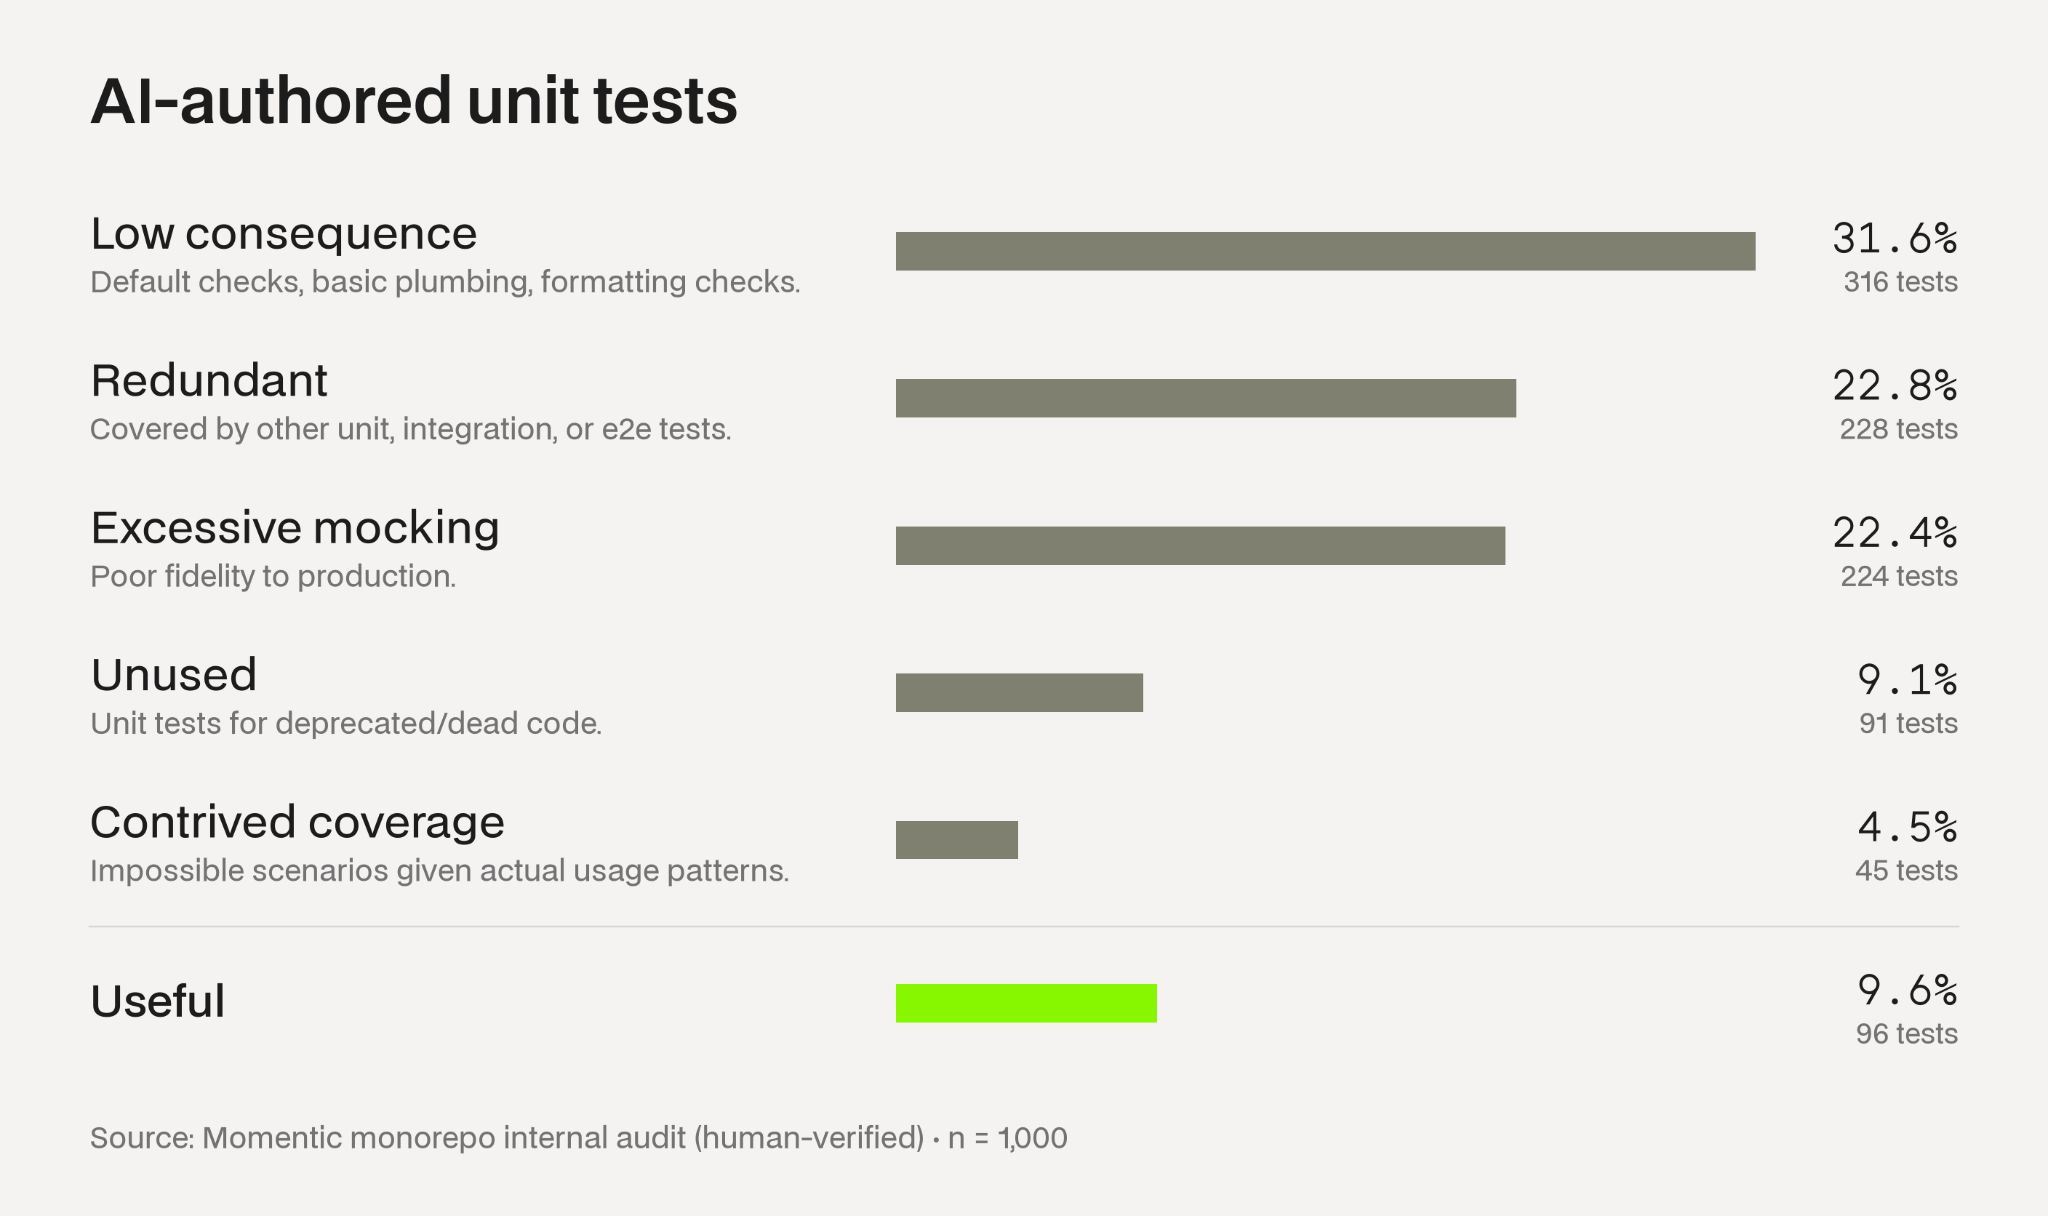
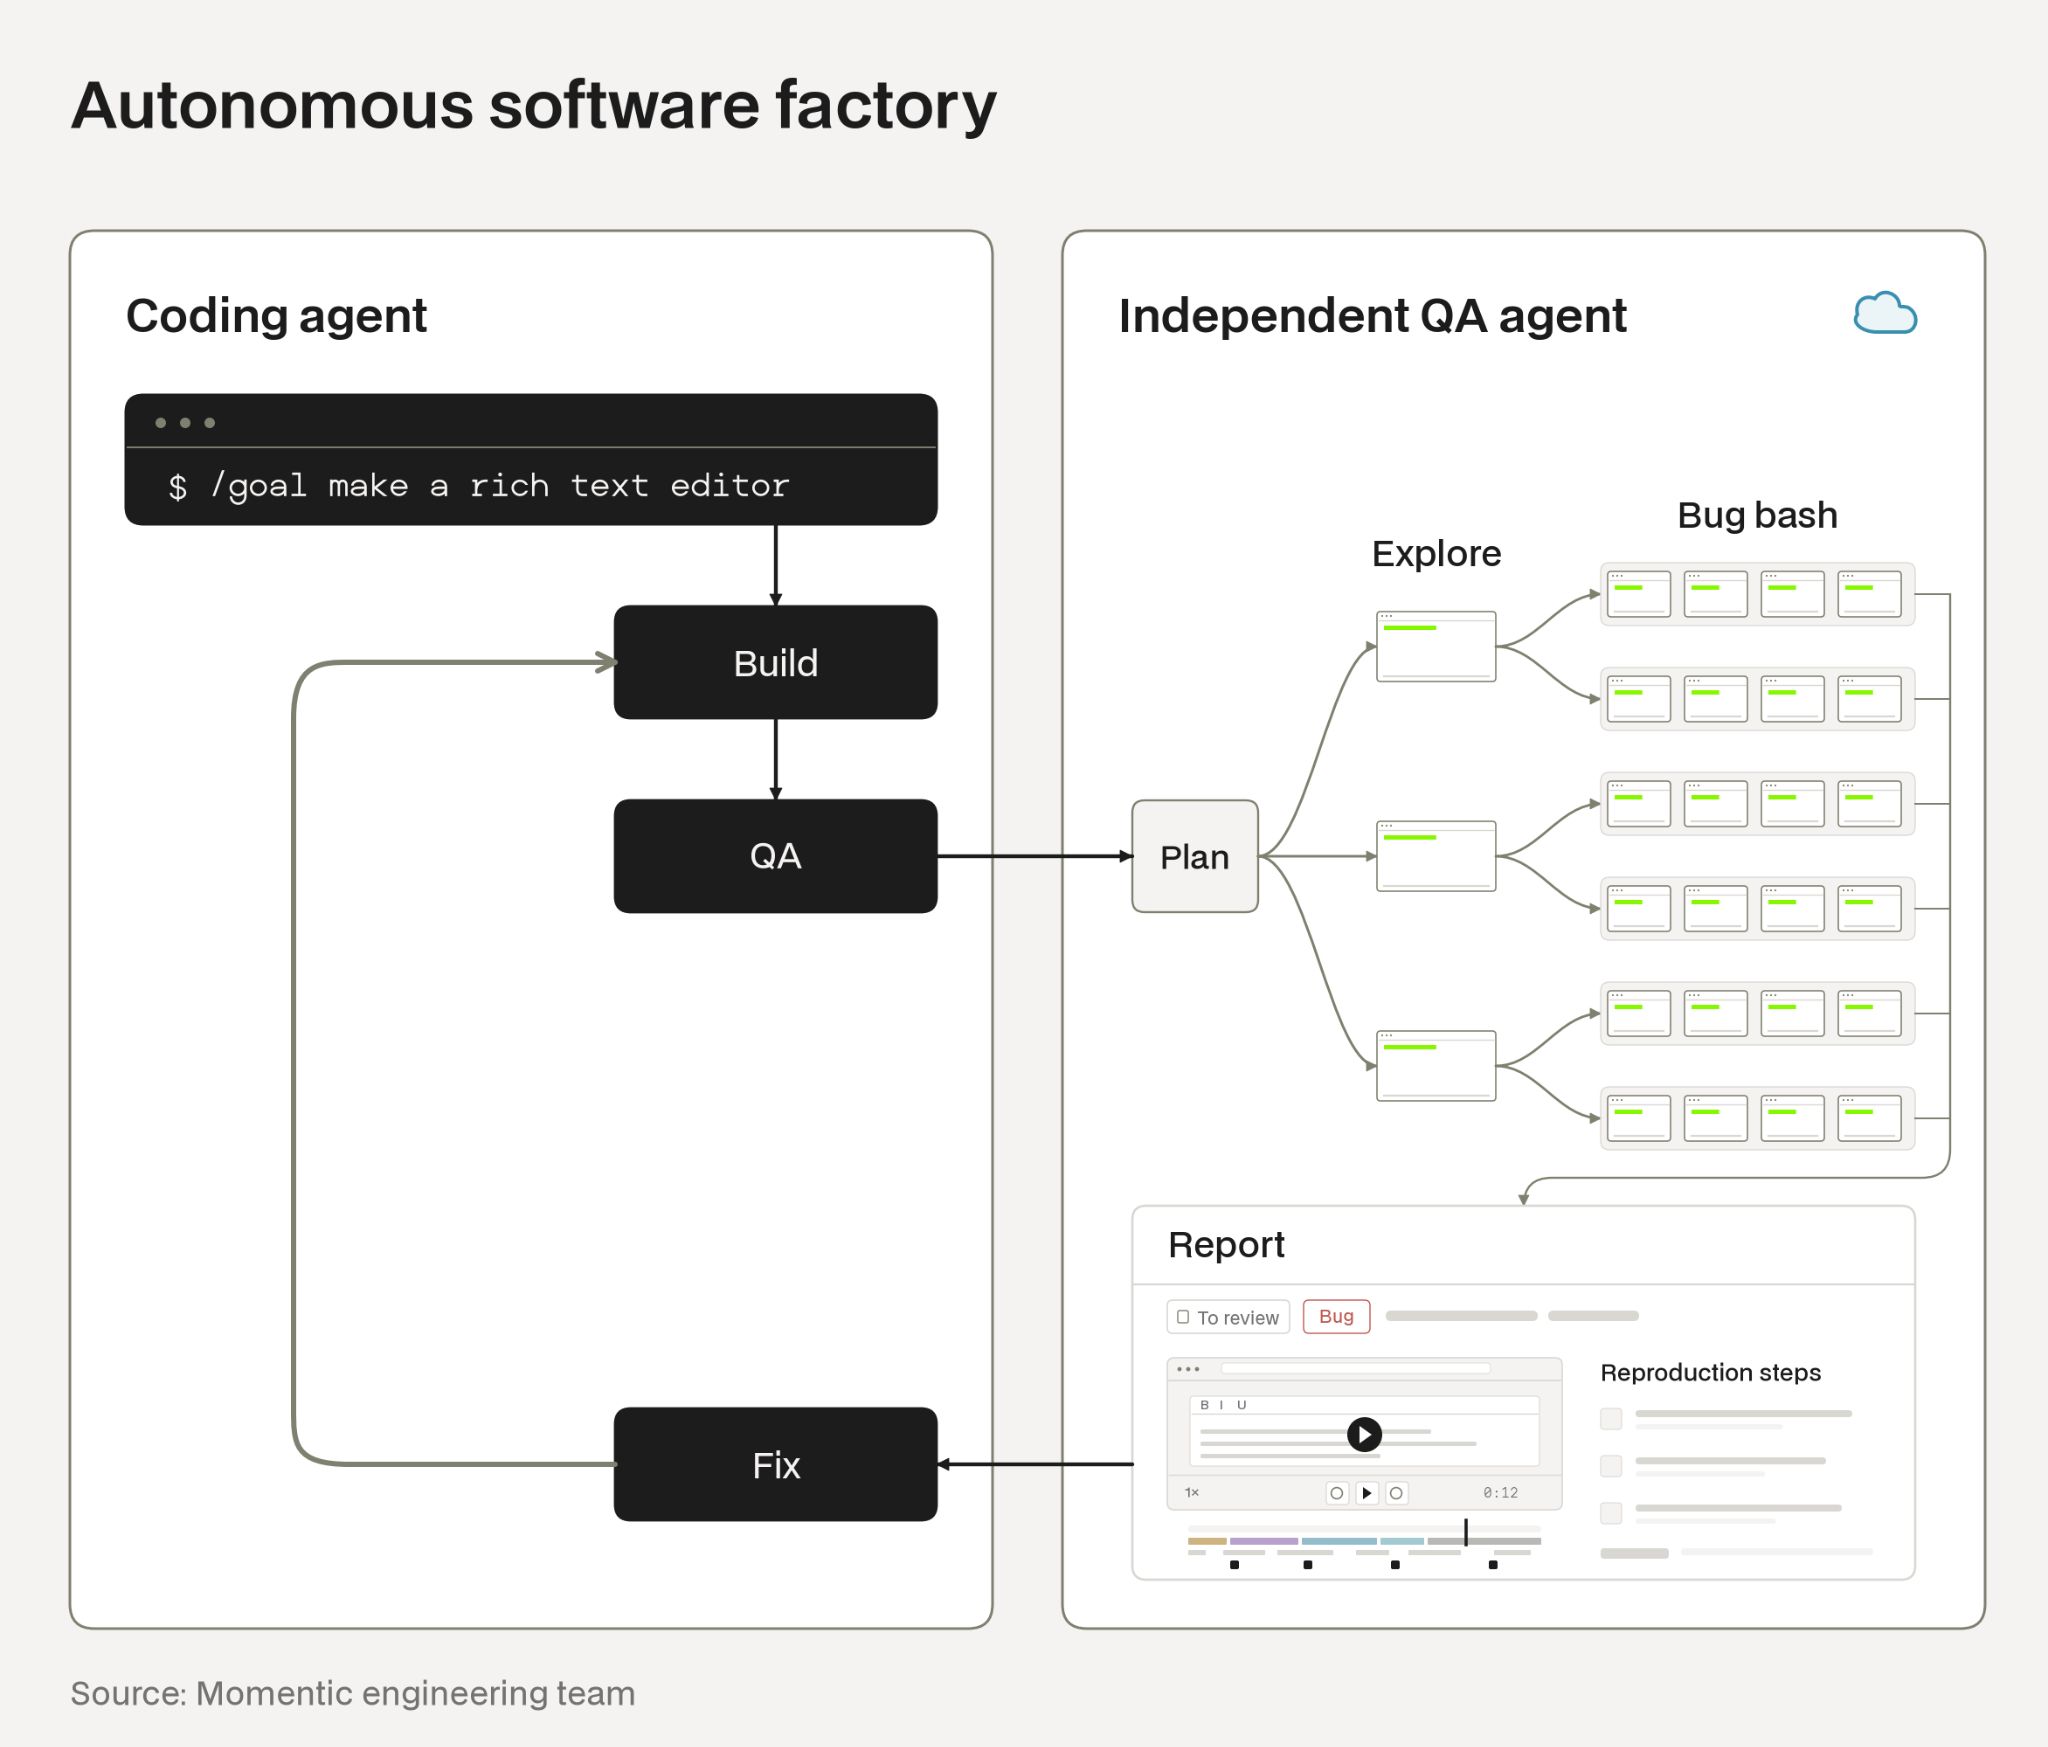
I lead an engineering team of eight at Momentic that has eagerly adopted background agents. My team frequently awes at the raw intelligence of these frontier models, but they also often complain that their agents will confidently declare that a feature was complete, only for basic functionality to fail when they opened the application for testing.
The problem isn't just that agents make mistakes. It's that their own verification often fails to catch them, leading to overconfidence.
Concretely, our engineering team has found three recurring problems: agents rely on shallow checks, inherit their own implementation blind spots, and become less reliable under the combined pressure of growing context and repeated failures.
Coding agents gravitate toward checks that are easy to write and easy to pass.…