Somewhere between “nanoGPT toy” and “you need a research lab” there’s a large, under-described region where one person with a few thousand dollars can train a meaningful model.
I wanted to see language and understanding emerge from random weights for myself, and to learn the parts you can only learn by starting from scratch. This project was written in the evenings, debugged on a 5090 and finished on rented B200s. It was heavily inspired by Andrej Karpathy’s nanochat .
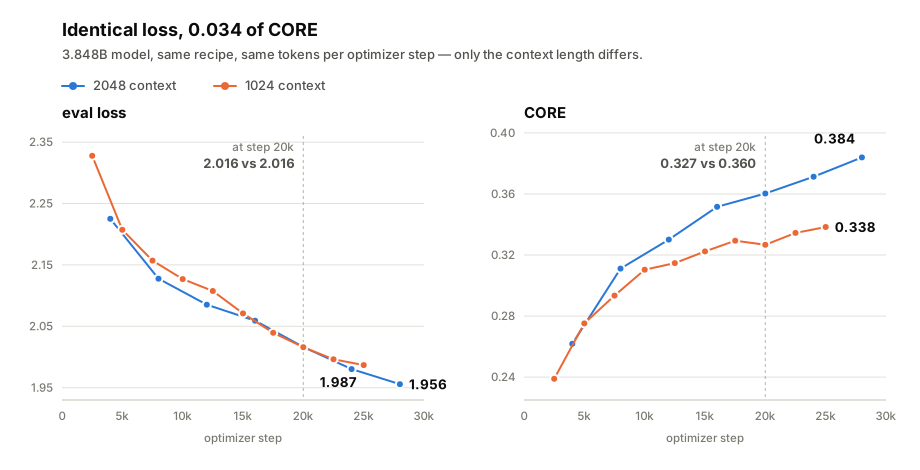
The result is a 3.8B-parameter model scoring 0.384 on CORE , trained on 65B tokens in 43 hours for $998 .
What follows is what worked, what didn’t, and what I still don’t know.
Model Params Tokens Hardware Time Cost CORE
GPT-2 (OpenAI) 1.5B — — — — 0.2565
nanochat d26 ~561M 11.2B 8× H100 ~3h — ~0.258
nanochat d32 ~1B — 8× H100 ~33h ~$1000 0.310
little-lm 3.8B (1024 ctx) 3.848B 57.3B 8× B200 35.9h $820 0.338
little-lm 3.8B (2048 ctx) 3.848B 65.3B 8× B200 43h $998 0.384
My model is larger than nanochat d32 and took similar wall-clock…