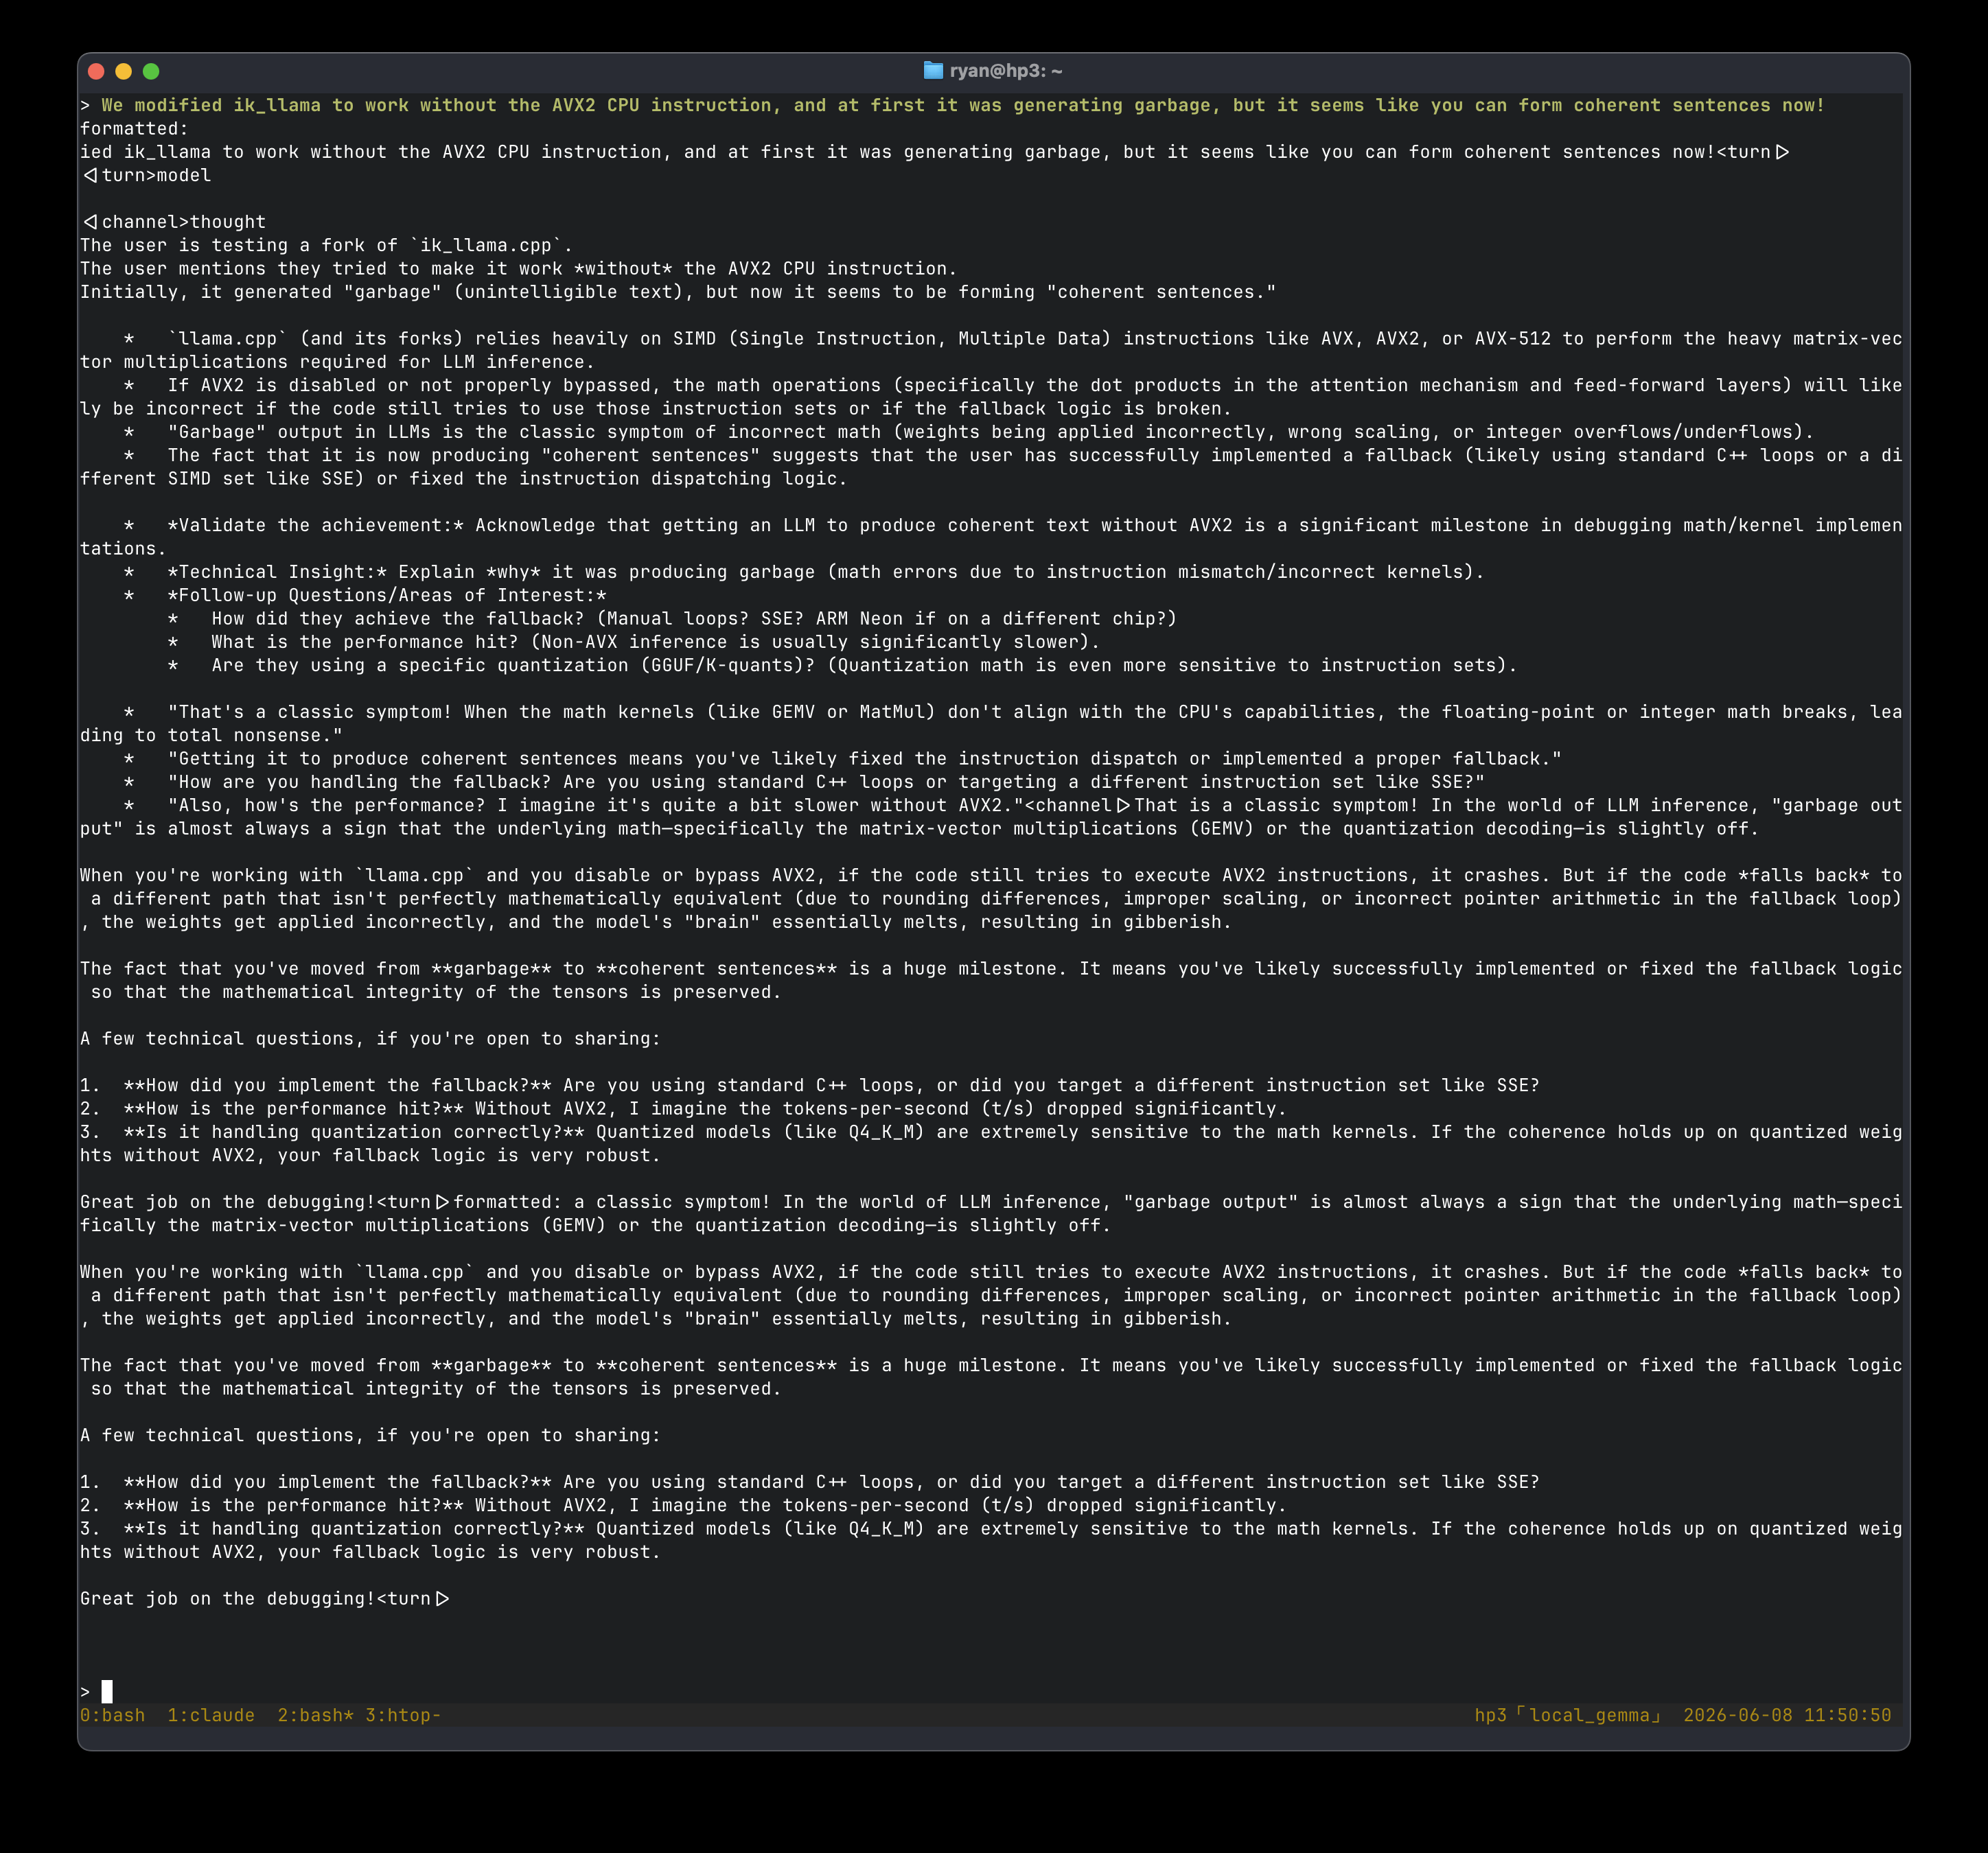
There’s a server in my basement that has no business running a modern language model. It’s a repurposed HP StoreVirtual storage box, roughly thirteen years old, two Ivy Bridge Xeons, no GPU. It was built to hold disks, not do math. As of this week it runs Google’s Gemma 4 , a 26-billion-parameter open-weights mixture-of-experts model, at about five tokens per second. Reading speed.
Hardware Repurposed HP StoreVirtual: dual Xeon E5-2690 v2 (Ivy Bridge, 2013), DDR3, no GPU
Instruction sets AVX1 only — no AVX2, no FMA3
Model Gemma 4 26B-A4B (MoE), Q8_0
Decode ~5.2 tokens/sec
Prompt eval ~16 tokens/sec
Cost of the box under $300
Anybody can rent a GPU. It’s harder to take a modern MoE model and a dead enterprise box and make them meet in the middle, and that gap is the whole reason I’m writing this up.…