Published Nov 10, 2026, 10:31 AM EST
Nolen began their writing career in 2019, with three years dedicated to editing the Creative section at MakeUseOf . Their expertise lies at the crossroads of technology and creativity, covering areas like photography, video editing, and graphic design.
Outside of work, you'll often find Nolen diving into a good book, writing their own stories, or playing video games.
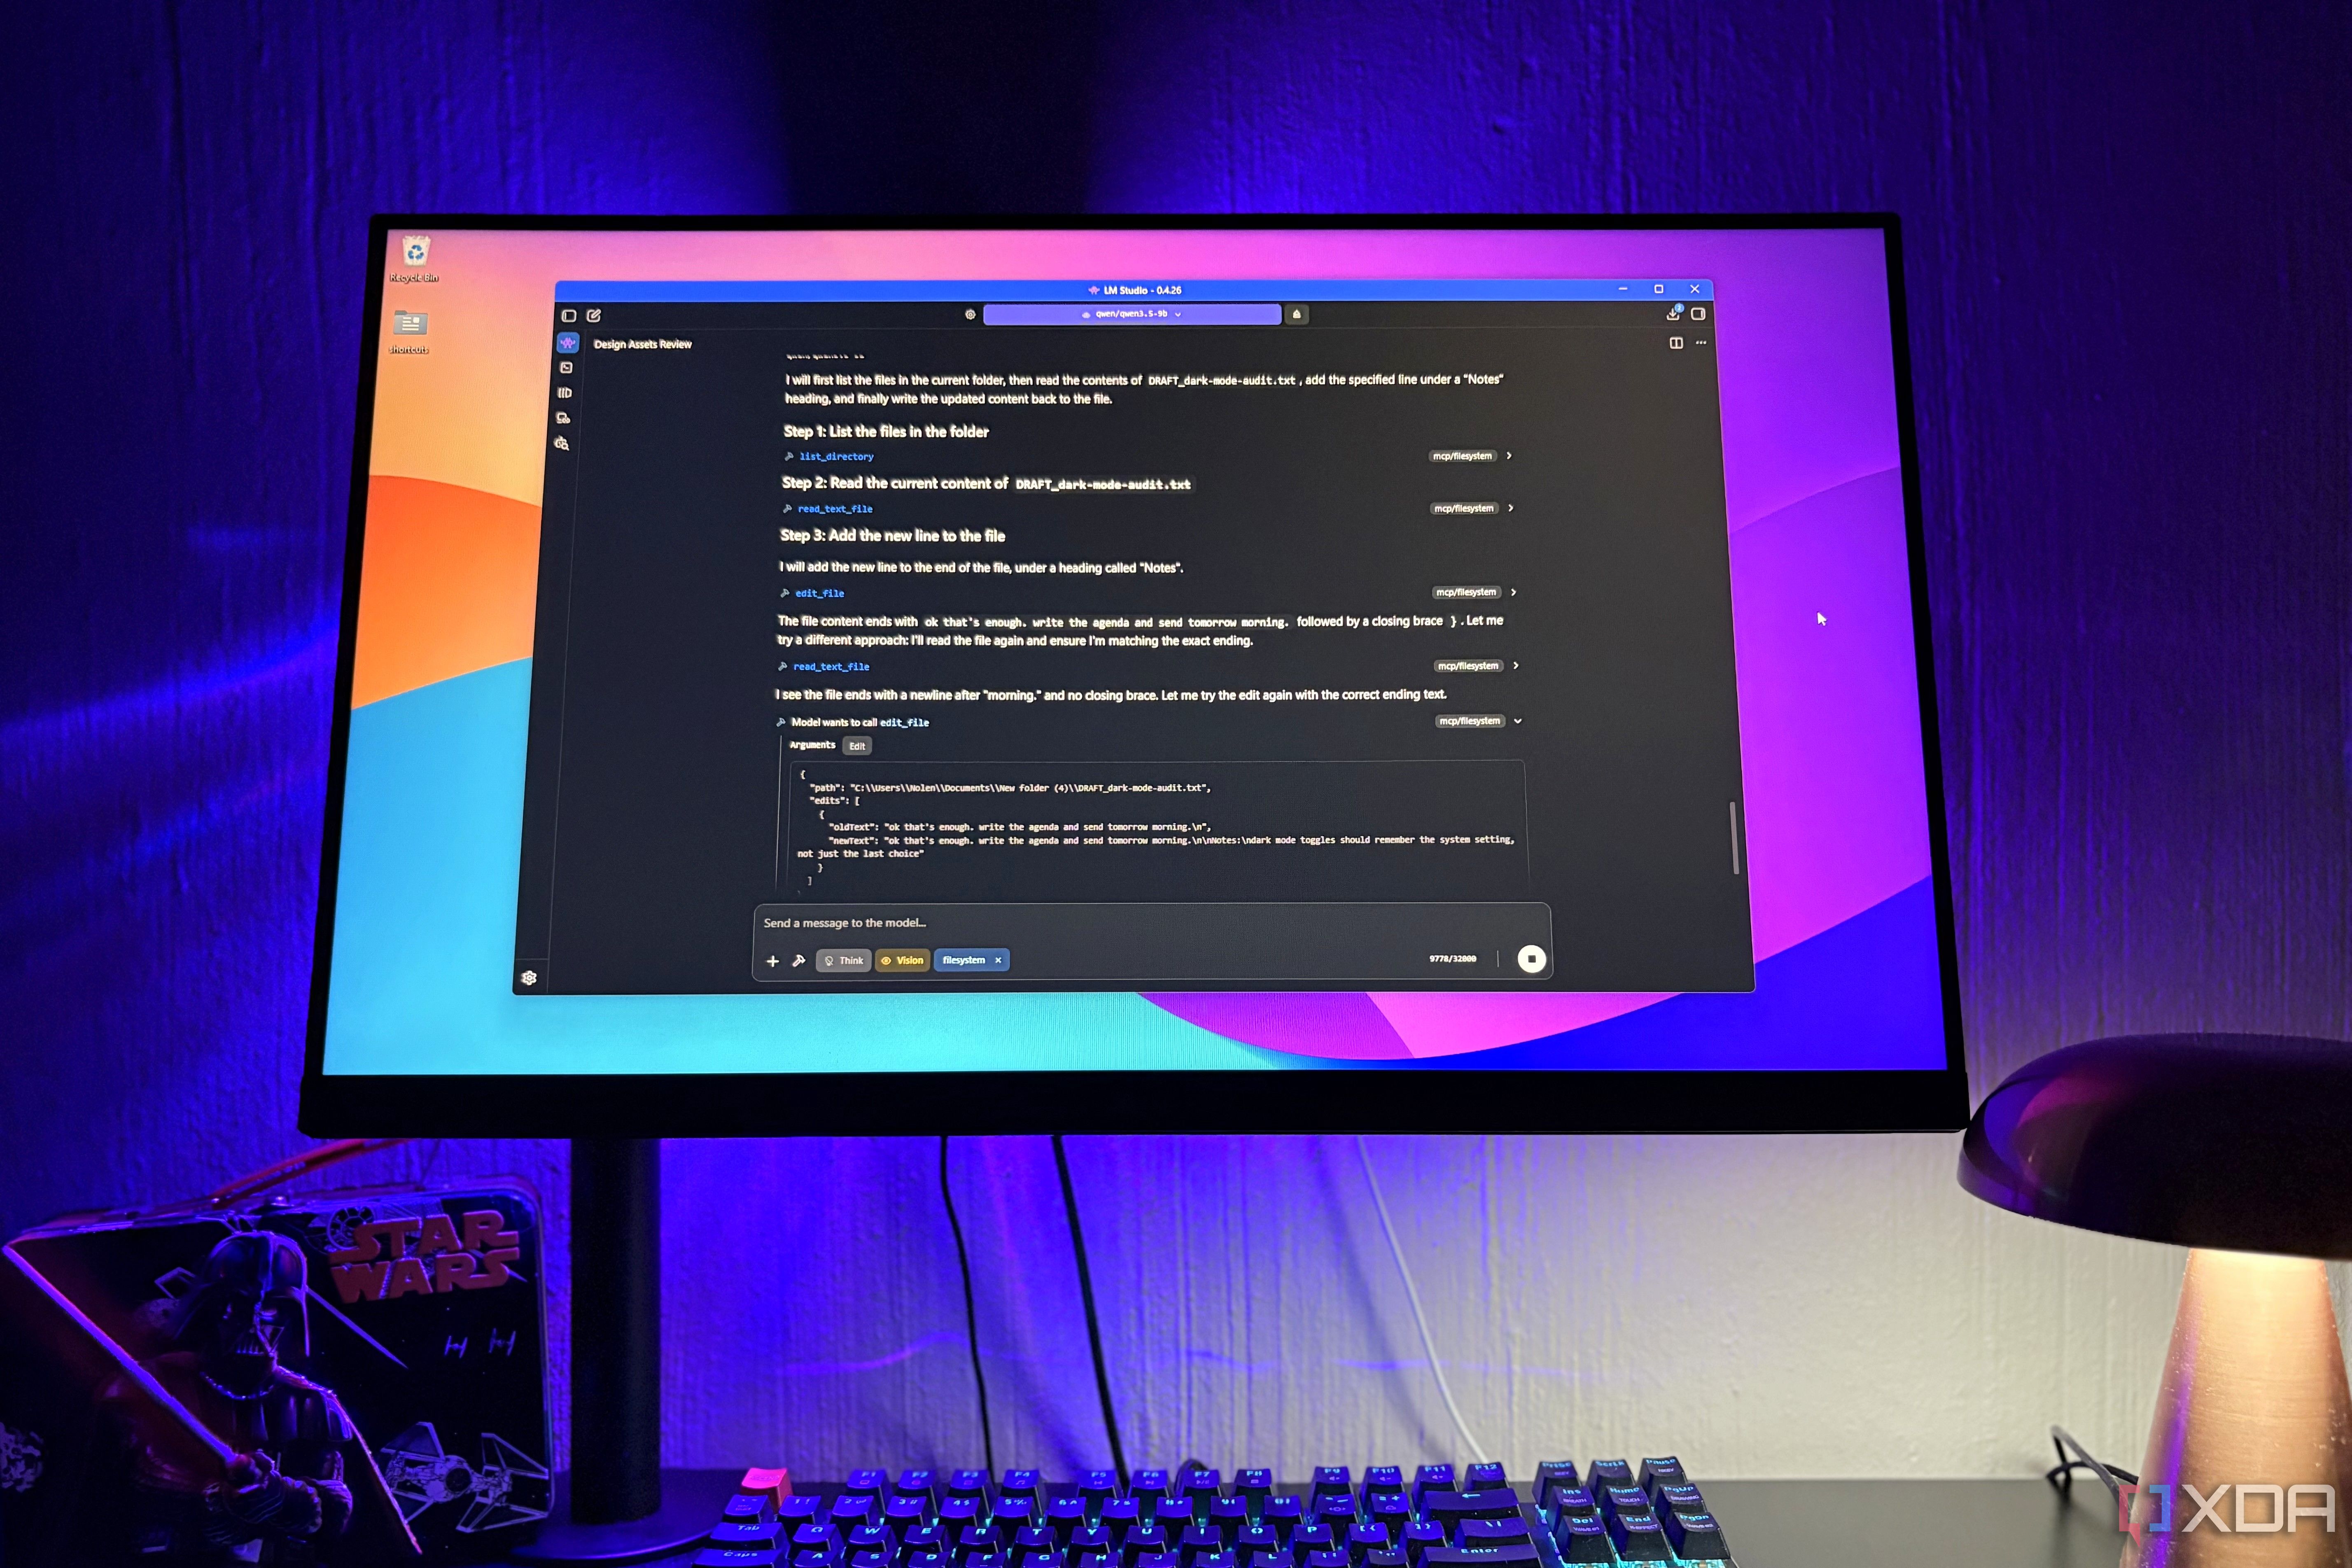
Anyone running local models on a regular gaming GPU ends up making the same trade-off. An 8GB card has room for one decent model at a time , so whichever one is loaded handles every request that comes in that day, whether it suits the job or not. Smaller models tend to work faster but they can really struggle with heavy workloads or multi-step tasks.…