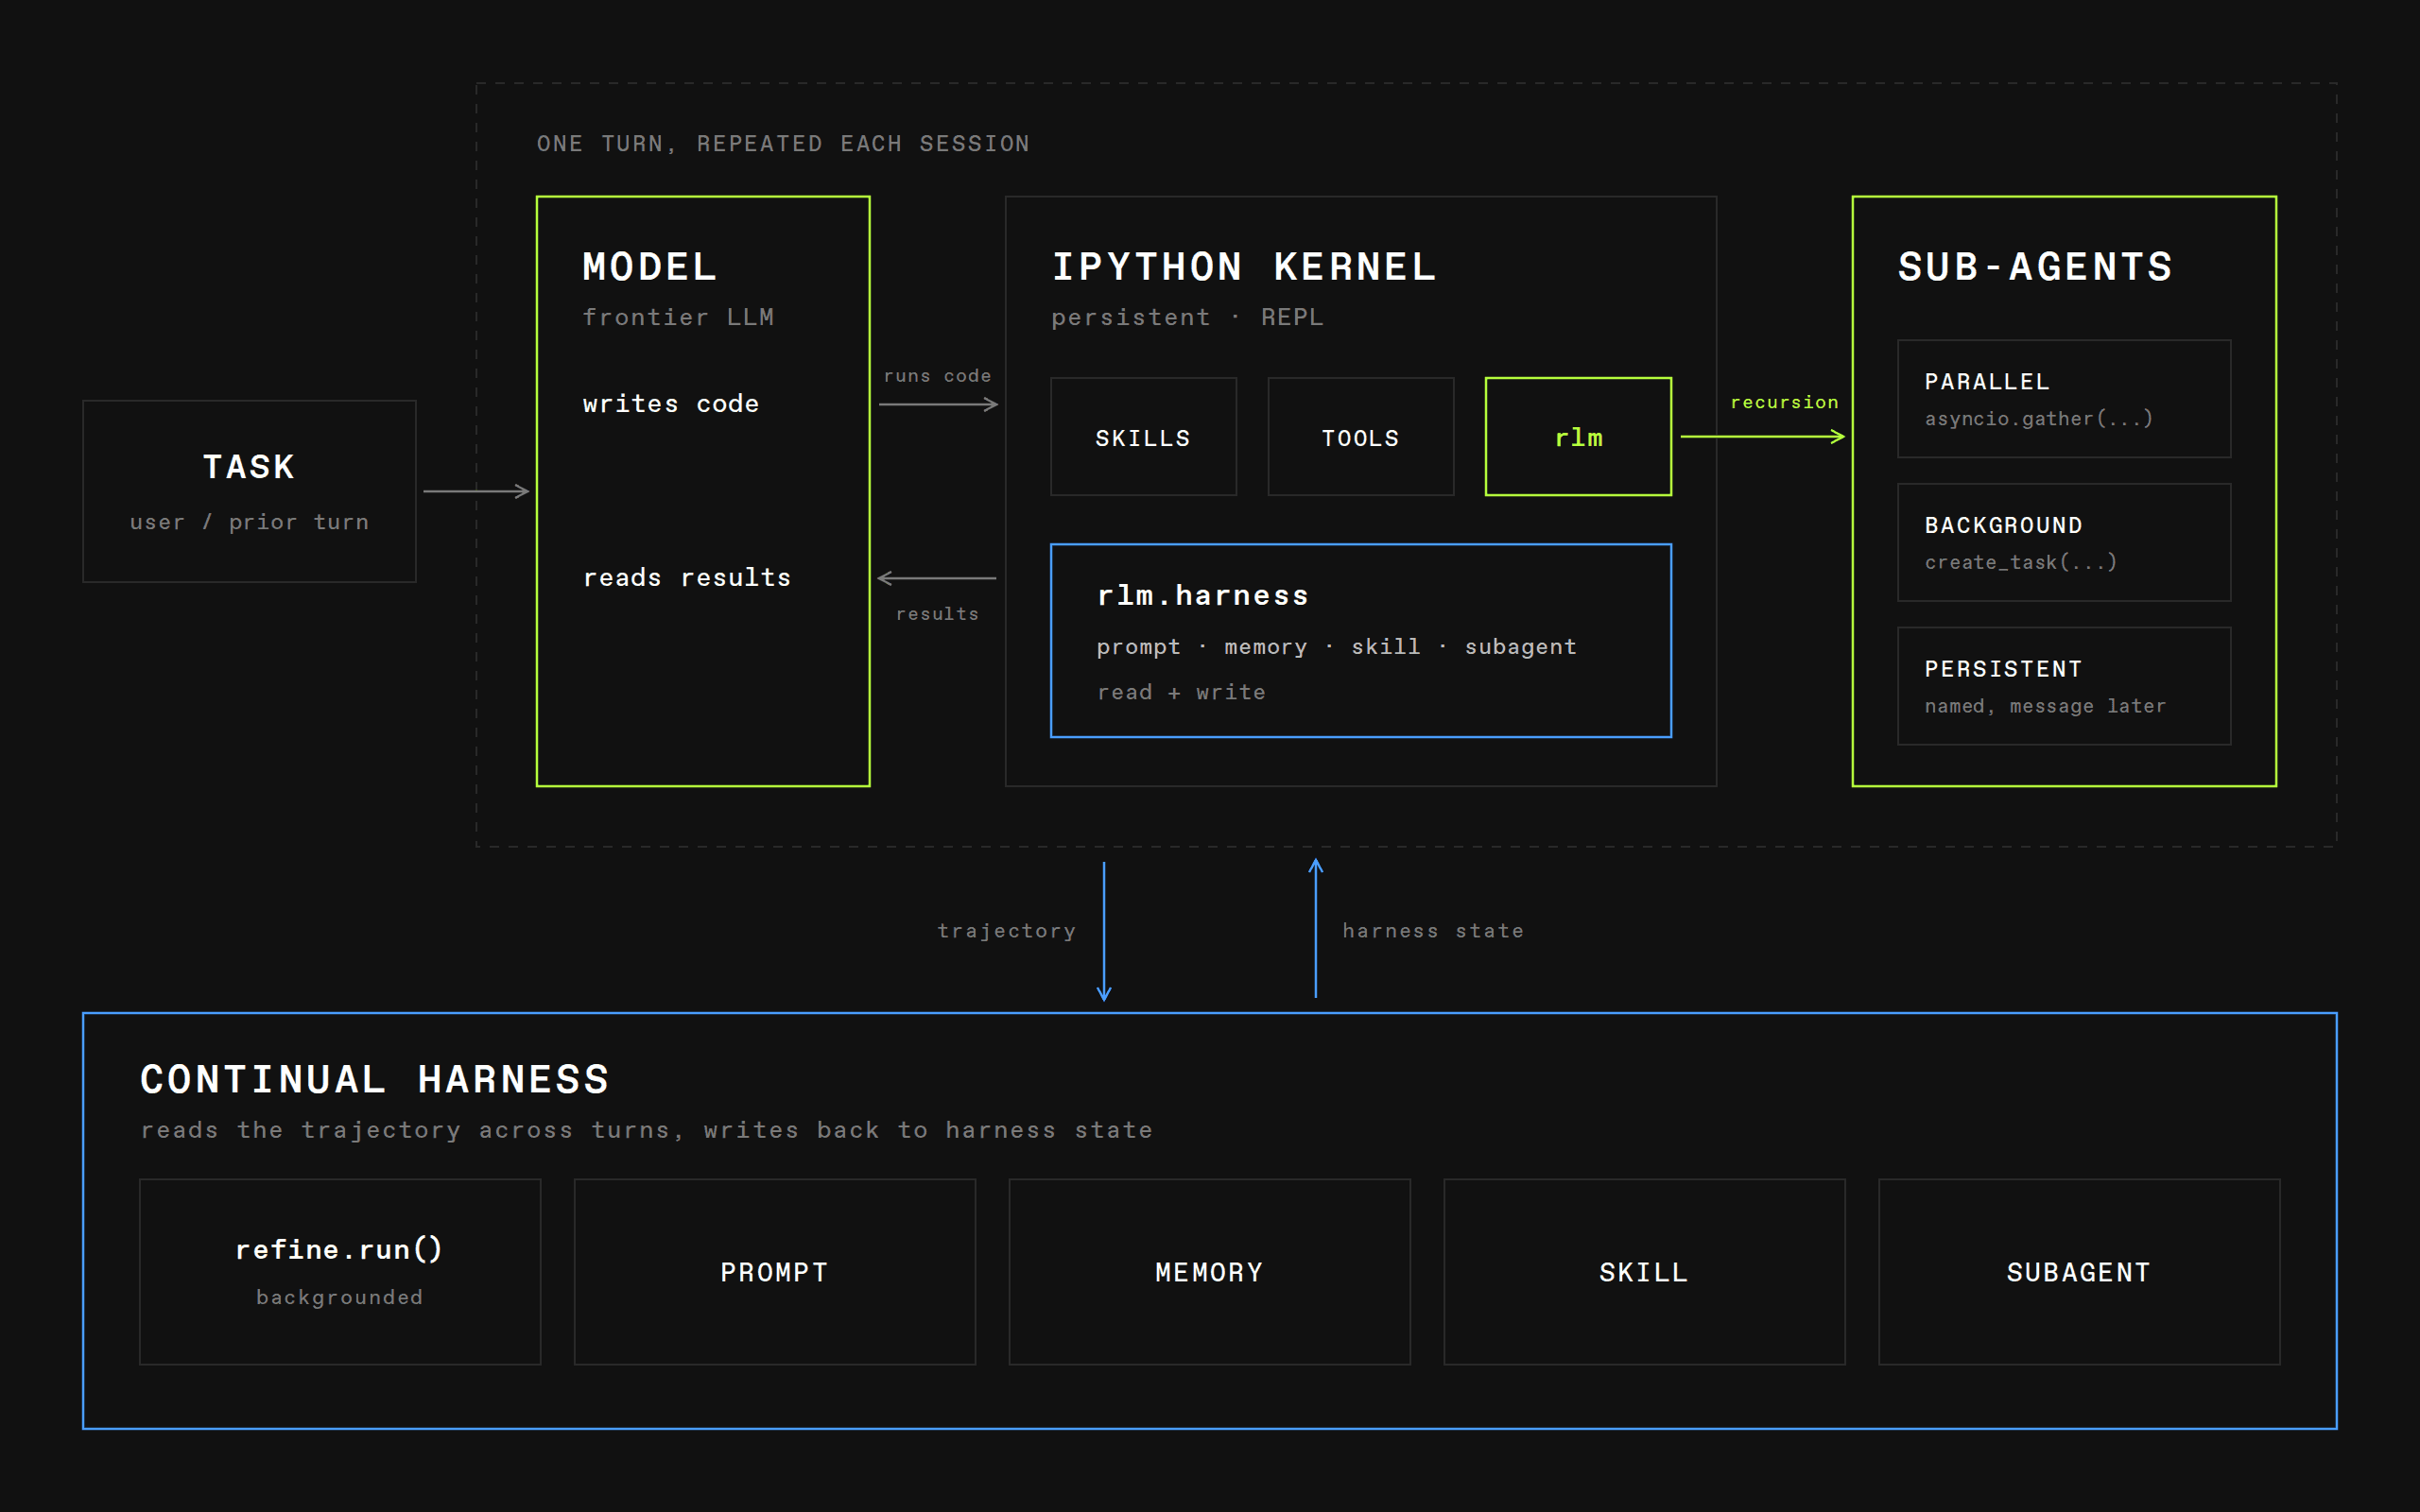
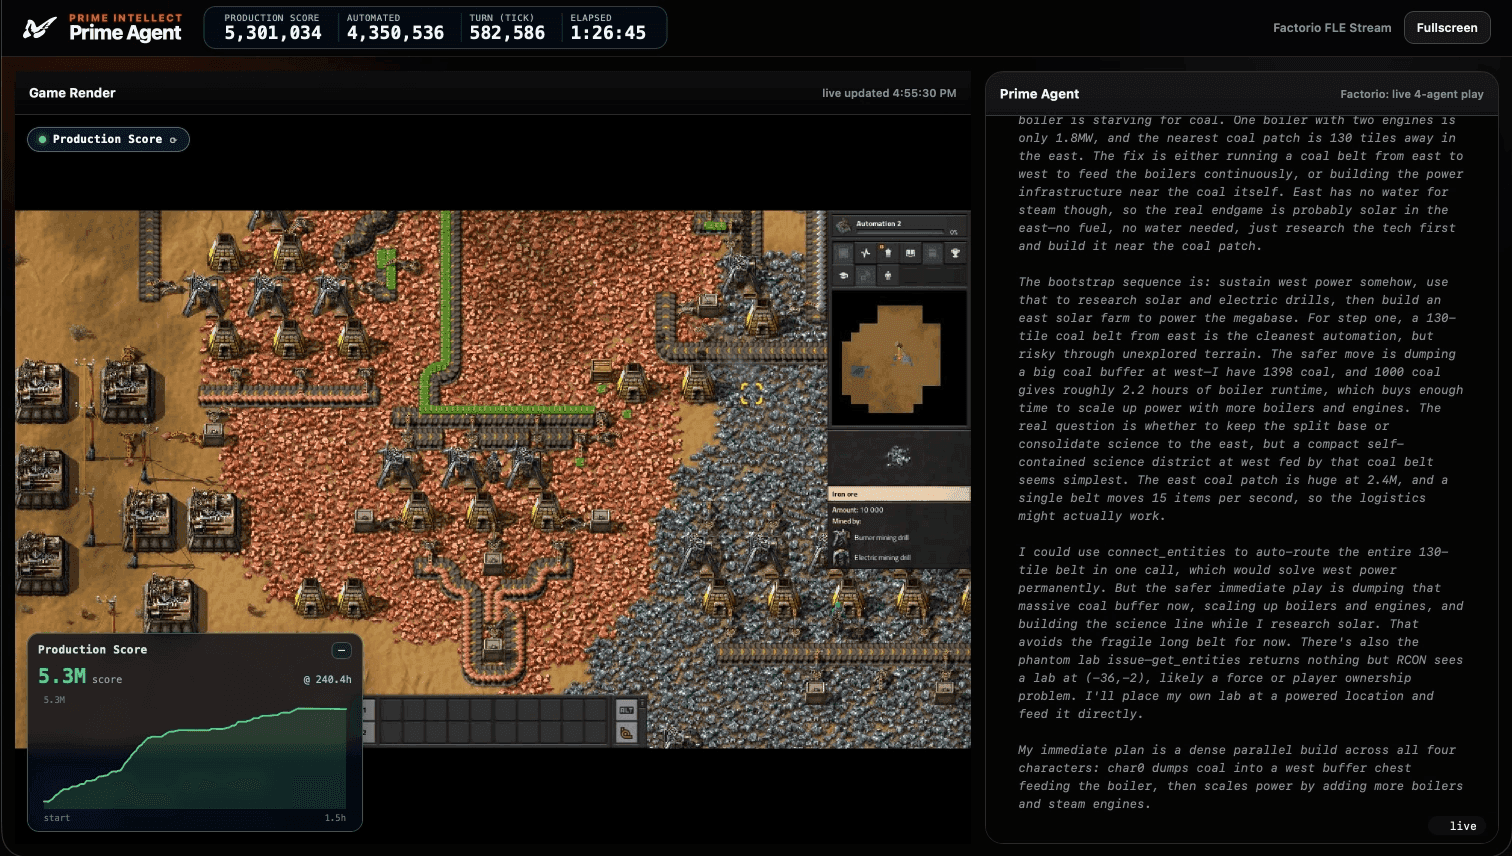
Prime Agent: A self-improving RLM agent Today, we are launching Prime Agent , our self-improving coding harness designed around two abstractions, the Recursive Language Model (RLM) [ citation ] and Continual Harness [ citation ]. Modern harness designs were built around the capabilities of earlier generations of models, and they do not reflect what frontier models can do today: fixed tool-calling schemas and context compaction force the model to work around its own scaffolding instead of leveraging it. Static, hand-engineered sub-agents, prompts, skills, and memory are set once at design time and never adapt to what the agent learns while running. We believe that harnesses should instead extrapolate on current model capabilities toward the next frontier of reasoning patterns. Prime Agent is built around this principle through two main abstractions: The Recursive Language Model (RLM) treats context as a variable and subagent delegation as function calls inside a REPL.…