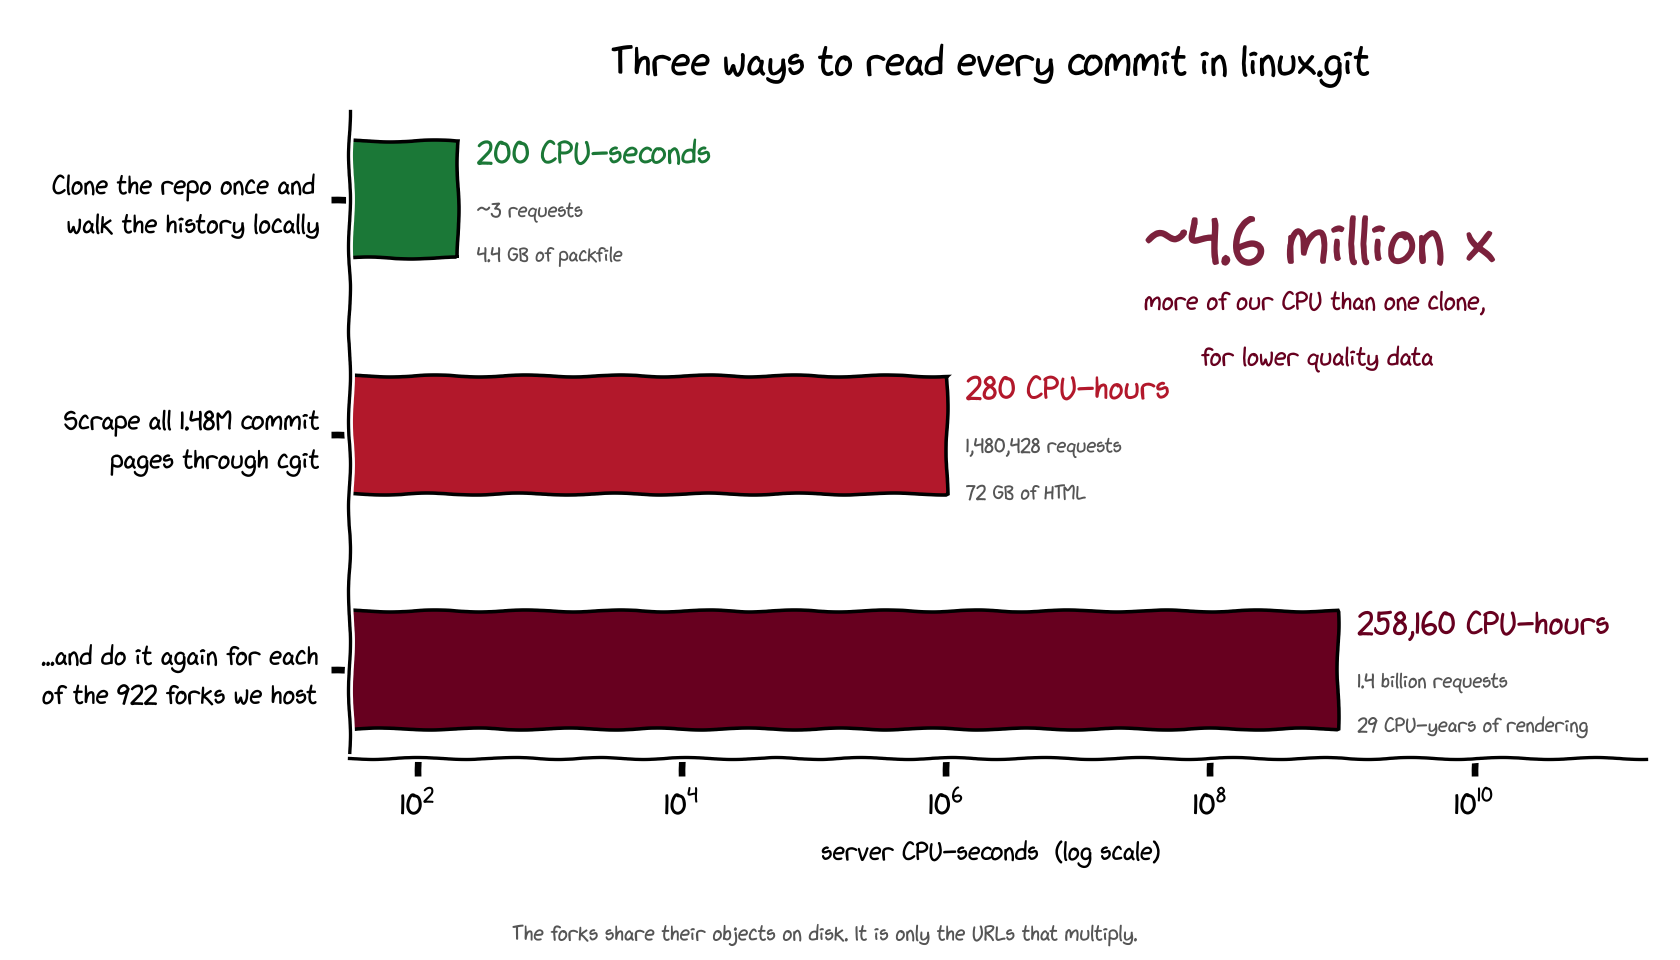
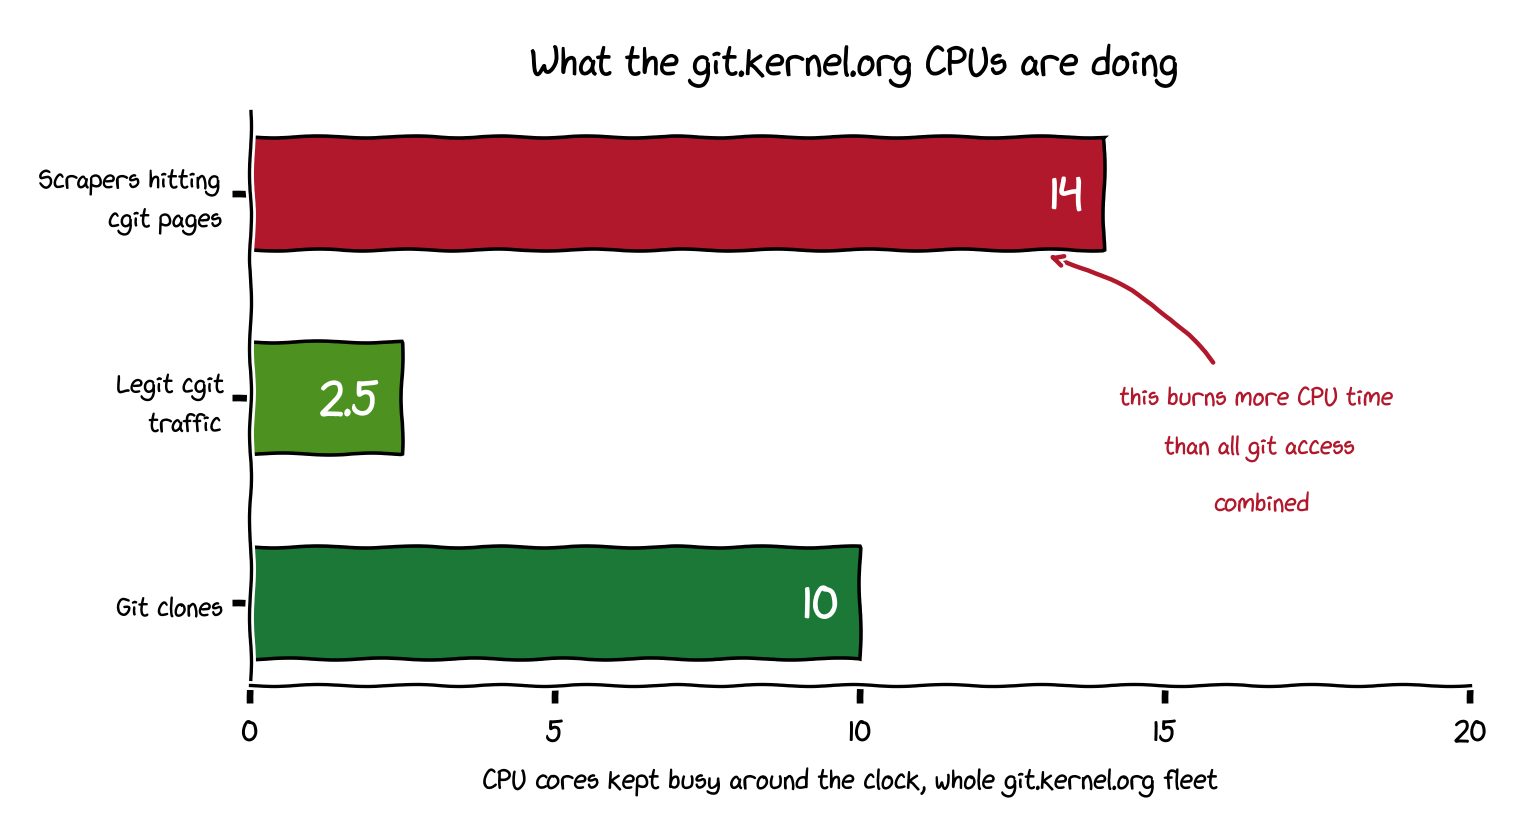
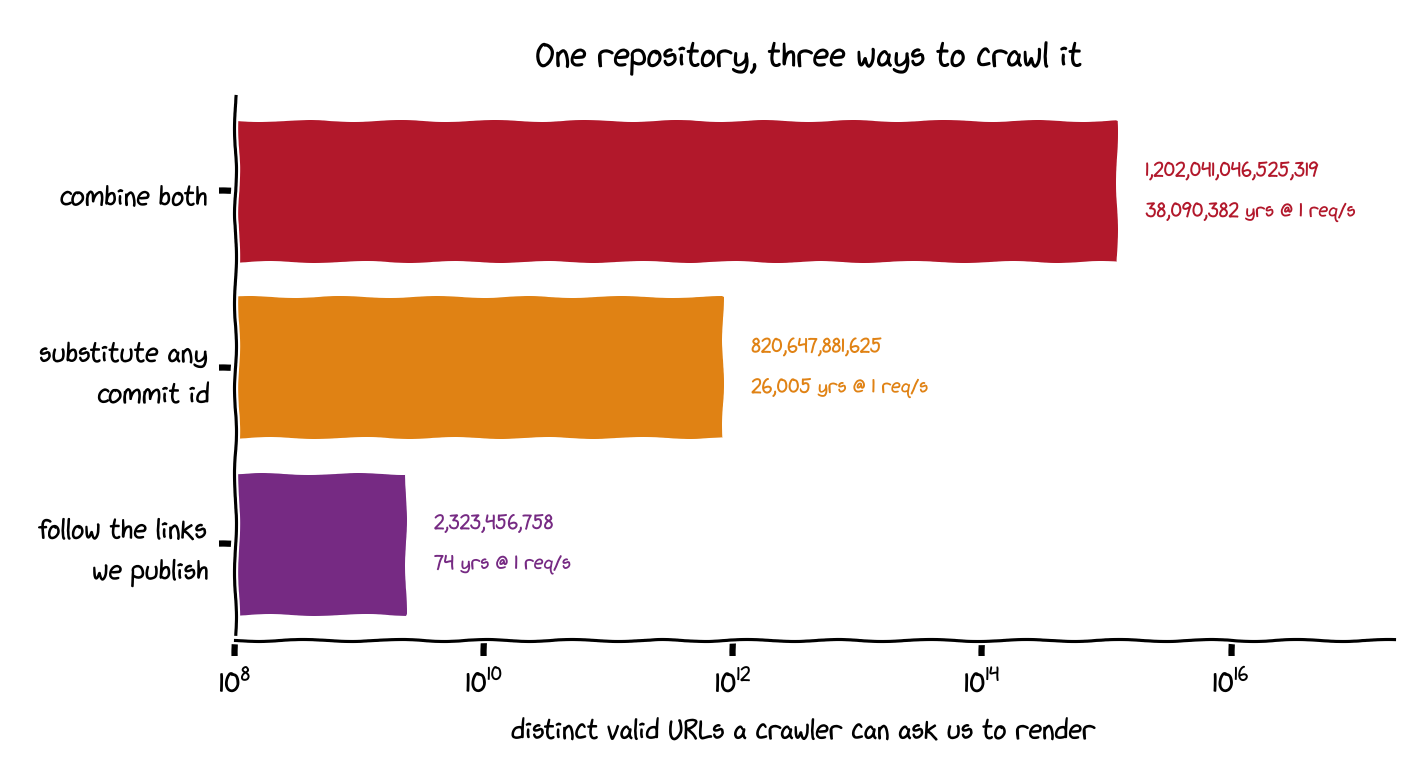
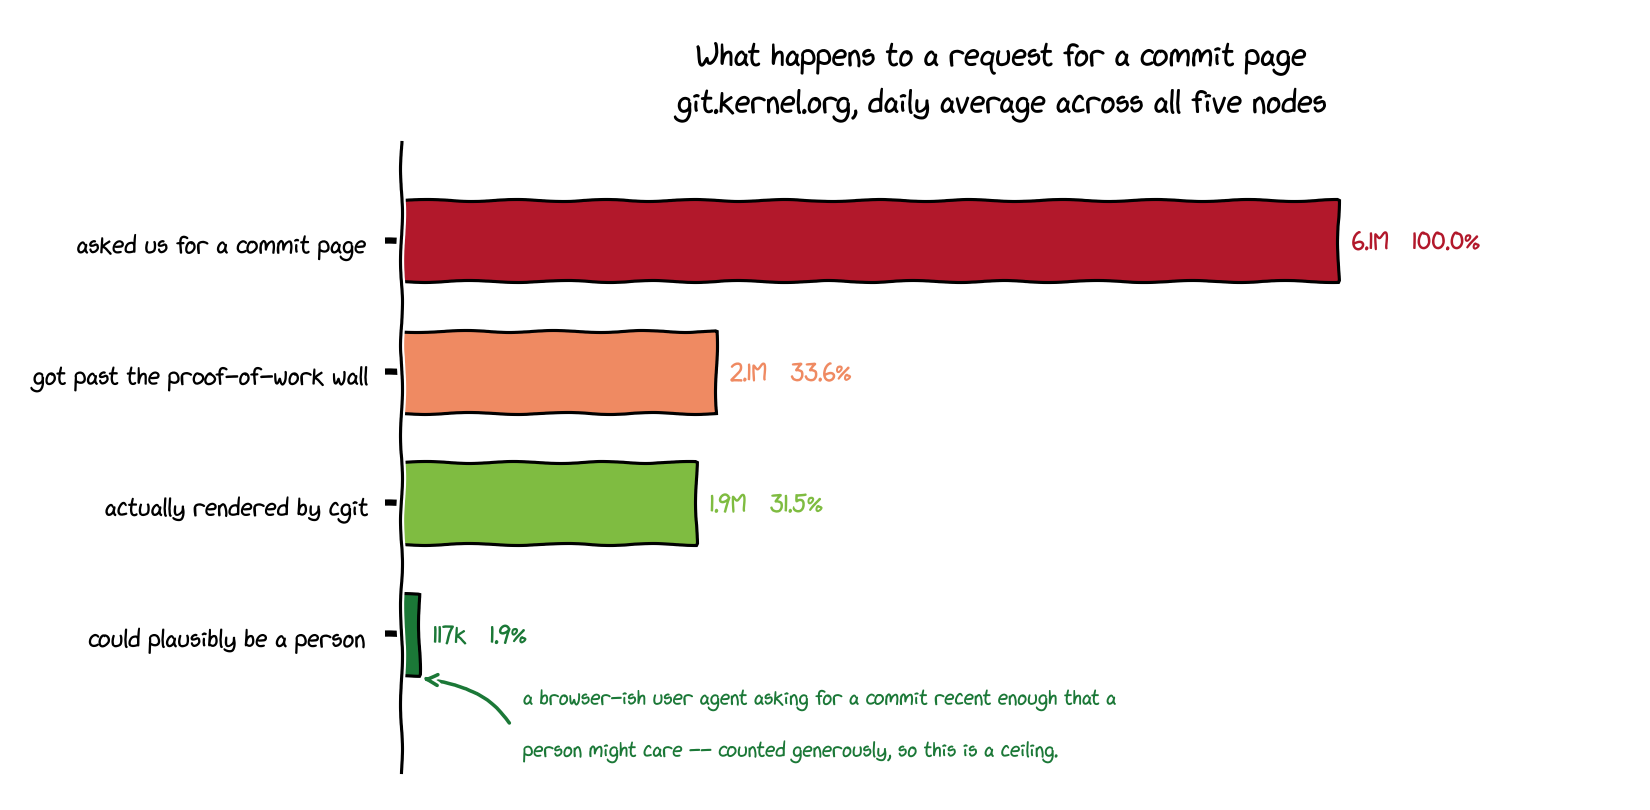
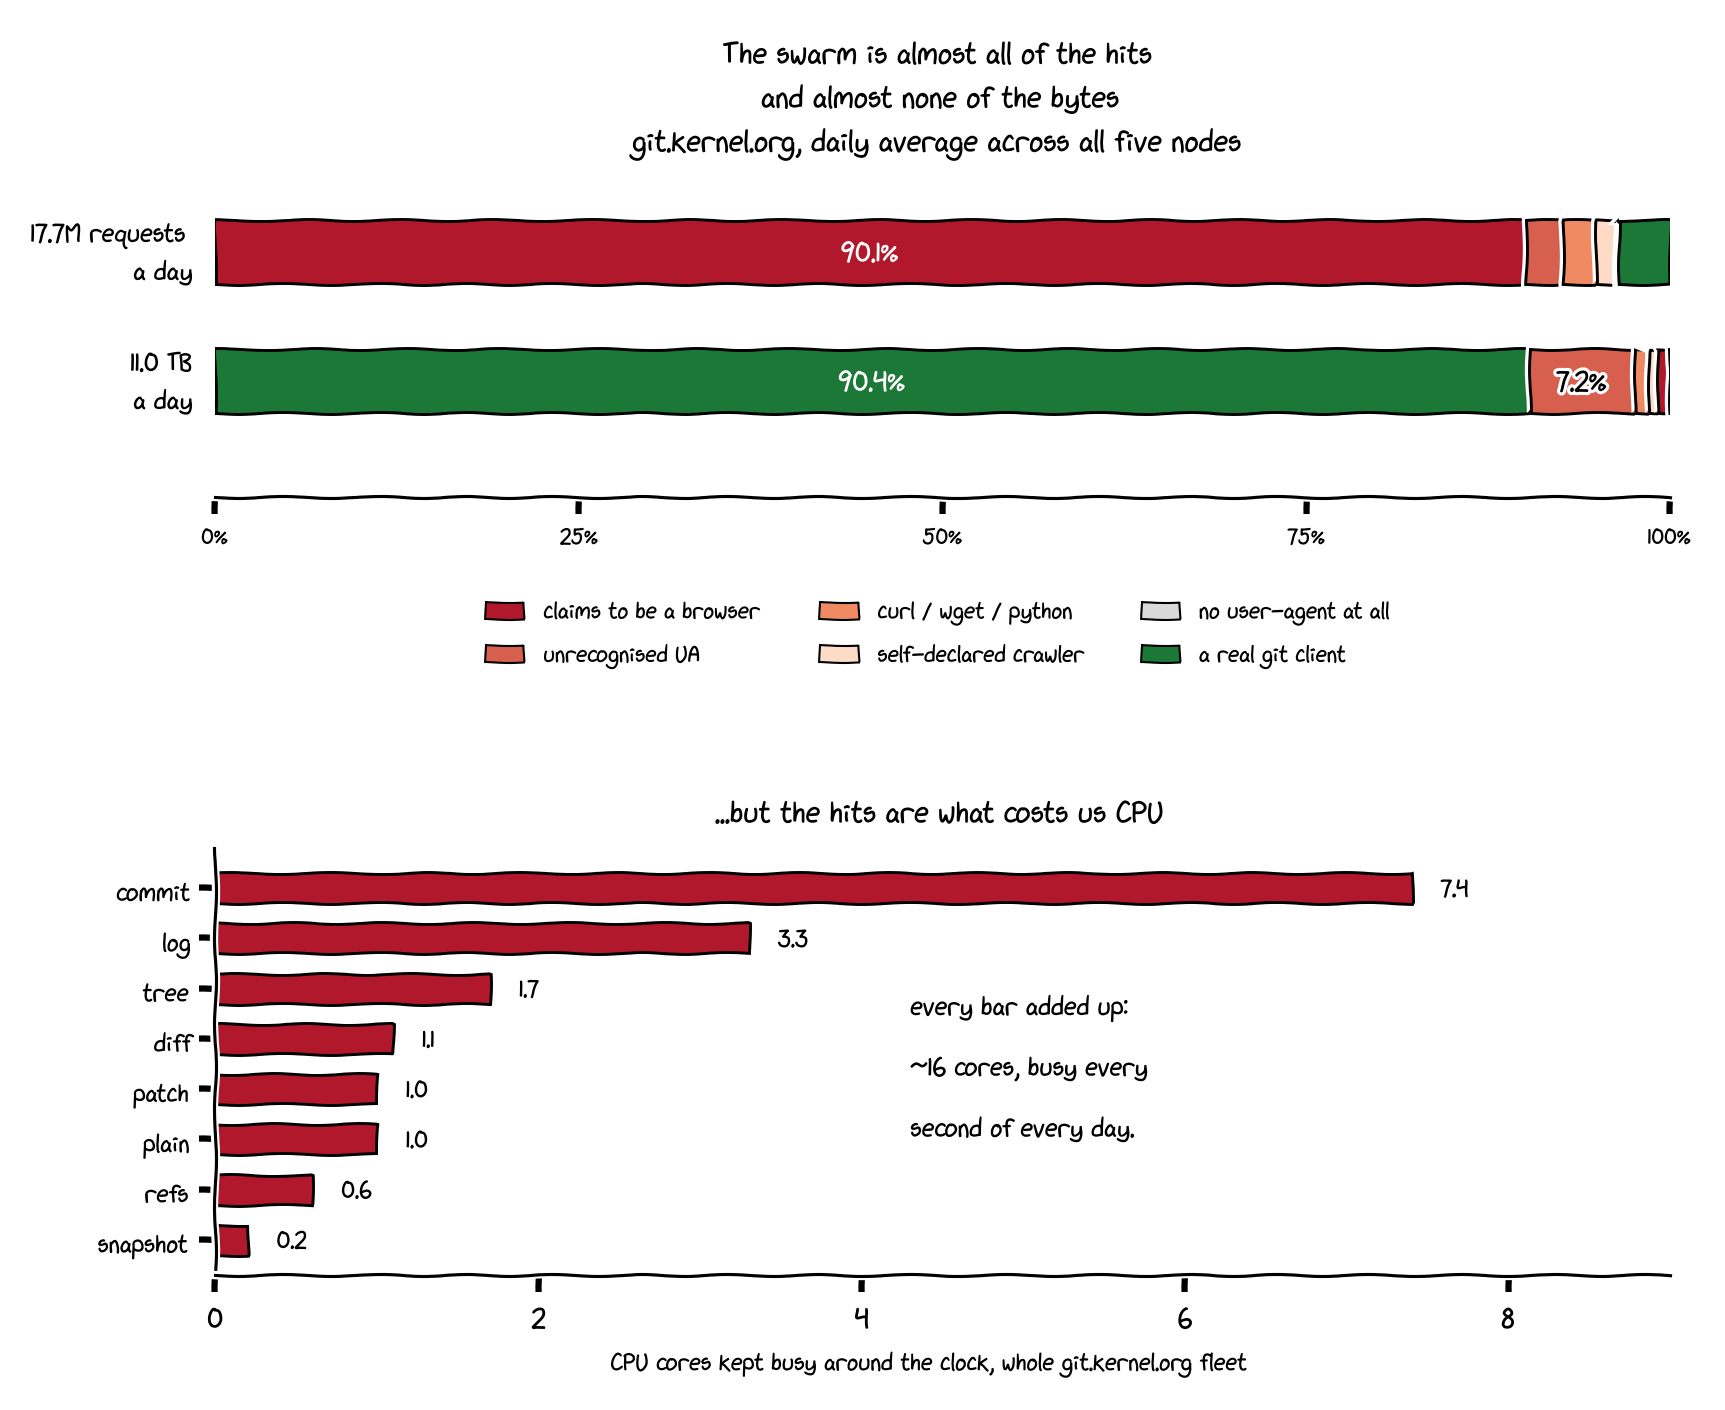
You've probably heard me complain about the “AI crawlers” before, but now I actually have some hard numbers I can put up to show their impact. In a few words, it's bad enough to create a constant “background radiation” of system load, permanently tying up a chunk of capacity spent on producing output that is only useful for a single purpose — feeding a learning model. TL;DR: we spend more CPU cycles rendering commits for scrapers than we spend on all other kinds of legitimate access, including git clones. At any one time, across 5 geo-distributed nodes, there are 14 CPU cores doing nothing but rendering git commits as html. Why is git.kernel.org “interesting” to crawlers Linux development happens in the open — from git repositories you can clone, to discussion archives you can follow in real time. To a large language model, this is a goldmine of learning data, because all of this is not only immediately available, but is easy to filter in order to guarantee pure unadulterated pre-AI content.…