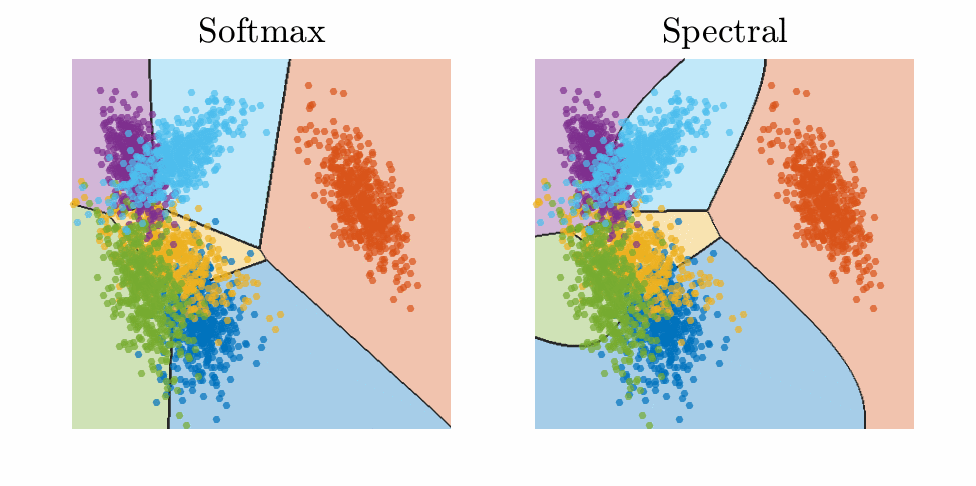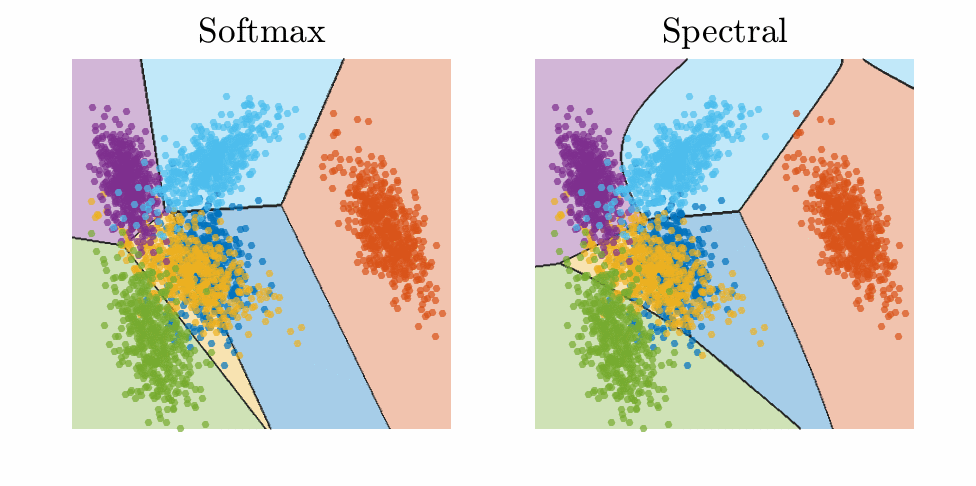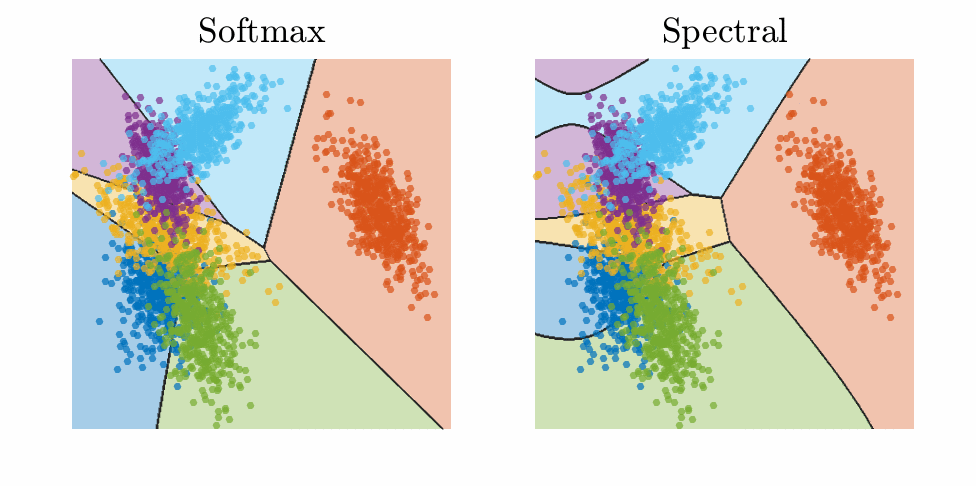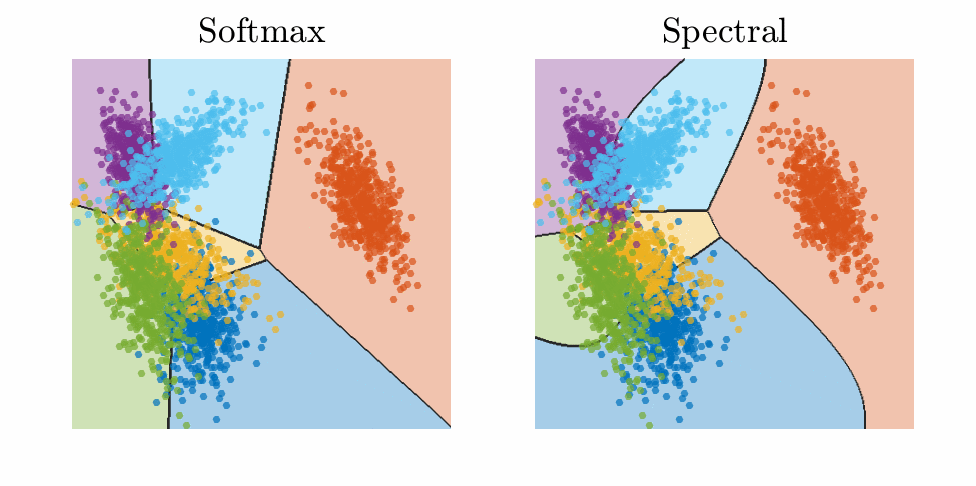
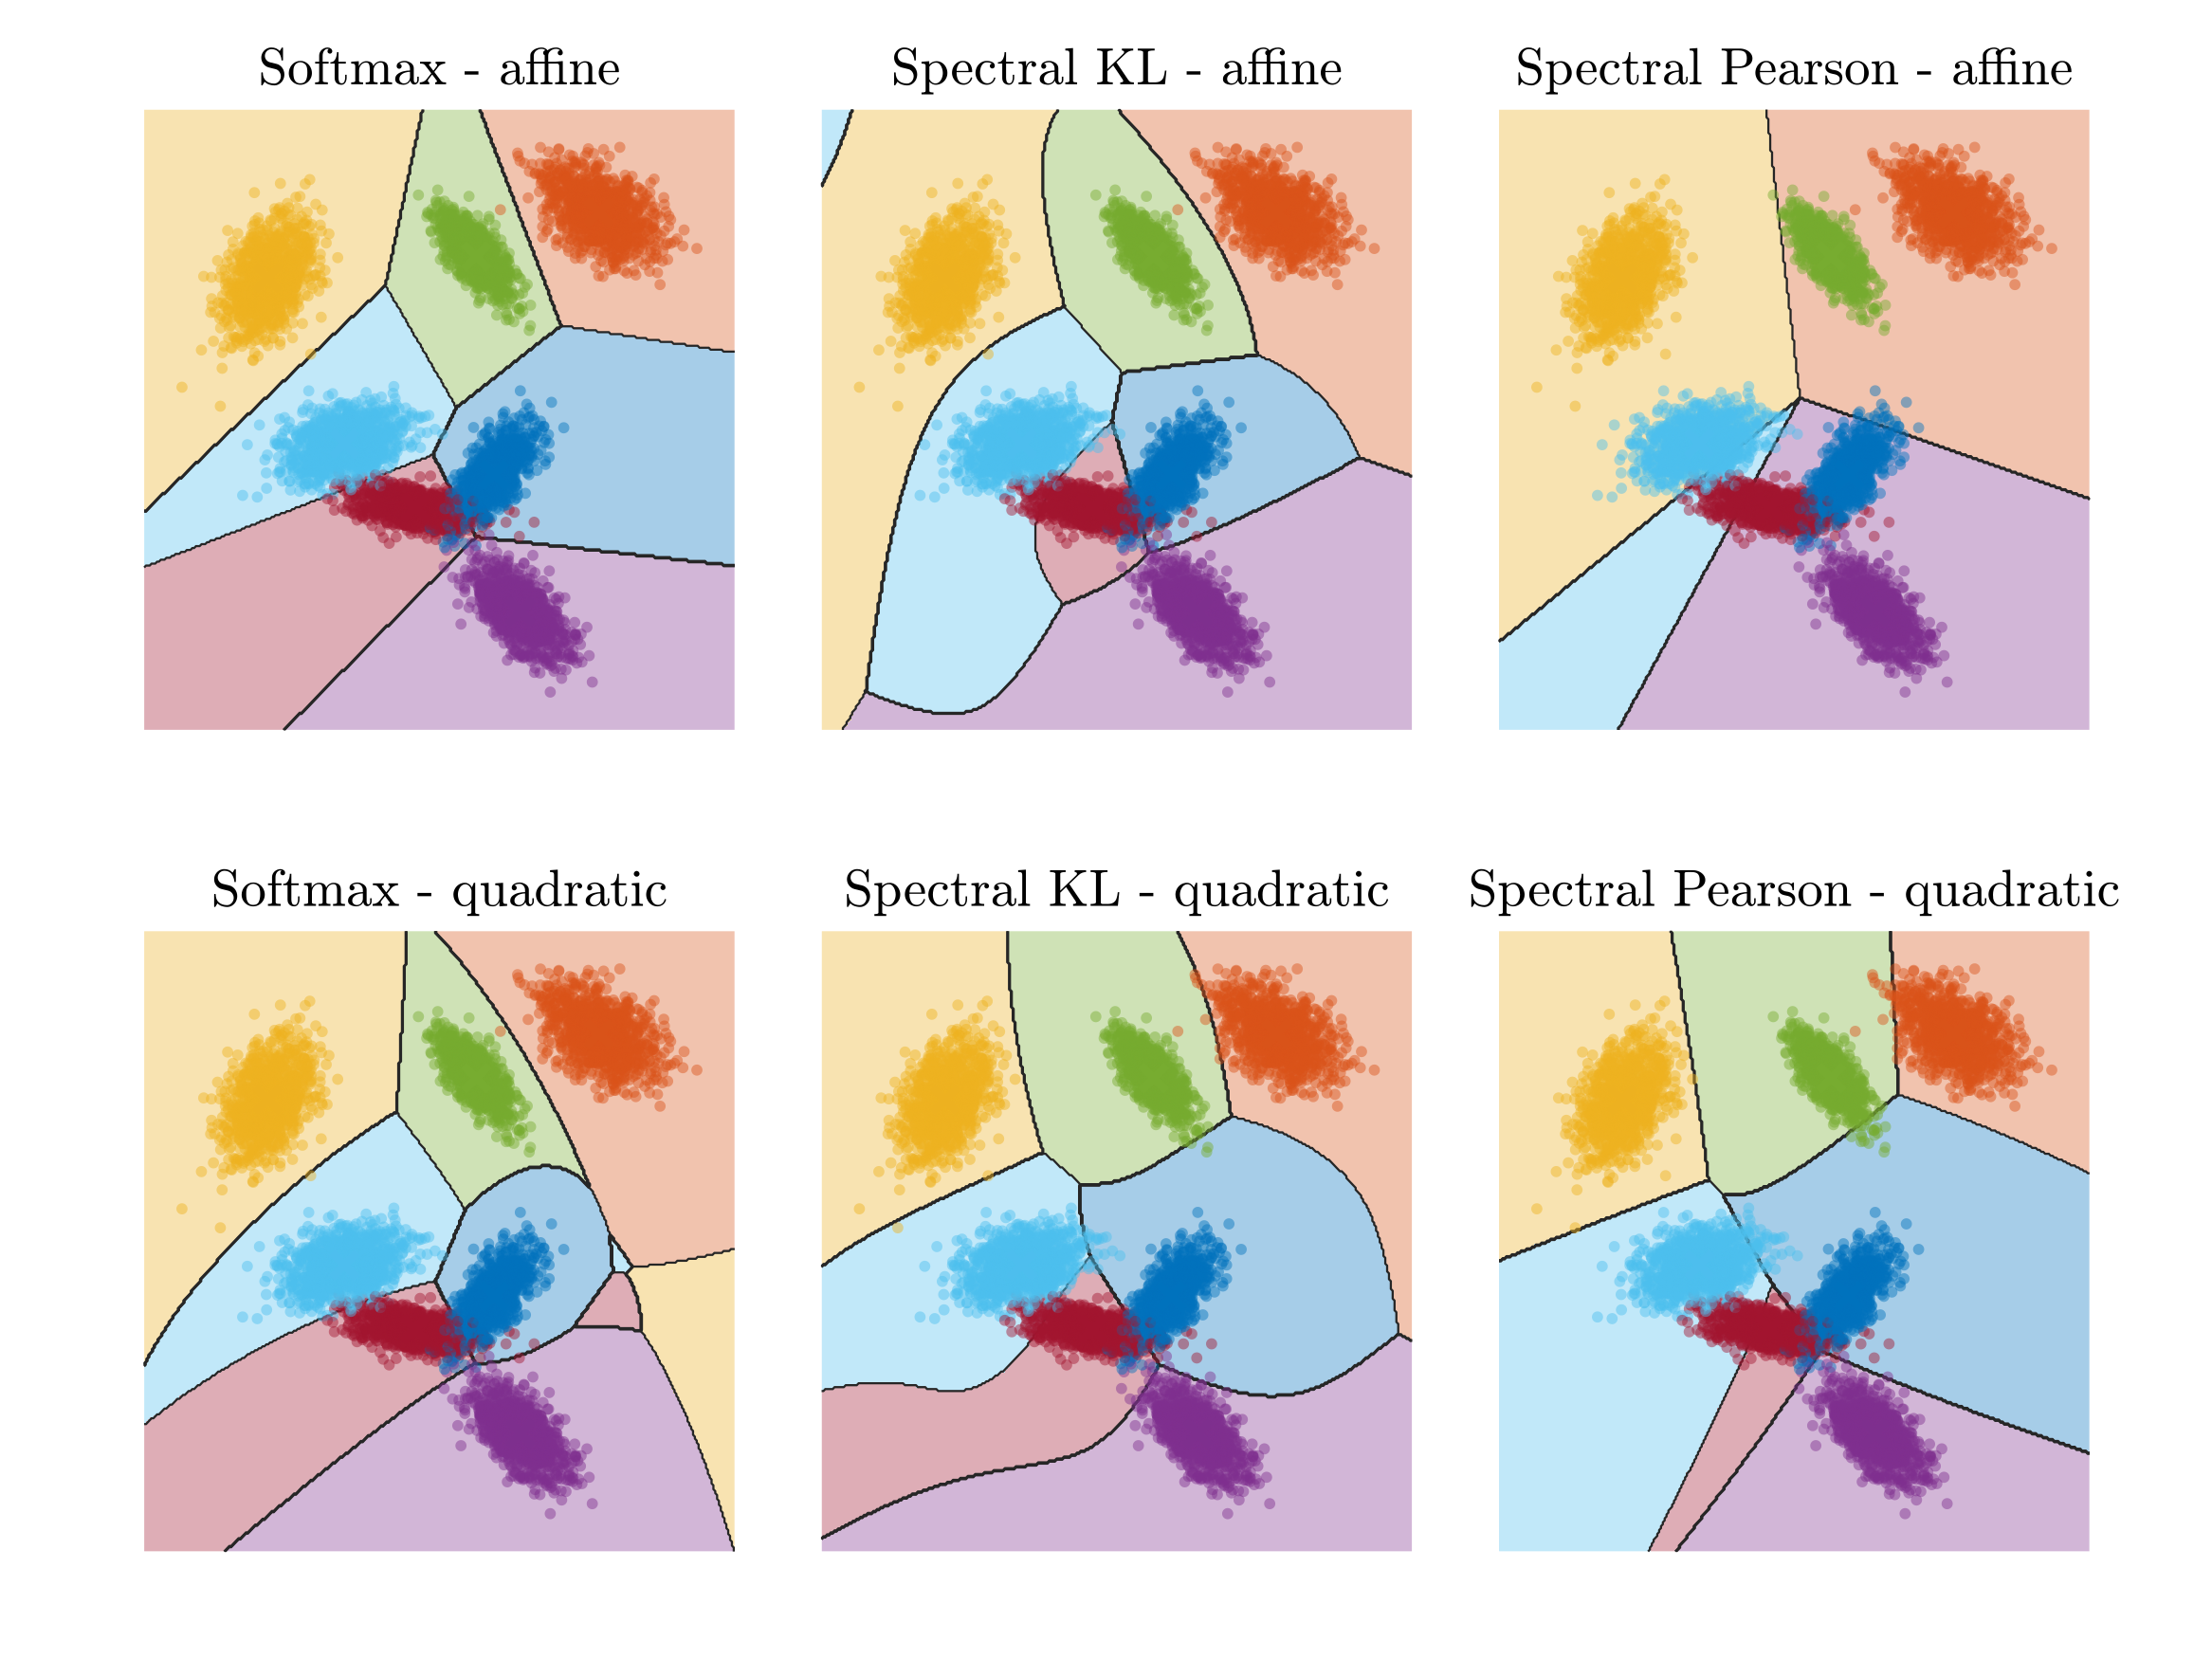
A common task in machine learning is to estimate or optimize “log-sum-exp” functions with (potentially continuously) many terms such as $$ \log \Big( \int_{\mathcal{X}} e^{v(x)} dq(x) \Big),$$ where \(v: \mathcal{X} \to \mathbb{R}\) is some potential function, and \(q\) is a probability distribution on the set \(\mathcal{X}\). This has many applications throughout data science, often through the normalization of probabilistic models , but also as a smooth approximation to the maximum , in transformers through its derivatives, or in reinforcement learning when using entropy regularization [ 19 ]. Sometimes the set \(\mathcal{X}\) is finite (potentially big) and the integral can be done by explicit summing, but often an exact computation is infeasible, and sampling from the probability distribution \(q\) is used instead. The key difficulty comes from the variance of such estimates, in particular when \(v\) takes large values.…