I’ve been working with local models since they came out, and finally, they’re surprisingly good now.
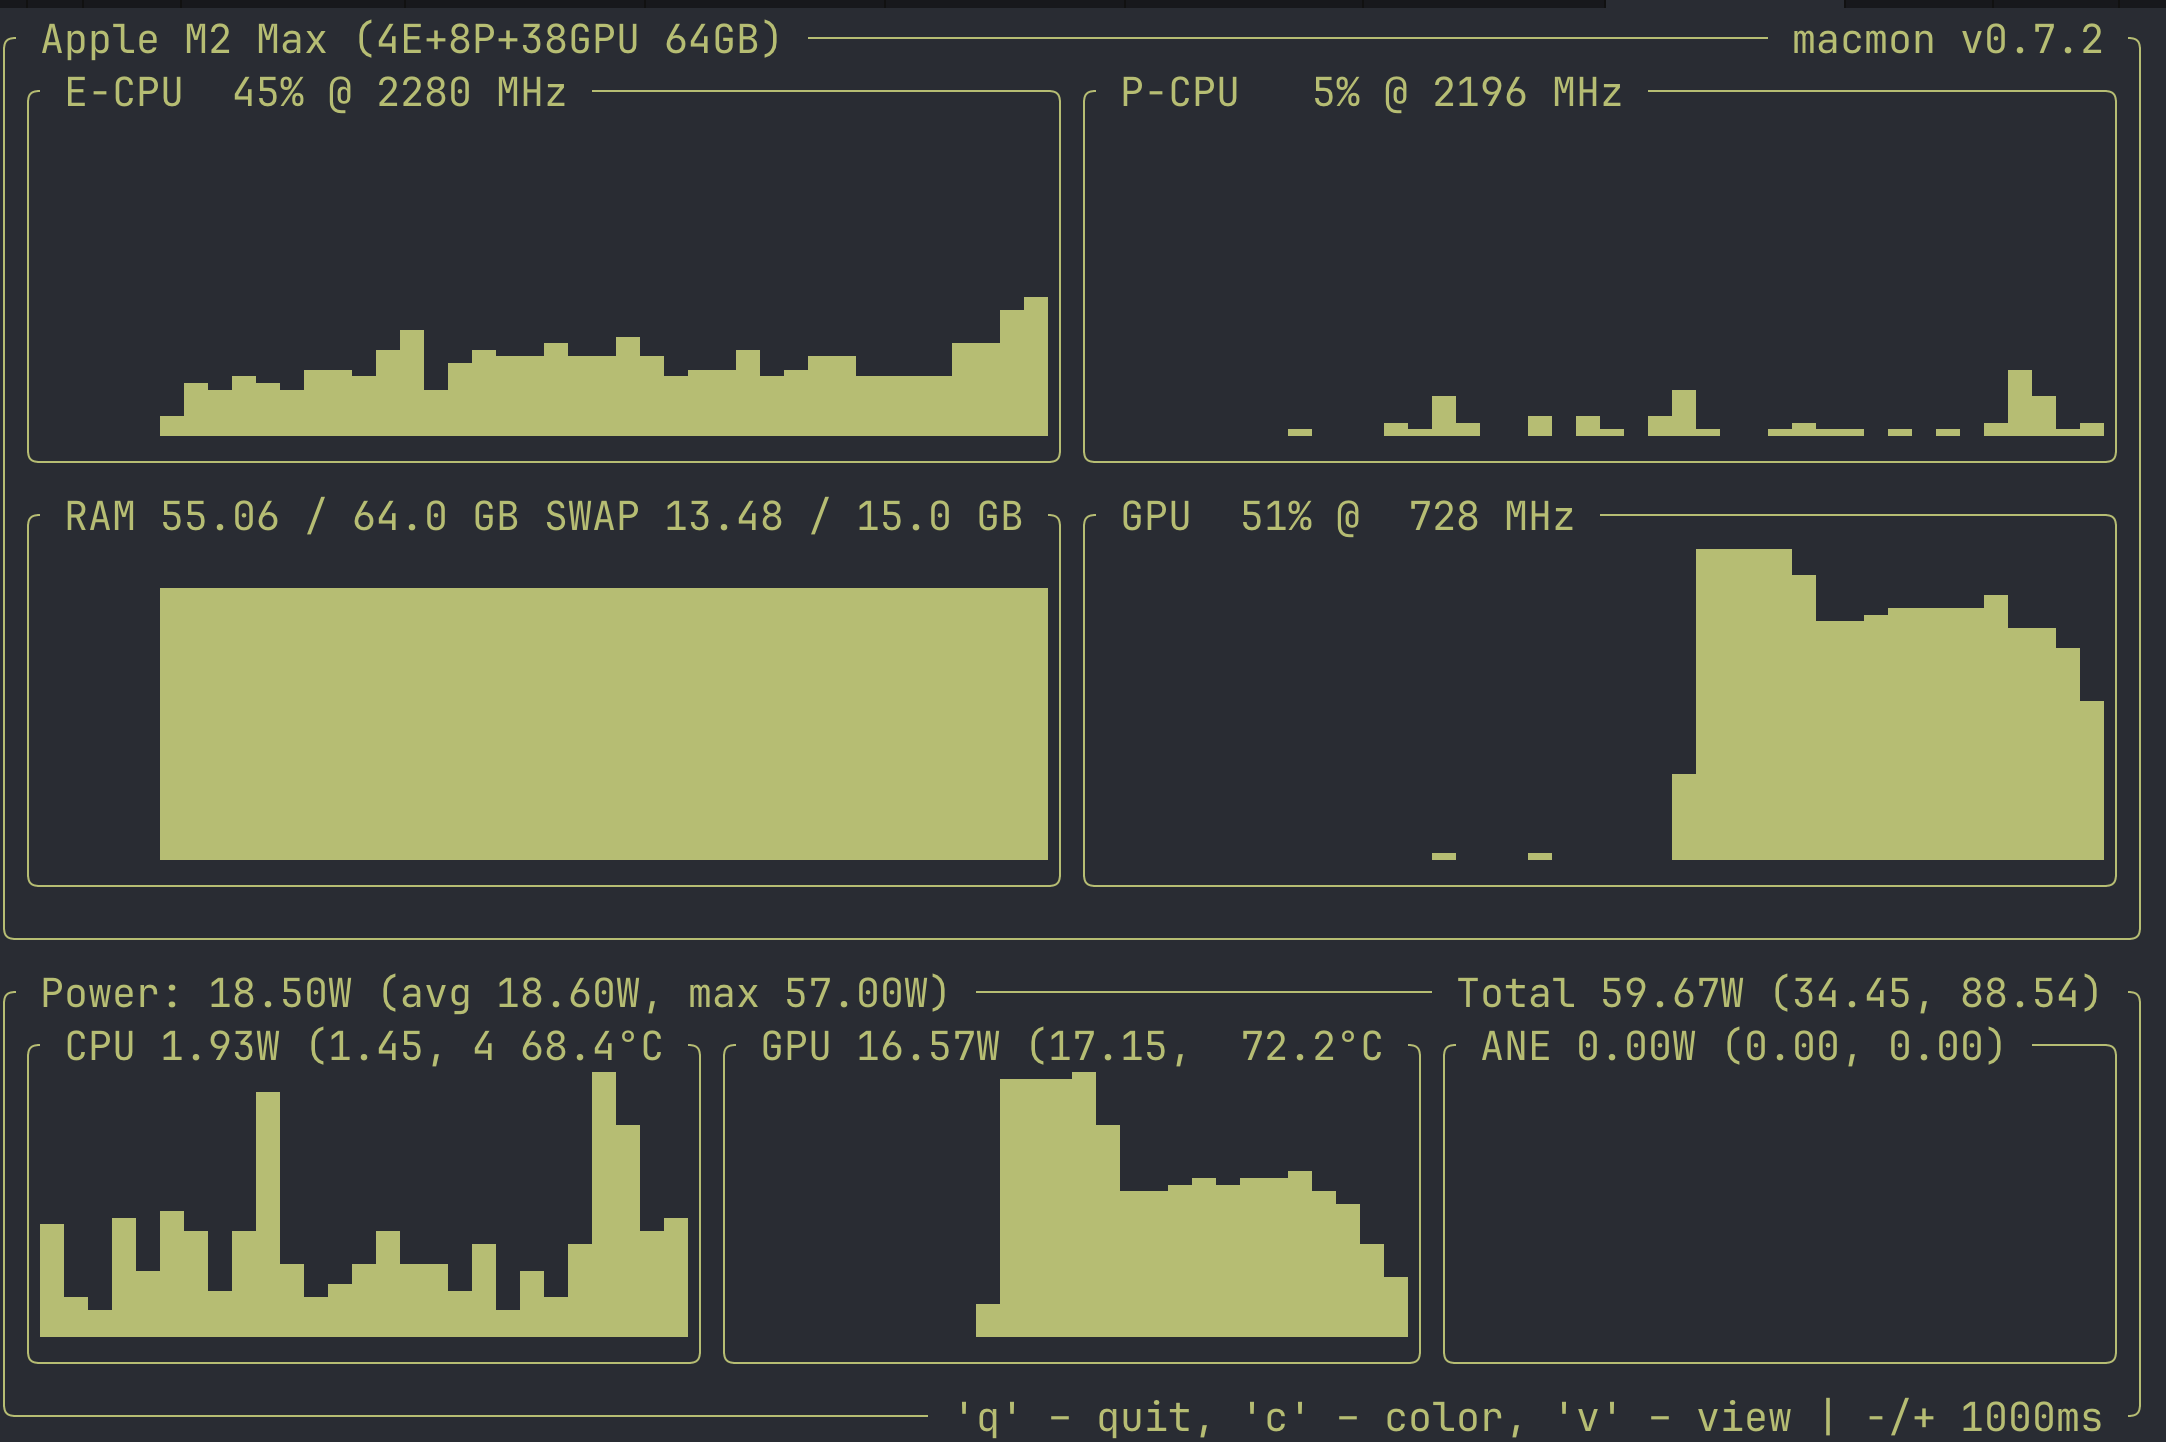
I have a 2022 M2 Mac with 64 GB RAM and 1TB storage and I’ve used
Mistral 7B
Gemma 3
OpenAI OSS-20B
Qwen 3 MOE , as well as a number of other Qwen variants like Qwen 2.5 Coder
across a lot of different system setups like
raw llama.cpp with Open WebUI
llama-cpp-python
Ollama
llamafiles and
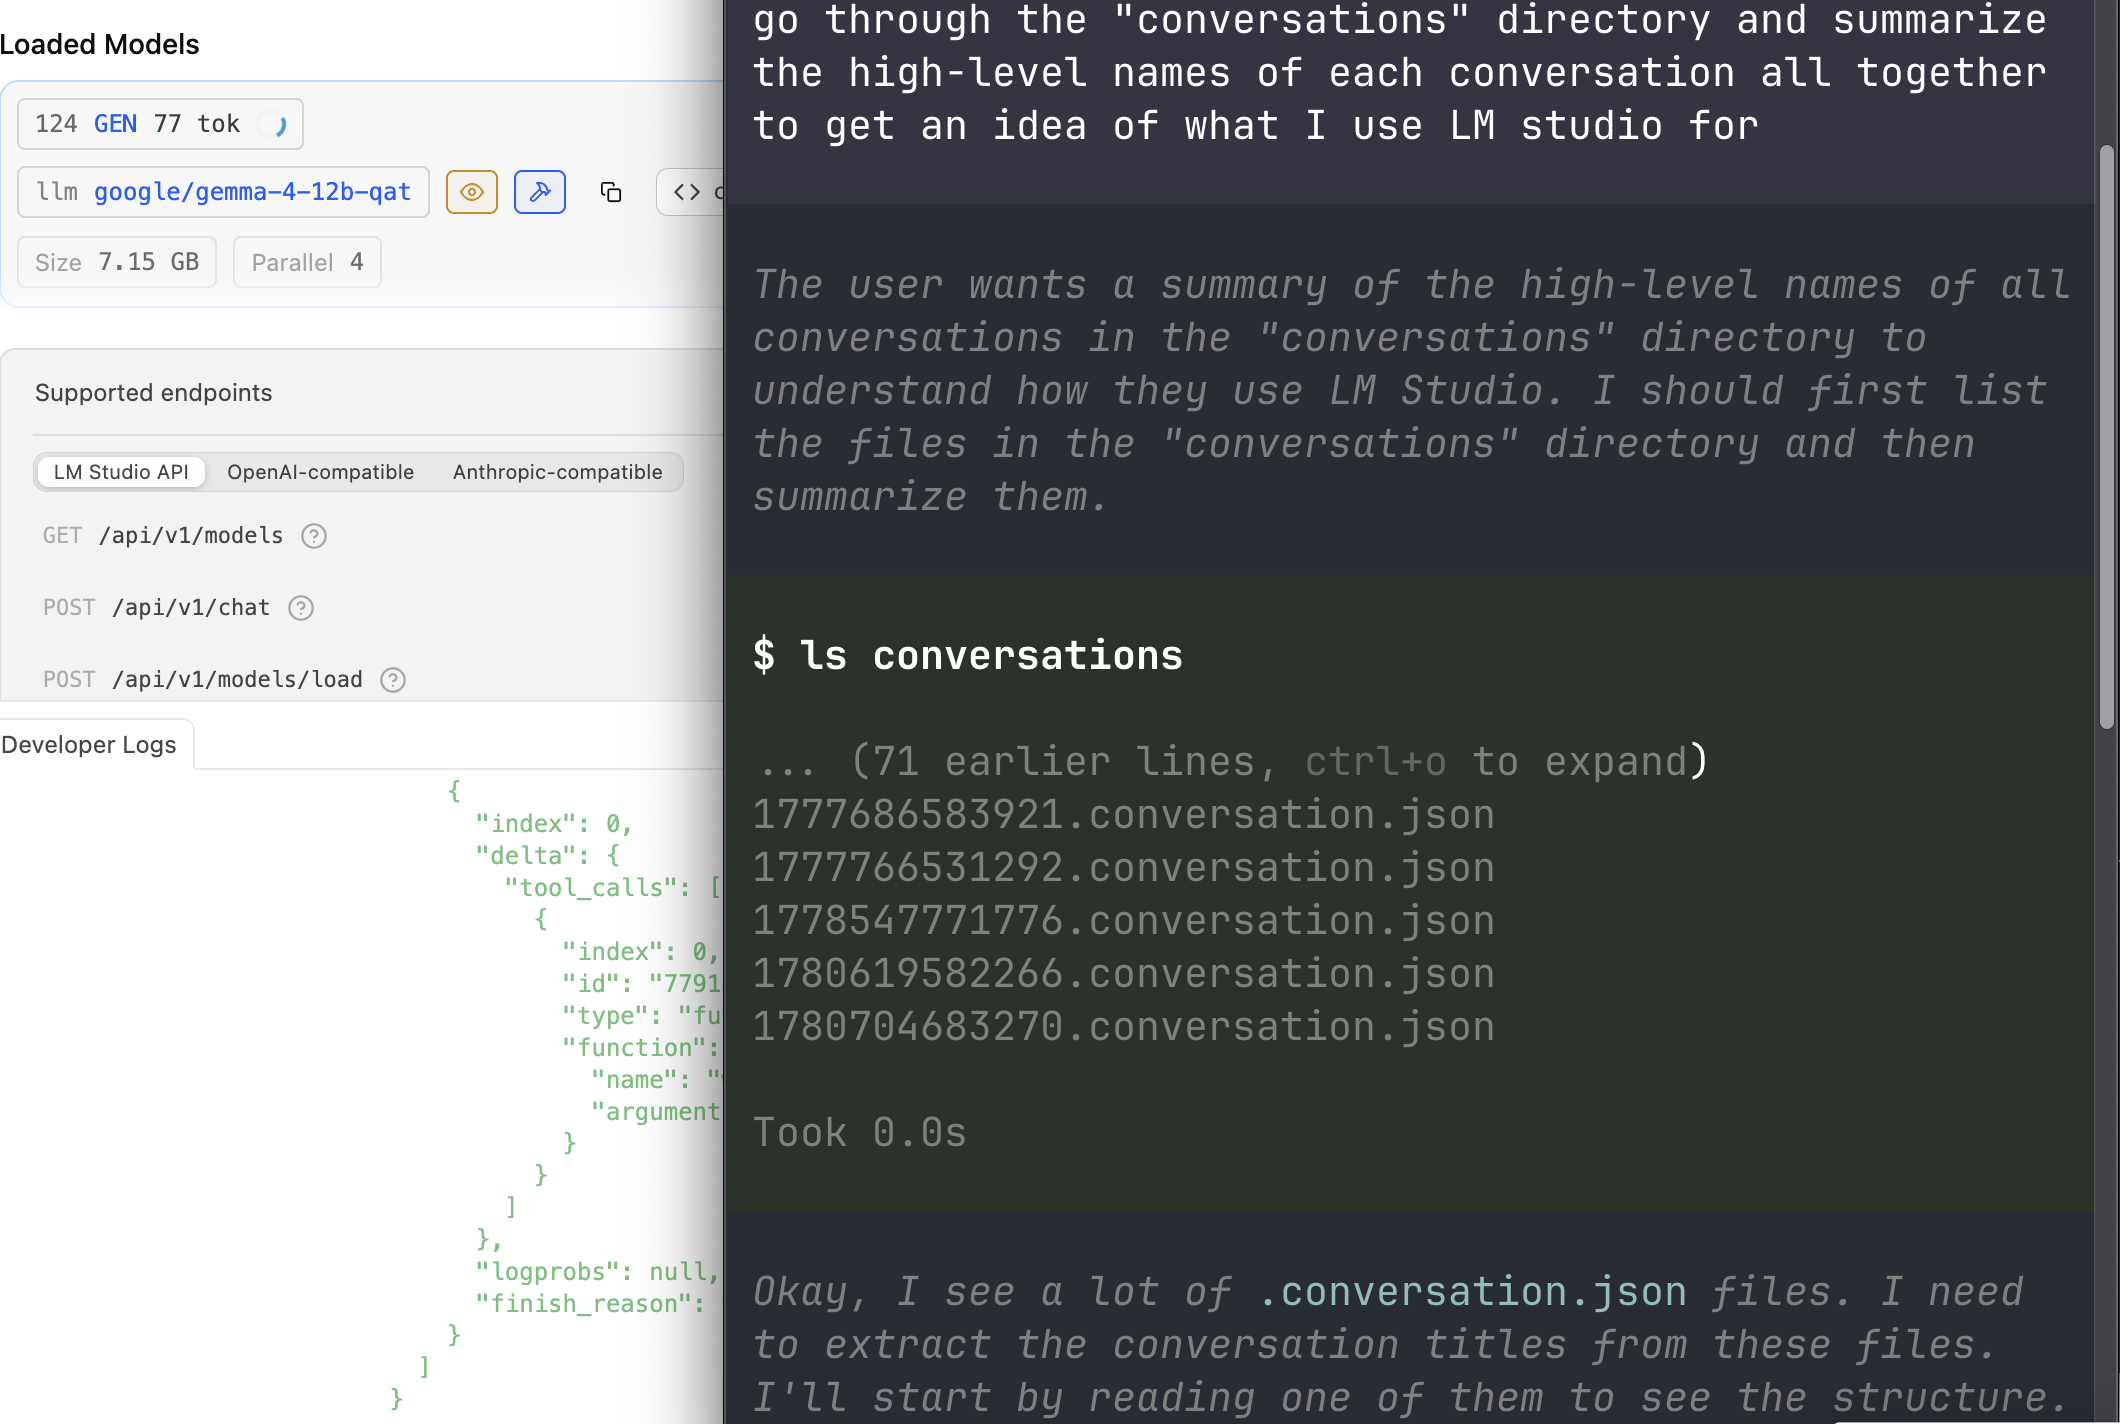
LM Studio
Where are local models now?
Early on, models were slow, hard to use, and just not that accurate for most programming tasks. The idea that local models were severely lagging behind was largely true until, for me, the release of GPT-OSS.…