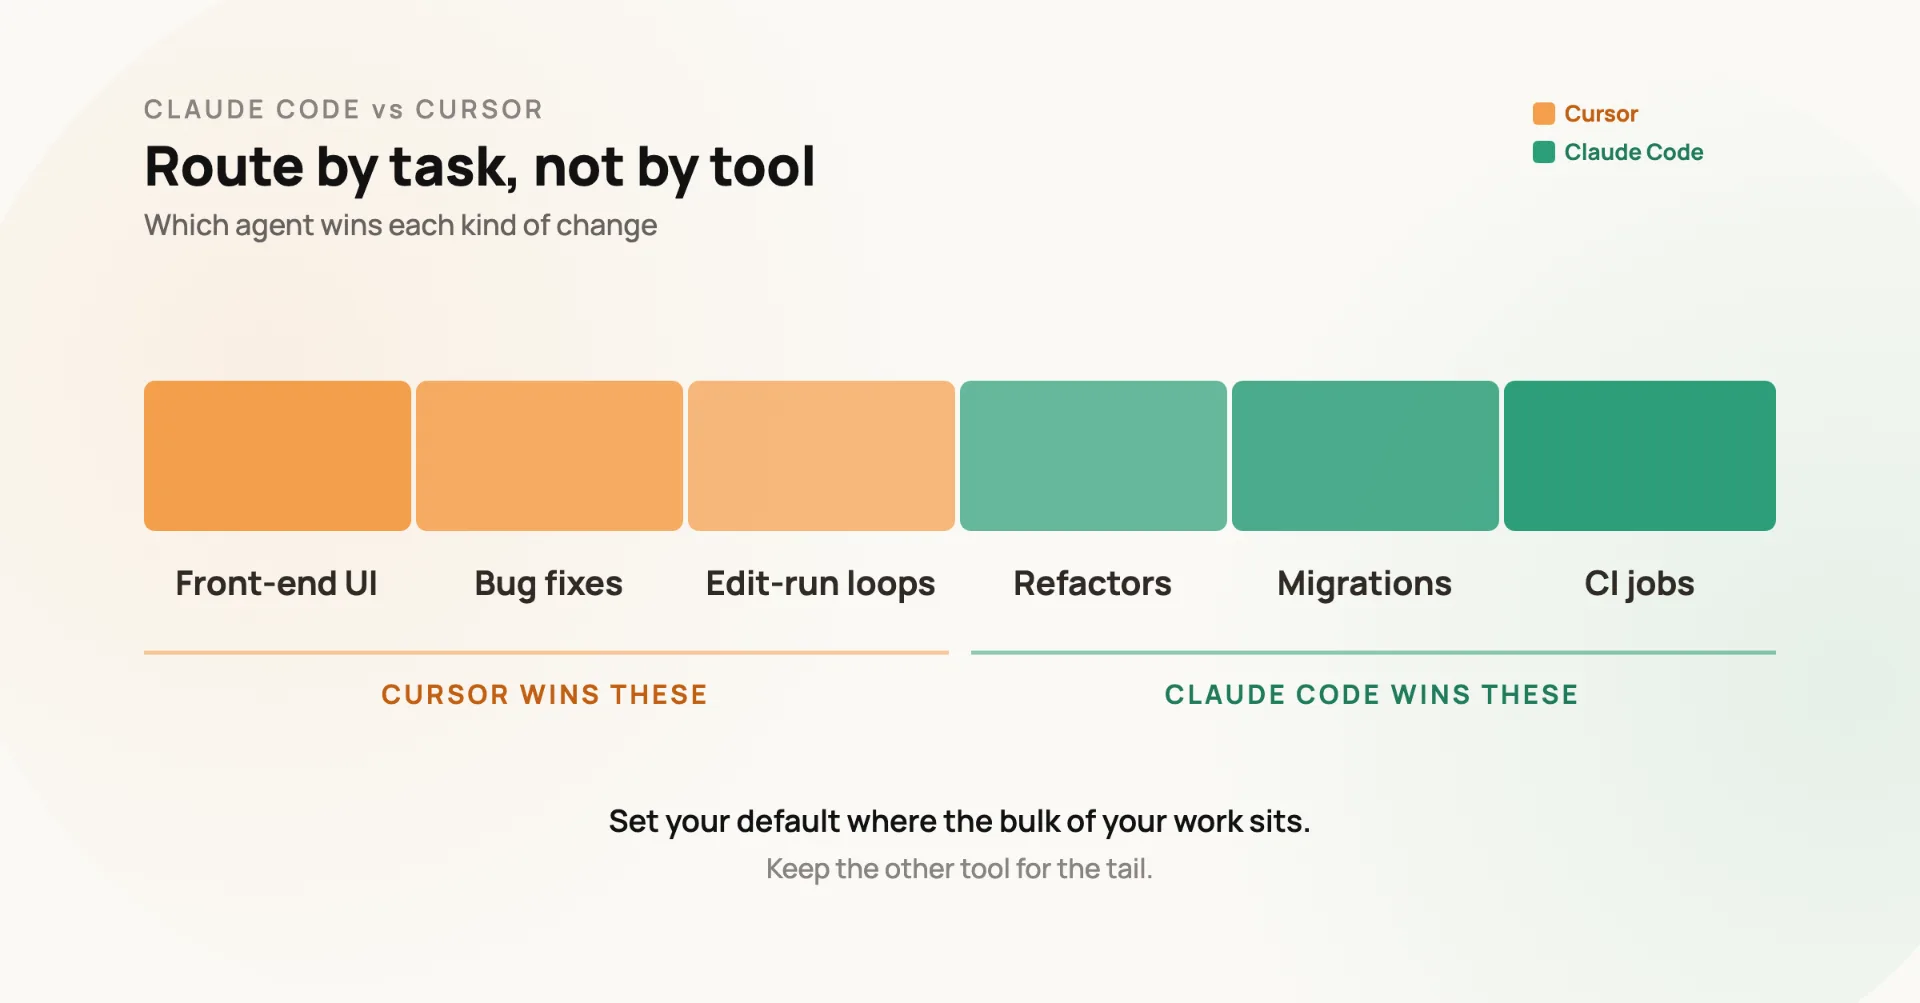
If you search "Claude Code vs Cursor," you get a wall of feature tables. Tab autocomplete versus terminal agents. Multi-model versus Claude-only. A column of green checkmarks on each side, and a conclusion that almost always lands on "it depends, most teams use both."
All of that is true, and almost none of it helps you decide. I noticed it most clearly in the benchmarks. One popular comparison reports that Claude Code completed a task in about 33,000 tokens while Cursor burned through 188,000 on the same work. Another comparison reports the opposite, Cursor at roughly 33,000 and Claude Code at 188,000. Both numbers are real. Both were measured. And the fact that they contradict each other by the same multiple, in opposite directions, tells you everything about why a single benchmark cannot answer this question.
Token cost on a coding task is not a property of the tool. It is a property of the task, the codebase, and how the human drove the agent. Change any of those and the winner flips.…