Published Nov 17, 2026, 12:00 PM EST
Maker, meme-r, and unabashed geek, Joe has been writing about technology since starting his career in 2018 at KnowTechie. He's covered everything from Apple to apps and crowdfunding and loves getting to the bottom of complicated topics. In that time, he's also written for SlashGear and numerous corporate clients before finding his home at XDA in the spring of 2023.
He was the kid who took apart every toy to see how it worked, even if it didn't exactly go back together afterward. That's given him a solid background for explaining how complex systems work together, and he promises he's gotten better at the putting things back together stage since then.
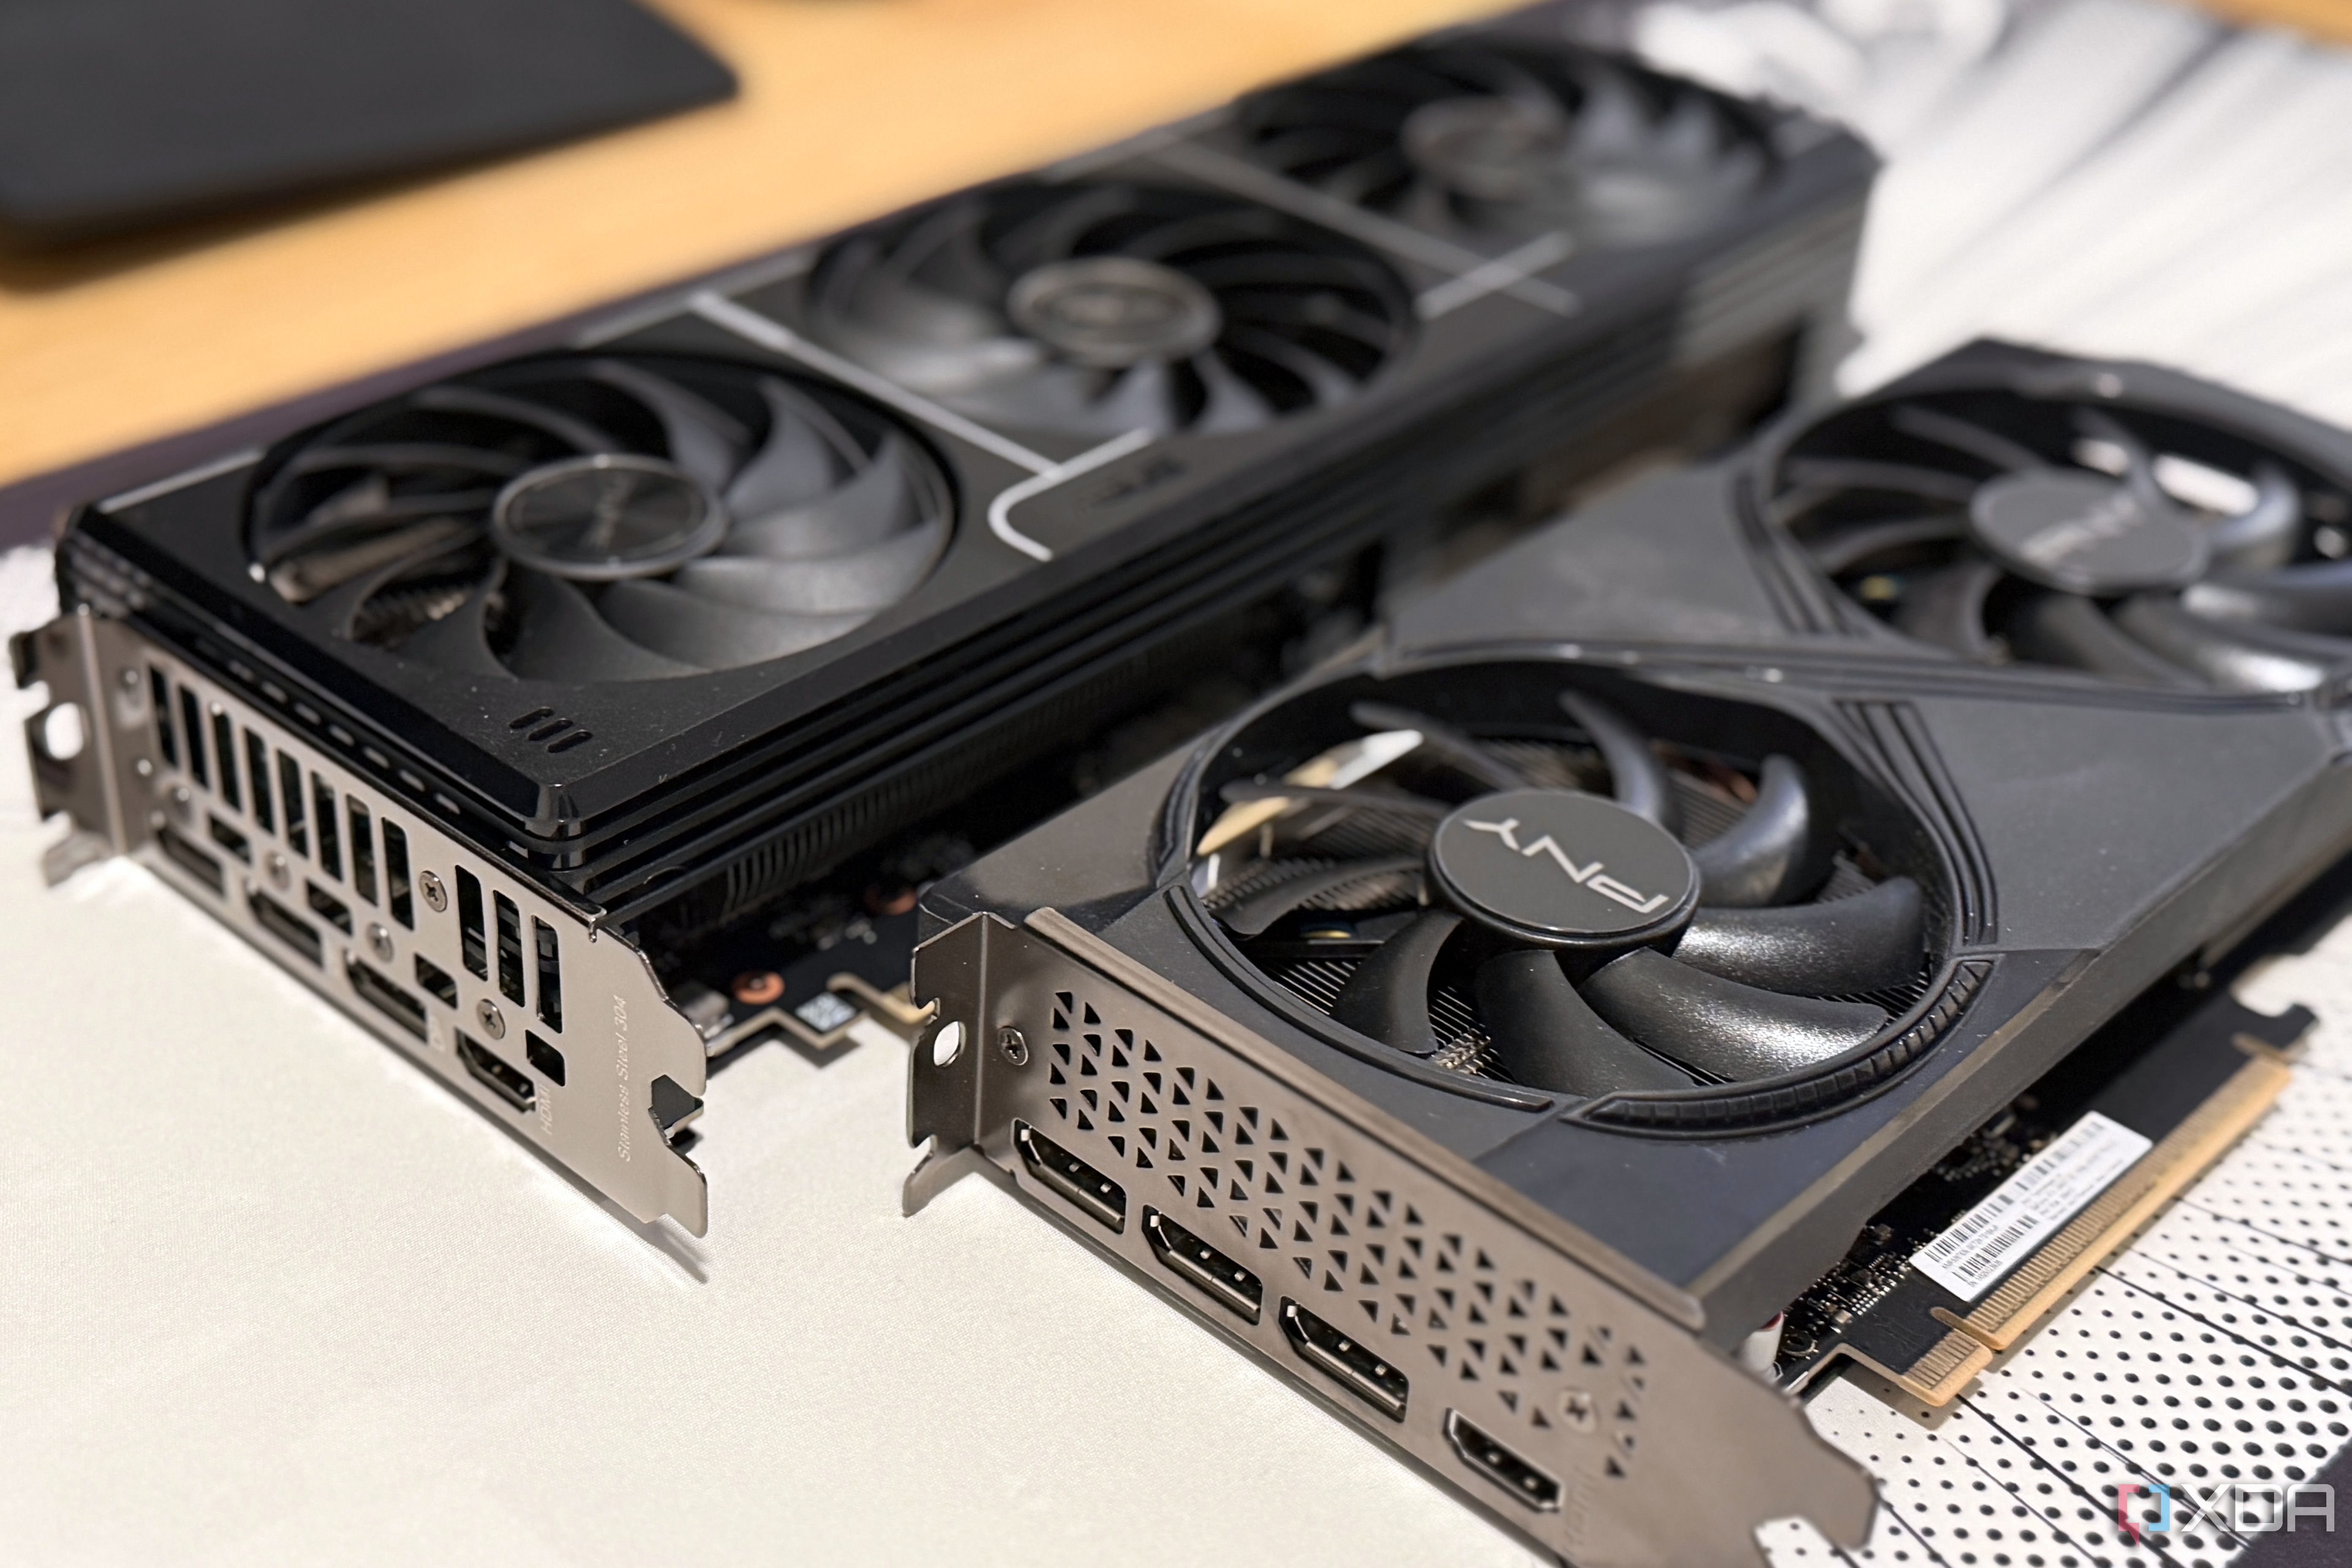
Let's face it, the standard advice for running local LLMs is to buy the biggest single graphics card you can afford. Local AI is more accessible than ever, but it comes with one major GPU-sized caveat : video memory decides which models you can load at all.…