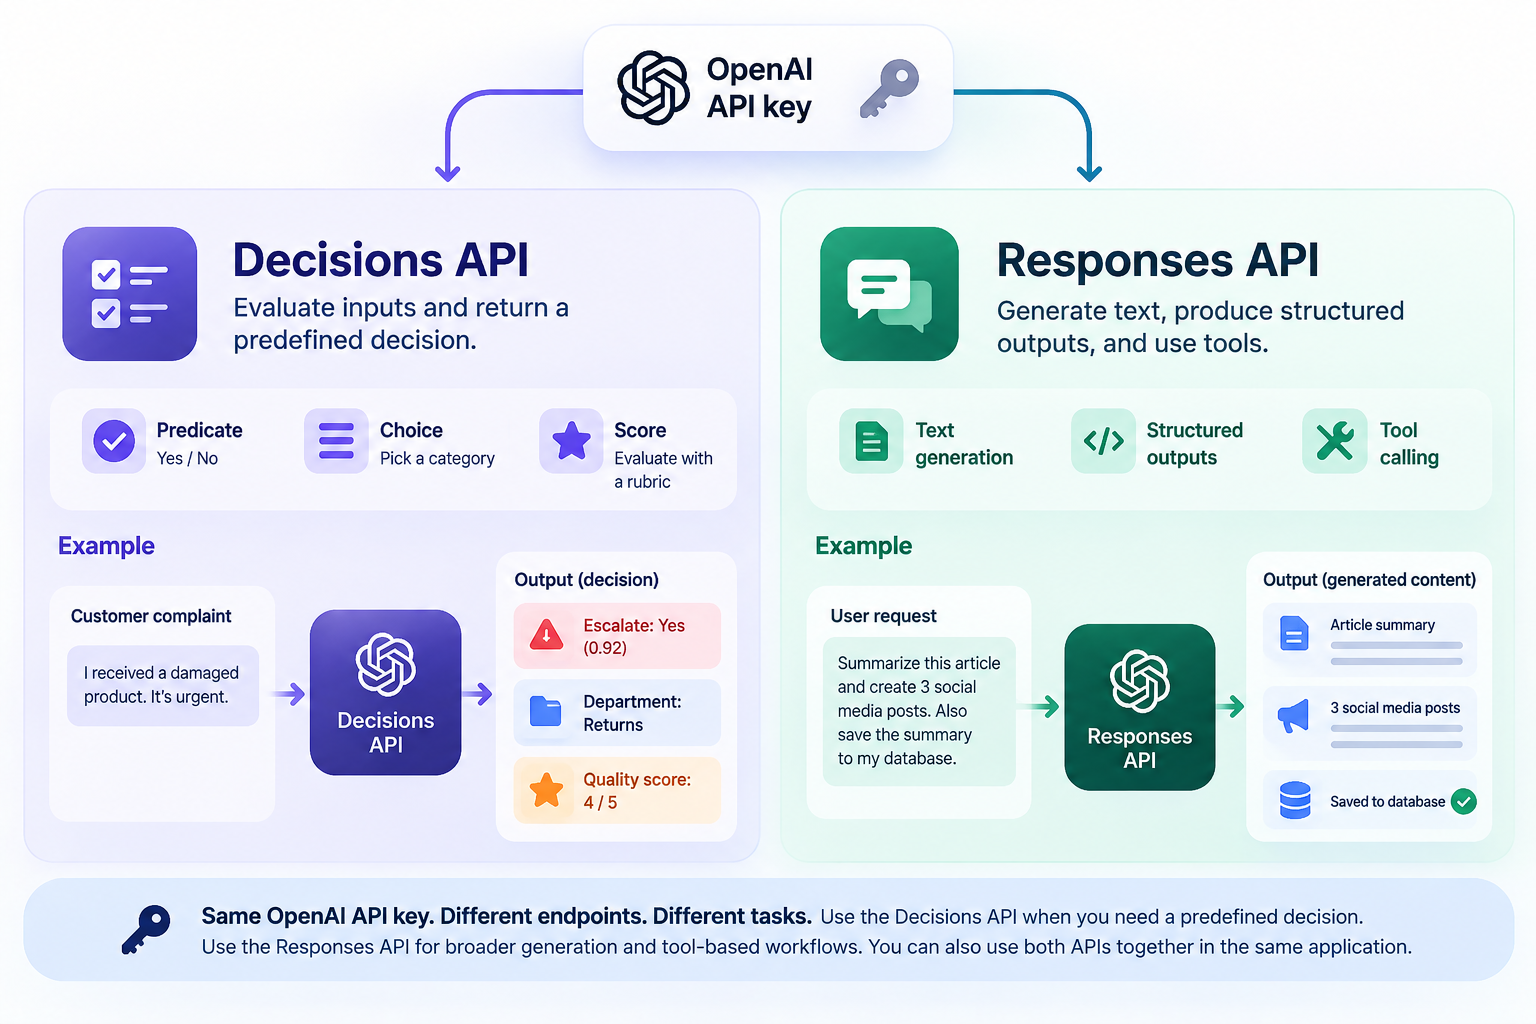
Imagine building an AI agent that has to decide whether a customer complaint needs human intervention, which department should handle a query, or whether a submitted delivery photo is valid. Getting these decisions right matters. A false positive can trigger an unnecessary escalation, while a false negative can let a genuine issue slip through.
Traditionally, developers have had to build classification rules, confidence thresholds, and evaluation pipelines around their LLMs to handle such decisions reliably. Newer approaches, like Jev , focus on making model decisions more structured by returning fixed answers with confidence scores instead of open-ended responses.
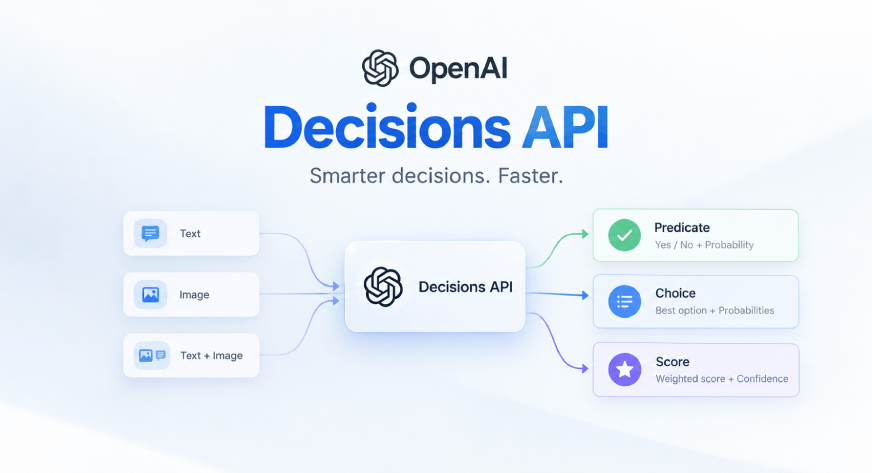
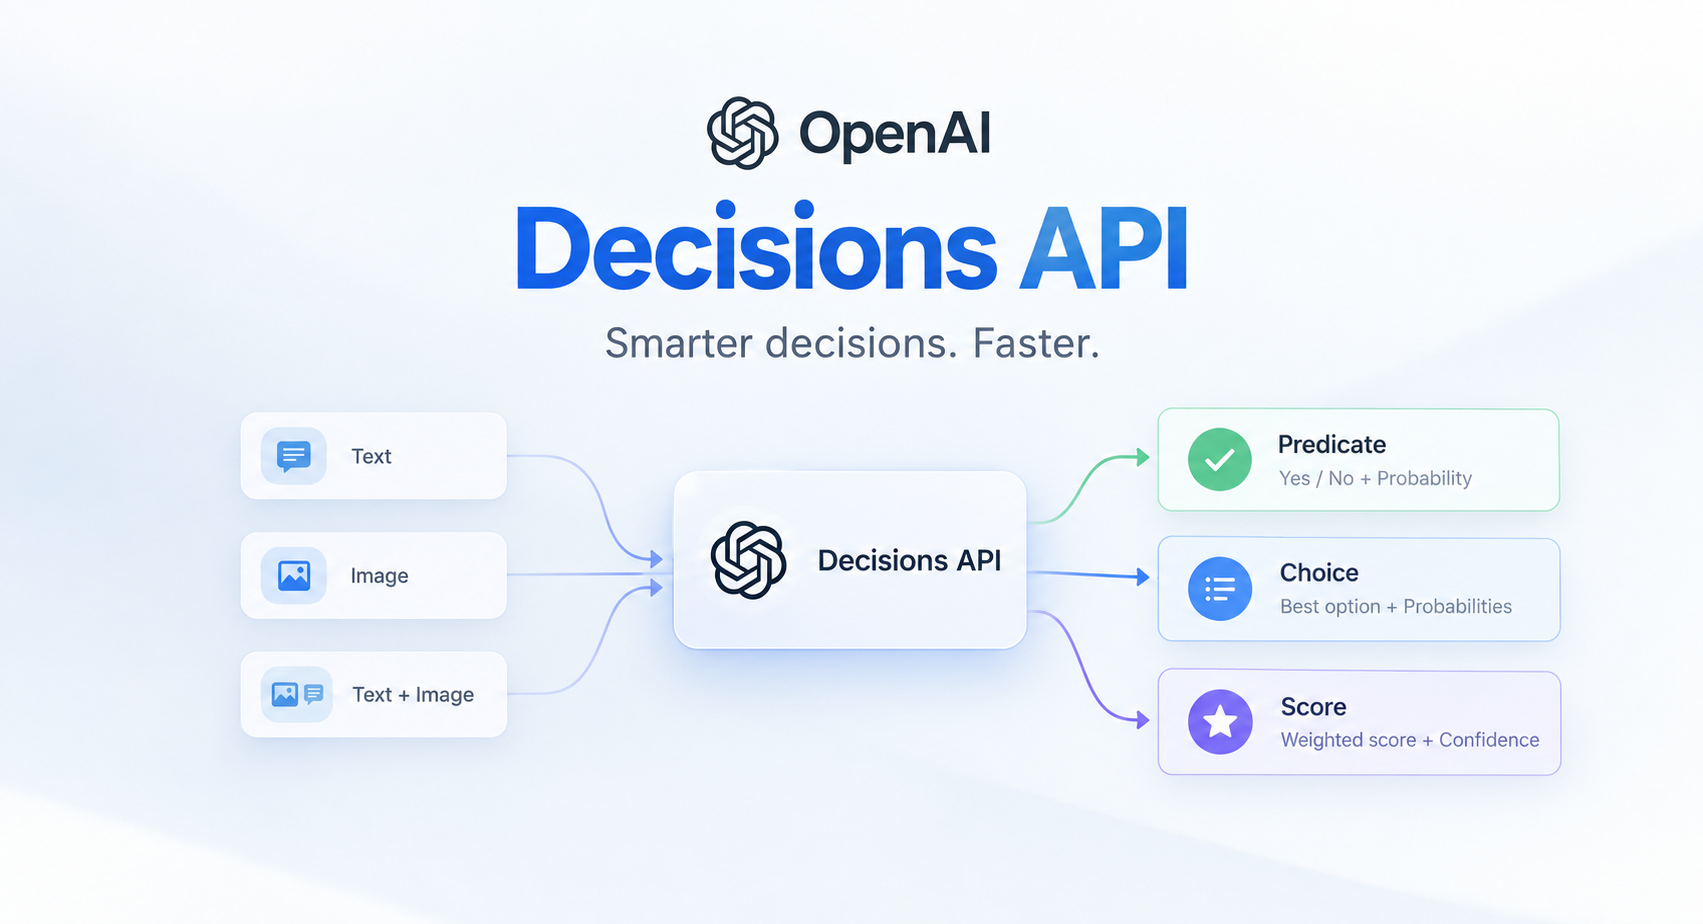
OpenAI is now bringing a similar idea to its API with the Decisions API. Rather than using a general-purpose response for every task, developers can define what the model needs to evaluate and whether it should return a probability, choose from predefined options, or assign a score against ordered levels.…