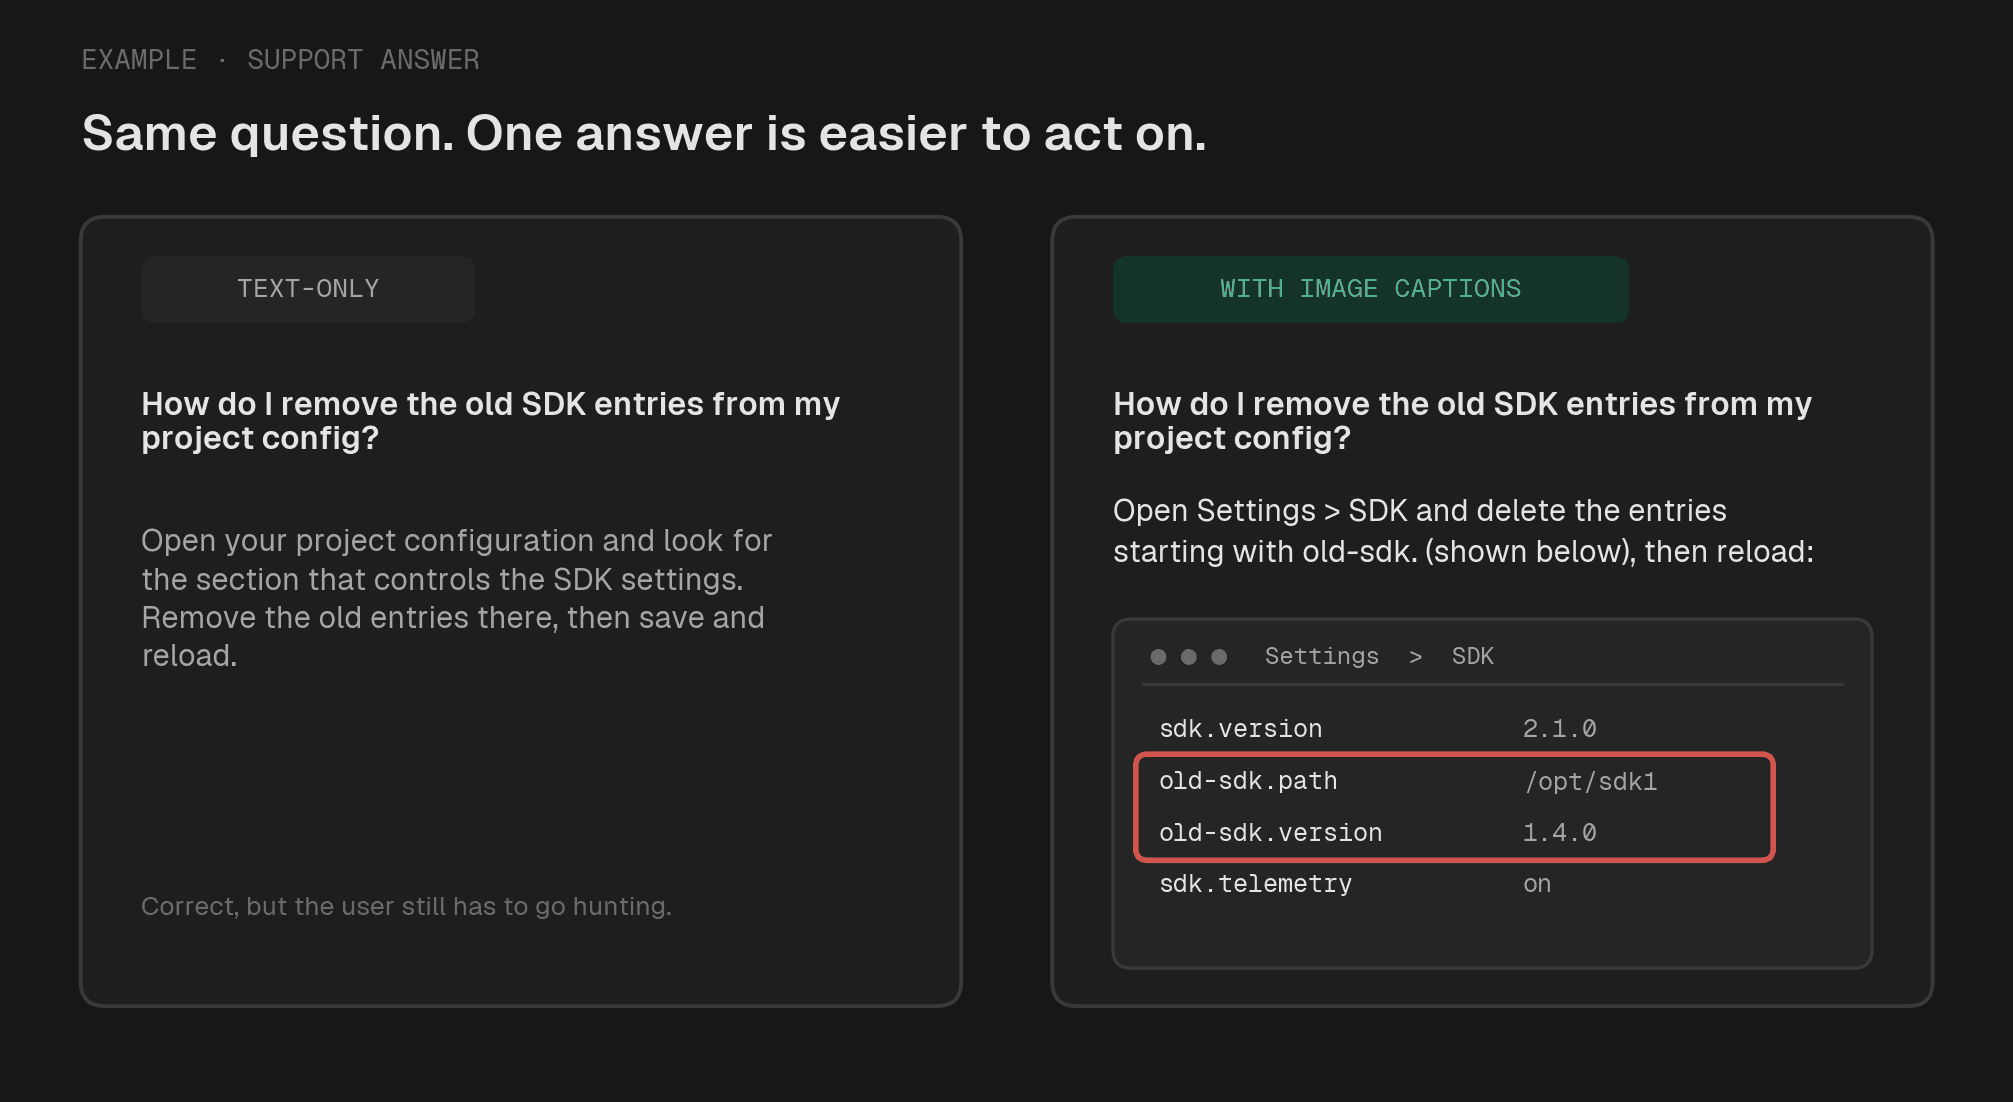
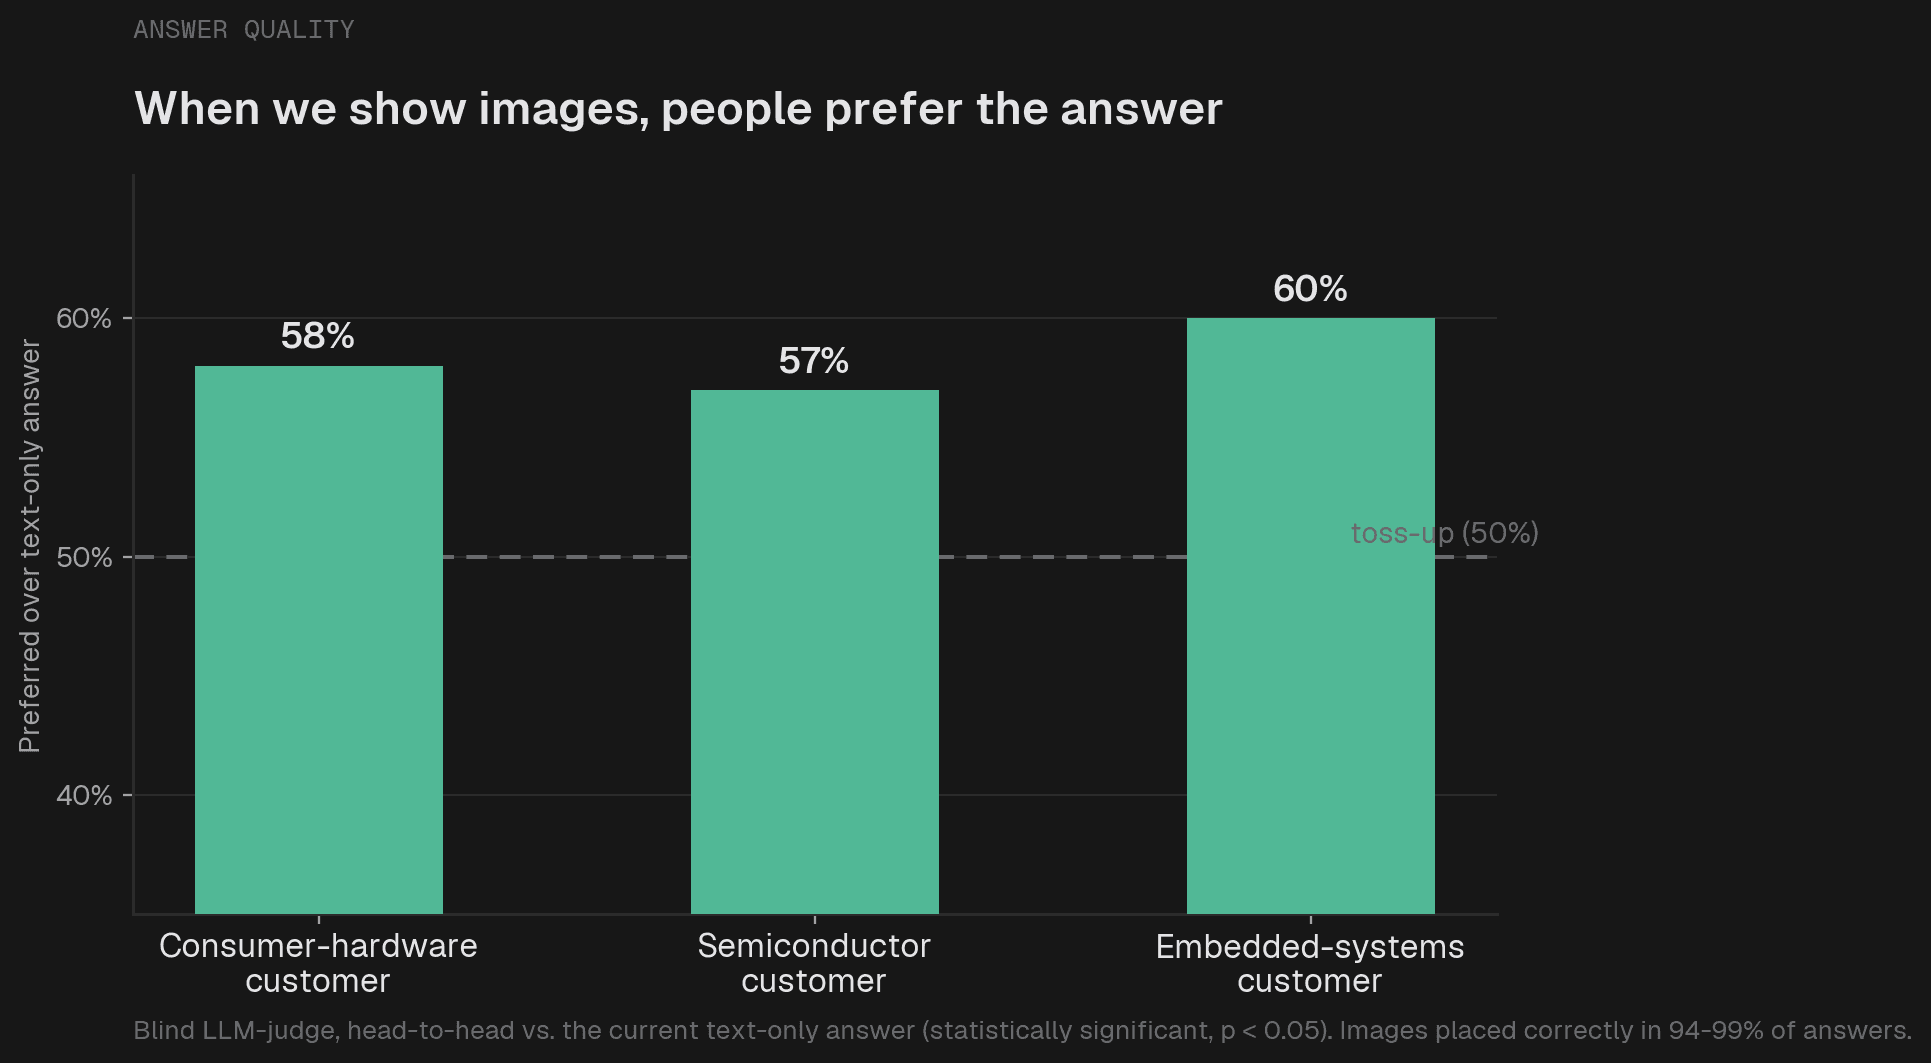
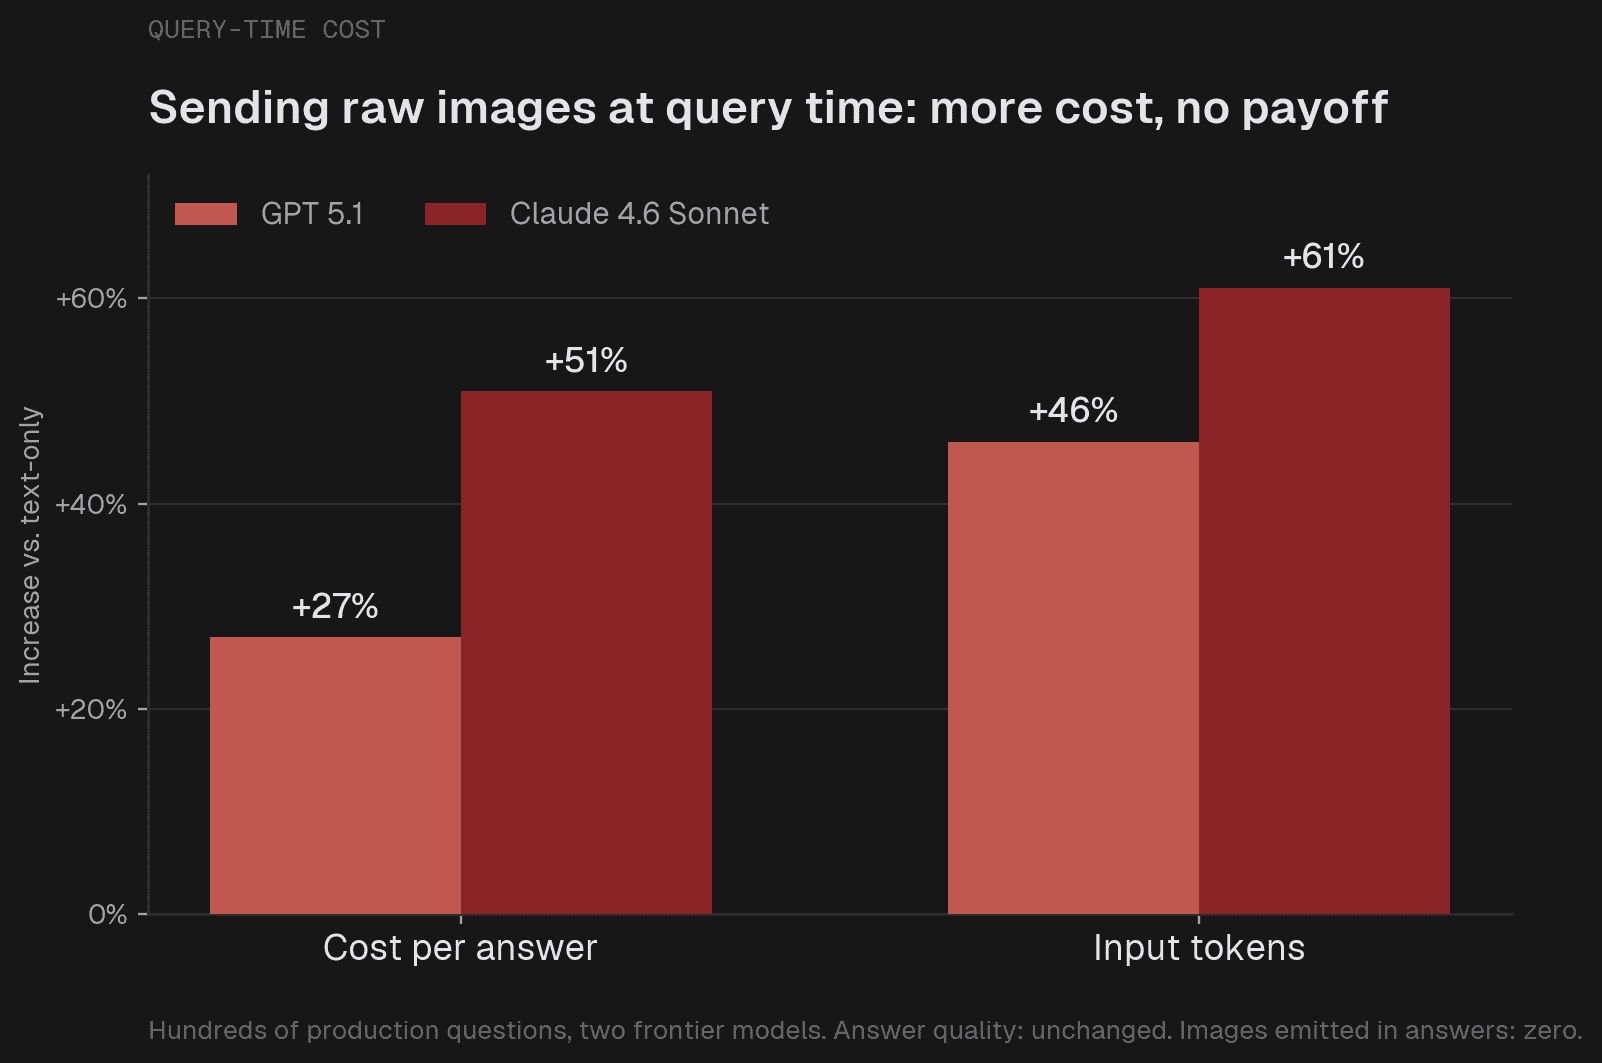
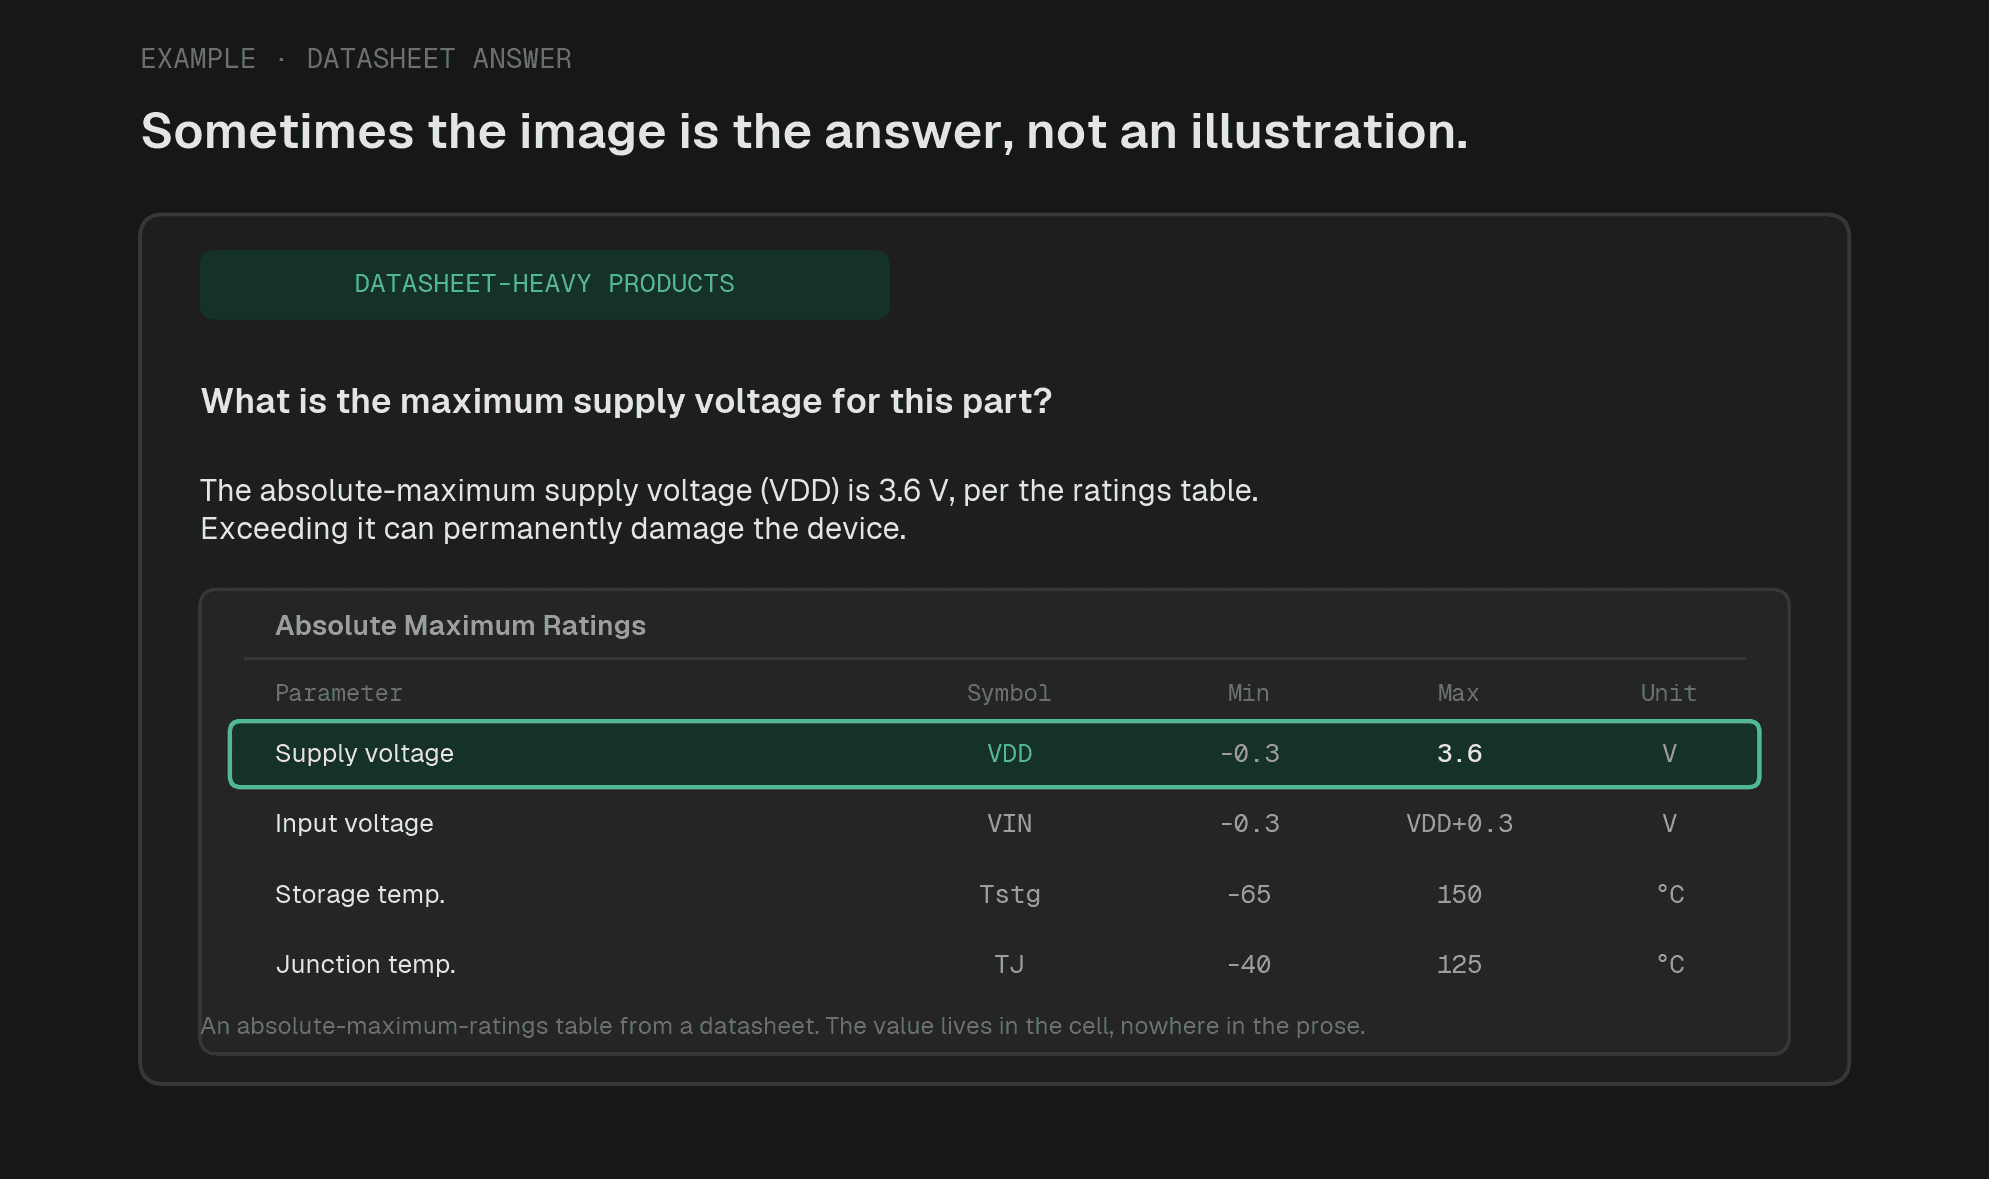
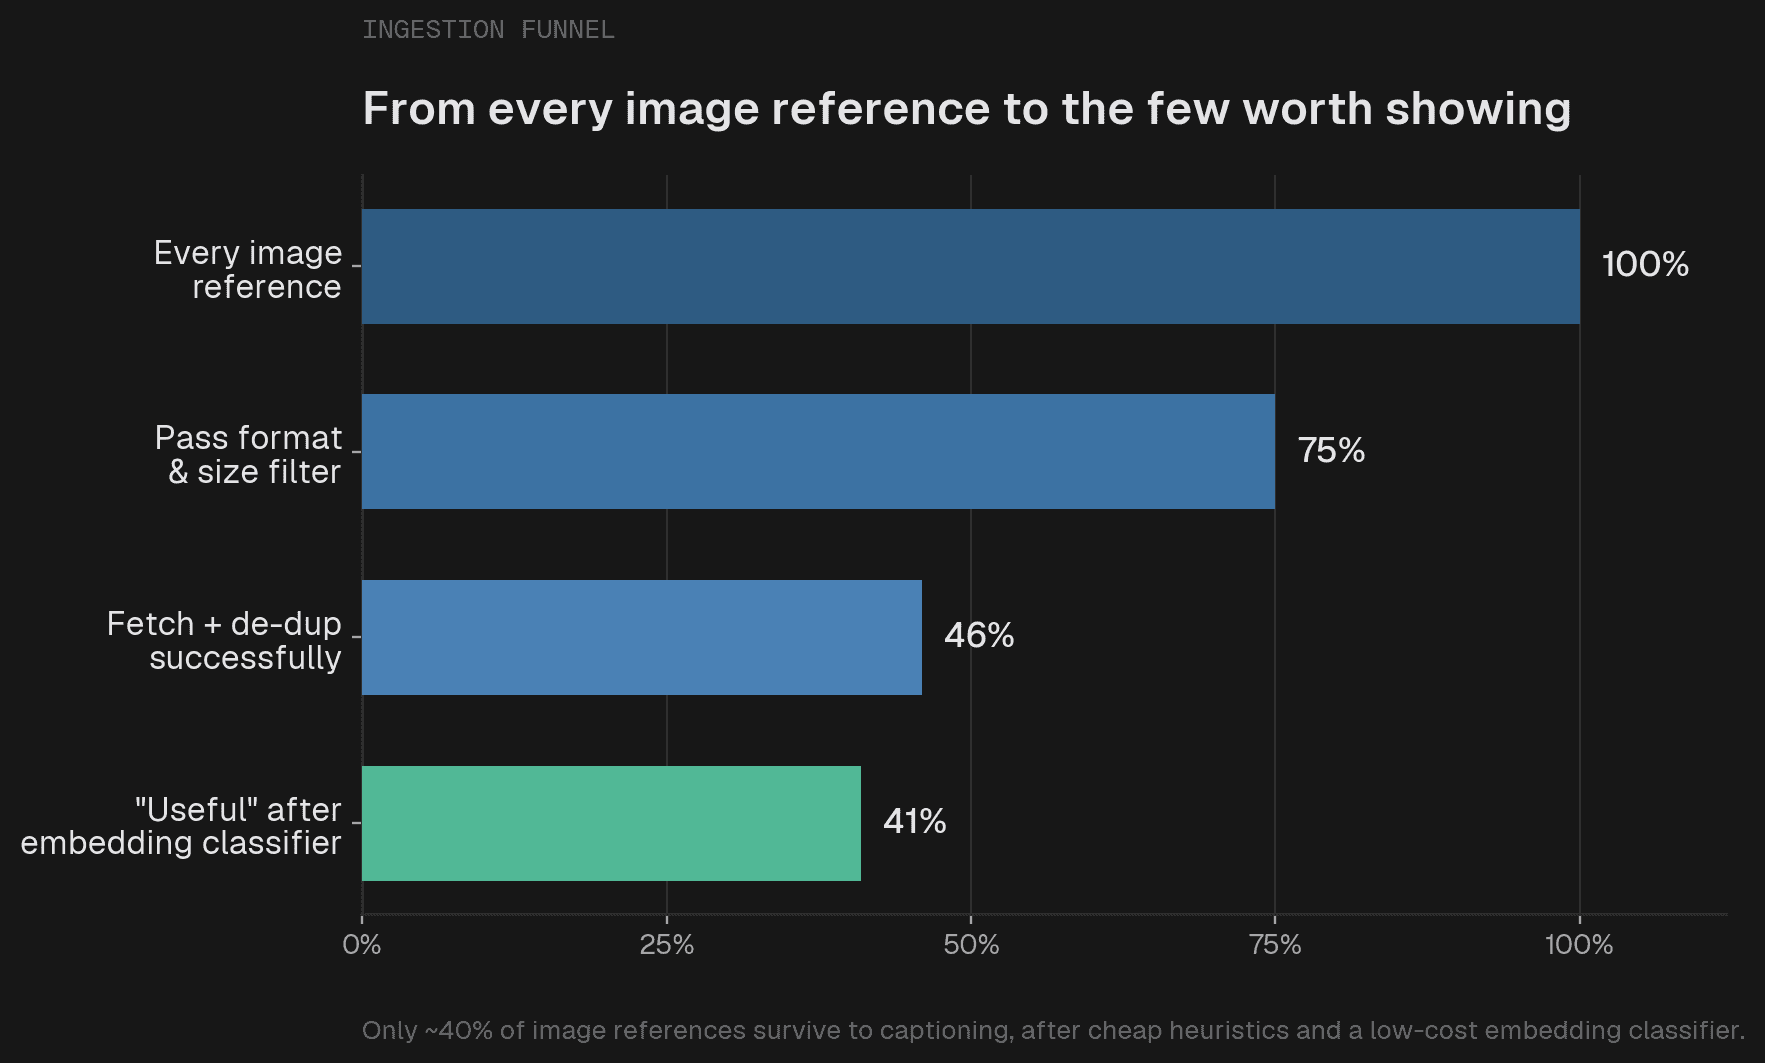
Kapa builds AI assistants that answer questions from technical documentation. The knowledge bases we process hold millions of images: screenshots, architecture diagrams, circuit schematics, annotated UI walkthroughs. We spent several months working out how to make them useful in our RAG pipeline. The short version: we don't send images to the model at query time. We describe each image once, at indexing time, with a cheap vision model, store the descriptions as text, and retrieve them alongside ordinary text chunks. Indexing is a one-time cost; after that, per-query overhead is 1% to 6% over text-only, and answers are measurably, statistically significantly better. This post explains how we got there. Both answers are correct. The one that shows the screenshot is the one a user can act on without hunting for the setting.…