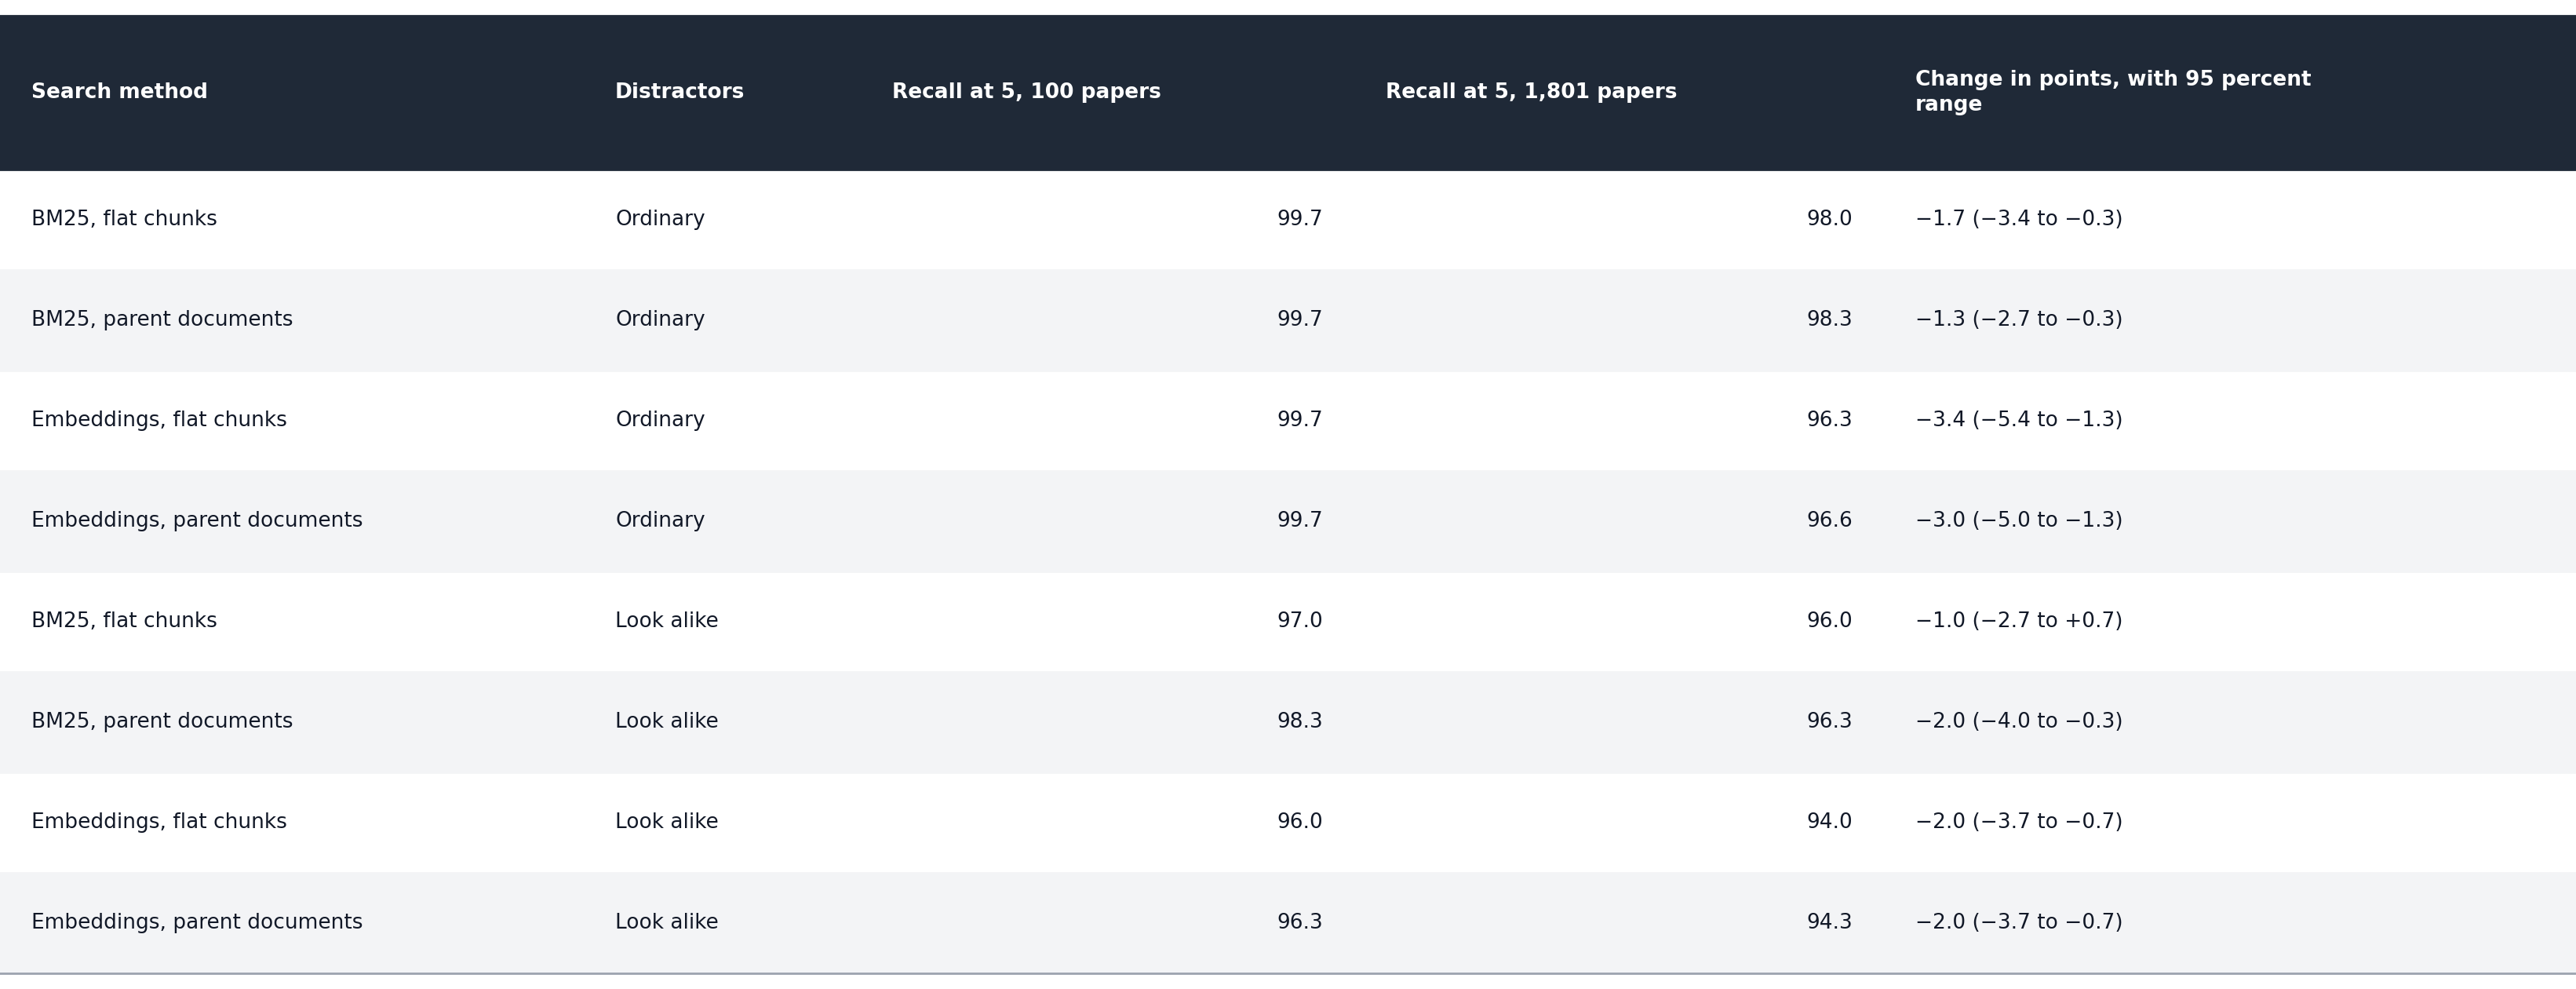
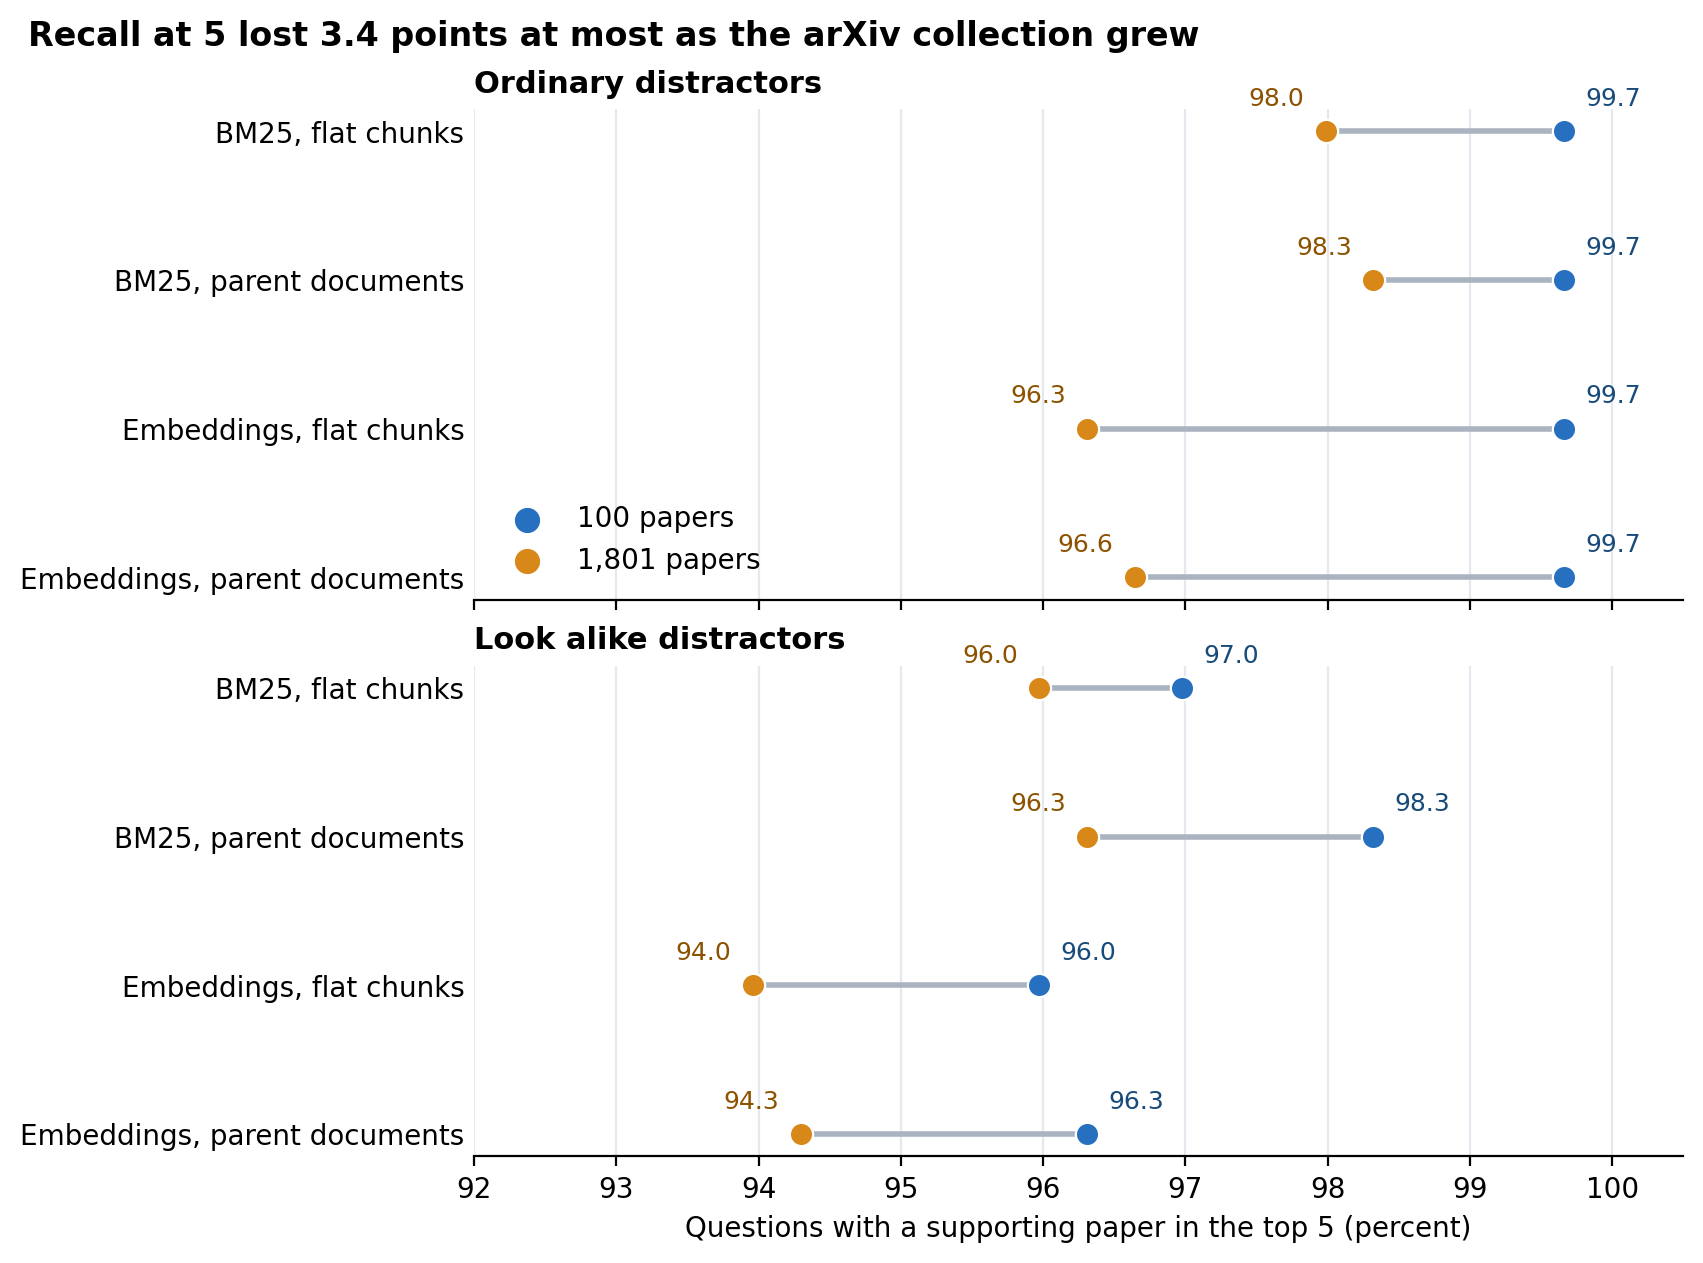
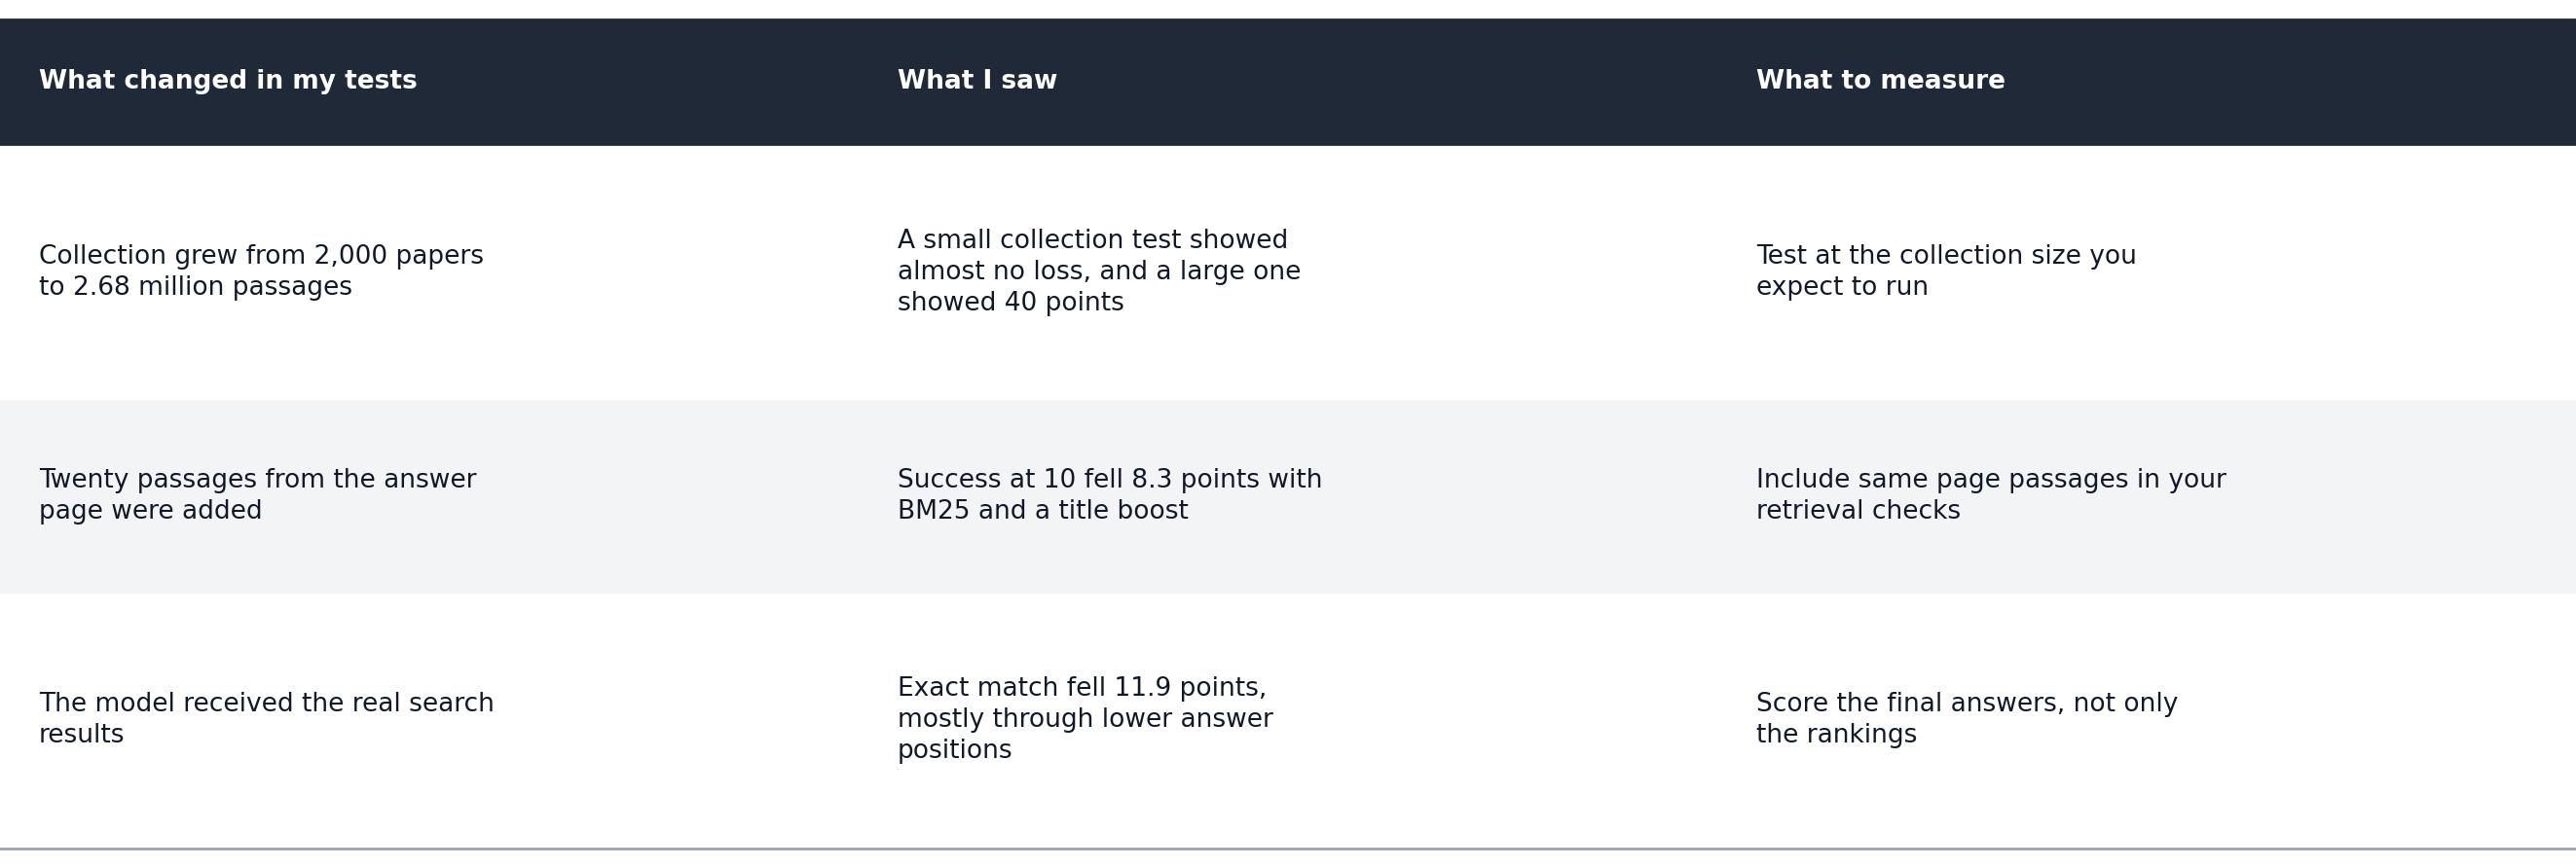
On a collection of 100 research papers, BM25, a standard text search method, put a paper that answered the question in its top five results for 99.7 percent of questions. On 1,801 papers, that number was 98 percent. I built the test to find the threshold at which that number drops, and it barely moved.
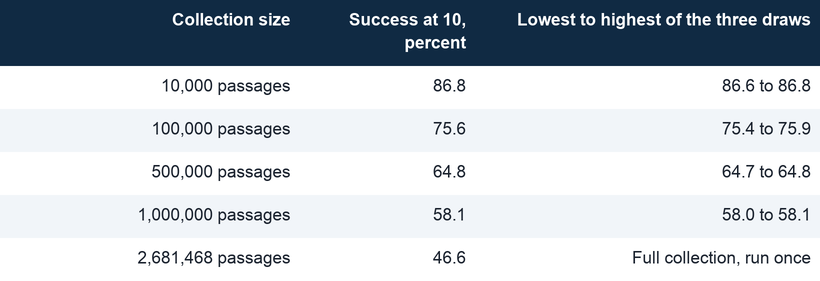
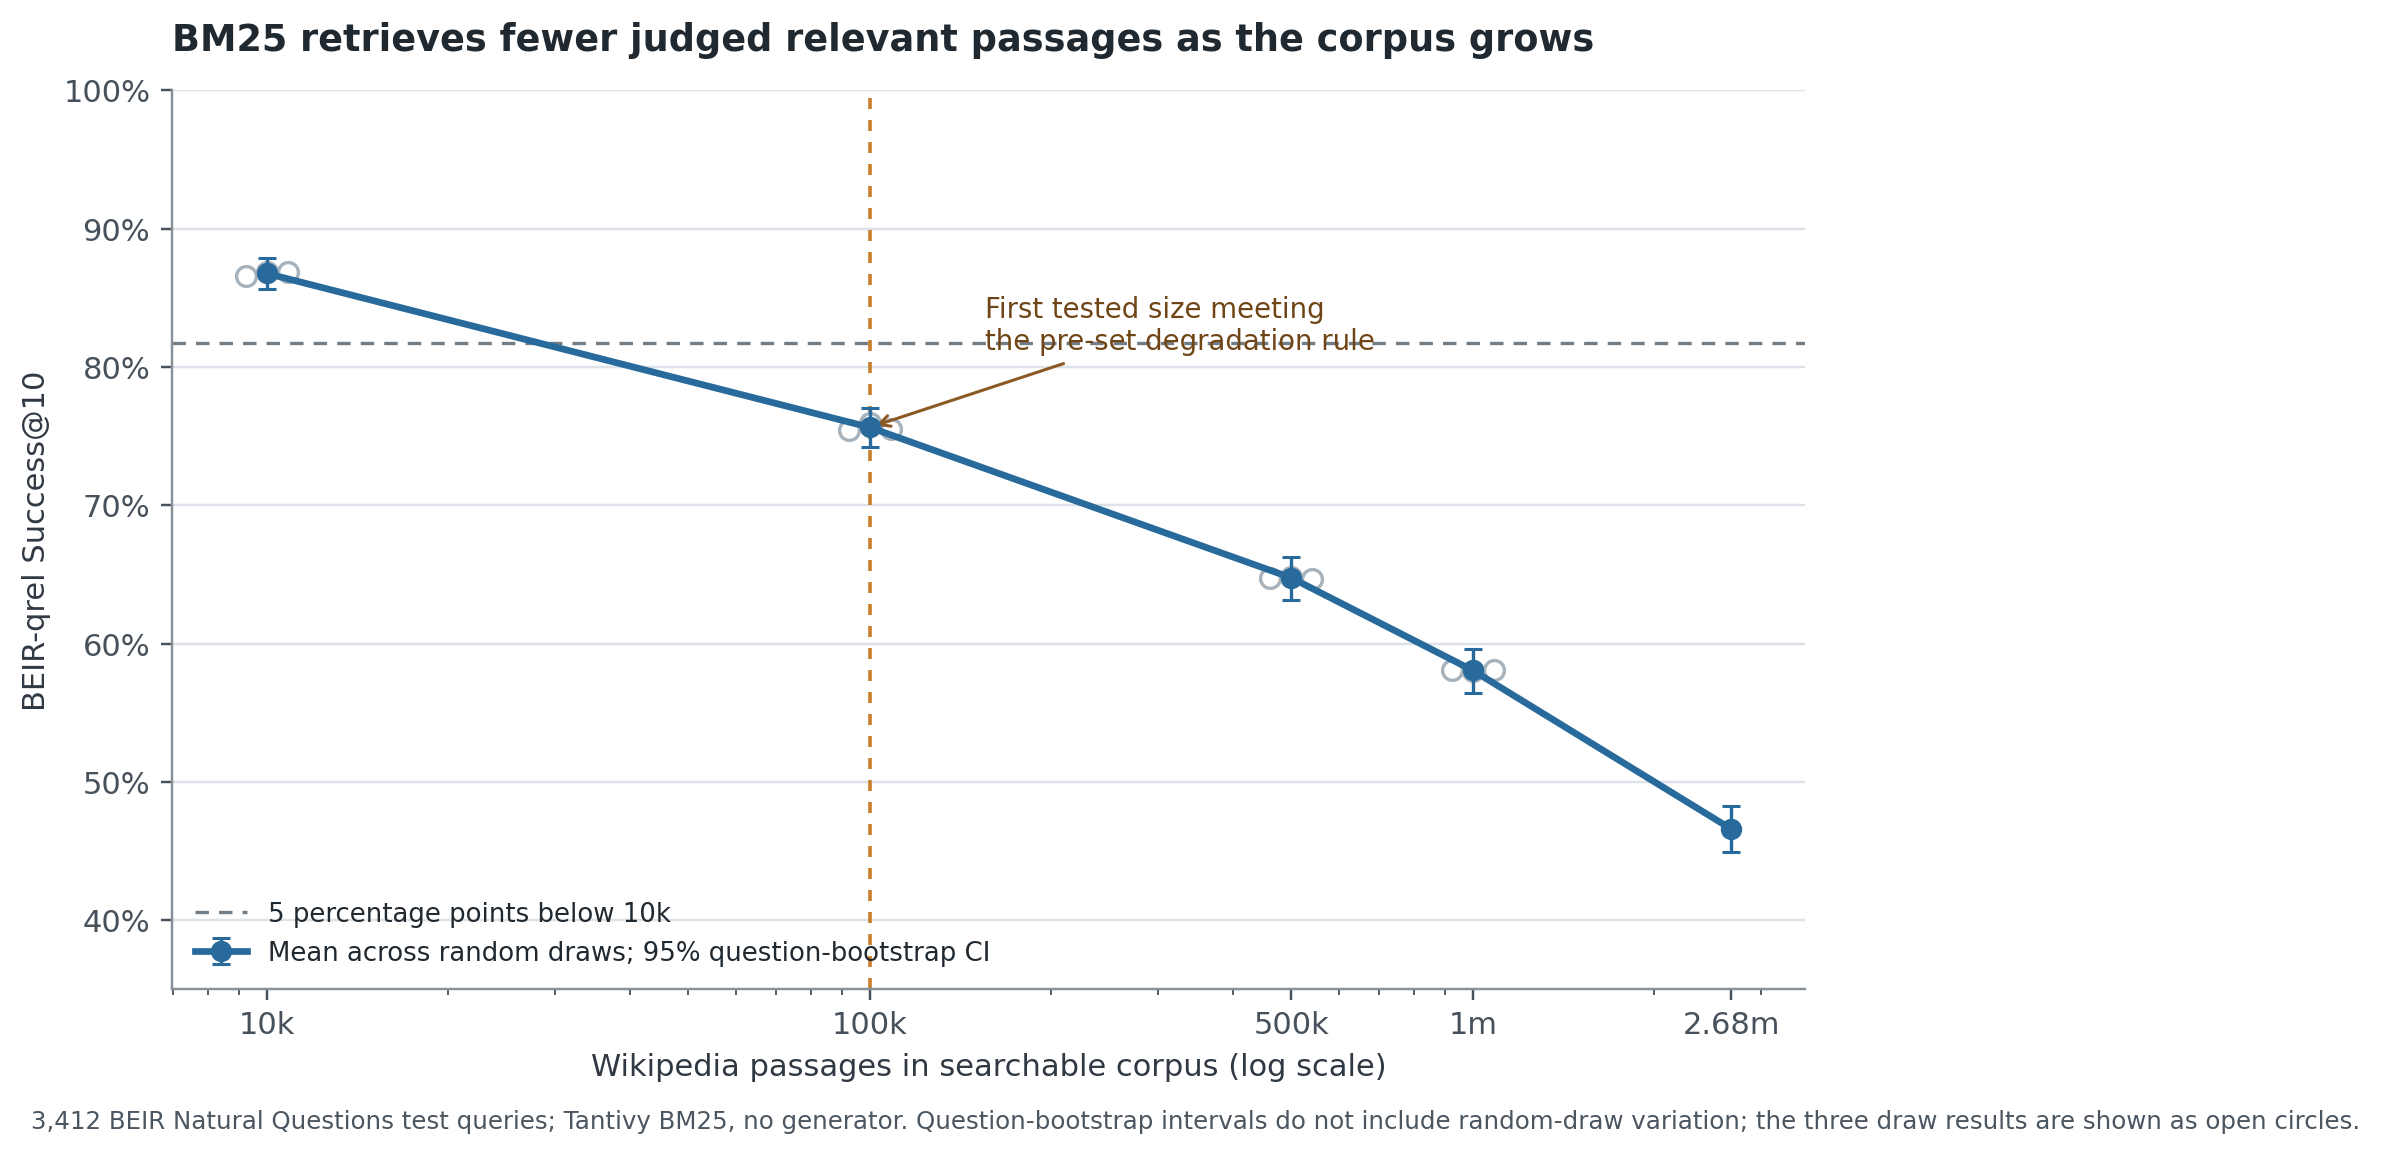
That result looked like good news for anyone running retrieval augmented generation, or RAG, where an AI model answers a question using passages that a search step fetched first. If search stays good as the collection grows, the rest of the system has solid ground to stand on. Then I ran the same kind of test on 2.68 million Wikipedia passages, and the picture changed.
This article reports both tests as one story. The first test used questions from my earlier test of agentic retrieval .…