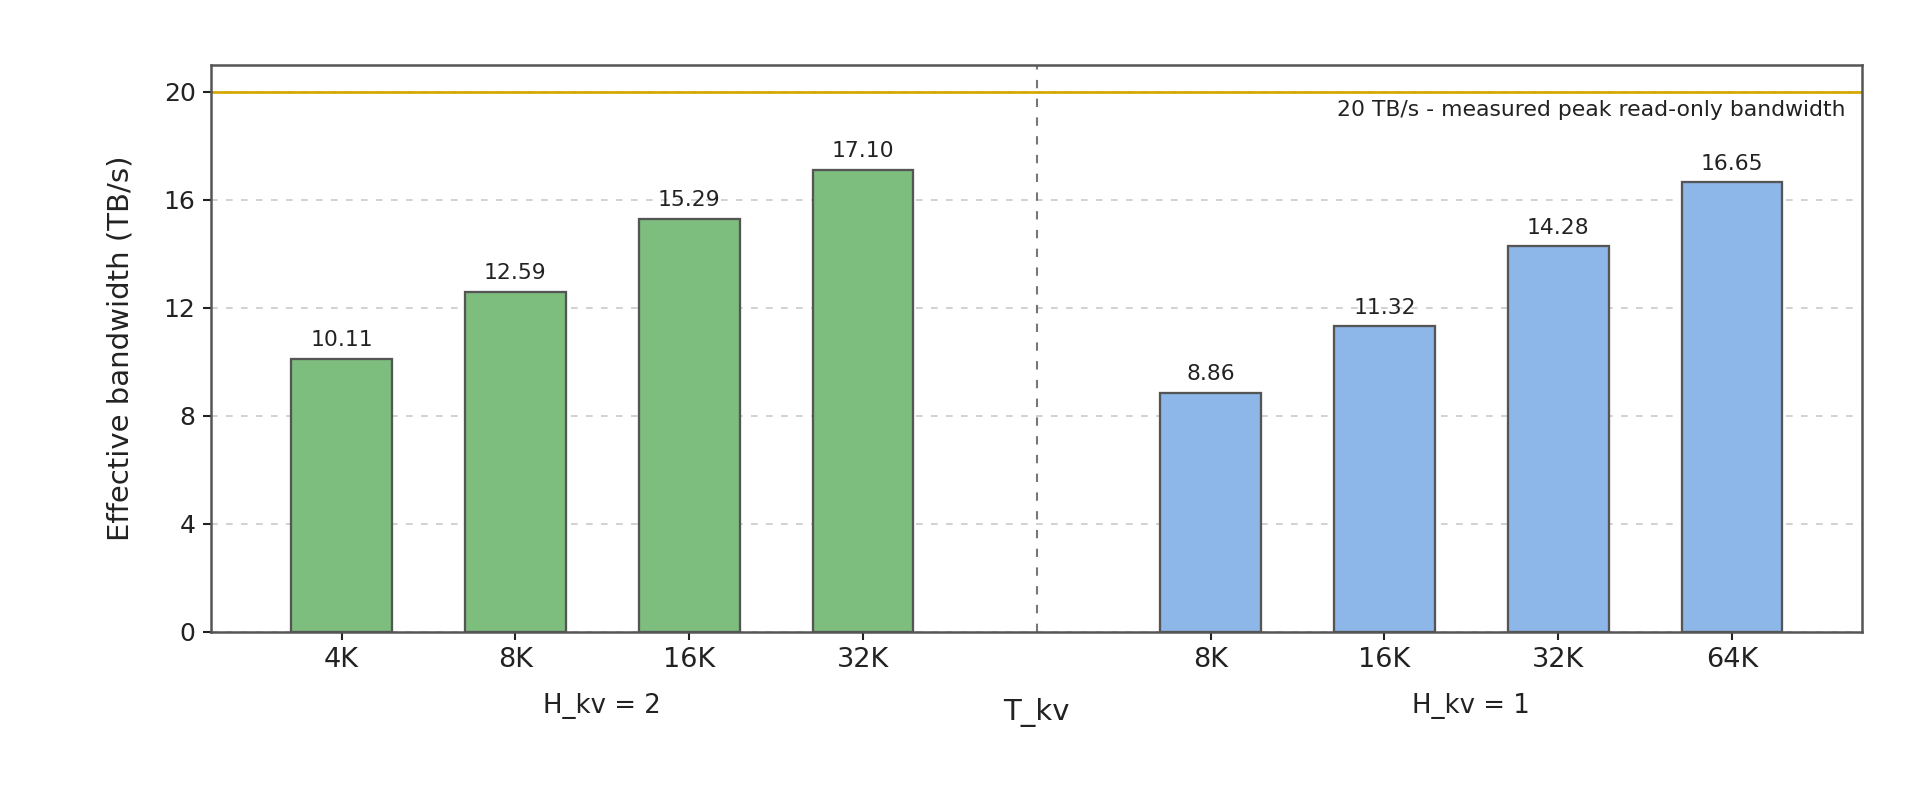
Attention Decode on AMD MI450 GPUs: A Gluon Kernel Optimization Guide # 14 min read. | 3480 total words. Agentic AI applications are pushing LLM inference into a new regime. A request can now reach one million tokens from aggregated long prompts, tool calls, retrieval results, and multi-turn reasoning. During the text generation phase, each new token must attend to all previous tokens from the KV cache, so the kernel needs to repeatedly read past states from HBM. As a result, the performance bottleneck shifts from compute units to the memory system. The AMD Instinct MI450 series GPU introduces a new set of hardware features for memory-sensitive AI workloads. This blog uses attention decode as a case study and discusses how to design a high-performance kernel on MI450. We will walk through core hardware features, explain how kernels can use these features, and showcase the performance of an optimized Gluon kernel, which achieves 85% of the peak HBM bandwidth on MI450 as an early result.…