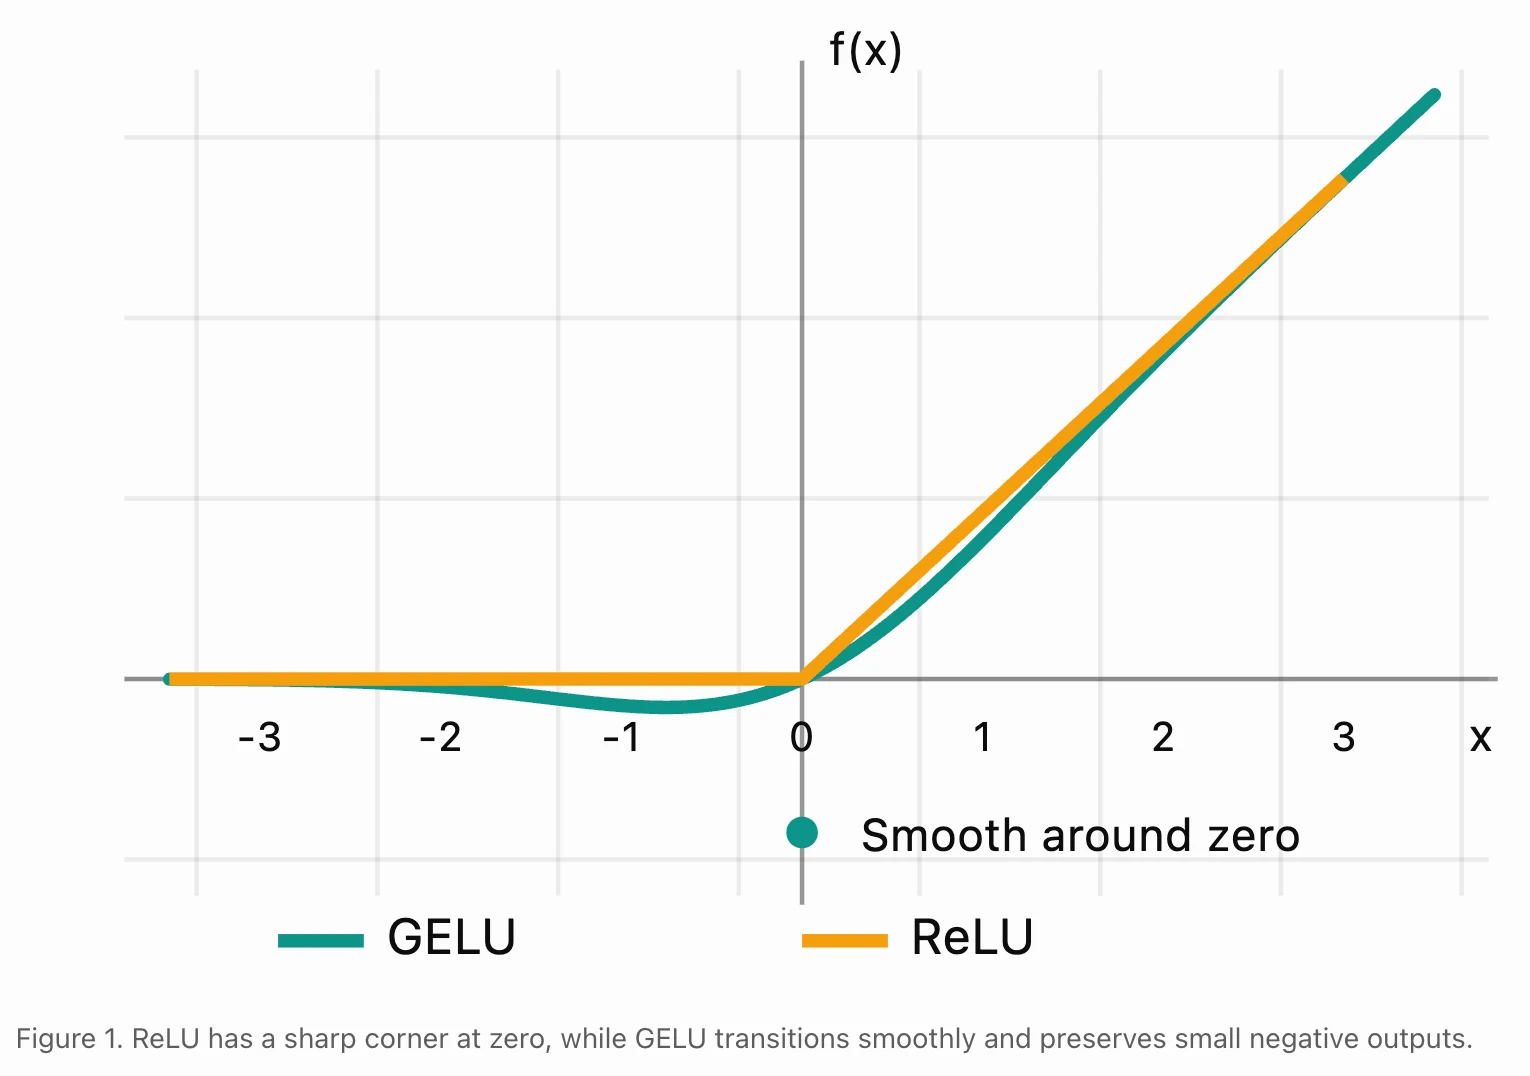
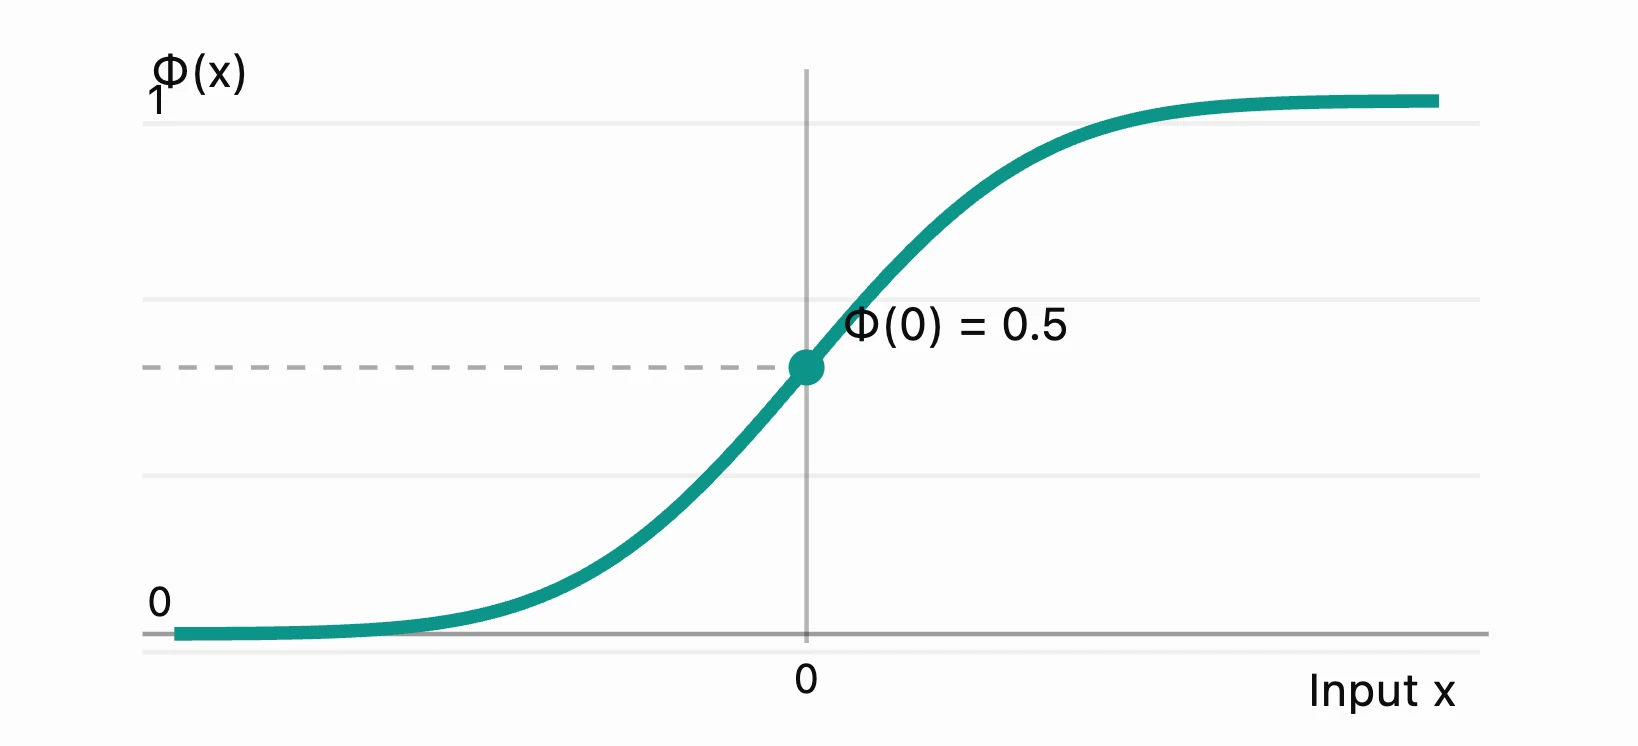
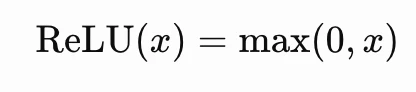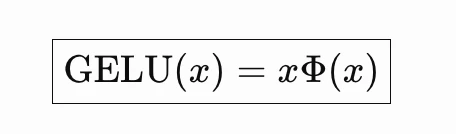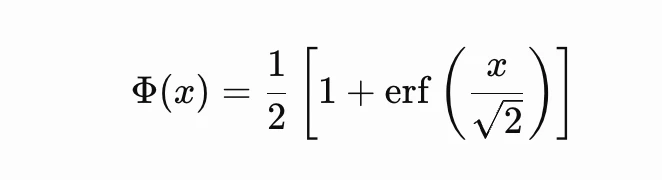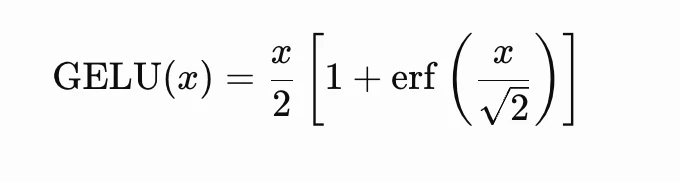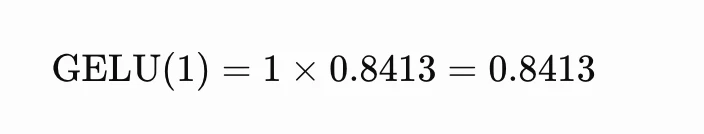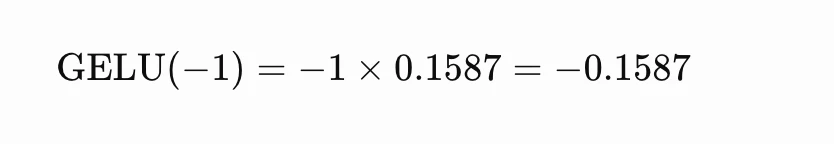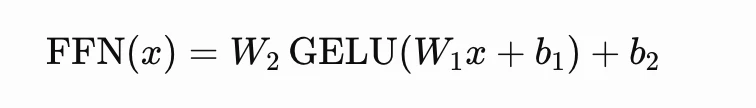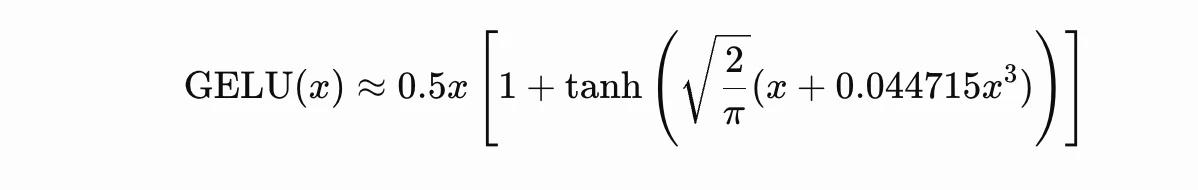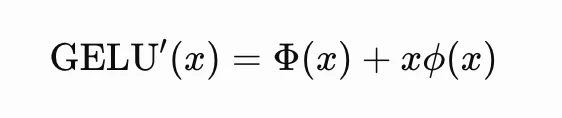Why do Transformer models like BERT use GELU instead of the traditional ReLU activation function? The answer lies in how these functions process information. While ReLU completely removes negative inputs, GELU uses a smooth, input-dependent mechanism to decide how much information should pass through. This small mathematical difference can influence how neural networks learn complex patterns.
In this article, we will understand the GELU activation function, explore its mathematics, compare it with ReLU, and implement both functions using Python.
Table of contents
What Is the GELU Activation Function?
Understanding GELU vs ReLU Visually
The Mathematics Behind GELU
Why Does GELU Use a Gaussian Distribution?
GELU vs ReLU: Key Differences
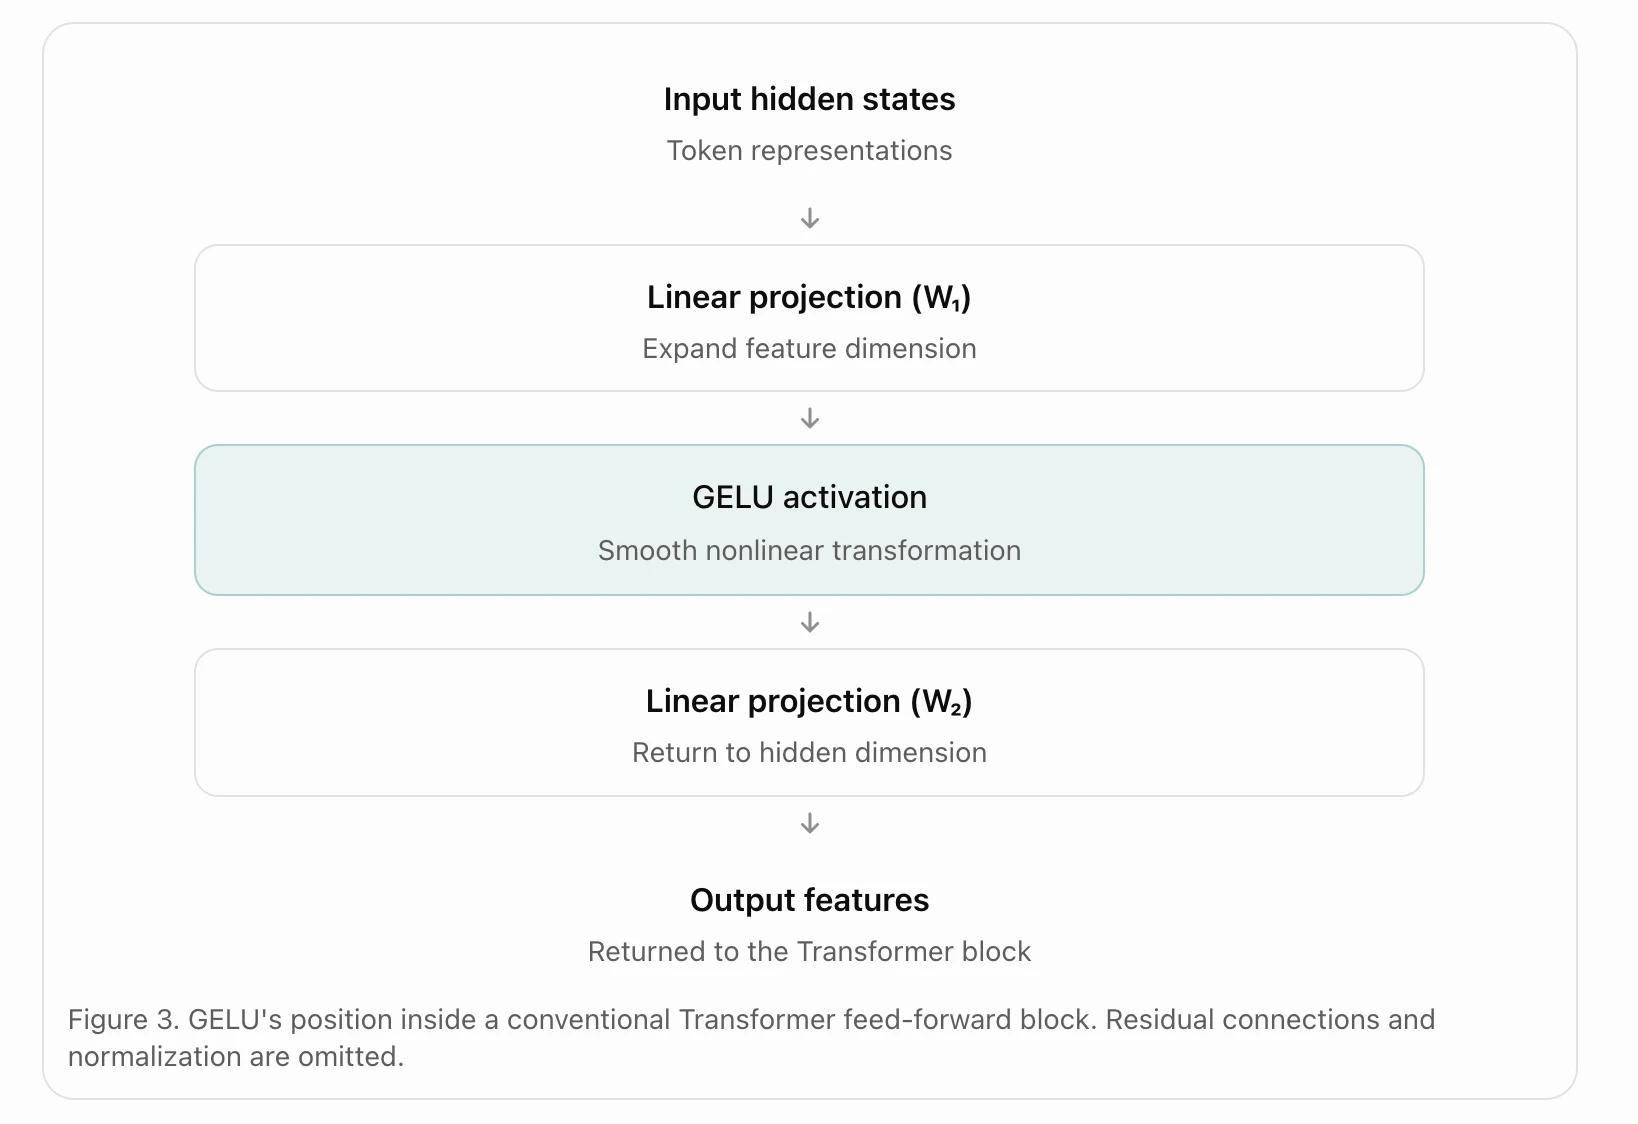
Why Is GELU Used in Transformers?
Approximating GELU for Efficient Computation
Hands-On: Comparing GELU and ReLU Using Python
Advantages and Limitations of GELU
When Should You Use GELU?
Conclusion
Frequently Asked Questions
What Is the GELU Activation…