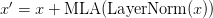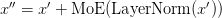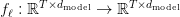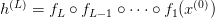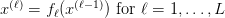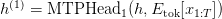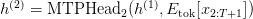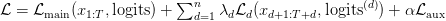Table of Contents
DeepSeek-V3 from Scratch: Building the Architecture in PyTorch
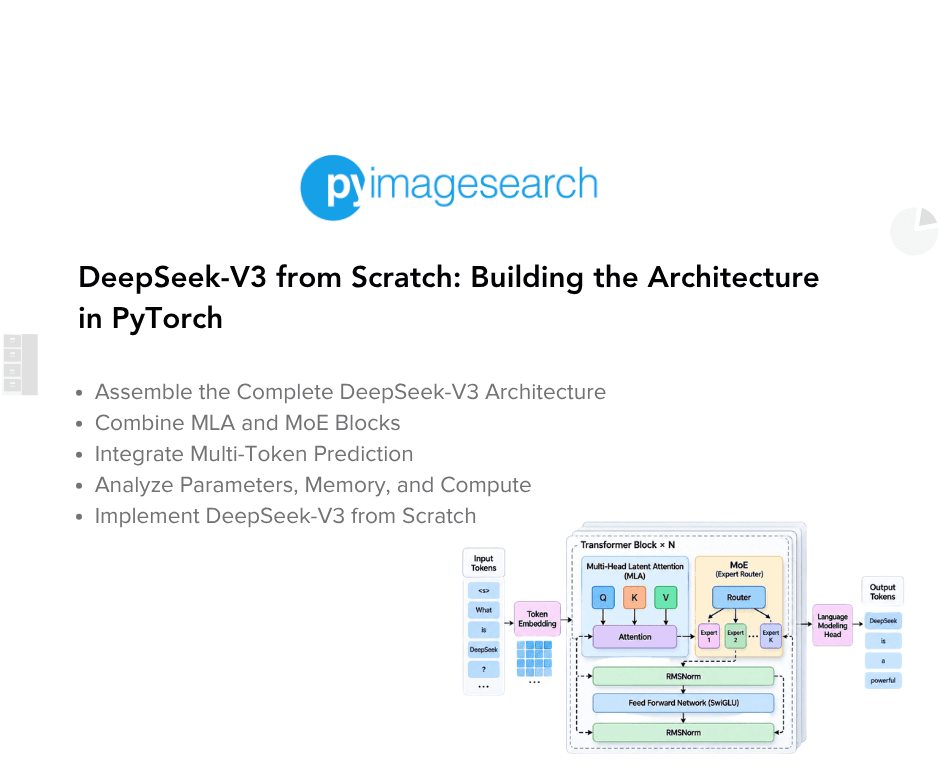
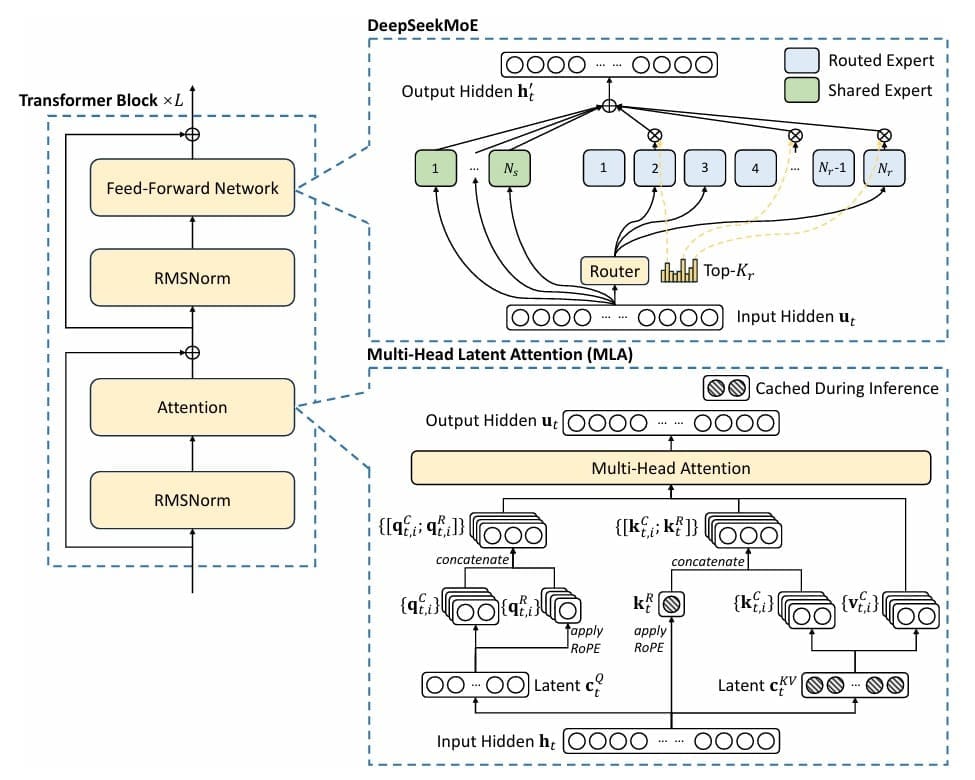
The Transformer Block: Combining MLA and MoE
The Complete Model: From Tokens to Logits
Weight Tying: Sharing Token Embeddings and Output Weights
Multi-Token Prediction Integration
Implementing the DeepSeek-V3 Architecture in PyTorch
Architectural Design Patterns
Parameter Count Analysis
Memory and Computation Footprint
Summary Citation Information
Across the first 4 lessons, we have carefully constructed the building blocks of DeepSeek-V3: starting with its configuration and Rotary Position Embeddings (RoPE) , advancing through Multihead Latent Attention (MLA) , scaling capacity with the Mixture of Experts (MoE) , and using Multi-Token Prediction (MTP) to improve training efficiency and enable faster inference through speculative decoding.…