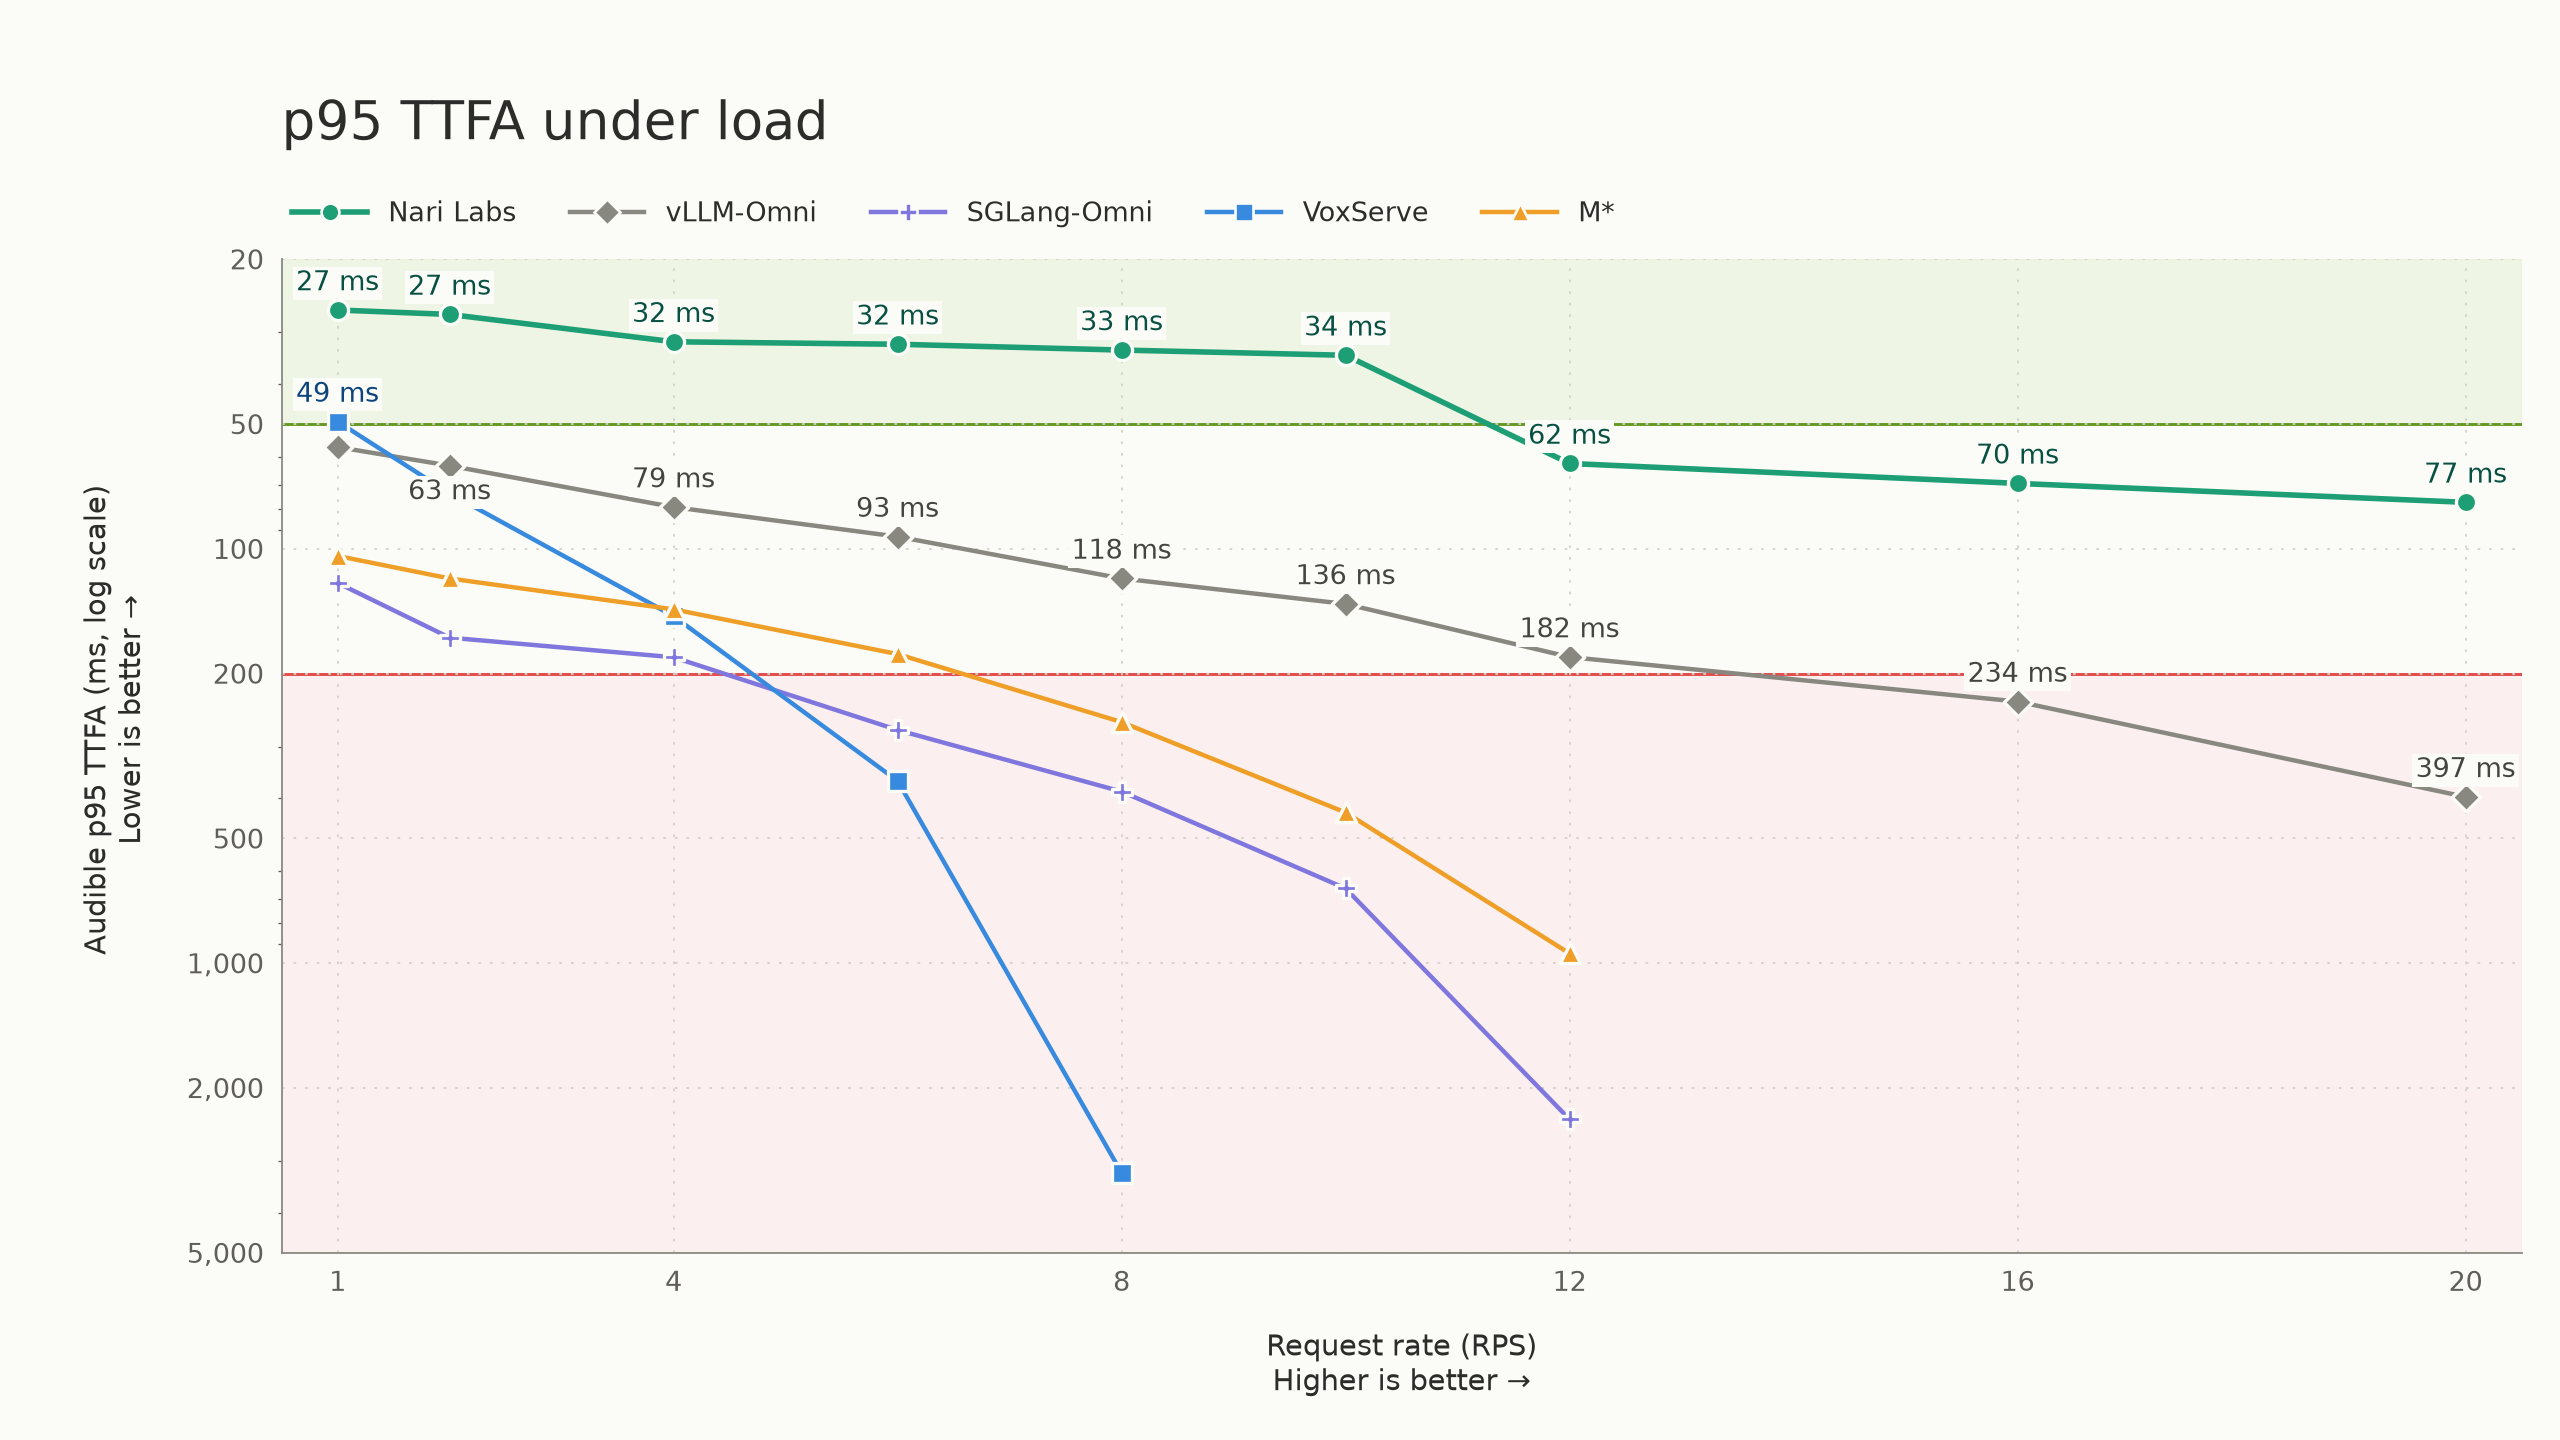
TL;DR Our Qwen3-TTS 1.7B CustomVoice implementation achieves 10 requests per second (RPS) and sub-50 ms p95 time-to-first-audio (TTFA) while maintaining real-time playback on a single NVIDIA H100 SXM. We compare five implementations: ours, vLLM-Omni, SGLang-Omni △ , VoxServe, and M*, under Poisson open-loop traffic. After tuning each implementation for low-latency streaming, ours is the only one to achieve sub-50 ms p95 TTFA . We maintain sub-50 ms p95 TTFA through 10 RPS and keep it below 100 ms even at 20 RPS . Our system produces approximately 630 characters per second at 10 RPS. At $4.29 per hour for a 1× H100 SXM instance, this translates to ~$2 per 1M characters at full utilization 1 . For comparison , ElevenLabs V3 is $100 / 1M and Cartesia Sonic 3.5 is $49 / 1M at a higher TTFA . We open source the implementation and benchmark . Our methodology is explained below. Defining “Real-time” TTS Let’s start by discussing what a real-time TTS server needs to achieve.…