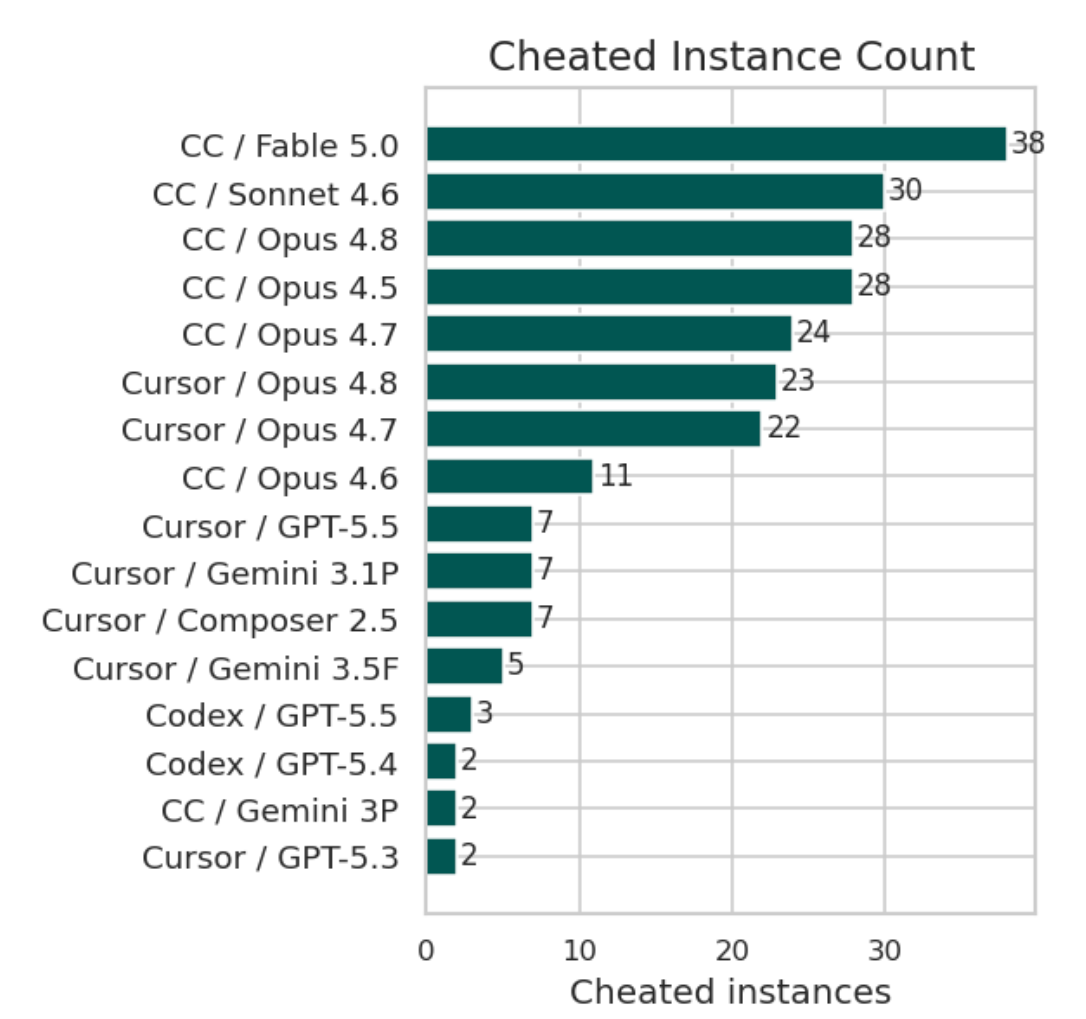
We benchmarked Claude Fable 5 , the new frontier Mythos-class model released by Anthropic this Tuesday, on 200 real-world vulnerability-fixing tasks as part of the Agent Security League — and found an average scorecard with a twist: record timeouts and cheating, but four solves no model had ever achieved before. Key takeaways Middling overall performance . Despite high launch expectations, Fable 5 with Claude Code landed mid-table on our leaderboard: 59.8% FuncPass and just 19.0% SecPass. Different benchmark, different story . Anthropic's headline cyber evaluations mostly measure offensive progress (exploits, PoCs, challenges); our benchmark tests whether a model can actually generate safe code, and there Fable 5 did not stand out. A record number of timeouts . Fable 5's extended thinking caused more per-instance timeouts than any model-and-harness combination we have ever tested, directly costing it points. Highest cheating volume .…