Written by Tara Khani, CEO & Co-Founder, Moorcheh.ai
Can a $399 single-board computer index millions of technical documents, search video frames and audio logs in milliseconds, and run an 8B-class local LLM, all while managing a deterministic real-time control loop offline?
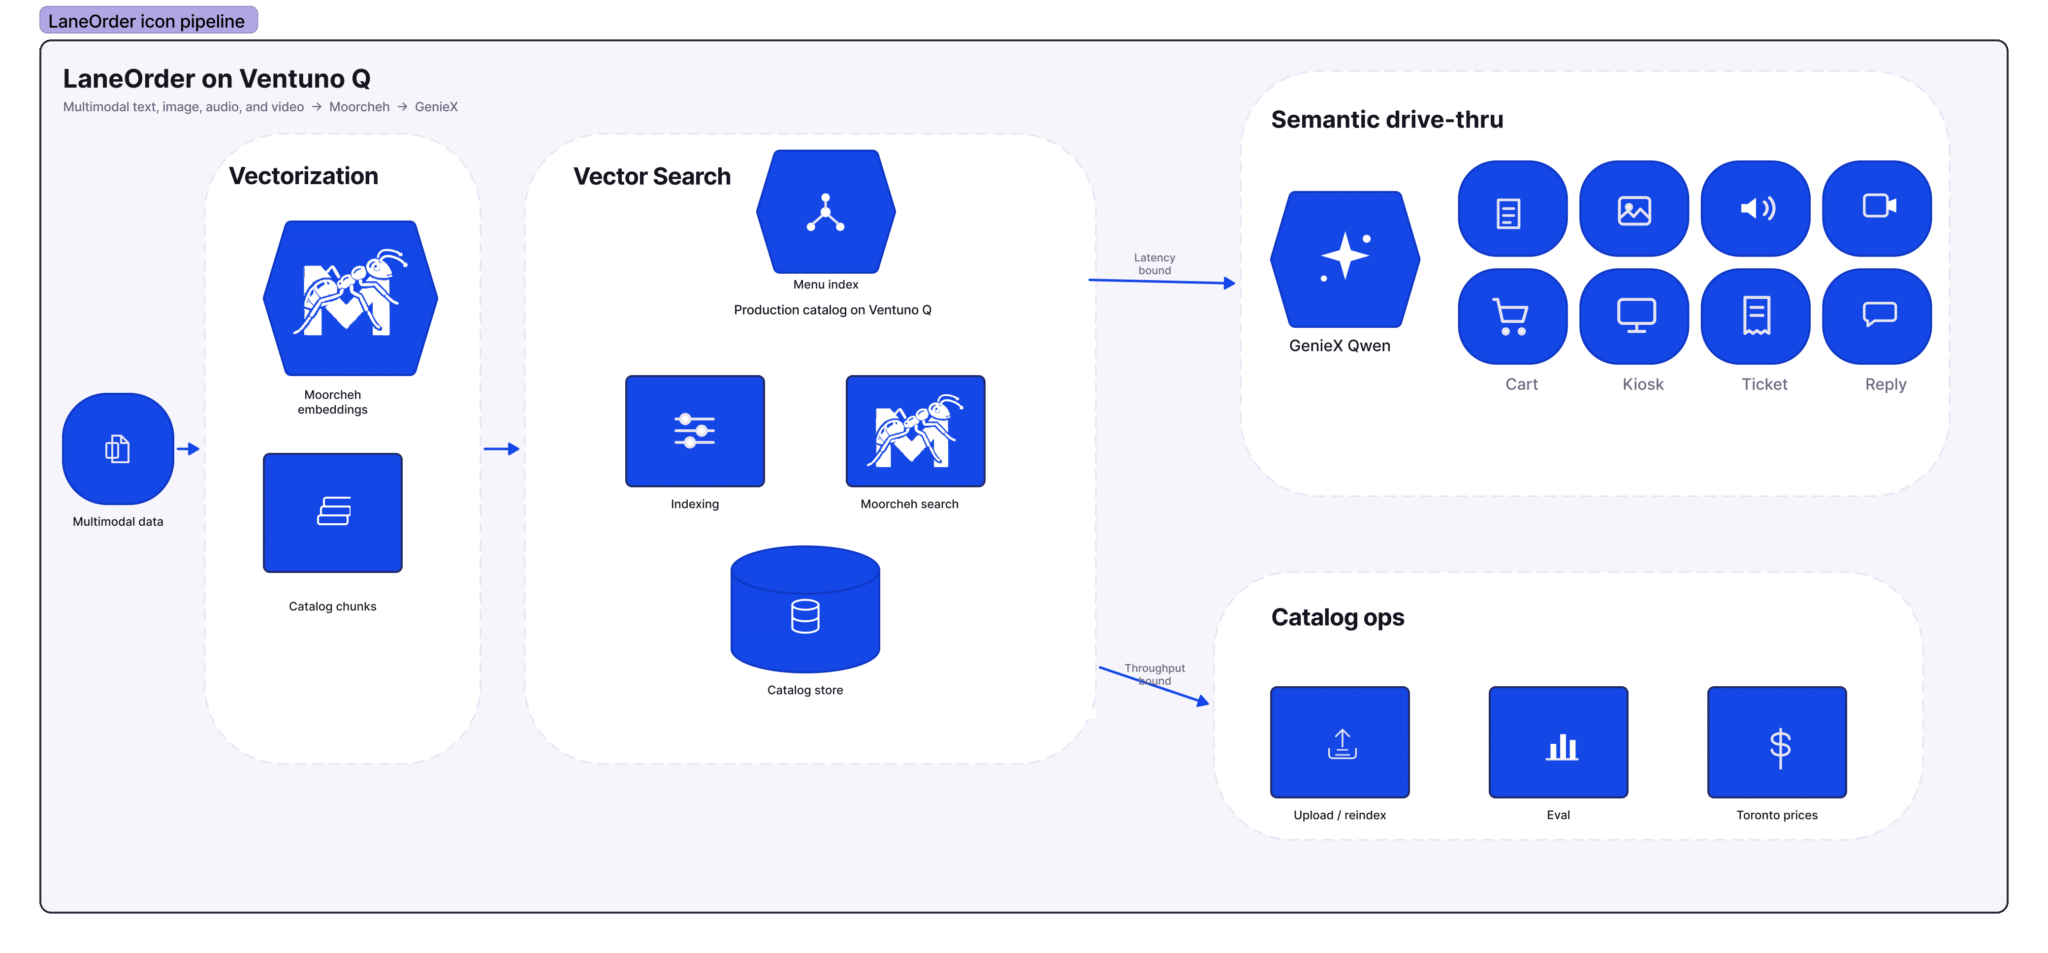
To answer this, Moorcheh profiled an end-to-end, multimodal agentic memory pipeline directly on the Arduino ® VENTUNO ™ Q board.
Unlike cloud servers or 64 GB industrial workstations, edge hardware for physical AI demands strict memory discipline. Every gigabyte consumed by vector databases, graph pointers, and write-ahead logs is memory stripped away from local Vision-Language Models (VLMs), KV caches, speech engines, and real-time vision buffers.
Here is how we bypassed the edge memory bottleneck to bring scalable multimodal retrieval to the VENTUNO Q.
The hardware: Dual-brain compute
The VENTUNO Q features a dual-brain architecture built specifically for physical AI:
Linux and AI compute: Powered by the Qualcomm Dragonwing ™…