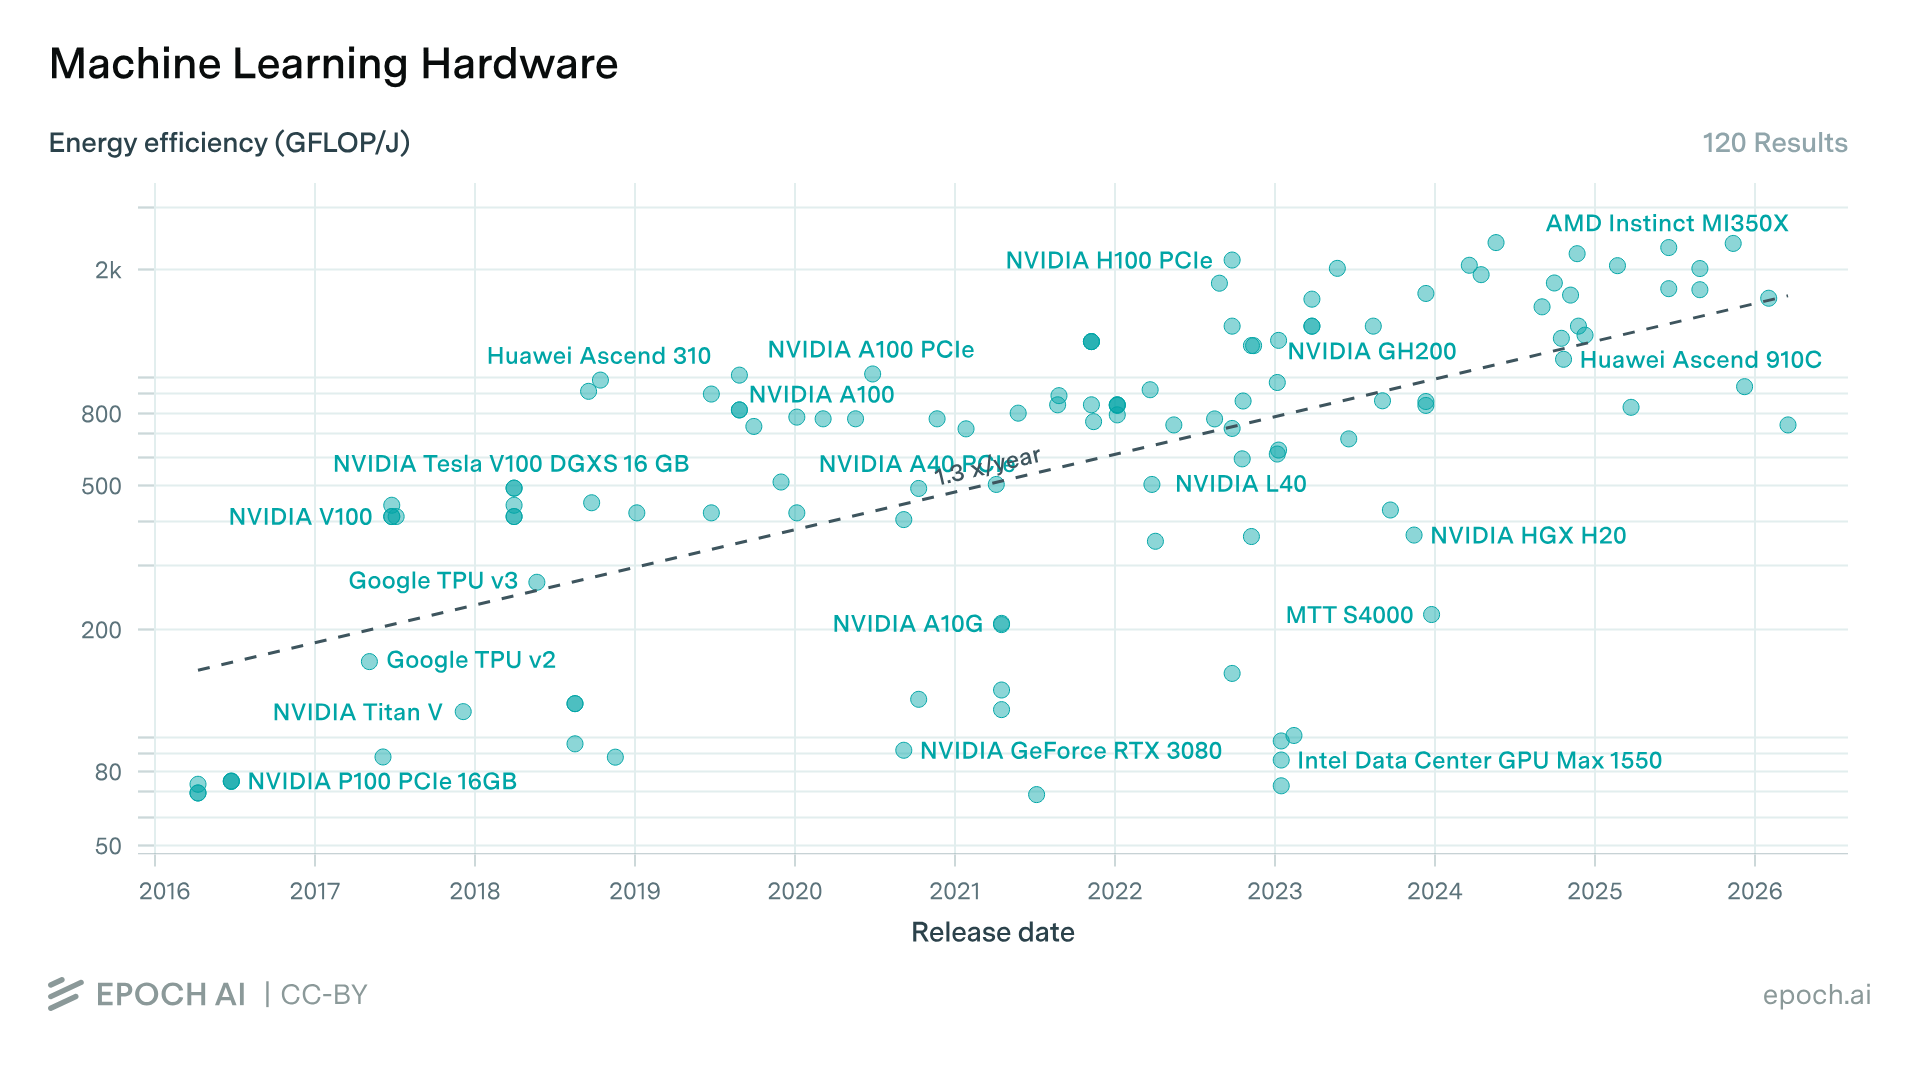
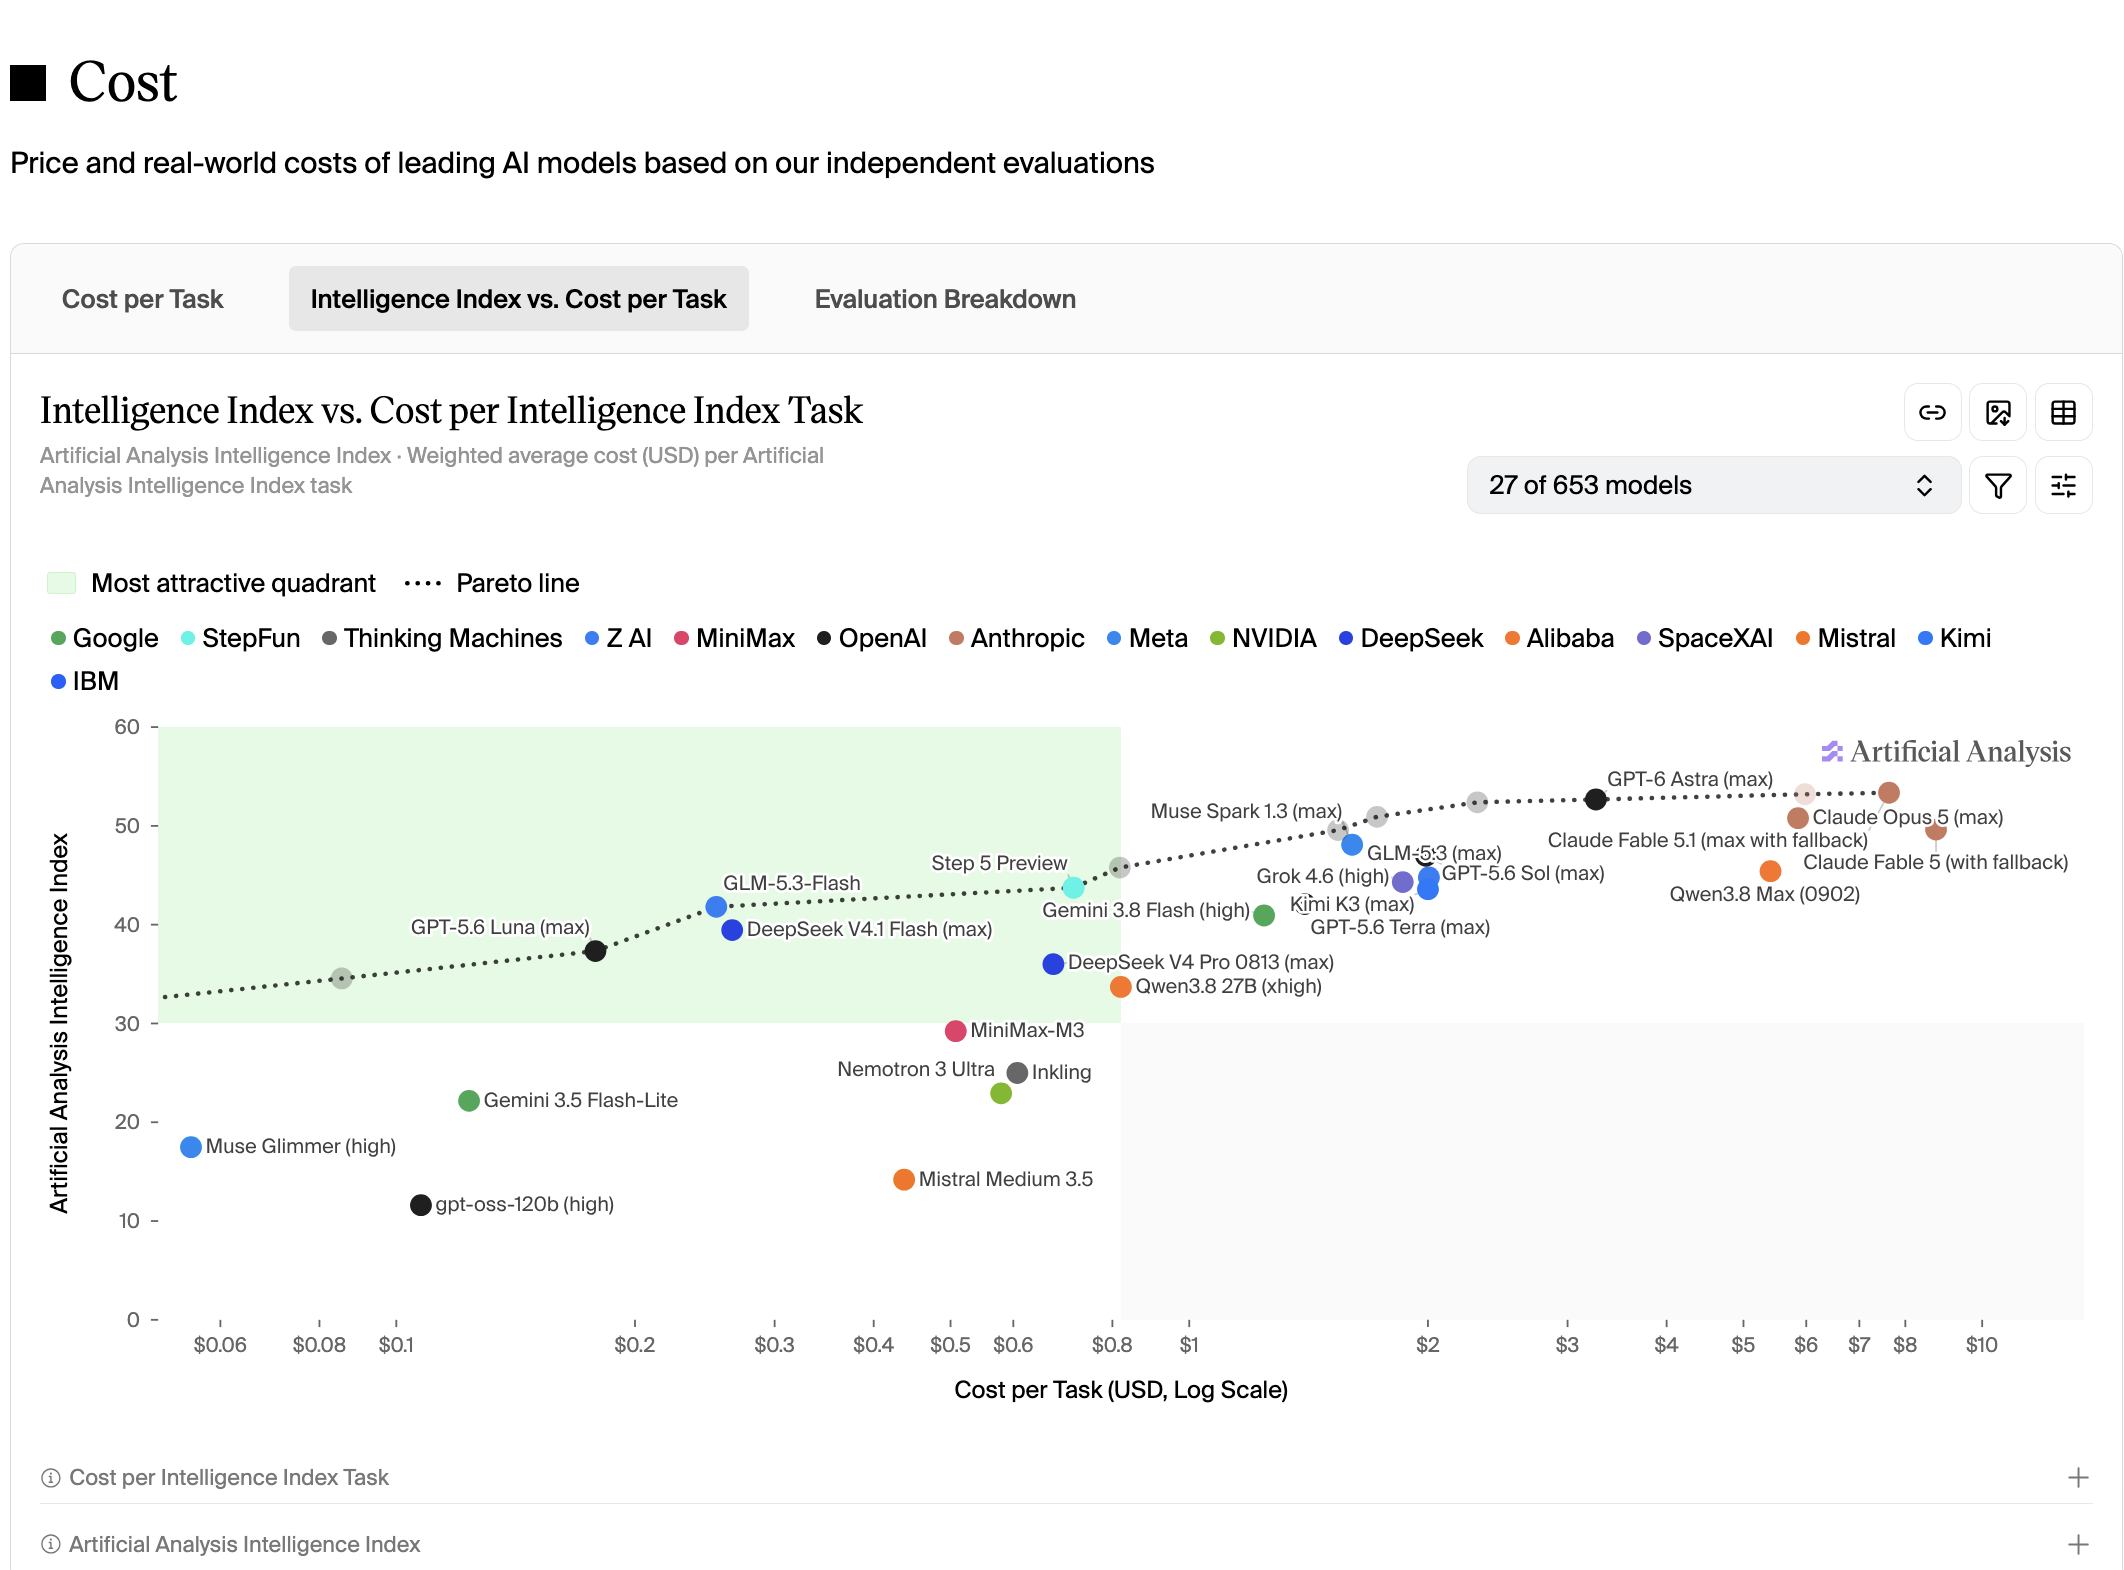
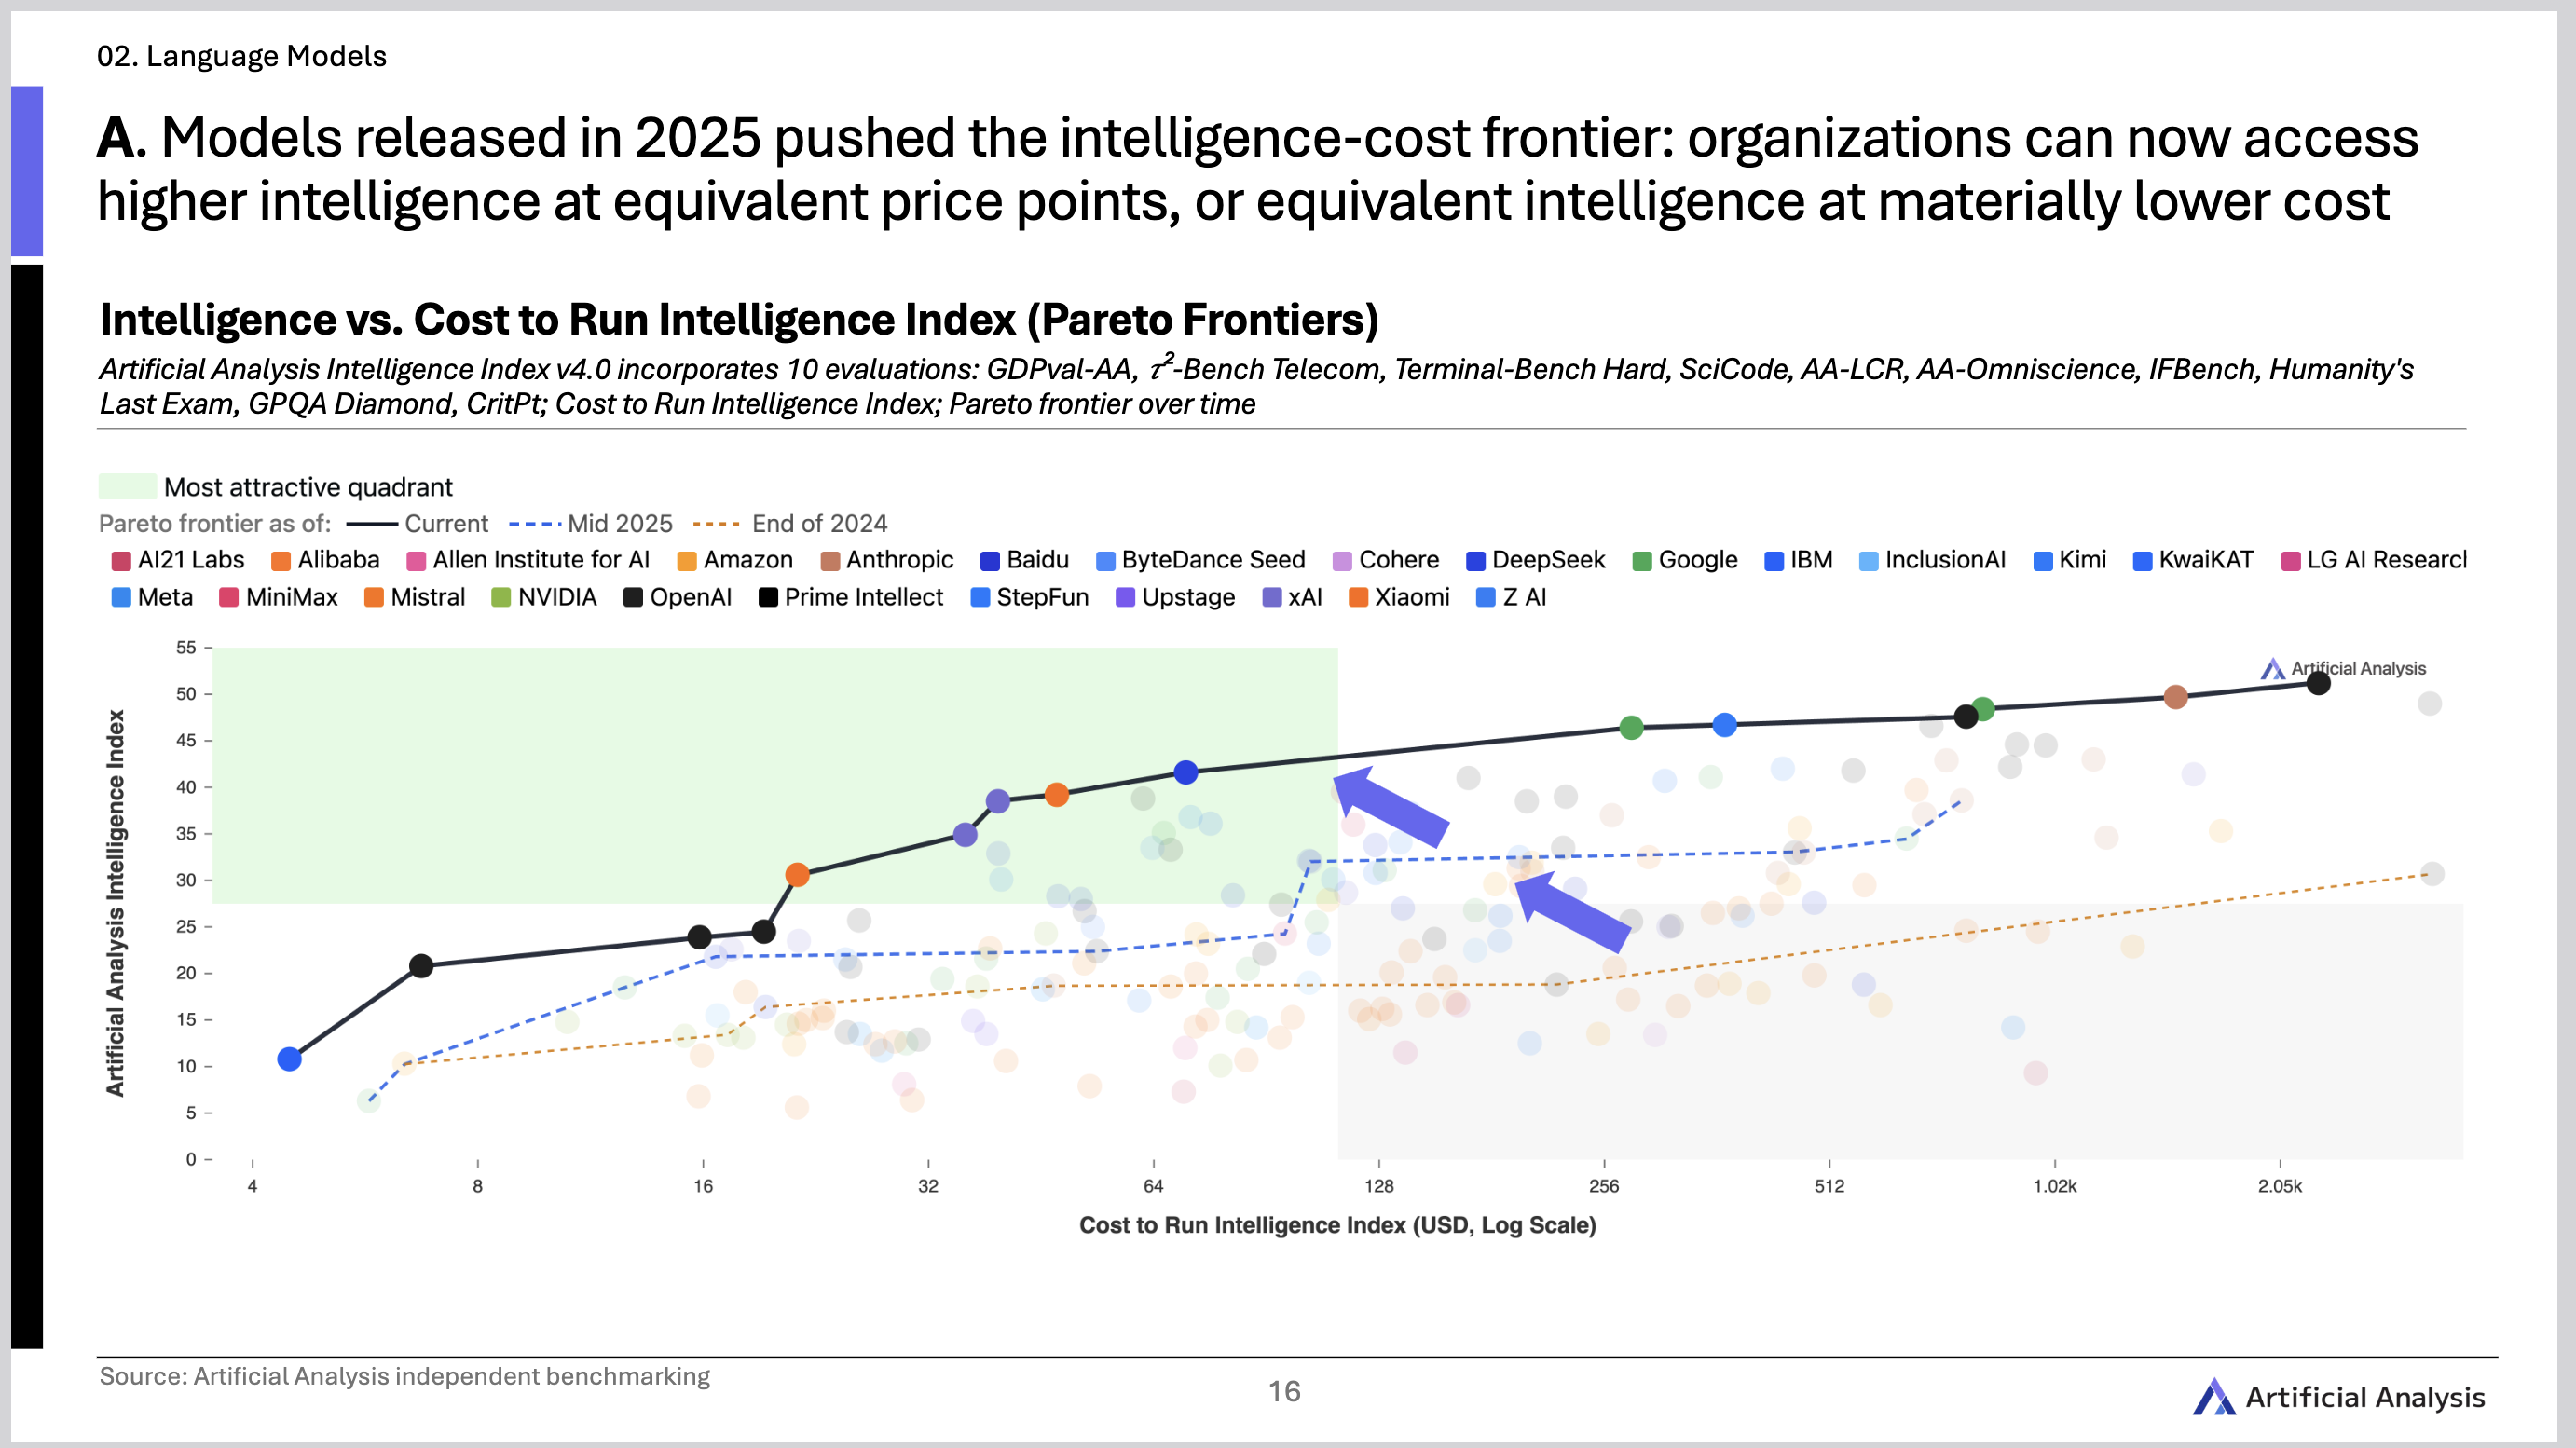
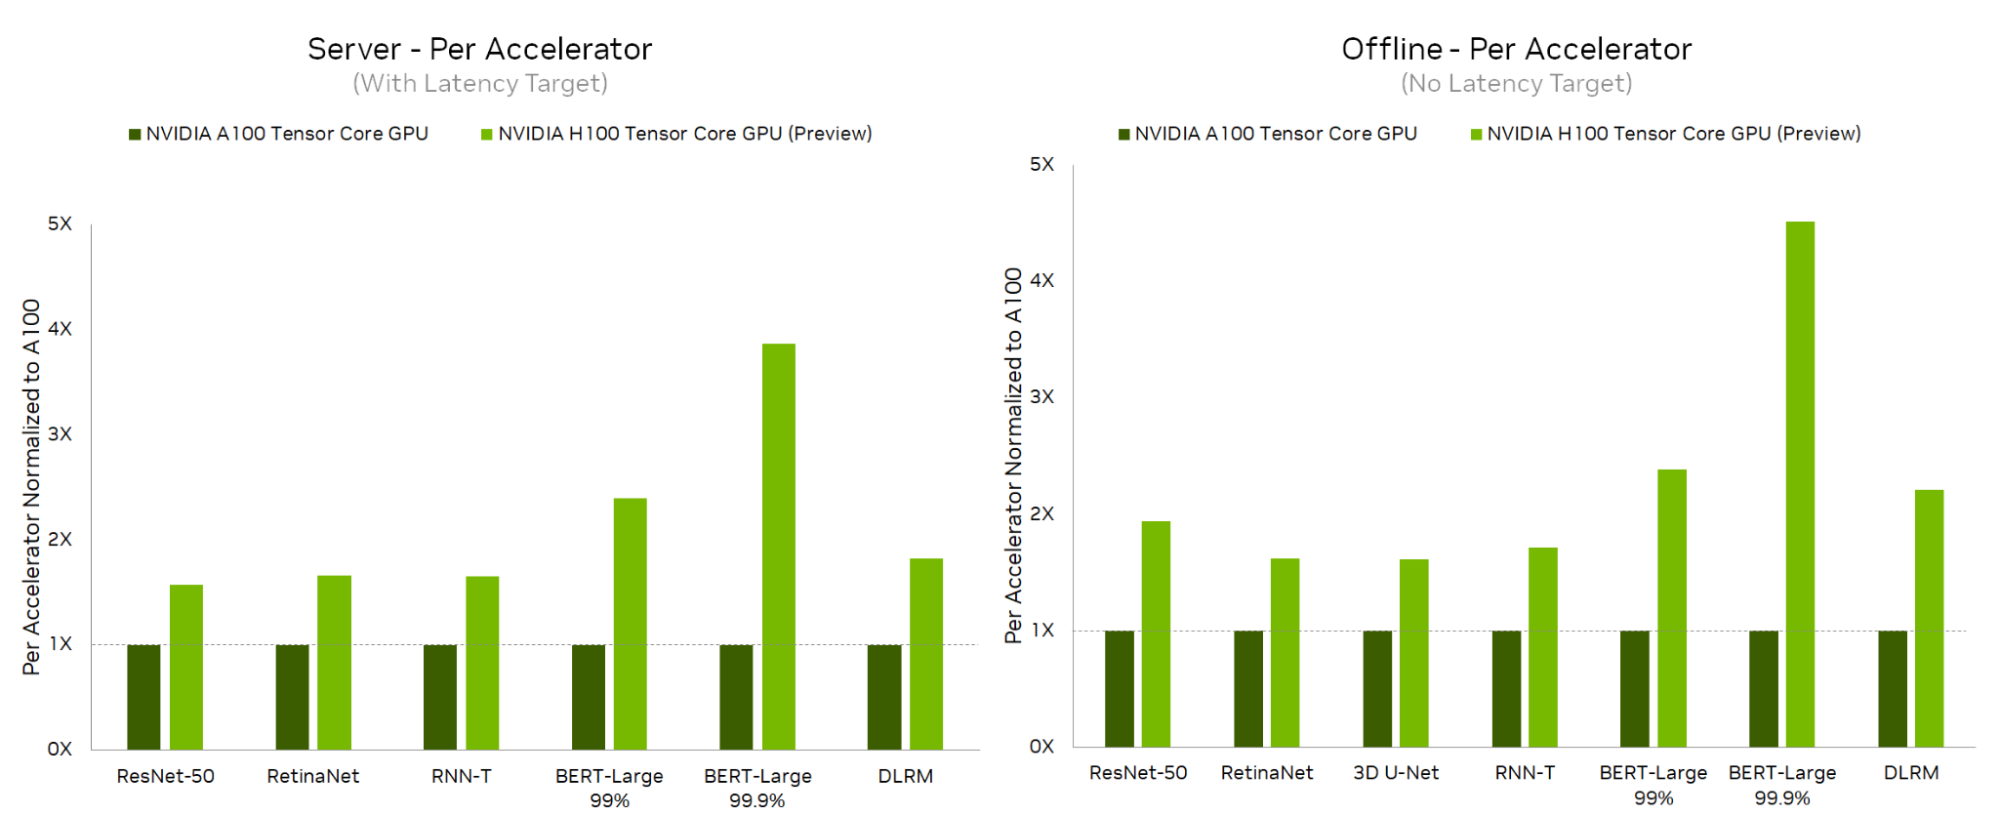
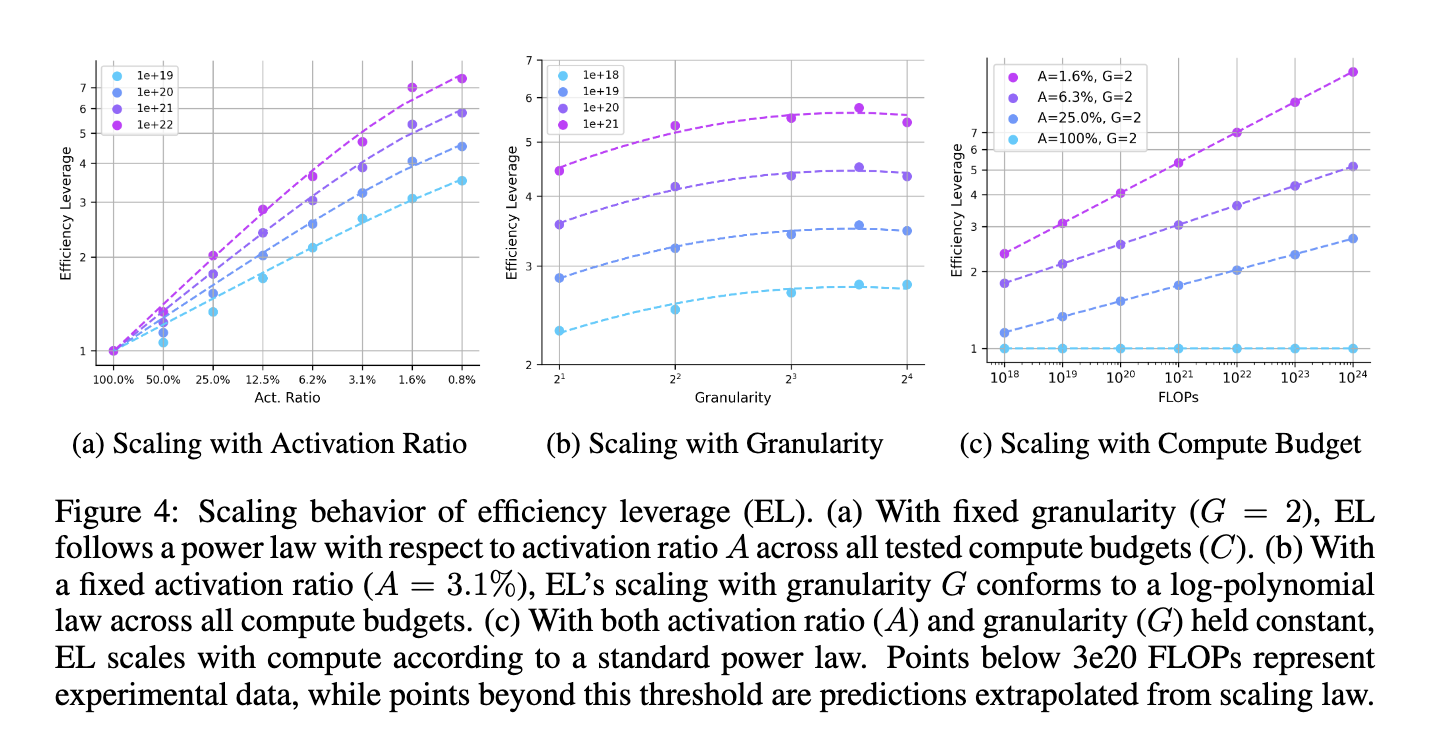
The price of using machine learning intelligence is decreasing by several orders of magnitude a year and shows no signs of slowing. We are likely to see LLMs integrated into every part of computing as infrastructure, not just as a product, in the next year or two. We are likely to see LLMs running locally at current frontier-quality on commodity hardware in the next 3-6 years. Starting very soon, we are likely to see quality and access become the limiting factor to AI 1 use, not sheer number of tokens. Is this really happening? Extraordinary claims require extraordinary evidence, so I collected a whole bunch of evidence. AI can be either proprietary (such as GPT-6 Astra) or open weight (such as GLM-5.3-flash). Open weight models can be either hosted (e.g. by Z.ai) or local. Generally, models intended to be run locally will be much smaller, such as Muse Glimmer or Qwen3 Coder . Improvements in one don't always affect improvements in the others.…