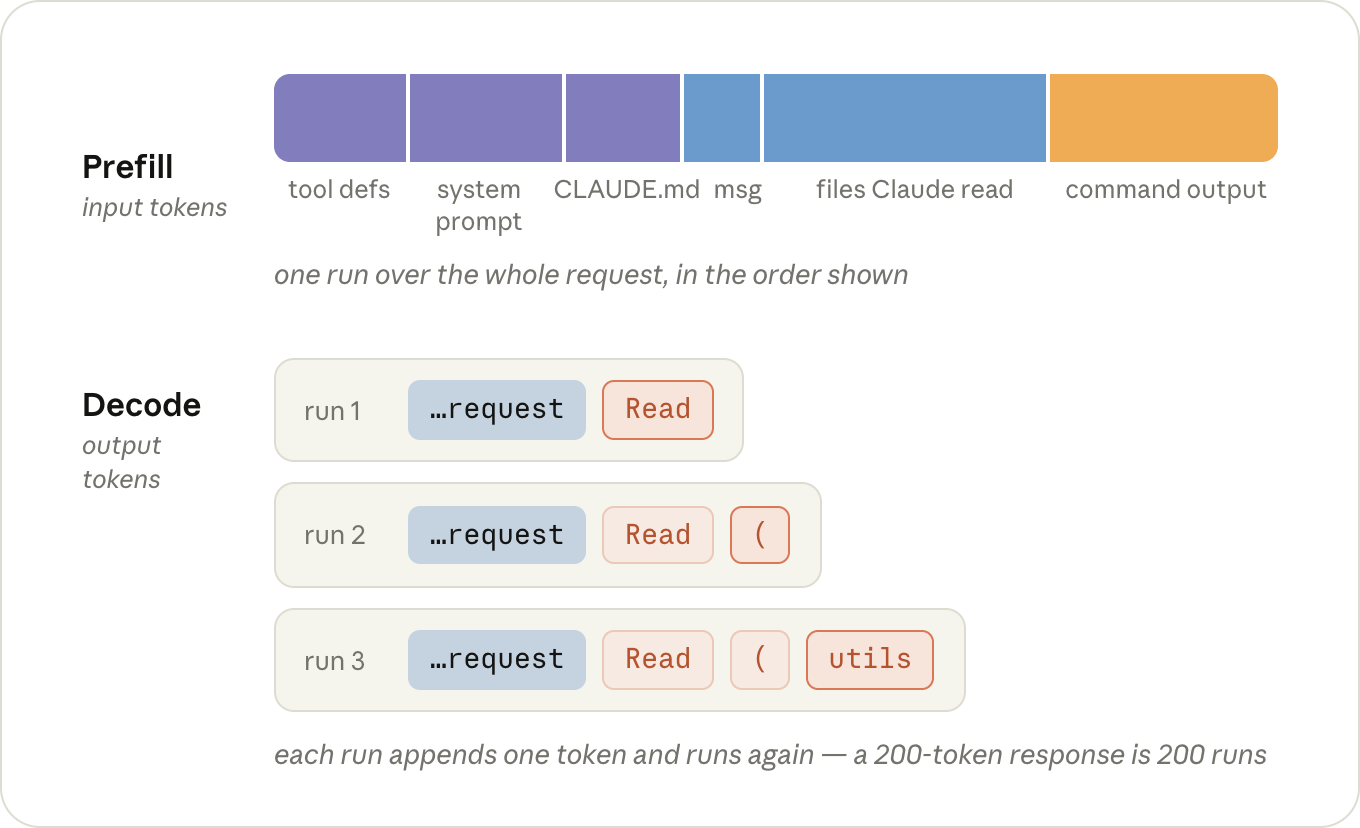
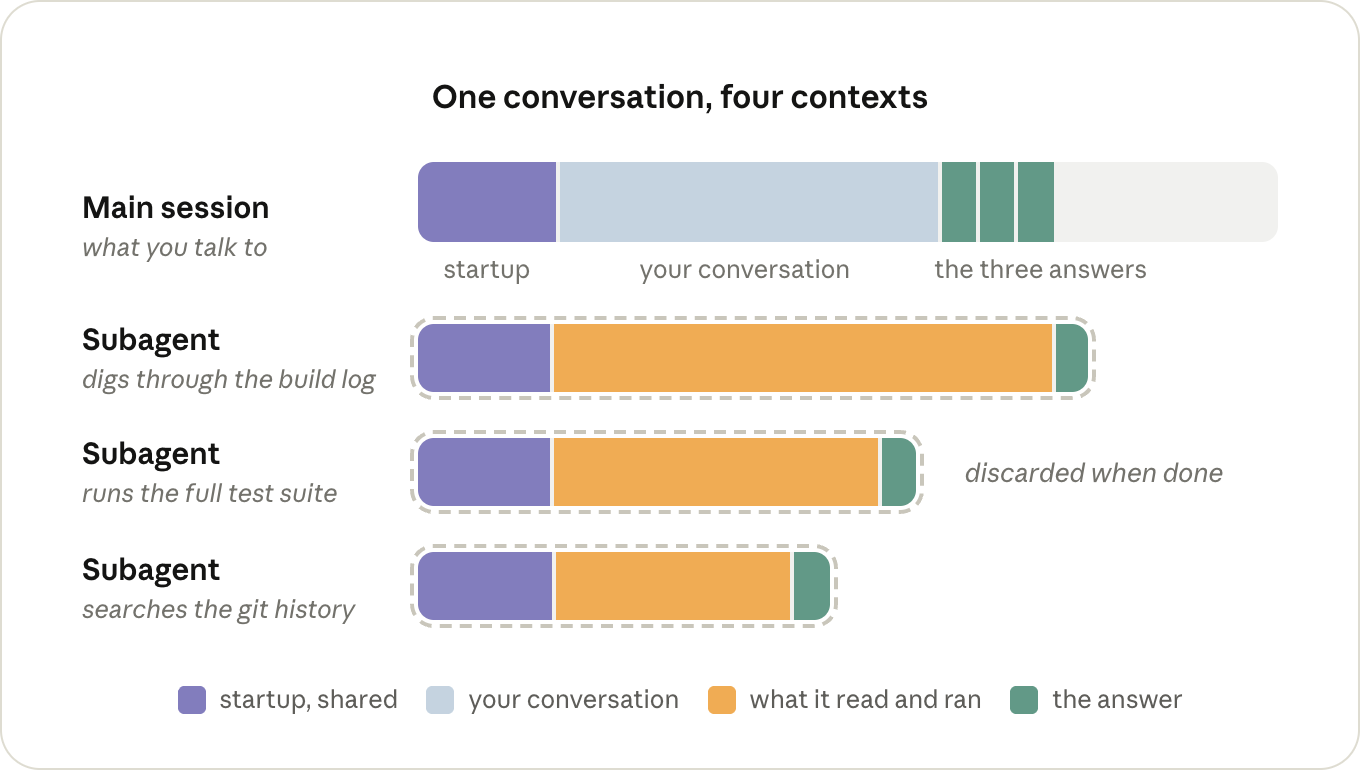
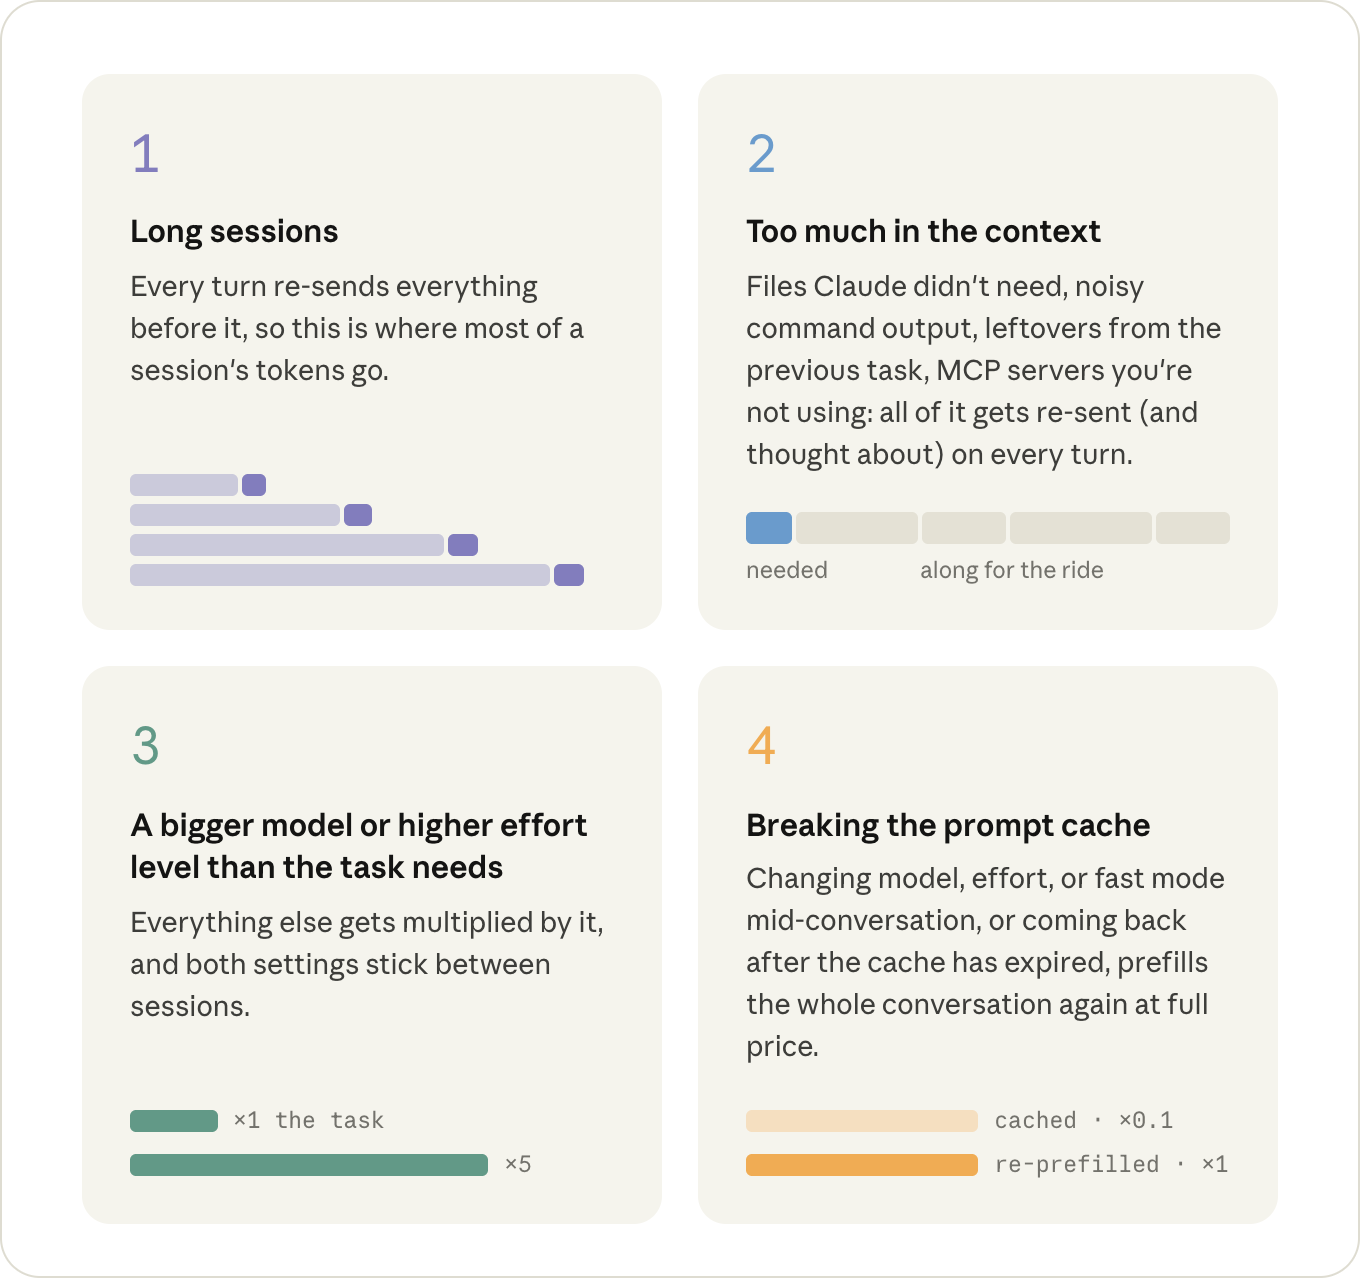
Input and output tokens A request goes through the GPU in two phases, and they cost different amounts. First, during prefill, the model reads your request and context: the system prompt, your CLAUDE.md , your message, and everything that's been added to the conversation since (the files Claude has read and the output of the commands it ran). Those are your input tokens. Then, during decode, it writes output tokens: its thinking, the tool calls it makes, and the text you see. This happens one token at a time; a 200-token response is 200 runs of the model, one after the other. Per token, decode keeps the GPU busy for a lot longer, which is why output is priced at roughly 5x input. A lot of the output tokens in a session are thinking tokens, and how much thinking the model does per turn is what the effort level controls. Like the model, the level you pick with /effort sticks around as your default for the next session too. Tip: run /model and /effort once in a fresh session to see what you're actually on.…