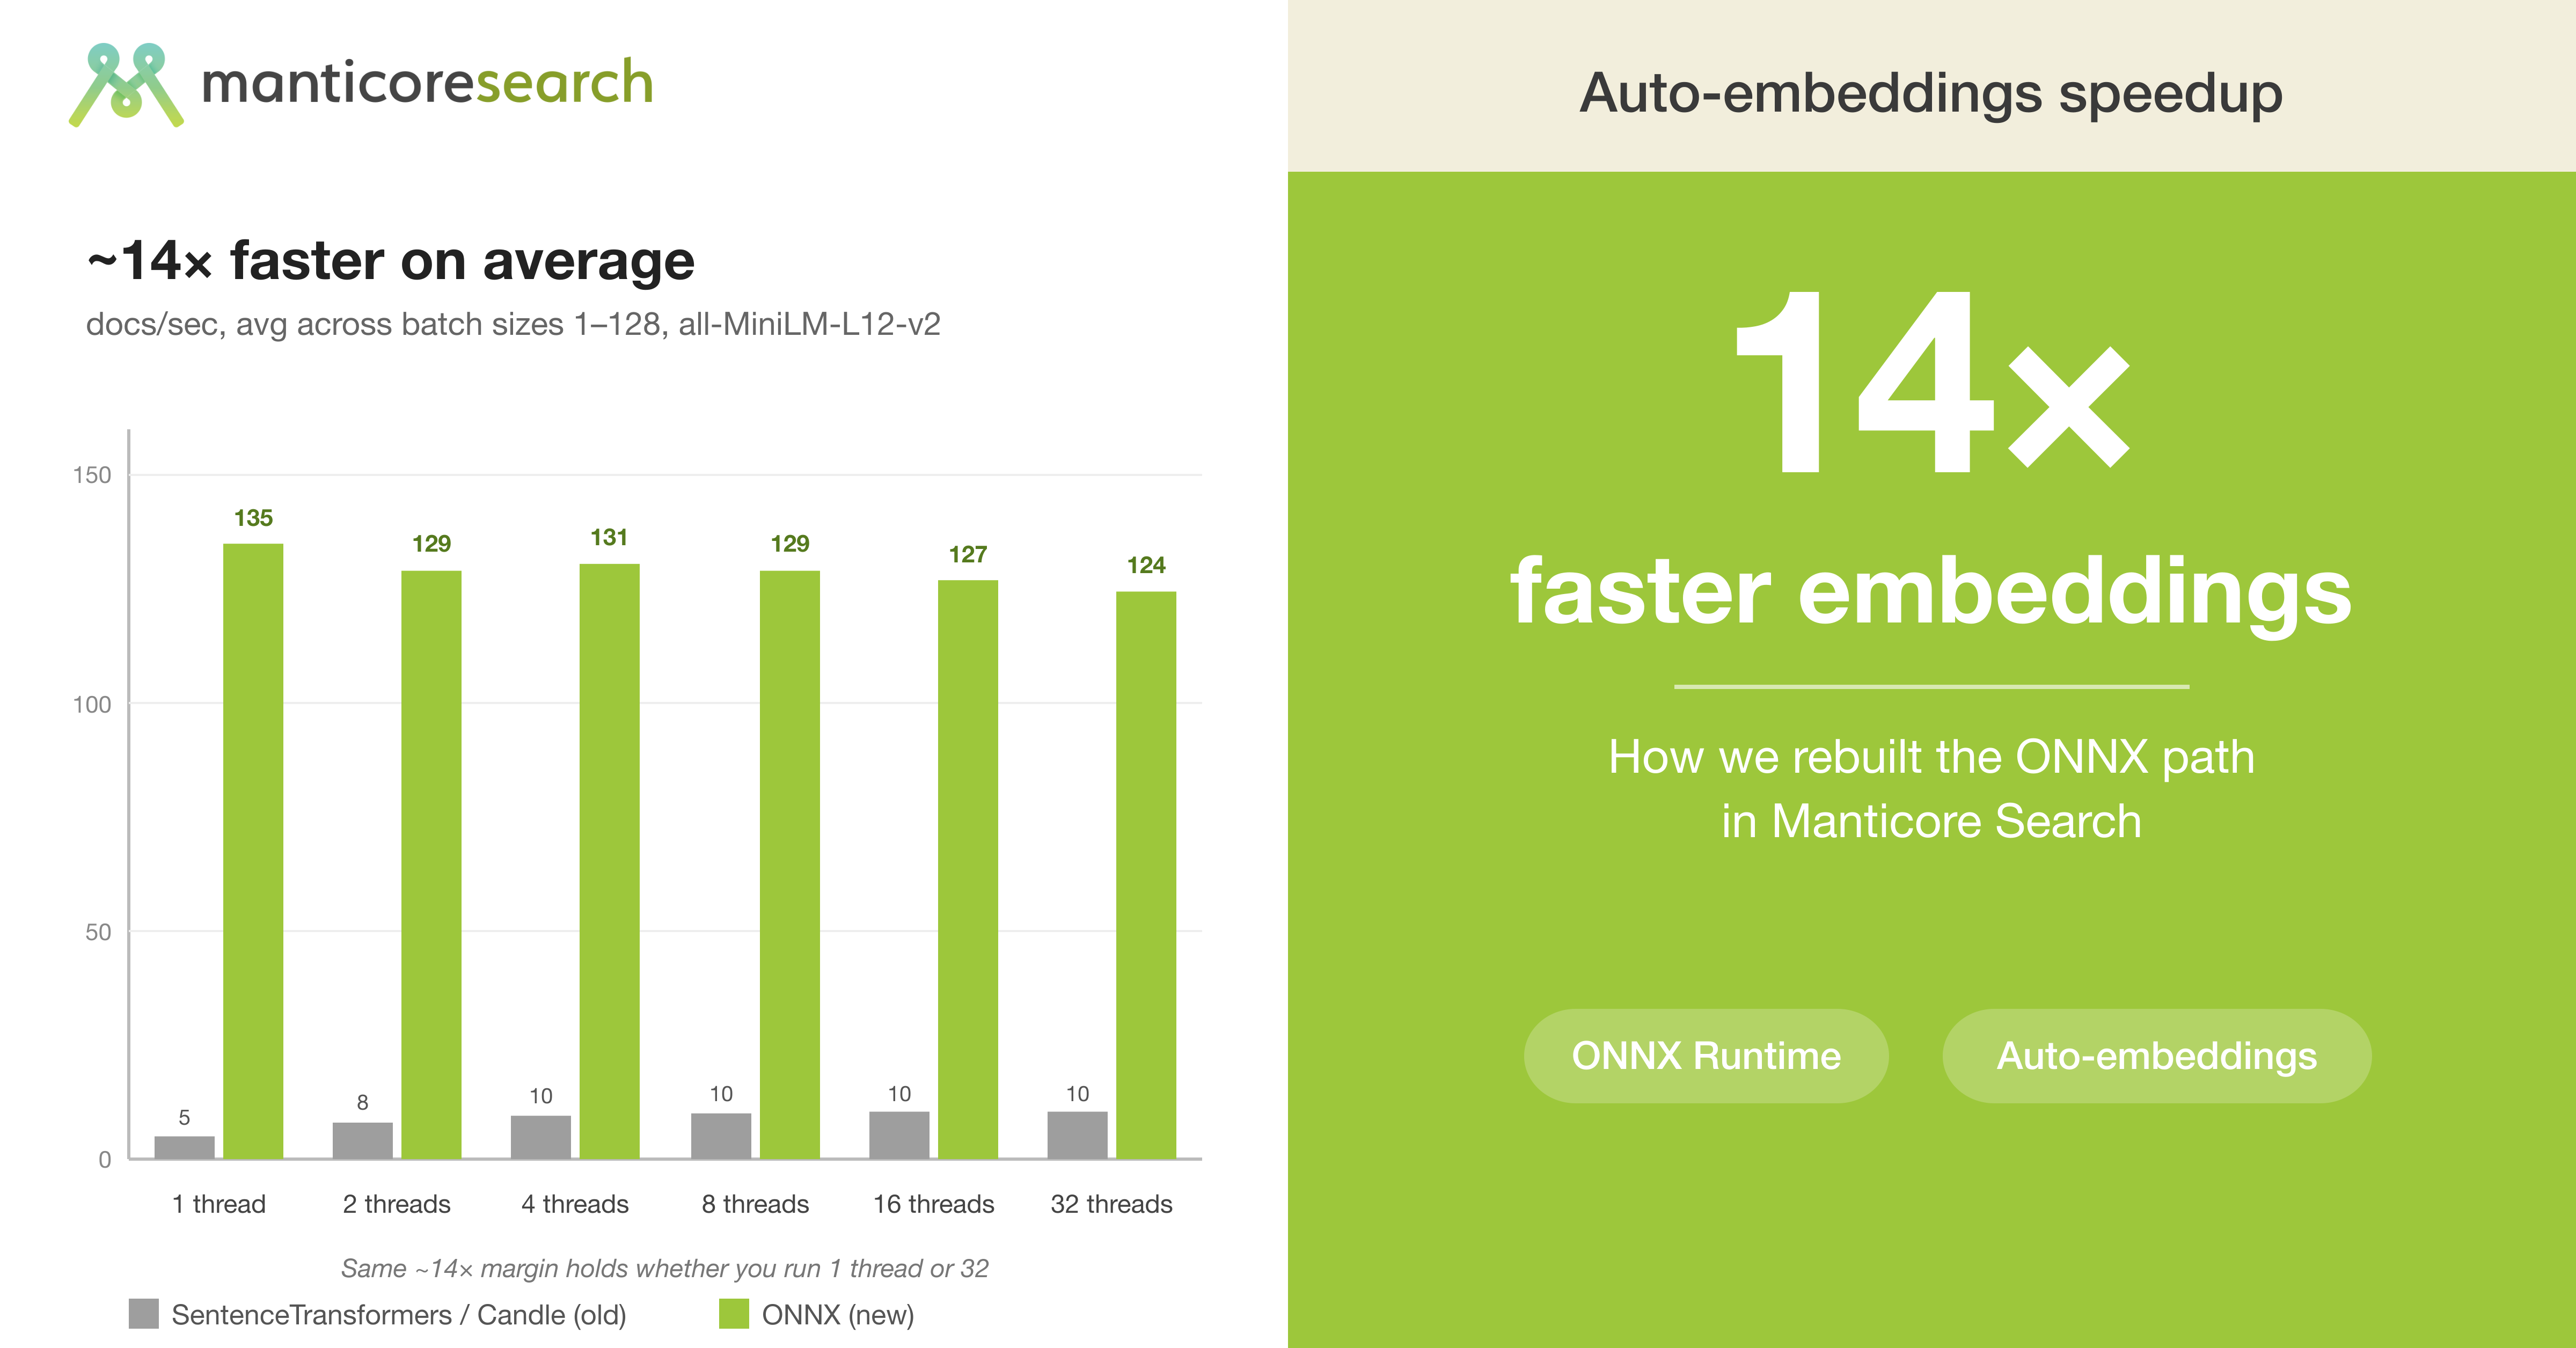
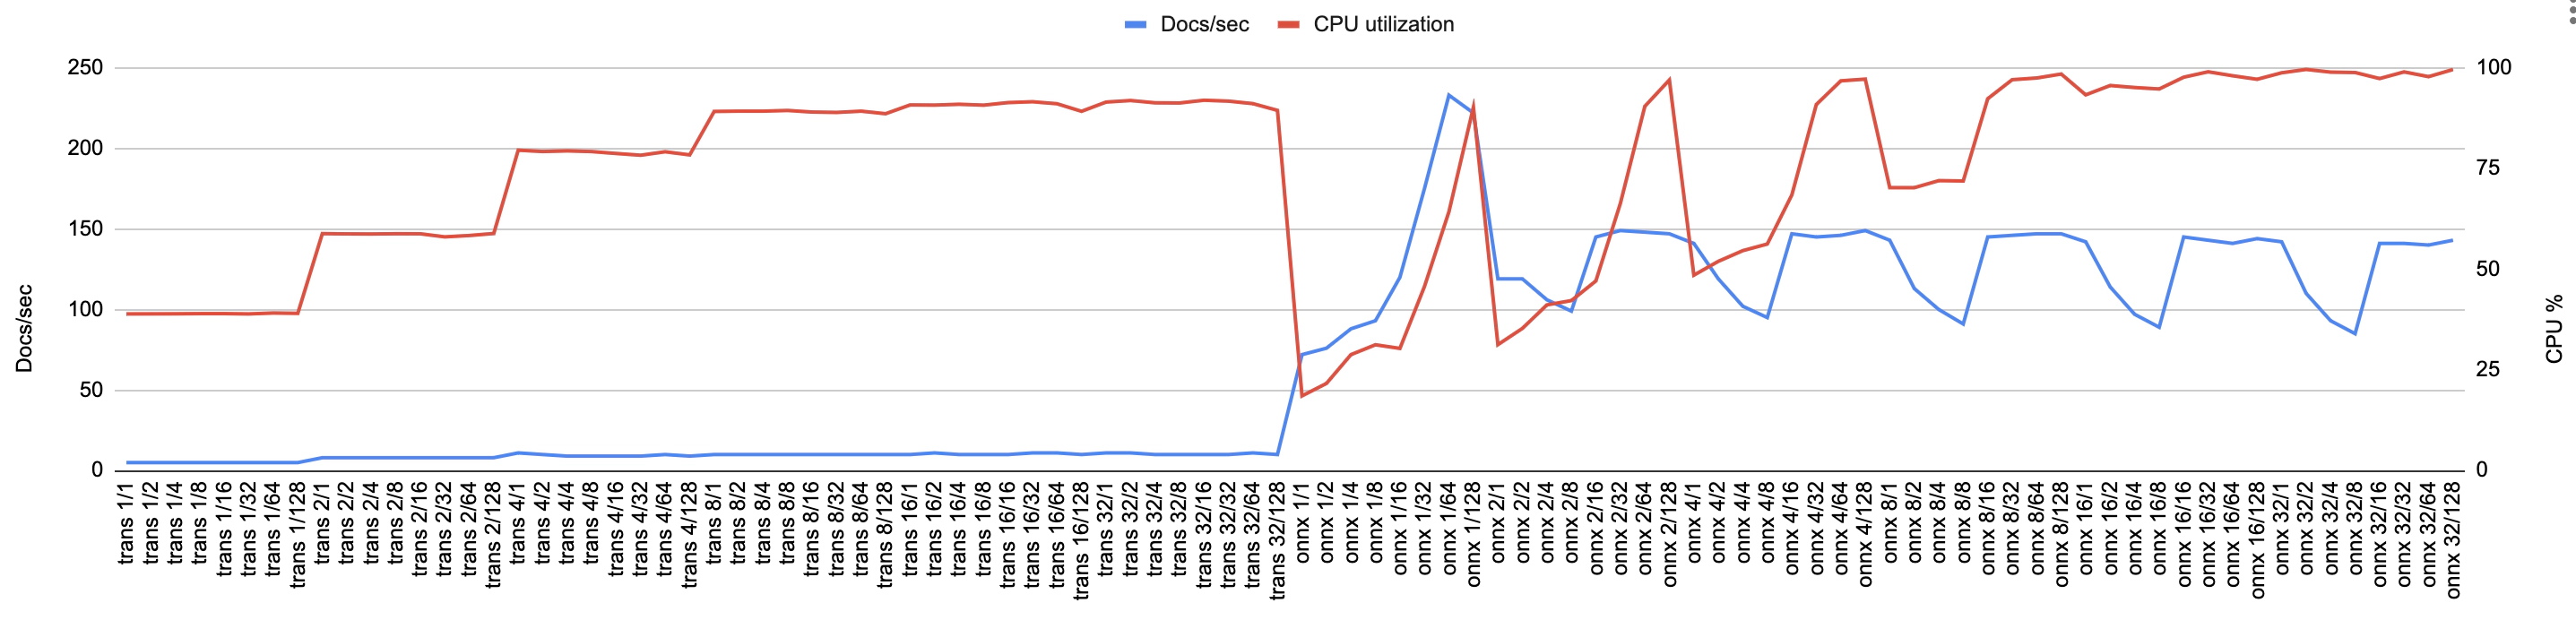
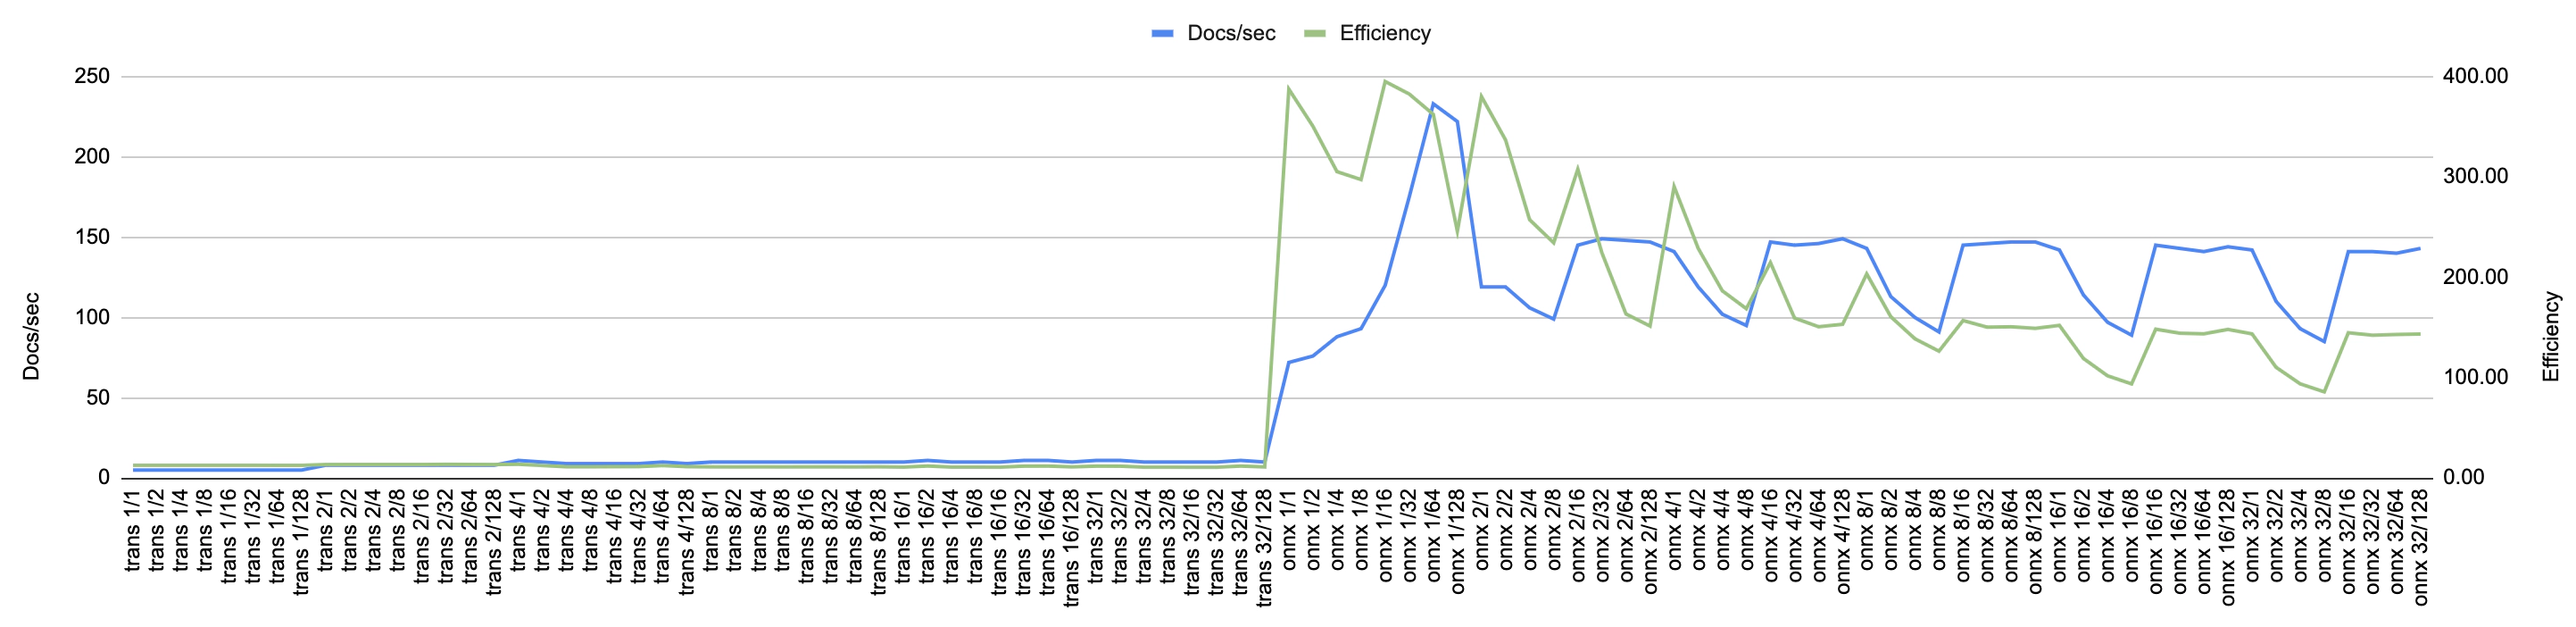
When we shipped Auto Embeddings — the feature that turns any text column into a vector automatically, with no separate model service to run — the most common piece of feedback was about speed. The previous path went through SentenceTransformers on top of Candle , Hugging Face's pure-Rust ML inference runtime, and it left a lot of CPU on the floor: most workloads sat in the low-double-digits of docs/sec no matter how we fed them, and concurrent calls serialised on a single model session. So we spent a few weeks rebuilding how Manticore runs ONNX models. The new ONNX Runtime backend shipped in Manticore Search 27.1.5 . ONNX (Open Neural Network Exchange) is the portable model format that most of the popular open-source embedding models — MiniLM, BGE, E5, and friends — already publish.…