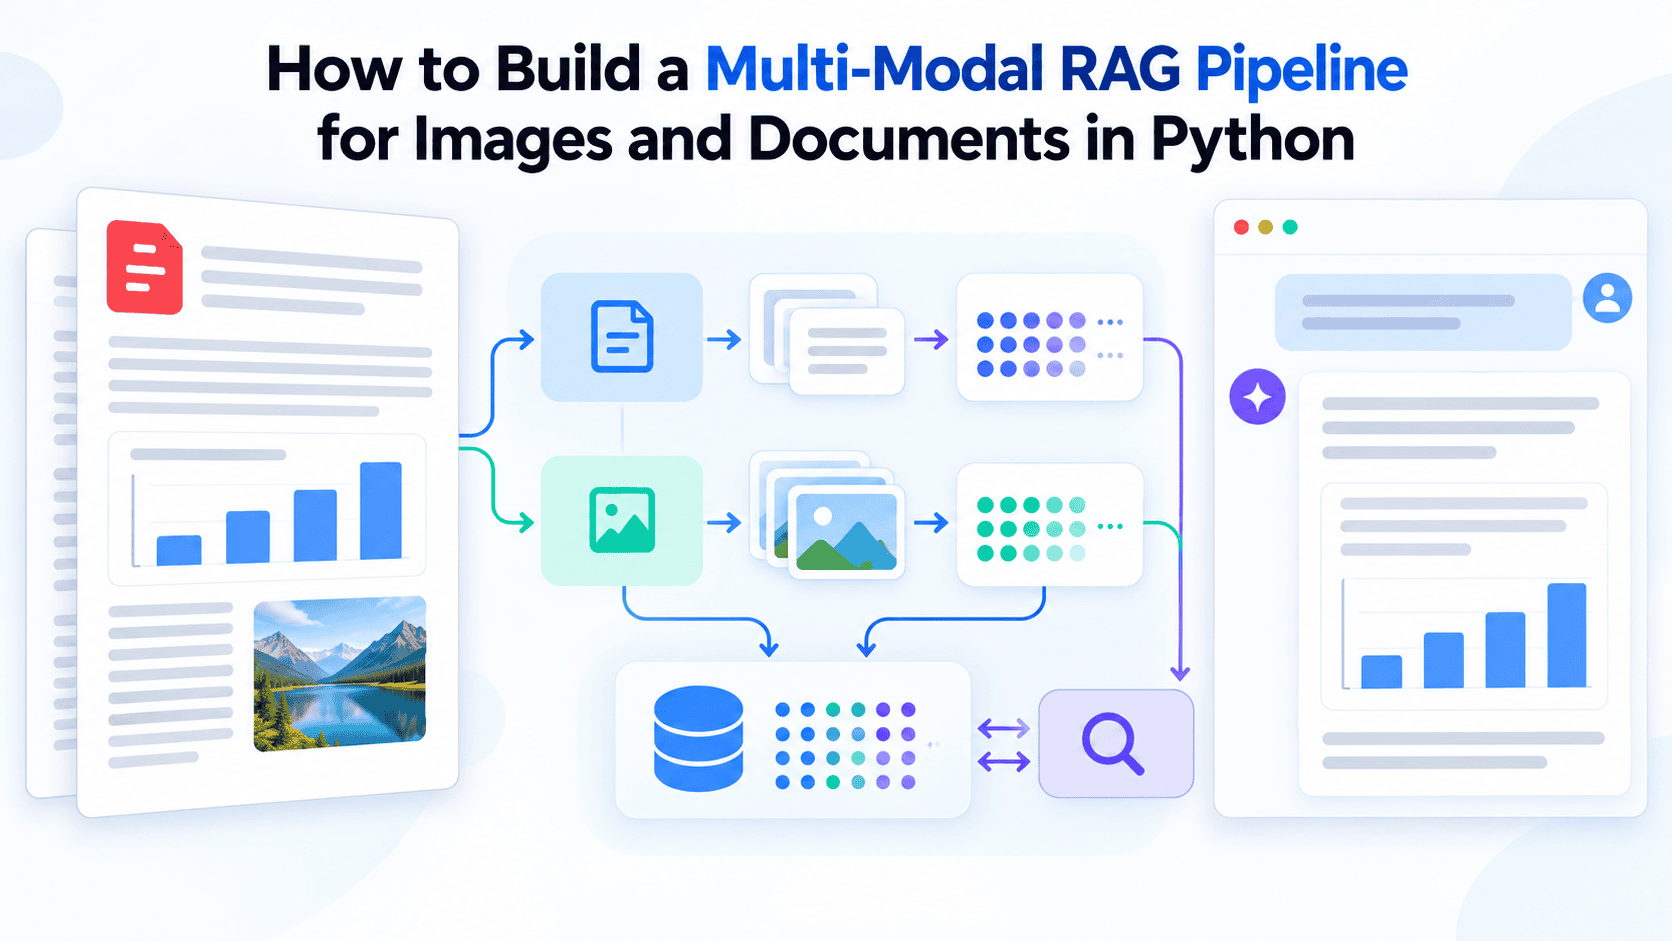
In this article, you will learn how to build a multi-modal RAG pipeline in Python that retrieves and reasons over both text and images extracted from complex documents.
Topics we will cover include:
How to parse a PDF into separate text and image elements using the unstructured library.
How to generate searchable text summaries for extracted images using GPT-4o, and store everything in a multi-vector retrieval system.
How to query the pipeline with a multimodal prompt that passes both text chunks and raw images to GPT-4o for a grounded final answer.
Standard retrieval-augmented generation works great for plain text. But feed it a PDF packed with embedded charts, scanned diagrams, or data tables, and things fall apart fast. Text-based chunking destroys table formatting and skips images, so your pipeline ends up answering questions from an incomplete picture of the document.
A multi-modal RAG pipeline fixes this by treating images as first-class retrievable objects alongside text.…